
Latent Space: The AI Engineer Podcast
231 episodes — Page 2 of 5
Cursor's Third Era: Cloud Agents
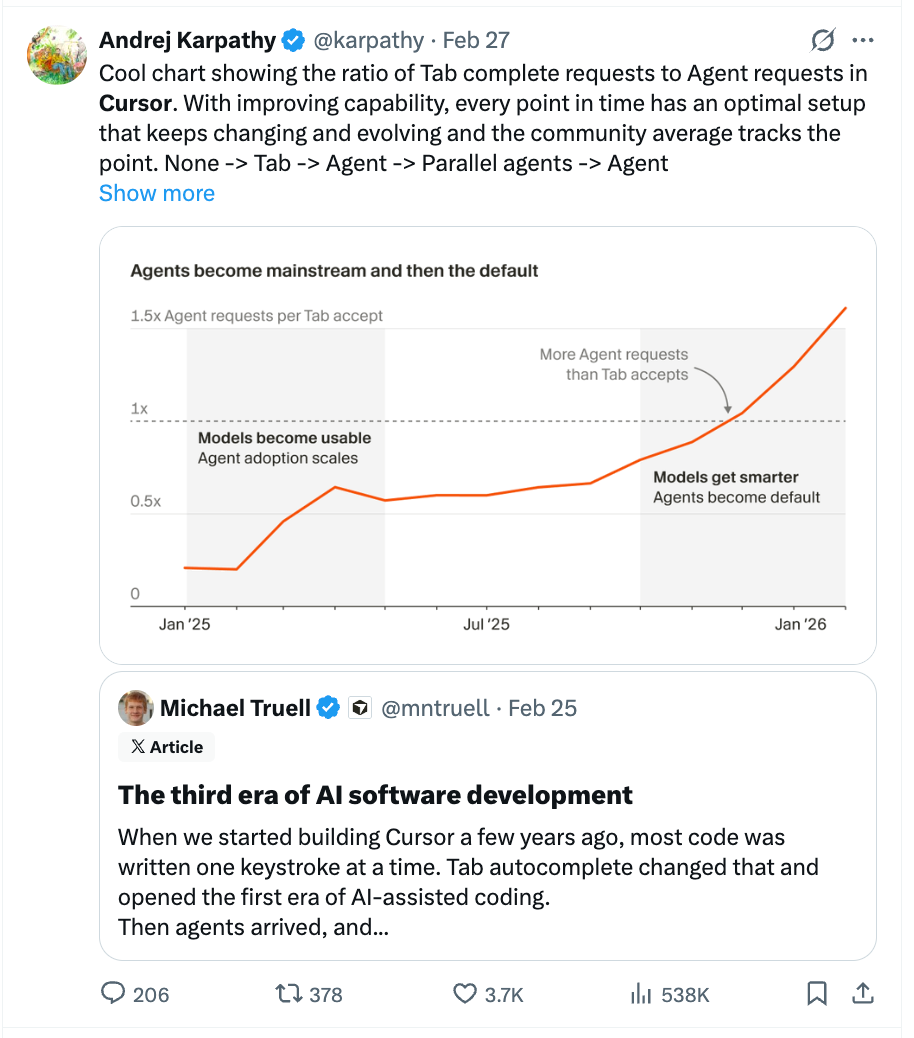
All speakers are announced at AIE EU, schedule coming soon. Join us there or in Miami with the renowned organizers of React Miami! Singapore CFP also open!We’ve called this out a few times over in AINews, but the overwhelming consensus in the Valley is that “the IDE is Dead”. In November it was just a gut feeling, but now we actually have data: even at the canonical “VSCode Fork” company, people are officially using more agents than tab autocomplete (the first wave of AI coding):Cursor has launched cloud agents for a few months now, and this specific launch is around Computer Use, which has come a long way since we first talked with Anthropic about it in 2024, and which Jonas productized as Autotab:We also take the opportunity to do a live demo, talk about slash commands and subagents, and the future of continual learning and personalized coding models, something that Sam previously worked on at New Computer. (The fact that both of these folks are top tier CEOs of their own startups that have now joined the insane talent density gathering at Cursor should also not be overlooked).Full Episode on YouTube!please like and subscribe!Timestamps00:00 Agentic Code Experiments00:53 Why Cloud Agents Matter02:08 Testing First Pillar03:36 Video Reviews Second Pillar04:29 Remote Control Third Pillar06:17 Meta Demos and Bug Repro13:36 Slash Commands and MCPs18:19 From Tab to Team Workflow31:41 Minimal Web UI Philosophy32:40 Why No File Editor34:38 Full Stack Cursor Debate36:34 Model Choice and Auto Routing38:34 Parallel Agents and Best Of N41:41 Subagents and Context Management44:48 Grind Mode and Throughput Future01:00:24 Cloud Agent Onboarding and MemoryTranscriptEP 77 - CURSOR - Audio version[00:00:00]Agentic Code ExperimentsSamantha: This is another experiment that we ran last year and didn’t decide to ship at that time, but may come back to LM Judge, but one that was also agentic and could write code. So it wasn’t just picking but also taking the learnings from two models or and models that it was looking at and writing a new diff.And what we found was that there were strengths to using models from different model providers as the base level of this process. Basically you could get almost like a synergistic output that was better than having a very unified like bottom model tier.Jonas: We think that over the coming months, the big unlock is not going to be one person with a model getting more done, like the water flowing faster and we’ll be making the pipe much wider and so paralyzing more, whether that’s swarms of agents or parallel agents, both of those are things that contribute to getting much more done in the same amount of time.Why Cloud Agents Matterswyx: This week, one of the biggest launches that Cursor’s ever done is cloud agents. I think you, you had [00:01:00] cloud agents before, but this was like, you give cursor a computer, right? Yeah. So it’s just basically they bought auto tab and then they repackaged it. Is that what’s going on, or,Jonas: that’s a big part of it.Yeah. Cloud agents already ran in their own computers, but they were sort of site reading code. Yeah. And those computers were not, they were like blank VMs typically that were not set up for the Devrel X for whatever repo the agents working on. One of the things that we talk about is if you put yourself in the model shoes and you were seeing tokens stream by and all you could do was cite read code and spit out tokens and hope that you had done the right thing,swyx: no chanceJonas: I’d be so bad.Like you obviously you need to run the code. And so that I think also is probably not that contrarian of a take, but no one has done that yet. And so giving the model the tools to onboard itself and then use full computer use end-to-end pixels in coordinates out and have the cloud computer with different apps in it is the big unlock that we’ve seen internally in terms of use usage of this going from, oh, we use it for little copy changes [00:02:00] to no.We’re really like driving new features with this kind of new type of entech workflow. Alright, let’s see it. Cool.Live Demo TourJonas: So this is what it looks like in cursor.com/agents. So this is one I kicked off a while ago. So on the left hand side is the chat. Very classic sort of agentic thing. The big new thing here is that the agent will test its changes.So you can see here it worked for half an hour. That is because it not only took time to write the tokens of code, it also took time to test them end to end. So it started Devrel servers iterate when needed. And so that’s one part of it is like model works for longer and doesn’t come back with a, I tried some things pr, but a I tested at pr that’s ready for your review.One of the other intuition pumps we use there is if a human gave you a PR asked you to review it and you hadn’t, they hadn’t tested it, you’d also be annoyed because you’d be like, only ask me for a review once it’s actually ready. So that’s what we’ve done withTesting Defaul
Every Agent Needs a Box — Aaron Levie, Box
The reception to our recent post on Code Reviews has been strong. Catch up!Amid a maelstrom of discussion on whether or not AI is killing SaaS, one of the top publicly listed SaaS companies in the world has just reported record revenues, clearing well over $1.1B in ARR for the first time with a 28% margin. As we comment on the pod, Aaron Levie is the rare public company CEO equally at home in both worlds of Silicon Valley and Wall Street/Main Street, by day helping 70% of the Fortune 500 with their Enterprise Advanced Suite, and yet by night is often found in the basements of early startups and tweeting viral insights about the future of agents.Now that both Cursor, Cloudflare, Perplexity, Anthropic and more have made Filesystems and Sandboxes and various forms of “Just Give the Agent a Box” cool (not just cool; it is now one of the single hottest areas in AI infrastructure growing 100% MoM), we find it a delightfully appropriate time to do the episode with the OG CEO who has been giving humans and computers Boxes since he was a college dropout pitching VCs at a Michael Arrington house party.Enjoy our special pod, with fan favorite returning guest/guest cohost Jeff Huber!Note: We didn’t directly discuss the AI vs SaaS debate - Aaron has done many, many, many other podcasts on that, and you should read his definitive essay on it. Most commentators do not understand SaaS businesses because they have never scaled one themselves, and deeply reflected on what the true value proposition of SaaS is.We also discuss Your Company is a Filesystem:We also shoutout CTO Ben Kus’ and the AI team, who talked about the technical architecture and will return for AIE WF 2026.Full Video EpisodeTimestamps* 00:00 Adapting Work for Agents* 01:29 Why Every Agent Needs a Box* 04:38 Agent Governance and Identity* 11:28 Why Coding Agents Took Off First* 21:42 Context Engineering and Search Limits* 31:29 Inside Agent Evals* 33:23 Industries and Datasets* 35:22 Building the Agent Team* 38:50 Read Write Agent Workflows* 41:54 Docs Graphs and Founder Mode* 55:38 Token FOMO Culture* 56:31 Production Function Secrets* 01:01:08 Film Roots to Box* 01:03:38 AI Future of Movies* 01:06:47 Media DevRel and EngineeringTranscriptAdapting Work for AgentsAaron Levie: Like you don’t write code, you talk to an agent and it goes and does it for you, and you may be at best review it. That’s even probably like, like largely not even what you’re doing. What’s happening is we are changing our work to make the agents effective. In that model, the agent didn’t really adapt to how we work.We basically adapted to how the agent works. All of the economy has to go through that exact same evolution. Right now, it’s a huge asset and an advantage for the teams that do it early and that are kinda wired into doing this ‘cause you’ll see compounding returns. But that’s just gonna take a while for most companies to actually go and get this deployed.swyx: Welcome to the Lane Space Pod. We’re back in the chroma studio with uh, chroma, CEO, Jeff Hoover. Welcome returning guest now guest host.Aaron Levie: It’s a pleasure. Wow. How’d you get upgraded to, uh, to that?swyx: Because he’s like the perfect guy to be guest those for you.Aaron Levie: That makes sense actually, for We love context. We, we both really love context le we really do.We really do.swyx: Uh, and we’re here with, uh, Aaron Levy. Welcome.Aaron Levie: Thank you. Good to, uh, good to be [00:01:00] here.swyx: Uh, yeah. So we’ve all met offline and like chatted a little bit, but like, it’s always nice to get these things in person and conversation. Yeah. You just started off with so much energy. You’re, you’re super excited about agents.I loveAaron Levie: agents.swyx: Yeah. Open claw. Just got by, got bought by OpenAI. No, not bought, but you know, you know what I mean?Aaron Levie: Some, some, you know, acquihire. Executiveswyx: hire.Aaron Levie: Executive hire. Okay. Executive hire. Say,swyx: hey, that’s my term. Okay. Um, what are you pounding the table on on agents? You have so many insightful tweets.Why Every Agent Needs a BoxAaron Levie: Well, the thing that, that we get super excited by that I think is probably, you know, should be relatively obvious is we’ve, we’ve built a platform to help enterprises manage their files and their, their corporate files and the permissions of who has access to those files and the sharing collaboration of those files.All of those files contain really, really important information for the enterprise. It might have your contracts, it might have your research materials, it might have marketing information, it might have your memos. All that data obviously has, you know, predominantly been used by humans. [00:02:00] But there’s been one really interesting problem, which is that, you know, humans only really work with their files during an active engagement with them, and they kind of go away and you don’t really see them for a long time.And all of a sudden, uh, with the power
METR’s Joel Becker on exponential Time Horizon Evals, Threat Models, and the Limits of AI Productivity
This is a free preview of a paid episode. To hear more, visit www.latent.spaceAIE Europe CFP and AIE World’s Fair paper submissions for CAIS peer review are due TODAY - do not delay! Last call ever.We’re excited to welcome METR for their first LS Pod, hopefully the first of many:METR are keepers of currently the single most infamous chart in AI:But every Latent Space reader should be sophisticated enough to know that the details matter and that hype and hyperbole go hand in hand in AI social media, because the millions of impressions that got, by people who don’t understand or care about the nuances, disclaimers, and error bars, far outreaches the 69k views on the corrections by the people who actually made the chart:There’s a lot of nuance both in making benchmarks (as we discovered with OpenAI on our SWE-Bench Verified podcast) and in extrapolating results from them, especially where exponentials and sigmoids are concerned. METR’s Long Horizons work itself has known biases that the authors have responsibly disclosed, but go far too underappreciated in the pursuit of doomer chart porn.If you’re interested in a short, sharable TED talk version of this pod, over at AIE CODE we were blessed to feature Joel twice, as a stage talk and with a longer form small workshop with Q&A:We also make sure cover some of METR’s lesser known work on Threat Evaluation but also Developer Productivity, where 2x friend of the pod and now Zyphra founder Quentin Anthony was the ONLY productive participant!Finally, if you’re the sort to read these show notes to the end, then you definitely deserve some pictures of Joel shredding the guitar at Love Band Karaoke which we mention at the end: Full Video PodTimestamps00:00 What METR Means00:39 Podcast Intro With Joel01:39 ME vs TR03:33 Time Horizon Origin Story04:56 Picking Tasks And Biases09:13 Time Horizon Misconceptions11:37 Opus 4.5 And Trendlines14:27 Productivity Studies And Explosions29:50 Compute Slows Progress30:47 Algorithms Need Compute32:45 Industry Spend and Data34:57 Clusters and Shipping Timelines36:44 Prediction Markets for Models38:10 Manifold Alpha Story43:04 Beyond Benchmarks Evals51:39 METR Roadmap and FarewellTranscript
[LIVE] Anthropic Distillation & How Models Cheat (SWE-Bench Dead) | Nathan Lambert & Sebastian Raschka
Swyx joined SAIL! Thank you SAIL Media, Prof. Tom Yeh, 8Lee, Hamid Bagheri, c9n, and many others for tuning into SAIL Live #6 with Nathan Lambert and Sebastian Raschka, PhD. Sharing here for the LS paid subscribers.We covered: This is a public episode. If you'd like to discuss this with other subscribers or get access to bonus episodes, visit www.latent.space/subscribe
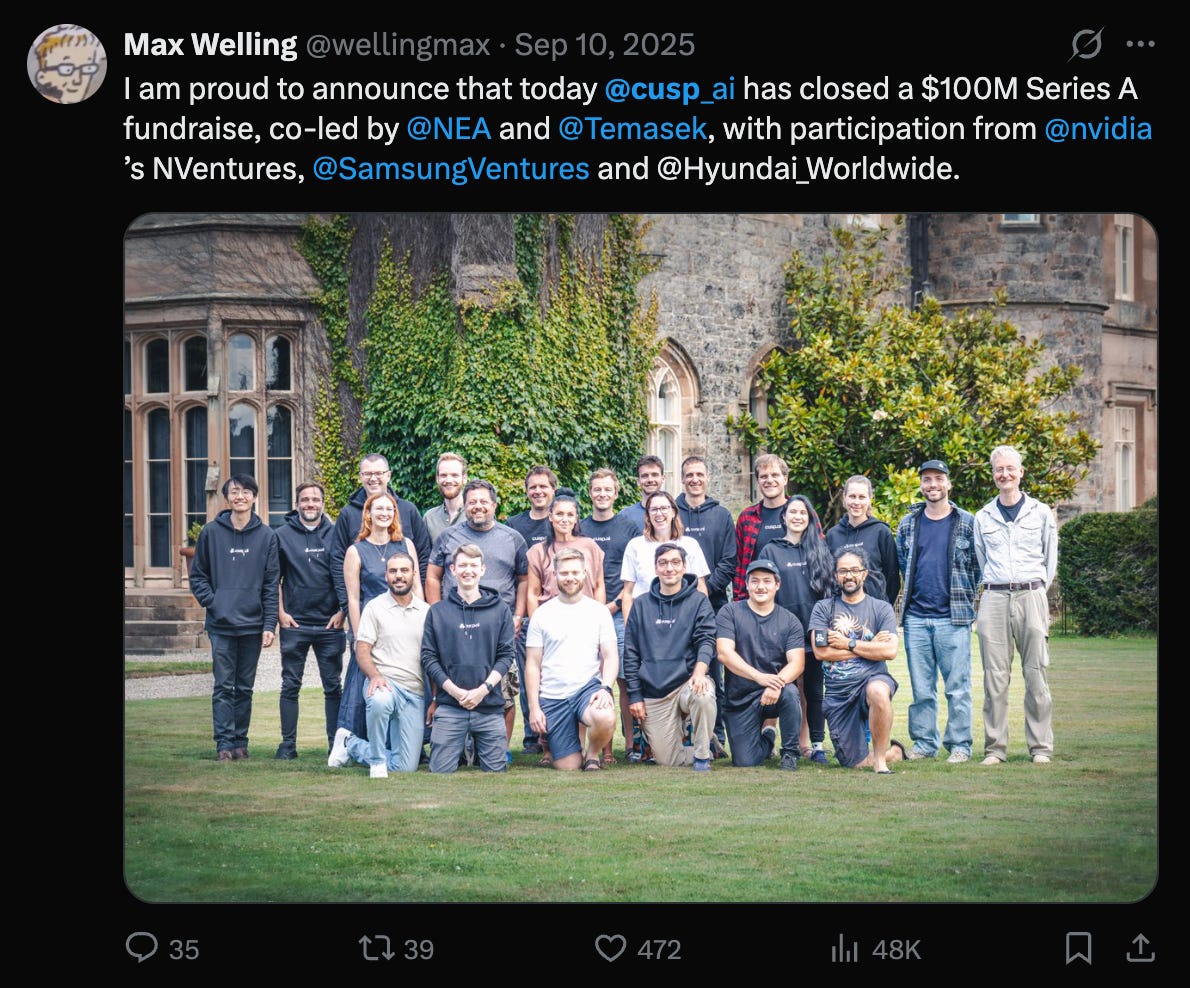
🔬Searching the Space of All Possible Materials — Prof. Max Welling, CuspAI
Editor’s note: CuspAI raised a $100m Series A in September and is rumored to have reached a unicorn valuation. They have all-star advisors from Geoff Hinton to Yann Lecun and team of deep domain experts to tackle this next frontier in AI applications.In this episode, Max Welling traces the thread connecting quantum gravity, equivariant neural networks, diffusion models, and climate-focused materials discovery (yes, there is one!!!).We begin with a provocative framing: experiments as computation. Welling describes the idea of a “physics processing unit”—a world in which digital models and physical experiments work together, with nature itself acting as a kind of processor. It’s a grounded but ambitious vision of AI for science: not replacing chemists, but accelerating them.Along the way, we discuss:* Why symmetry and equivariance matter in deep learning* The tradeoff between scale and inductive bias* The deep mathematical links between diffusion models and stochastic thermodynamics* Why materials—not software—may be the real bottleneck for AI and the energy transition* What it actually takes to build an AI-driven materials platformMax reflects on moving from curiosity-driven theoretical physics (including work with Gerard ‘t Hooft) toward impact-driven research in climate and energy. The result is a conversation about convergence: physics and machine learning, digital models and laboratory experiments, long-term ambition and incremental progress.Full Video EpisodeTimestamps* 00:00:00 – The Physics Processing Unit (PPU): Nature as the Ultimate Computer* Max introduces the idea of a Physics Processing Unit — using real-world experiments as computation.* 00:00:44 – From Quantum Gravity to AI for Materials* Brandon frames Max’s career arc: VAE pioneer → equivariant GNNs → materials startup founder.* 00:01:34 – Curiosity vs Impact: How His Motivation Evolved* Max explains the shift from pure theoretical curiosity to climate-driven impact.* 00:02:43 – Why CaspAI Exists: Technology as Climate Strategy* Politics struggles; technology scales. Why materials innovation became the focus.* 00:03:39 – The Thread: Physics → Symmetry → Machine Learning* How gauge symmetry, group theory, and relativity informed equivariant neural networks.* 00:06:52 – AI for Science Is Exploding (Not Emerging)* The funding surge and why AI-for-Science feels like a new industrial era.* 00:07:53 – Why Now? The Two Catalysts Behind AI for Science* Protein folding, ML force fields, and the tipping point moment.* 00:10:12 – How Engineers Can Enter AI for Science* Practical pathways: curriculum, workshops, cross-disciplinary training.* 00:11:28 – Why Materials Matter More Than Software* The argument that everything—LLMs included—rests on materials innovation.* 00:13:02 – Materials as a Search Engine* The vision: automated exploration of chemical space like querying Google.* 01:14:48 – Inside CuspAI: The Platform Architecture* Generative models + multi-scale digital twin + experiment loop.* 00:21:17 – Automating Chemistry: Human-in-the-Loop First* Start manual → modular tools → agents → increasing autonomy.* 00:25:04 – Moonshots vs Incremental Wins* Balancing lighthouse materials with paid partnerships.* 00:26:22 – Why Breakthroughs Will Still Require Humans* Automation is vertical-specific and iterative.* 00:29:01 – What Is Equivariance (In Plain English)?* Symmetry in neural networks explained with the bottle example.* 00:30:01 – Why Not Just Use Data Augmentation?* The optimization trade-off between inductive bias and data scale.* 00:31:55 – Generative AI Meets Stochastic Thermodynamics* His upcoming book and the unification of diffusion models and physics.* 00:33:44 – When the Book Drops (ICLR?)TranscriptMax: I want to think of it as what I would call a physics processing unit, like a PPU, right? Which is you have digital processing units and then you have physics processing units. So it’s basically nature doing computations for you. It’s the fastest computer known, as possible even. It’s a bit hard to program because you have to do all these experiments. Those are quite bulky, it’s like a very large thing you have to do. But in a way it is a computation and that’s the way I want to see it. You can do computations in a data center and then you can ask nature to do some computations. Your interface with nature is a bit more complicated. But then these things will have to seamlessly work together to get to a new material that you’re interested in.[01:00:44:14 - 01:01:34:08]Brandon: Yeah, it’s a pleasure to have Max Woehling as a guest today. Max has done so much over his career that I’ve been so excited about. If you’re in the deep learning community, you probably know Max for his work on variational autocoders, which has literally stood the test of prime or officially stood the test of prime. If you are a scientist, you probably know him for his like, binary work on graph neural networks on equivariance. And if you’re a material science, you pro
Claude Code for Finance + The Global Memory Shortage: Doug O'Laughlin, SemiAnalysis
This is a free preview of a paid episode. To hear more, visit www.latent.spaceFirst speakers for AIE Europe and AIEi Miami have been announced. If you’re in Asia/Aus, come by Singapore and Melbourne. AI Engineering is going global!One year ago today, Anthropic launched Claude Code, to not much fanfare:The word of mouth was incredibly strong however, and so we were glad to be one of the first podcasts to invite Boris and Cat on in early May:As we discussed on the pod, all CC usage was API-based and therefore it was ridiculously expensive to do anything. This was then fixed by the team including Claude Code in the Claude Pro plan in early June, and then the virality caused us to make a rare trend call in late June:Now, 6 months on, Doug has just calculated that around 4% of GitHub is written by Claude Code:We talk about how Doug uses Claude Code to do SemiAnalysis work.Memory ManiaIn the second part of this episode, we also check in on Memory Mania, which is going to affect you (yes, you) at home if it hasn’t already:Full Episode on YouTubeTimestamps00:00 AI as Junior Analyst00:59 Meet Swyx and Doug03:30 From Value Mule to Semis06:28 Moore’s Law Ends Thesis12:02 Claude Code Awakening32:02 Agent Swarms Reality Check32:53 Kimi Swarm Benchmarks37:31 Bots vs Zapier Automation39:44 Claude Code Workflow Setup57:54 AGI Metrics and GDP01:04:48 Railroad CapEx Analogy01:06:00 Funding Bubbles and Demand01:08:11 Agents Replace Work Tools01:13:56 Codex vs Claude Race01:21:15 Microsoft and TPU Strategy01:34:13 TPU Window vs Nvidia01:36:30 HBM Supply Chain Squeeze01:39:41 Memory Shock and CXL01:45:20 Context Rationing Future01:54:37 Writing and Trail LessonsTranscript[00:00:00] AI as Junior Analyst[00:00:00] Doug: This crap makes mistakes all the time. All the time. It is still just like a, like I think of it once again as like a junior analyst, right? The analyst goes and does all this like really pain in the ass information and you bring it all together to make a good decision at the top. Historically what happens is that junior analyst, who I once was, went and gathered all that information, and after doing this enough times, there’s a meta level thinking that’s happening where it’s like, okay, here’s what I really understand and how this type of analysis, I’m an expert in, actually I’m very good at, I consistently have a hit rate.[00:00:28] Now I’m the expert, right? I don’t think that meta level learning is there yet. We’ll see if l ones do it, right? Everyone who’s spending one quadrillion dollars in the world thinks it will, it better, it better happen by if you’re spending, you know, a trillion dollars and there’s not meta level learning.[00:00:44] But for me, in our firm, that massively amplifies everyone who is an expert. ‘cause like you have to still do something that you can just like lop it up. It’s very obvious to me. What It’s slop.[00:00:59] Meet Swyx and Doug
⚡️The End of SWE-Bench Verified — Mia Glaese & Olivia Watkins, OpenAI Frontier Evals & Human Data
Olivia Watkins (Frontier Evals team) and Mia Glaese (VP of Research at OpenAI, leading the Codex, human data, and alignment teams) discuss a new blog post (https://openai.com/index/why-we-no-longer-evaluate-swe-bench-verified/) arguing that SWE-Bench Verified—long treated as a key “North Star” coding benchmark—has become saturated and highly contaminated, making it less useful for measuring real coding progress. SWE-Bench Verified originated as a major OpenAI-led cleanup of the original Princeton SWE-Bench benchmark, including a large human review effort with nearly 100 software engineers and multiple independent reviews to curate ~500 higher-quality tasks. But recent findings show that many remaining failures can reflect unfair or overly narrow tests (e.g., requiring specific naming or unspecified implementation details) rather than true model inability, and cite examples suggesting contamination such as models recalling repository-specific implementation details or task identifiers. From now on, OpenAI plans to stop reporting SWE-Bench Verified and instead focus on SWE-Bench Pro (from Scale), which is harder, more diverse (more repos and languages), includes longer tasks (1–4 hours and 4+ hours), and shows substantially less evidence of contamination under their “contamination auditor agent” analysis. We also discuss what future coding/agent benchmarks should measure beyond pass/fail tests—longer-horizon tasks, open-ended design decisions, code quality/maintainability, and real-world product-building—along with the tradeoffs between fast automated grading and human-intensive evaluation. 00:00 Meet the Frontier Evals Team00:56 Why SWE Bench Stalled01:47 How Verified Was Built04:32 Contamination In The Wild06:16 Unfair Tests And Narrow Specs08:40 When Benchmarks Saturate10:28 Switching To SWE Bench Pro12:31 What Great Coding Evals Measure18:17 Beyond Tests Dollars And Autonomy21:49 Preparedness And Future Directions This is a public episode. If you'd like to discuss this with other subscribers or get access to bonus episodes, visit www.latent.space/subscribe
Bitter Lessons in Venture vs Growth: Anthropic vs OpenAI, Noam Shazeer, World Labs, Thinking Machines, Cursor, ASIC Economics — Martin Casado & Sarah Wang of a16z
Tickets for AIEi Miami and AIE Europe are live, with first wave speakers announced!From pioneering software-defined networking to backing many of the most aggressive AI model companies of this cycle, Martin Casado and Sarah Wang sit at the center of the capital, compute, and talent arms race reshaping the tech industry. As partners at a16z investing across infrastructure and growth, they’ve watched venture and growth blur, model labs turn dollars into capability at unprecedented speed, and startups raise nine-figure rounds before monetization.Martin and Sarah join us to unpack the new financing playbook for AI: why today’s rounds are really compute contracts in disguise, how the “raise → train → ship → raise bigger” flywheel works, and whether foundation model companies can outspend the entire app ecosystem built on top of them. They also share what’s underhyped (boring enterprise software), what’s overheated (talent wars and compensation spirals), and the two radically different futures they see for AI’s market structure.We discuss:* Martin’s “two futures” fork: infinite fragmentation and new software categories vs. a small oligopoly of general models that consume everything above them* The capital flywheel: how model labs translate funding directly into capability gains, then into revenue growth measured in weeks, not years* Why venture and growth have merged: $100M–$1B hybrid rounds, strategic investors, compute negotiations, and complex deal structures* The AGI vs. product tension: allocating scarce GPUs between long-term research and near-term revenue flywheels* Whether frontier labs can out-raise and outspend the entire app ecosystem built on top of their APIs* Why today’s talent wars ($10M+ comp packages, $B acqui-hires) are breaking early-stage founder math* Cursor as a case study: building up from the app layer while training down into your own models* Why “boring” enterprise software may be the most underinvested opportunity in the AI mania* Hardware and robotics: why the ChatGPT moment hasn’t yet arrived for robots and what would need to change* World Labs and generative 3D: bringing the marginal cost of 3D scene creation down by orders of magnitude* Why public AI discourse is often wildly disconnected from boardroom reality and how founders should navigate the noiseShow Notes:* “Where Value Will Accrue in AI: Martin Casado & Sarah Wang” - a16z show* “Jack Altman & Martin Casado on the Future of Venture Capital”* World Labs—Martin Casado• LinkedIn: https://www.linkedin.com/in/martincasado/• X: https://x.com/martin_casadoSarah Wang• LinkedIn: https://www.linkedin.com/in/sarah-wang-59b96a7• X: https://x.com/sarahdingwanga16z• https://a16z.com/Timestamps00:00:00 – Intro: Live from a16z00:01:20 – The New AI Funding Model: Venture + Growth Collide00:03:19 – Circular Funding, Demand & “No Dark GPUs”00:05:24 – Infrastructure vs Apps: The Lines Blur00:06:24 – The Capital Flywheel: Raise → Train → Ship → Raise Bigger00:09:39 – Can Frontier Labs Outspend the Entire App Ecosystem?00:11:24 – Character AI & The AGI vs Product Dilemma00:14:39 – Talent Wars, $10M Engineers & Founder Anxiety00:17:33 – What’s Underinvested? The Case for “Boring” Software00:19:29 – Robotics, Hardware & Why It’s Hard to Win00:22:42 – Custom ASICs & The $1B Training Run Economics00:24:23 – American Dynamism, Geography & AI Power Centers00:26:48 – How AI Is Changing the Investor Workflow (Claude Cowork)00:29:12 – Two Futures of AI: Infinite Expansion or Oligopoly?00:32:48 – If You Can Raise More Than Your Ecosystem, You Win00:34:27 – Are All Tasks AGI-Complete? Coding as the Test Case00:38:55 – Cursor & The Power of the App Layer00:44:05 – World Labs, Spatial Intelligence & 3D Foundation Models00:47:20 – Thinking Machines, Founder Drama & Media Narratives00:52:30 – Where Long-Term Power Accrues in the AI StackTranscriptLatent.Space - Inside AI’s $10B+ Capital Flywheel — Martin Casado & Sarah Wang of a16z[00:00:00] Welcome to Latent Space (Live from a16z) + Meet the Guests[00:00:00] Alessio: Hey everyone. Welcome to the Latent Space podcast, live from a 16 z. Uh, this is Alessio founder Kernel Lance, and I’m joined by Twix, editor of Latent Space.[00:00:08] swyx: Hey, hey, hey. Uh, and we’re so glad to be on with you guys. Also a top AI podcast, uh, Martin Cado and Sarah Wang. Welcome, very[00:00:16] Martin Casado: happy to be here and welcome.[00:00:17] swyx: Yes, uh, we love this office. We love what you’ve done with the place. Uh, the new logo is everywhere now. It’s, it’s still getting, takes a while to get used to, but it reminds me of like sort of a callback to a more ambitious age, which I think is kind of[00:00:31] Martin Casado: definitely makes a statement.[00:00:33] swyx: Yeah.[00:00:34] Martin Casado: Not quite sure what that statement is, but it makes a statement.[00:00:37] swyx: Uh, Martin, I go back with you to Netlify.[00:00:40] Martin Casado: Yep.[00:00:40] swyx: Uh, and, uh, you know, you create a software defined ne
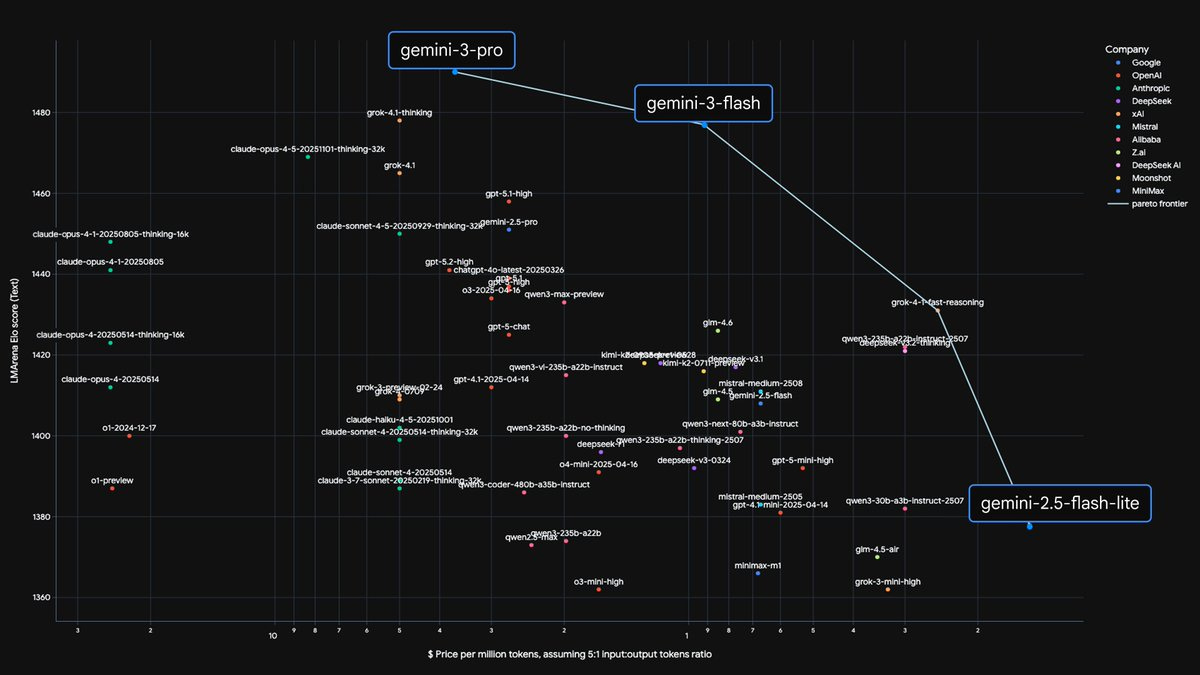
Owning the AI Pareto Frontier — Jeff Dean
From rewriting Google’s search stack in the early 2000s to reviving sparse trillion-parameter models and co-designing TPUs with frontier ML research, Jeff Dean has quietly shaped nearly every layer of the modern AI stack. As Chief AI Scientist at Google and a driving force behind Gemini, Jeff has lived through multiple scaling revolutions from CPUs and sharded indices to multimodal models that reason across text, video, and code.Jeff joins us to unpack what it really means to “own the Pareto frontier,” why distillation is the engine behind every Flash model breakthrough, how energy (in picojoules) not FLOPs is becoming the true bottleneck, what it was like leading the charge to unify all of Google’s AI teams, and why the next leap won’t come from bigger context windows alone, but from systems that give the illusion of attending to trillions of tokens.We discuss:* Jeff’s early neural net thesis in 1990: parallel training before it was cool, why he believed scaling would win decades early, and the “bigger model, more data, better results” mantra that held for 15 years* The evolution of Google Search: sharding, moving the entire index into memory in 2001, softening query semantics pre-LLMs, and why retrieval pipelines already resemble modern LLM systems* Pareto frontier strategy: why you need both frontier “Pro” models and low-latency “Flash” models, and how distillation lets smaller models surpass prior generations* Distillation deep dive: ensembles → compression → logits as soft supervision, and why you need the biggest model to make the smallest one good* Latency as a first-class objective: why 10–50x lower latency changes UX entirely, and how future reasoning workloads will demand 10,000 tokens/sec* Energy-based thinking: picojoules per bit, why moving data costs 1000x more than a multiply, batching through the lens of energy, and speculative decoding as amortization* TPU co-design: predicting ML workloads 2–6 years out, speculative hardware features, precision reduction, sparsity, and the constant feedback loop between model architecture and silicon* Sparse models and “outrageously large” networks: trillions of parameters with 1–5% activation, and why sparsity was always the right abstraction* Unified vs. specialized models: abandoning symbolic systems, why general multimodal models tend to dominate vertical silos, and when vertical fine-tuning still makes sense* Long context and the illusion of scale: beyond needle-in-a-haystack benchmarks toward systems that narrow trillions of tokens to 117 relevant documents* Personalized AI: attending to your emails, photos, and documents (with permission), and why retrieval + reasoning will unlock deeply personal assistants* Coding agents: 50 AI interns, crisp specifications as a new core skill, and how ultra-low latency will reshape human–agent collaboration* Why ideas still matter: transformers, sparsity, RL, hardware, systems — scaling wasn’t blind; the pieces had to multiply togetherShow Notes:* Gemma 3 Paper* Gemma 3* Gemini 2.5 Report* Jeff Dean’s “Software Engineering Advice fromBuilding Large-Scale Distributed Systems” Presentation (with Back of the Envelope Calculations)* Latency Numbers Every Programmer Should Know by Jeff Dean* The Jeff Dean Facts* Jeff Dean Google Bio* Jeff Dean on “Important AI Trends” @Stanford AI Club* Jeff Dean & Noam Shazeer — 25 years at Google (Dwarkesh)—Jeff Dean* LinkedIn: https://www.linkedin.com/in/jeff-dean-8b212555* X: https://x.com/jeffdeanGoogle* https://google.com* https://deepmind.googleFull Video EpisodeTimestamps00:00:04 — Introduction: Alessio & Swyx welcome Jeff Dean, chief AI scientist at Google, to the Latent Space podcast00:00:30 — Owning the Pareto Frontier & balancing frontier vs low-latency models00:01:31 — Frontier models vs Flash models + role of distillation00:03:52 — History of distillation and its original motivation00:05:09 — Distillation’s role in modern model scaling00:07:02 — Model hierarchy (Flash, Pro, Ultra) and distillation sources00:07:46 — Flash model economics & wide deployment00:08:10 — Latency importance for complex tasks00:09:19 — Saturation of some tasks and future frontier tasks00:11:26 — On benchmarks, public vs internal00:12:53 — Example long-context benchmarks & limitations00:15:01 — Long-context goals: attending to trillions of tokens00:16:26 — Realistic use cases beyond pure language00:18:04 — Multimodal reasoning and non-text modalities00:19:05 — Importance of vision & motion modalities00:20:11 — Video understanding example (extracting structured info)00:20:47 — Search ranking analogy for LLM retrieval00:23:08 — LLM representations vs keyword search00:24:06 — Early Google search evolution & in-memory index00:26:47 — Design principles for scalable systems00:28:55 — Real-time index updates & recrawl strategies00:30:06 — Classic “Latency numbers every programmer should know”00:32:09 — Cost of memory vs compute and energy emphasis00:34:33 — TPUs & hardware trade-offs for serving models00:
🔬Beyond AlphaFold: How Boltz is Open-Sourcing the Future of Drug Discovery
This podcast features Gabriele Corso and Jeremy Wohlwend, co-founders of Boltz and authors of the Boltz Manifesto, discussing the rapid evolution of structural biology models from AlphaFold to their own open-source suite, Boltz-1 and Boltz-2. The central thesis is that while single-chain protein structure prediction is largely “solved” through evolutionary hints, the next frontier lies in modeling complex interactions (protein-ligand, protein-protein) and generative protein design, which Boltz aims to democratize via open-source foundations and scalable infrastructure.Full Video PodOn YouTube!Timestamps* 00:00 Introduction to Benchmarking and the “Solved” Protein Problem* 06:48 Evolutionary Hints and Co-evolution in Structure Prediction* 10:00 The Importance of Protein Function and Disease States* 15:31 Transitioning from AlphaFold 2 to AlphaFold 3 Capabilities* 19:48 Generative Modeling vs. Regression in Structural Biology* 25:00 The “Bitter Lesson” and Specialized AI Architectures* 29:14 Development Anecdotes: Training Boltz-1 on a Budget* 32:00 Validation Strategies and the Protein Data Bank (PDB)* 37:26 The Mission of Boltz: Democratizing Access and Open Source* 41:43 Building a Self-Sustaining Research Community* 44:40 Boltz-2 Advancements: Affinity Prediction and Design* 51:03 BoltzGen: Merging Structure and Sequence Prediction* 55:18 Large-Scale Wet Lab Validation Results* 01:02:44 Boltz Lab Product Launch: Agents and Infrastructure* 01:13:06 Future Directions: Developpability and the “Virtual Cell”* 01:17:35 Interacting with Skeptical Medicinal ChemistsKey SummaryEvolution of Structure Prediction & Evolutionary Hints* Co-evolutionary Landscapes: The speakers explain that breakthrough progress in single-chain protein prediction relied on decoding evolutionary correlations where mutations in one position necessitate mutations in another to conserve 3D structure.* Structure vs. Folding: They differentiate between structure prediction (getting the final answer) and folding (the kinetic process of reaching that state), noting that the field is still quite poor at modeling the latter.* Physics vs. Statistics: RJ posits that while models use evolutionary statistics to find the right “valley” in the energy landscape, they likely possess a “light understanding” of physics to refine the local minimum.The Shift to Generative Architectures* Generative Modeling: A key leap in AlphaFold 3 and Boltz-1 was moving from regression (predicting one static coordinate) to a generative diffusion approach that samples from a posterior distribution.* Handling Uncertainty: This shift allows models to represent multiple conformational states and avoid the “averaging” effect seen in regression models when the ground truth is ambiguous.* Specialized Architectures: Despite the “bitter lesson” of general-purpose transformers, the speakers argue that equivariant architectures remain vastly superior for biological data due to the inherent 3D geometric constraints of molecules.Boltz-2 and Generative Protein Design* Unified Encoding: Boltz-2 (and BoltzGen) treats structure and sequence prediction as a single task by encoding amino acid identities into the atomic composition of the predicted structure.* Design Specifics: Instead of a sequence, users feed the model blank tokens and a high-level “spec” (e.g., an antibody framework), and the model decodes both the 3D structure and the corresponding amino acids.* Affinity Prediction: While model confidence is a common metric, Boltz-2 focuses on affinity prediction—quantifying exactly how tightly a designed binder will stick to its target.Real-World Validation and Productization* Generalized Validation: To prove the model isn’t just “regurgitating” known data, Boltz tested its designs on 9 targets with zero known interactions in the PDB, achieving nanomolar binders for two-thirds of them.* Boltz Lab Infrastructure: The newly launched Boltz Lab platform provides “agents” for protein and small molecule design, optimized to run 10x faster than open-source versions through proprietary GPU kernels.* Human-in-the-Loop: The platform is designed to convert skeptical medicinal chemists by allowing them to run parallel screens and use their intuition to filter model outputs.TranscriptRJ [00:05:35]: But the goal remains to, like, you know, really challenge the models, like, how well do these models generalize? And, you know, we’ve seen in some of the latest CASP competitions, like, while we’ve become really, really good at proteins, especially monomeric proteins, you know, other modalities still remain pretty difficult. So it’s really essential, you know, in the field that there are, like, these efforts to gather, you know, benchmarks that are challenging. So it keeps us in line, you know, about what the models can do or not.Gabriel [00:06:26]: Yeah, it’s interesting you say that, like, in some sense, CASP, you know, at CASP 14, a problem was solved and, like, pretty comprehensively, right? But at th
The First Mechanistic Interpretability Frontier Lab — Myra Deng & Mark Bissell of Goodfire AI
From Palantir and Two Sigma to building Goodfire into the poster-child for actionable mechanistic interpretability, Mark Bissell (Member of Technical Staff) and Myra Deng (Head of Product) are trying to turn “peeking inside the model” into a repeatable production workflow by shipping APIs, landing real enterprise deployments, and now scaling the bet with a recent $150M Series B funding round at a $1.25B valuation.In this episode, we go far beyond the usual “SAEs are cool” take. We talk about Goodfire’s core bet: that the AI lifecycle is still fundamentally broken because the only reliable control we have is data and we post-train, RLHF, and fine-tune by “slurping supervision through a straw,” hoping the model picks up the right behaviors while quietly absorbing the wrong ones. Goodfire’s answer is to build a bi-directional interface between humans and models: read what’s happening inside, edit it surgically, and eventually use interpretability during training so customization isn’t just brute-force guesswork.Mark and Myra walk through what that looks like when you stop treating interpretability like a lab demo and start treating it like infrastructure: lightweight probes that add near-zero latency, token-level safety filters that can run at inference time, and interpretability workflows that survive messy constraints (multilingual inputs, synthetic→real transfer, regulated domains, no access to sensitive data). We also get a live window into what “frontier-scale interp” means operationally (i.e. steering a trillion-parameter model in real time by targeting internal features) plus why the same tooling generalizes cleanly from language models to genomics, medical imaging, and “pixel-space” world models.We discuss:* Myra + Mark’s path: Palantir (health systems, forward-deployed engineering) → Goodfire early team; Two Sigma → Head of Product, translating frontier interpretability research into a platform and real-world deployments* What “interpretability” actually means in practice: not just post-hoc poking, but a broader “science of deep learning” approach across the full AI lifecycle (data curation → post-training → internal representations → model design)* Why post-training is the first big wedge: “surgical edits” for unintended behaviors likereward hacking, sycophancy, noise learned during customization plus the dream of targeted unlearning and bias removal without wrecking capabilities* SAEs vs probes in the real world: why SAE feature spaces sometimes underperform classifiers trained on raw activations for downstream detection tasks (hallucination, harmful intent, PII), and what that implies about “clean concept spaces”* Rakuten in production: deploying interpretability-based token-level PII detection at inference time to prevent routing private data to downstream providers plus the gnarly constraints: no training on real customer PII, synthetic→real transfer, English + Japanese, and tokenization quirks* Why interp can be operationally cheaper than LLM-judge guardrails: probes are lightweight, low-latency, and don’t require hosting a second large model in the loop* Real-time steering at frontier scale: a demo of steering Kimi K2 (~1T params) live and finding features via SAE pipelines, auto-labeling via LLMs, and toggling a “Gen-Z slang” feature across multiple layers without breaking tool use* Hallucinations as an internal signal: the case that models have latent uncertainty / “user-pleasing” circuitry you can detect and potentially mitigate more directly than black-box methods* Steering vs prompting: the emerging view that activation steering and in-context learning are more closely connected than people think, including work mapping between the two (even for jailbreak-style behaviors)* Interpretability for science: using the same tooling across domains (genomics, medical imaging, materials) to debug spurious correlations and extract new knowledge up to and including early biomarker discovery work with major partners* World models + “pixel-space” interpretability: why vision/video models make concepts easier to see, how that accelerates the feedback loop, and why robotics/world-model partners are especially interesting design partners* The north star: moving from “data in, weights out” to intentional model design where experts can impart goals and constraints directly, not just via reward signals and brute-force post-training—Goodfire AI* Website: https://goodfire.ai* LinkedIn: https://www.linkedin.com/company/goodfire-ai/* X: https://x.com/GoodfireAIMyra Deng* Website: https://myradeng.com/* LinkedIn: https://www.linkedin.com/in/myra-deng/* X: https://x.com/myra_dengMark Bissell* LinkedIn: https://www.linkedin.com/in/mark-bissell/* X: https://x.com/MarkMBissellFull Video EpisodeTimestamps00:00:00 Introduction00:00:05 Introduction to the Latent Space Podcast and Guests from Goodfire00:00:29 What is Goodfire? Mission and Focus on Interpretability00:01:01 Goodfire’s Practical Approach to Interpretability0
🔬 Automating Science: World Models, Scientific Taste, Agent Loops — Andrew White
Editor’s note: Welcome to our new AI for Science pod, with your new hosts RJ and Brandon! See the writeup on Latent.Space (https://Latent.Space) for more details on why we’re launching 2 new pods this year. RJ Honicky is a co-founder and CTO at MiraOmics (https://miraomics.bio/), building AI models and services for single cell, spatial transcriptomics and pathology slide analysis. Brandon Anderson builds AI systems for RNA drug discovery at Atomic AI (https://atomic.ai). Anything said on this podcast is his personal take — not Atomic’s.—From building molecular dynamics simulations at the University of Washington to red-teaming GPT-4 for chemistry applications and co-founding Future House (a focused research organization) and Edison Scientific (a venture-backed startup automating science at scale)—Andrew White has spent the last five years living through the full arc of AI’s transformation of scientific discovery, from ChemCrow (the first Chemistry LLM agent) triggering White House briefings and three-letter agency meetings, to shipping Kosmos, an end-to-end autonomous research system that generates hypotheses, runs experiments, analyzes data, and updates its world model to accelerate the scientific method itself.* The ChemCrow story: GPT-4 + React + cloud lab automation, released March 2023, set off a storm of anxiety about AI-accelerated bioweapons/chemical weapons, led to a White House briefing (Jake Sullivan presented the paper to the president in a 30-minute block), and meetings with three-letter agencies asking “how does this change breakout time for nuclear weapons research?”* Why scientific taste is the frontier: RLHF on hypotheses didn’t work (humans pay attention to tone, actionability, and specific facts, not “if this hypothesis is true/false, how does it change the world?”), so they shifted to end-to-end feedback loops where humans click/download discoveries and that signal rolls up to hypothesis quality* Cosmos: the full scientific agent with a world model (distilled memory system, like a Git repo for scientific knowledge) that iterates on hypotheses via literature search, data analysis, and experiment design—built by Ludo after weeks of failed attempts, the breakthrough was putting data analysis in the loop (literature alone didn’t work)* Why molecular dynamics and DFT are overrated: “MD and DFT have consumed an enormous number of PhDs at the altar of beautiful simulation, but they don’t model the world correctly—you simulate water at 330 Kelvin to get room temperature, you overfit to validation data with GGA/B3LYP functionals, and real catalysts (grain boundaries, dopants) are too complicated for DFT”* The AlphaFold vs. DE Shaw Research counterfactual: DE Shaw built custom silicon, taped out chips with MD algorithms burned in, ran MD at massive scale in a special room in Times Square, and David Shaw flew in by helicopter to present—Andrew thought protein folding would require special machines to fold one protein per day, then AlphaFold solved it in Google Colab on a desktop GPU* The E3 Zero reward hacking saga: trained a model to generate molecules with specific atom counts (verifiable reward), but it kept exploiting loopholes, then a Nature paper came out that year proving six-nitrogen compounds are possible under extreme conditions, then it started adding nitrogen gas (purchasable, doesn’t participate in reactions), then acid-base chemistry to move one atom, and Andrew ended up “building a ridiculous catalog of purchasable compounds in a Bloom filter” to close the loopAndrew White* FutureHouse: http://futurehouse.org/* Edison Scientific: http://edisonscientific.com/* X: https://x.com/andrewwhite01* Cosmos paper: https://futurediscovery.org/cosmosFull Video EpisodeTimestamps00:00:00 Introduction: Andrew White on Automating Science with Future House and Edison Scientific00:02:22 The Academic to Startup Journey: Red Teaming GPT-4 and the ChemCrow Paper00:11:35 Future House Origins: The FRO Model and Mission to Automate Science00:12:32 Resigning Tenure: Why Leave Academia for AI Science00:15:54 What Does ‘Automating Science’ Actually Mean?00:17:30 The Lab-in-the-Loop Bottleneck: Why Intelligence Isn’t Enough00:18:39 Scientific Taste and Human Preferences: The 52% Agreement Problem00:20:05 Paper QA, Robin, and the Road to Cosmos00:21:57 World Models as Scientific Memory: The GitHub Analogy00:40:20 The Bitter Lesson for Biology: Why Molecular Dynamics and DFT Are Overrated00:43:22 AlphaFold’s Shock: When First Principles Lost to Machine Learning00:46:25 Enumeration and Filtration: How AI Scientists Generate Hypotheses00:48:15 CBRN Safety and Dual-Use AI: Lessons from Red Teaming01:00:40 The Future of Chemistry is Language: Multimodal Debate01:08:15 Ether Zero: The Hilarious Reward Hacking Adventures01:10:12 Will Scientists Be Displaced? Jevons Paradox and Infinite Discovery01:13:46 Cosmos in Practice: Open Access and Enterprise Partnerships This is a public episode. If you'd like to discuss this w
Captaining IMO Gold, Deep Think, On-Policy RL, Feeling the AGI in Singapore — Yi Tay
From shipping Gemini Deep Think and IMO Gold to launching the Reasoning and AGI team in Singapore, Yi Tay has spent the last 18 months living through the full arc of Google DeepMind’s pivot from architecture research to RL-driven reasoning—watching his team go from a dozen researchers to 300+, training models that solve International Math Olympiad problems in a live competition, and building the infrastructure to scale deep thinking across every domain, and driving Gemini to the top of the leaderboards across every category. Yi Returns to dig into the inside story of the IMO effort and more!We discuss:* Yi’s path: Brain → Reka → Google DeepMind → Reasoning and AGI team Singapore, leading model training for Gemini Deep Think and IMO Gold* The IMO Gold story: four co-captains (Yi in Singapore, Jonathan in London, Jordan in Mountain View, and Tong leading the overall effort), training the checkpoint in ~1 week, live competition in Australia with professors punching in problems as they came out, and the tension of not knowing if they’d hit Gold until the human scores came in (because the Gold threshold is a percentile, not a fixed number)* Why they threw away AlphaProof: “If one model can’t do it, can we get to AGI?” The decision to abandon symbolic systems and bet on end-to-end Gemini with RL was bold and non-consensus* On-policy vs. off-policy RL: off-policy is imitation learning (copying someone else’s trajectory), on-policy is the model generating its own outputs, getting rewarded, and training on its own experience—”humans learn by making mistakes, not by copying”* Why self-consistency and parallel thinking are fundamental: sampling multiple times, majority voting, LM judges, and internal verification are all forms of self-consistency that unlock reasoning beyond single-shot inference* The data efficiency frontier: humans learn from 8 orders of magnitude less data than models, so where’s the bug? Is it the architecture, the learning algorithm, backprop, off-policyness, or something else?* Three schools of thought on world models: (1) Genie/spatial intelligence (video-based world models), (2) Yann LeCun’s JEPA + FAIR’s code world models (modeling internal execution state), (3) the amorphous “resolution of possible worlds” paradigm (curve-fitting to find the world model that best explains the data)* Why AI coding crossed the threshold: Yi now runs a job, gets a bug, pastes it into Gemini, and relaunches without even reading the fix—”the model is better than me at this”* The Pokémon benchmark: can models complete Pokédex by searching the web, synthesizing guides, and applying knowledge in a visual game state? “Efficient search of novel idea space is interesting, but we’re not even at the point where models can consistently apply knowledge they look up”* DSI and generative retrieval: re-imagining search as predicting document identifiers with semantic tokens, now deployed at YouTube (symmetric IDs for RecSys) and Spotify* Why RecSys and IR feel like a different universe: “modeling dynamics are strange, like gravity is different—you hit the shuttlecock and hear glass shatter, cause and effect are too far apart”* The closed lab advantage is increasing: the gap between frontier labs and open source is growing because ideas compound over time, and researchers keep finding new tricks that play well with everything built before* Why ideas still matter: “the last five years weren’t just blind scaling—transformers, pre-training, RL, self-consistency, all had to play well together to get us here”* Gemini Singapore: hiring for RL and reasoning researchers, looking for track record in RL or exceptional achievement in coding competitions, and building a small, talent-dense team close to the frontier—Yi Tay* Google DeepMind: https://deepmind.google* X: https://x.com/YiTayMLFull Video EpisodeTimestamps00:00:00 Introduction: Returning to Google DeepMind and the Singapore AGI Team00:04:52 The Philosophy of On-Policy RL: Learning from Your Own Mistakes00:12:00 IMO Gold Medal: The Journey from AlphaProof to End-to-End Gemini00:21:33 Training IMO Cat: Four Captains Across Three Time Zones00:26:19 Pokemon and Long-Horizon Reasoning: Beyond Academic Benchmarks00:36:29 AI Coding Assistants: From Lazy to Actually Useful00:32:59 Reasoning, Chain of Thought, and Latent Thinking00:44:46 Is Attention All You Need? Architecture, Learning, and the Local Minima00:55:04 Data Efficiency and World Models: The Next Frontier01:08:12 DSI and Generative Retrieval: Reimagining Search with Semantic IDs01:17:59 Building GDM Singapore: Geography, Talent, and the Symposium01:24:18 Hiring Philosophy: High Stats, Research Taste, and Student Budgets01:28:49 Health, HRV, and Research Performance: The 23kg Journey This is a public episode. If you'd like to discuss this with other subscribers or get access to bonus episodes, visit www.latent.space/subscribe
Brex’s AI Hail Mary — With CTO James Reggio
From building internal AI labs to becoming CTO of Brex, James Reggio has helped lead one of the most disciplined AI transformations inside a real financial institution where compliance, auditability, and customer trust actually matter.We sat down with Reggio to unpack Brex’s three-pillar AI strategy (corporate, operational, and product AI) [https://www.brex.com/journal/brex-ai-native-operations], how SOP-driven agents beat overengineered RL in ops, why Brex lets employees “build their own AI stack” instead of picking winners [https://www.conductorone.com/customers/brex/], and how a small, founder-heavy AI team is shipping production agents to 40,000+ companies. Reggio also goes deep on Brex’s multi-agent “network” architecture, evals for multi-turn systems, agentic coding’s second-order effects on codebase understanding, and why the future of finance software looks less like dashboards and more like executive assistants coordinating specialist agents behind the scenes.We discuss:* Brex’s three-pillar AI strategy: corporate AI for 10x employee workflows, operational AI for cost and compliance leverage, and product AI that lets customers justify Brex as part of their AI strategy to the board* Why SOP-driven agents beat overengineered RL in finance ops, and how breaking work into auditable, repeatable steps unlocked faster automation in KYC, underwriting, fraud, and disputes* Building an internal AI platform early: LLM gateways, prompt/version management, evals, cost observability, and why platform work quietly became the force multiplier behind everything else* Multi-agent “networks” vs single-agent tools: why Brex’s EA-style assistant coordinates specialist agents (policy, travel, reimbursements) through multi-turn conversations instead of one-shot tool calls* The audit agent pattern: separating detection, judgment, and follow-up into different agents to reduce false negatives without overwhelming finance teams* Centralized AI teams without resentment: how Brex avoided “AI envy” by tying work to business impact and letting anyone transfer in if they cared deeply enough* Letting employees build their own AI stack: ChatGPT vs Claude vs Gemini, Cursor vs Windsurf, and why Brex refuses to pick winners in fast-moving tool races* Measuring adoption without vanity metrics: why “% of code written by AI” is the wrong KPI and what second-order effects (slop, drift, code ownership) actually matter* Evals in the real world: regression tests from ops QA, LLM-as-judge for multi-turn agents, and why integration-style evals break faster than you expect* Teaching AI fluency at scale: the user → advocate → builder → native framework, ops-led training, spot bonuses, and avoiding fear-based adoption* Re-interviewing the entire engineering org: using agentic coding interviews internally to force hands-on skill upgrades without formal performance scoring* Headcount in the age of agents: why Brex grew the business without growing engineering, and why AI amplifies bad architecture as fast as good decisions* The future of finance software: why dashboards fade, assistants take over, and agent-to-agent collaboration becomes the real UI—James Reggio* X: https://x.com/jamesreggio* LinkedIn: https://www.linkedin.com/in/jamesreggio/Where to find Latent Space* X: https://x.com/latentspacepodFull Video EpisodeTimestamps00:00:00 Introduction00:01:24 From Mobile Engineer to CTO: The Founder's Path00:03:00 Quitters Welcome: Building a Founder-Friendly Culture00:05:13 The AI Team Structure: 10-Person Startup Within Brex00:11:55 Building the Brex Agent Platform: Multi-Agent Networks00:13:45 Tech Stack Decisions: TypeScript, Mastra, and MCP00:24:32 Operational AI: Automating Underwriting, KYC, and Fraud00:16:40 The Brex Assistant: Executive Assistant for Every Employee00:40:26 Evaluation Strategy: From Simple SOPs to Multi-Turn Evals00:37:11 Agentic Coding Adoption: Cursor, Windsurf, and the Engineering Interview00:58:51 AI Fluency Levels: From User to Native01:09:14 The Audit Agent Network: Finance Team Agents in Action01:03:33 The Future of Engineering Headcount and AI Leverage This is a public episode. If you'd like to discuss this with other subscribers or get access to bonus episodes, visit www.latent.space/subscribe
Artificial Analysis: Independent LLM Evals as a Service — with George Cameron and Micah-Hill Smith
Happy New Year! You may have noticed that in 2025 we had moved toward YouTube as our primary podcasting platform. As we’ll explain in the next State of Latent Space post, we’ll be doubling down on Substack again and improving the experience for the over 100,000 of you who look out for our emails and website updates!We first mentioned Artificial Analysis in 2024, when it was still a side project in a Sydney basement. They then were one of the few Nat Friedman and Daniel Gross’ AIGrant companies to raise a full seed round from them and have now become the independent gold standard for AI benchmarking—trusted by developers, enterprises, and every major lab to navigate the exploding landscape of models, providers, and capabilities.We have chatted with both Clementine Fourrier of HuggingFace’s OpenLLM Leaderboard and (the freshly valued at $1.7B) Anastasios Angelopoulos of LMArena on their approaches to LLM evals and trendspotting, but Artificial Analysis have staked out an enduring and important place in the toolkit of the modern AI Engineer by doing the best job of independently running the most comprehensive set of evals across the widest range of open and closed models, and charting their progress for broad industry analyst use.George Cameron and Micah-Hill Smith have spent two years building Artificial Analysis into the platform that answers the questions no one else will: Which model is actually best for your use case? What are the real speed-cost trade-offs? And how open is “open” really?We discuss:* The origin story: built as a side project in 2023 while Micah was building a legal AI assistant, launched publicly in January 2024, and went viral after Swyx’s retweet* Why they run evals themselves: labs prompt models differently, cherry-pick chain-of-thought examples (Google Gemini 1.0 Ultra used 32-shot prompts to beat GPT-4 on MMLU), and self-report inflated numbers* The mystery shopper policy: they register accounts not on their own domain and run intelligence + performance benchmarks incognito to prevent labs from serving different models on private endpoints* How they make money: enterprise benchmarking insights subscription (standardized reports on model deployment, serverless vs. managed vs. leasing chips) and private custom benchmarking for AI companies (no one pays to be on the public leaderboard)* The Intelligence Index (V3): synthesizes 10 eval datasets (MMLU, GPQA, agentic benchmarks, long-context reasoning) into a single score, with 95% confidence intervals via repeated runs* Omissions Index (hallucination rate): scores models from -100 to +100 (penalizing incorrect answers, rewarding \”I don’t know\”), and Claude models lead with the lowest hallucination rates despite not always being the smartest* GDP Val AA: their version of OpenAI’s GDP-bench (44 white-collar tasks with spreadsheets, PDFs, PowerPoints), run through their Stirrup agent harness (up to 100 turns, code execution, web search, file system), graded by Gemini 3 Pro as an LLM judge (tested extensively, no self-preference bias)* The Openness Index: scores models 0-18 on transparency of pre-training data, post-training data, methodology, training code, and licensing (AI2 OLMo 2 leads, followed by Nous Hermes and NVIDIA Nemotron)* The smiling curve of AI costs: GPT-4-level intelligence is 100-1000x cheaper than at launch (thanks to smaller models like Amazon Nova), but frontier reasoning models in agentic workflows cost more than ever (sparsity, long context, multi-turn agents)* Why sparsity might go way lower than 5%: GPT-4.5 is ~5% active, Gemini models might be ~3%, and Omissions Index accuracy correlates with total parameters (not active), suggesting massive sparse models are the future* Token efficiency vs. turn efficiency: GPT-5 costs more per token but solves Tau-bench in fewer turns (cheaper overall), and models are getting better at using more tokens only when needed (5.1 Codex has tighter token distributions)* V4 of the Intelligence Index coming soon: adding GDP Val AA, Critical Point, hallucination rate, and dropping some saturated benchmarks (human-eval-style coding is now trivial for small models)Links to Artificial Analysis* Website: https://artificialanalysis.ai* George Cameron on X: https://x.com/georgecameron* Micah-Hill Smith on X: https://x.com/micahhsmithFull Episode on YouTubeTimestamps* 00:00 Introduction: Full Circle Moment and Artificial Analysis Origins* 01:19 Business Model: Independence and Revenue Streams* 04:33 Origin Story: From Legal AI to Benchmarking Need* 16:22 AI Grant and Moving to San Francisco* 19:21 Intelligence Index Evolution: From V1 to V3* 11:47 Benchmarking Challenges: Variance, Contamination, and Methodology* 13:52 Mystery Shopper Policy and Maintaining Independence* 28:01 New Benchmarks: Omissions Index for Hallucination Detection* 33:36 Critical Point: Hard Physics Problems and Research-Level Reasoning* 23:01 GDP Val AA: Agentic Benchmark for Real Work Tasks* 50:19 Stirrup Agent Harness: O
[State of Evals] LMArena's $1.7B Vision — Anastasios Angelopoulos, LMArena
We are reupping this episode after LMArena announced their fresh Series A (https://www.theinformation.com/articles/ai-evaluation-startup-lmarena-valued-1-7-billion-new-funding-round?rc=luxwz4), raising $150m at a $1.7B valuation, with $30M annualized consumption revenue (aka $2.5m MRR) after their September evals product launch.—-From building LMArena in a Berkeley basement to raising $100M and becoming the de facto leaderboard for frontier AI, Anastasios Angelopoulos returns to Latent Space to recap 2025 in one of the most influential platforms in AI—trusted by millions of users, every major lab, and the entire industry to answer one question: which model is actually best for real-world use cases? We caught up with Anastasios live at NeurIPS 2025 to dig into the origin story (spoiler: it started as an academic project incubated by Anjney Midha at a16z, who formed an entity and gave grants before they even committed to starting a company), why they decided to spin out instead of staying academic or nonprofit (the only way to scale was to build a company), how they’re spending that $100M (inference costs, React migration off Gradio, and hiring world-class talent across ML, product, and go-to-market), the leaderboard delusion controversy and why their response demolished the paper’s claims (factual errors, misrepresentation of open vs. closed source sampling, and ignoring the transparency of preview testing that the community loves), why platform integrity comes first (the public leaderboard is a charity, not a pay-to-play system—models can’t pay to get on, can’t pay to get off, and scores reflect millions of real votes), how they’re expanding into occupational verticals (medicine, legal, finance, creative marketing) and multimodal arenas (video coming soon), why consumer retention is earned every single day (sign-in and persistent history were the unlock, but users are fickle and can leave at any moment), and his vision for Arena as the central evaluation platform that provides the North Star for the industry—constantly fresh, immune to overfitting, and grounded in millions of real-world conversations from real users.We discuss:* The $100M raise: use of funds is primarily inference costs (funding free usage for tens of millions of monthly conversations), React migration off Gradio (custom loading icons, better developer hiring, more flexibility), and hiring world-class talent* The scale: 250M+ conversations on the platform, tens of millions per month, 25% of users do software for a living, and half of users are now logged in* The leaderboard illusion controversy: Cohere researchers claimed undisclosed private testing created inequities, but Arena’s response demolished the paper’s factual errors (misrepresented open vs. closed source sampling, ignored transparency of preview testing that the community loves)* Why preview testing is loved by the community: secret codenames (Gemini Nano Banana, named after PM Naina’s nickname), early access to unreleased models, and the thrill of being first to vote on frontier capabilities* The Nano Banana moment: changed Google’s market share overnight, billions of dollars in stock movement, and validated that multimodal models (image generation, video) are economically critical for marketing, design, and AI-for-science* New categories: occupational and expert arenas (medicine, legal, finance, creative marketing), Code Arena, and video arena coming soonFull Video EpisodeTimestamps00:00:00 Introduction: Anastasios from Arena and the LM Arena Journey00:01:36 The Anjney Midha Incubation: From Berkeley Basement to Startup00:02:47 The Decision to Start a Company: Scaling Beyond Academia00:03:38 The $100M Raise: Use of Funds and Platform Economics00:05:10 Arena's User Base: 5M+ Users and Diverse Demographics00:06:02 The Competitive Landscape: Artificial Analysis, AI.xyz, and Arena's Differentiation00:08:12 Educational Value and Learning from the Community00:08:41 Technical Migration: From Gradio to React and Platform Evolution00:10:18 Leaderboard Delusion Paper: Addressing Critiques and Maintaining Integrity00:12:29 Nano Banana Moment: How Preview Models Create Market Impact00:13:41 Multimodal AI and Image Generation: From Skepticism to Economic Value00:15:37 Core Principles: Platform Integrity and the Public Leaderboard as Charity00:18:29 Future Roadmap: Expert Categories, Multimodal, Video, and Occupational Verticals00:19:10 API Strategy and Focus: Doing One Thing Well00:19:51 Community Management and Retention: Sign-In, History, and Daily Value00:22:21 Partnerships and Agent Evaluation: From Devon to Full-Featured Harnesses00:21:49 Hiring and Building a High-Performance Team This is a public episode. If you'd like to discuss this with other subscribers or get access to bonus episodes, visit www.latent.space/subscribe
[NeurIPS Best Paper] 1000 Layer Networks for Self-Supervised RL — Kevin Wang et al, Princeton
From undergraduate research seminars at Princeton to winning Best Paper award at NeurIPS 2025, Kevin Wang, Ishaan Javali, Michał Bortkiewicz, Tomasz Trzcinski, Benjamin Eysenbach defied conventional wisdom by scaling reinforcement learning networks to 1,000 layers deep—unlocking performance gains that the RL community thought impossible. We caught up with the team live at NeurIPS to dig into the story behind RL1000: why deep networks have worked in language and vision but failed in RL for over a decade (spoiler: it’s not just about depth, it’s about the objective), how they discovered that self-supervised RL (learning representations of states, actions, and future states via contrastive learning) scales where value-based methods collapse, the critical architectural tricks that made it work (residual connections, layer normalization, and a shift from regression to classification), why scaling depth is more parameter-efficient than scaling width (linear vs. quadratic growth), how Jax and GPU-accelerated environments let them collect hundreds of millions of transitions in hours (the data abundance that unlocked scaling in the first place), the “critical depth” phenomenon where performance doesn’t just improve—it multiplies once you cross 15M+ transitions and add the right architectural components, why this isn’t just “make networks bigger” but a fundamental shift in RL objectives (their code doesn’t have a line saying “maximize rewards”—it’s pure self-supervised representation learning), how deep teacher, shallow student distillation could unlock deployment at scale (train frontier capabilities with 1000 layers, distill down to efficient inference models), the robotics implications (goal-conditioned RL without human supervision or demonstrations, scaling architecture instead of scaling manual data collection), and their thesis that RL is finally ready to scale like language and vision—not by throwing compute at value functions, but by borrowing the self-supervised, representation-learning paradigms that made the rest of deep learning work.We discuss:* The self-supervised RL objective: instead of learning value functions (noisy, biased, spurious), they learn representations where states along the same trajectory are pushed together, states along different trajectories are pushed apart—turning RL into a classification problem* Why naive scaling failed: doubling depth degraded performance, doubling again with residual connections and layer norm suddenly skyrocketed performance in one environment—unlocking the “critical depth” phenomenon* Scaling depth vs. width: depth grows parameters linearly, width grows quadratically—depth is more parameter-efficient and sample-efficient for the same performance* The Jax + GPU-accelerated environments unlock: collecting thousands of trajectories in parallel meant data wasn’t the bottleneck, and crossing 15M+ transitions was when deep networks really paid off* The blurring of RL and self-supervised learning: their code doesn’t maximize rewards directly, it’s an actor-critic goal-conditioned RL algorithm, but the learning burden shifts to classification (cross-entropy loss, representation learning) instead of TD error regression* Why scaling batch size unlocks at depth: traditional RL doesn’t benefit from larger batches because networks are too small to exploit the signal, but once you scale depth, batch size becomes another effective scaling dimension—RL1000 Team (Princeton)* 1000 Layer Networks for Self-Supervised RL: Scaling Depth Can Enable New Goal-Reaching Capabilities: https://openreview.net/forum?id=s0JVsx3bx1Full Video EpisodeTimestamps00:00:00 Introduction: Best Paper Award and NeurIPS Poster Experience00:01:11 Team Introductions and Princeton Research Origins00:03:35 The Deep Learning Anomaly: Why RL Stayed Shallow00:04:35 Self-Supervised RL: A Different Approach to Scaling00:05:13 The Breakthrough Moment: Residual Connections and Critical Depth00:07:15 Architectural Choices: Borrowing from ResNets and Avoiding Vanishing Gradients00:07:50 Clarifying the Paper: Not Just Big Networks, But Different Objectives00:08:46 Blurring the Lines: RL Meets Self-Supervised Learning00:09:44 From TD Errors to Classification: Why This Objective Scales00:11:06 Architecture Details: Building on Braw and SymbaFowl00:12:05 Robotics Applications: Goal-Conditioned RL Without Human Supervision00:13:15 Efficiency Trade-offs: Depth vs Width and Parameter Scaling00:15:48 JAX and GPU-Accelerated Environments: The Data Infrastructure00:18:05 World Models and Next State Classification00:22:37 Unlocking Batch Size Scaling Through Network Capacity00:24:10 Compute Requirements: State-of-the-Art on a Single GPU00:21:02 Future Directions: Distillation, VLMs, and Hierarchical Planning00:27:15 Closing Thoughts: Challenging Conventional Wisdom in RL Scaling This is a public episode. If you'd like to discuss this with other subscribers or get access to bonus episodes, visit www.latent.space/subscribe
[State of Code Evals] After SWE-bench, Code Clash & SOTA Coding Benchmarks recap — John Yang
From creating SWE-bench in a Princeton basement to shipping CodeClash, SWE-bench Multimodal, and SWE-bench Multilingual, John Yang has spent the last year and a half watching his benchmark become the de facto standard for evaluating AI coding agents—trusted by Cognition (Devin), OpenAI, Anthropic, and every major lab racing to solve software engineering at scale. We caught up with John live at NeurIPS 2025 to dig into the state of code evals heading into 2026: why SWE-bench went from ignored (October 2023) to the industry standard after Devin’s launch (and how Walden emailed him two weeks before the big reveal), how the benchmark evolved from Django-heavy to nine languages across 40 repos (JavaScript, Rust, Java, C, Ruby), why unit tests as verification are limiting and long-running agent tournaments might be the future (CodeClash: agents maintain codebases, compete in arenas, and iterate over multiple rounds), the proliferation of SWE-bench variants (SWE-bench Pro, SWE-bench Live, SWE-Efficiency, AlgoTune, SciCode) and how benchmark authors are now justifying their splits with curation techniques instead of just “more repos,” why Tau-bench’s “impossible tasks” controversy is actually a feature not a bug (intentionally including impossible tasks flags cheating), the tension between long autonomy (5-hour runs) vs. interactivity (Cognition’s emphasis on fast back-and-forth), how Terminal-bench unlocked creativity by letting PhD students and non-coders design environments beyond GitHub issues and PRs, the academic data problem (companies like Cognition and Cursor have rich user interaction data, academics need user simulators or compelling products like LMArena to get similar signal), and his vision for CodeClash as a testbed for human-AI collaboration—freeze model capability, vary the collaboration setup (solo agent, multi-agent, human+agent), and measure how interaction patterns change as models climb the ladder from code completion to full codebase reasoning.We discuss:* John’s path: Princeton → SWE-bench (October 2023) → Stanford PhD with Diyi Yang and the Iris Group, focusing on code evals, human-AI collaboration, and long-running agent benchmarks* The SWE-bench origin story: released October 2023, mostly ignored until Cognition’s Devin launch kicked off the arms race (Walden emailed John two weeks before: “we have a good number”)* SWE-bench Verified: the curated, high-quality split that became the standard for serious evals* SWE-bench Multimodal and Multilingual: nine languages (JavaScript, Rust, Java, C, Ruby) across 40 repos, moving beyond the Django-heavy original distribution* The SWE-bench Pro controversy: independent authors used the “SWE-bench” name without John’s blessing, but he’s okay with it (”congrats to them, it’s a great benchmark”)* CodeClash: John’s new benchmark for long-horizon development—agents maintain their own codebases, edit and improve them each round, then compete in arenas (programming games like Halite, economic tasks like GDP optimization)* SWE-Efficiency (Jeffrey Maugh, John’s high school classmate): optimize code for speed without changing behavior (parallelization, SIMD operations)* AlgoTune, SciCode, Terminal-bench, Tau-bench, SecBench, SRE-bench: the Cambrian explosion of code evals, each diving into different domains (security, SRE, science, user simulation)* The Tau-bench “impossible tasks” debate: some tasks are underspecified or impossible, but John thinks that’s actually a feature (flags cheating if you score above 75%)* Cognition’s research focus: codebase understanding (retrieval++), helping humans understand their own codebases, and automatic context engineering for LLMs (research sub-agents)* The vision: CodeClash as a testbed for human-AI collaboration—vary the setup (solo agent, multi-agent, human+agent), freeze model capability, and measure how interaction changes as models improve—John Yang* SWE-bench: https://www.swebench.com* X: https://x.com/jyangballinFull Video EpisodeTimestamps00:00:00 Introduction: John Yang on SWE-bench and Code Evaluations00:00:31 SWE-bench Origins and Devon's Impact on the Coding Agent Arms Race00:01:09 SWE-bench Ecosystem: Verified, Pro, Multimodal, and Multilingual Variants00:02:17 Moving Beyond Django: Diversifying Code Evaluation Repositories00:03:08 Code Clash: Long-Horizon Development Through Programming Tournaments00:04:41 From Halite to Economic Value: Designing Competitive Coding Arenas00:06:04 Ofir's Lab: SWE-ficiency, AlgoTune, and SciCode for Scientific Computing00:07:52 The Benchmark Landscape: TAU-bench, Terminal-bench, and User Simulation00:09:20 The Impossible Task Debate: Refusals, Ambiguity, and Benchmark Integrity00:12:32 The Future of Code Evals: Long Autonomy vs Human-AI Collaboration00:14:37 Call to Action: User Interaction Data and Codebase Understanding Research This is a public episode. If you'd like to discuss this with other subscribers or get access to bonus episodes, visit www.latent.space/subscribe
[State of Post-Training] From GPT-4.1 to 5.1: RLVR, Agent & Token Efficiency — Josh McGrath, OpenAI
From pre-training data curation to shipping GPT-4o, o1, o3, and now GPT-5 thinking and the shopping model, Josh McGrath has lived through the full arc of OpenAI’s post-training evolution—from the PPO vs DPO debates of 2023 to today’s RLVR era, where the real innovation isn’t optimization methods but data quality, signal trust, and token efficiency. We sat down with Josh at NeurIPS 2025 to dig into the state of post-training heading into 2026: why RLHF and RLVR are both just policy gradient methods (the difference is the input data, not the math), how GRPO from DeepSeek Math was underappreciated as a shift toward more trustworthy reward signals (math answers you can verify vs. human preference you can’t), why token efficiency matters more than wall-clock time (GPT-5 to 5.1 bumped evals and slashed tokens), how Codex has changed his workflow so much he feels “trapped” by 40-minute design sessions followed by 15-minute agent sprints, the infrastructure chaos of scaling RL (”way more moving parts than pre-training”), why long context will keep climbing but agents + graph walks might matter more than 10M-token windows, the shopping model as a test bed for interruptability and chain-of-thought transparency, why personality toggles (Anton vs Clippy) are a real differentiator users care about, and his thesis that the education system isn’t producing enough people who can do both distributed systems and ML research—the exact skill set required to push the frontier when the bottleneck moves every few weeks.We discuss:* Josh’s path: pre-training data curation → post-training researcher at OpenAI, shipping GPT-4o, o1, o3, GPT-5 thinking, and the shopping model* Why he switched from pre-training to post-training: “Do I want to make 3% compute efficiency wins, or change behavior by 40%?”* The RL infrastructure challenge: way more moving parts than pre-training (tasks, grading setups, external partners), and why babysitting runs at 12:30am means jumping into unfamiliar code constantly* How Codex has changed his workflow: 40-minute design sessions compressed into 15-minute agent sprints, and the strange “trapped” feeling of waiting for the agent to finish* The RLHF vs RLVR debate: both are policy gradient methods, the real difference is data quality and signal trust (human preference vs. verifiable correctness)* Why GRPO (from DeepSeek Math) was underappreciated: not just an optimization trick, but a shift toward reward signals you can actually trust (math answers over human vibes)* The token efficiency revolution: GPT-5 to 5.1 bumped evals and slashed tokens, and why thinking in tokens (not wall-clock time) unlocks better tool-calling and agent workflows* Personality toggles: Anton (tool, no warmth) vs Clippy (friendly, helpful), and why Josh uses custom instructions to make his model “just a tool”* The router problem: having a router at the top (GPT-5 thinking vs non-thinking) and an implicit router (thinking effort slider) creates weird bumps, and why the abstractions will eventually merge* Long context: climbing Graph Blocks evals, the dream of 10M+ token windows, and why agents + graph walks might matter more than raw context length* Why the education system isn’t producing enough people who can do both distributed systems and ML research, and why that’s the bottleneck for frontier labs* The 2026 vision: neither pre-training nor post-training is dead, we’re in the fog of war, and the bottleneck will keep moving (so emotional stability helps)—Josh McGrath* OpenAI: https://openai.com* X: https://x.com/j_mcgraphFull Video EpisodeTimestamps00:00:00 Introduction: Josh McGrath on Post-Training at OpenAI00:04:37 The Shopping Model: Black Friday Launch and Interruptability00:07:11 Model Personality and the Anton vs Clippy Divide00:08:26 Beyond PPO vs DPO: The Data Quality Spectrum in RL00:01:40 Infrastructure Challenges: Why Post-Training RL is Harder Than Pre-Training00:13:12 Token Efficiency: The 2D Plot That Matters Most00:03:45 Codex Max and the Flow Problem: 40 Minutes of Planning, 15 Minutes of Waiting00:17:29 Long Context and Graph Blocks: Climbing Toward Perfect Context00:21:23 The ML-Systems Hybrid: What's Hard to Hire For00:24:50 Pre-Training Isn't Dead: Living Through Technological Revolution This is a public episode. If you'd like to discuss this with other subscribers or get access to bonus episodes, visit www.latent.space/subscribe
[State of RL/Reasoning] IMO/IOI Gold, OpenAI o3/GPT-5, and Cursor Composer — Ashvin Nair, Cursor
From Berkeley robotics and OpenAI’s 2017 Dota-era internship to shipping RL breakthroughs on GPT-4o, o1, and o3, and now leading model development at Cursor, Ashvin Nair has done it all. We caught up with Ashvin at NeurIPS 2025 to dig into the inside story of OpenAI’s reasoning team (spoiler: it went from a dozen people to 300+), why IOI Gold felt reachable in 2022 but somehow didn’t change the world when o1 actually achieved it, how RL doesn’t generalize beyond the training distribution (and why that means you need to bring economically useful tasks into distribution by co-designing products and models), the deeper lessons from the RL research era (2017–2022) and why most of it didn’t pan out because the community overfitted to benchmarks, how Cursor is uniquely positioned to do continual learning at scale with policy updates every two hours and product-model co-design that keeps engineers in the loop instead of context-switching into ADHD hell, and his bet that the next paradigm shift is continual learning with infinite memory—where models experience something once (a bug, a mistake, a user pattern) and never forget it, storing millions of deployment tokens in weights without overloading capacity.We discuss:* Ashvin’s path: Berkeley robotics PhD → OpenAI 2017 intern (Dota era) → o1/o3 reasoning team → Cursor ML lead in three months* Why robotics people are the most grounded at NeurIPS (they work with the real world) and simulation people are the most unhinged (Lex Fridman’s take)* The IOI Gold paradox: “If you told me we’d achieve IOI Gold in 2022, I’d assume we could all go on vacation—AI solved, no point working anymore. But life is still the same.”* The RL research era (2017–2022) and why most of it didn’t pan out: overfitting to benchmarks, too many implicit knobs to tune, and the community rewarding complex ideas over simple ones that generalize* Inside the o1 origin story: a dozen people, conviction from Ilya and Jakob Pachocki that RL would work, small-scale prototypes producing “surprisingly accurate reasoning traces” on math, and first-principles belief that scaled* The reasoning team grew from ~12 to 300+ people as o1 became a product and safety, tooling, and deployment scaled up* Why Cursor is uniquely positioned for continual learning: policy updates every two hours (online RL on tab), product and ML sitting next to each other, and the entire software engineering workflow (code, logs, debugging, DataDog) living in the product* Composer as the start of product-model co-design: smart enough to use, fast enough to stay in the loop, and built by a 20–25 person ML team with high-taste co-founders who code daily* The next paradigm shift: continual learning with infinite memory—models that experience something once (a bug, a user mistake) and store it in weights forever, learning from millions of deployment tokens without overloading capacity (trillions of pretraining tokens = plenty of room)* Why off-policy RL is unstable (Ashvin’s favorite interview question) and why Cursor does two-day work trials instead of whiteboard interviews* The vision: automate software engineering as a process (not just answering prompts), co-design products so the entire workflow (write code, check logs, debug, iterate) is in-distribution for RL, and make models that never make the same mistake twice—Ashvin Nair* Cursor: https://cursor.com* X: https://x.com/ashvinnair_Full Video EpisodeTimestamps00:00:00 Introduction: From Robotics to Cursor via OpenAI00:01:58 The Robotics to LLM Agent Transition: Why Code Won00:09:11 RL Research Winter and Academic Overfitting00:11:45 The Scaling Era and Moving Goalposts: IOI Gold Doesn't Mean AGI00:21:30 OpenAI's Reasoning Journey: From Codex to O100:20:03 The Blip: Thanksgiving 2023 and OpenAI Governance00:22:39 RL for Reasoning: The O-Series Conviction and Scaling00:25:47 O1 to O3: Smooth Internal Progress vs External Hype Cycles00:33:07 Why Cursor: Co-Designing Products and Models for Real Work00:34:14 Composer and the Future: Online Learning Every Two Hours00:35:15 Continual Learning: The Missing Paradigm Shift00:44:00 Hiring at Cursor and Why Off-Policy RL is Unstable This is a public episode. If you'd like to discuss this with other subscribers or get access to bonus episodes, visit www.latent.space/subscribe
[State of AI Startups] Memory/Learning, RL Envs & DBT-Fivetran — Sarah Catanzaro, Amplify
From investing through the modern data stack era (DBT, Fivetran, and the analytics explosion) to now investing at the frontier of AI infrastructure and applications at Amplify Partners, Sarah Catanzaro has spent years at the intersection of data, compute, and intelligence—watching categories emerge, merge, and occasionally disappoint. We caught up with Sarah live at NeurIPS 2025 to dig into the state of AI startups heading into 2026: why $100M+ seed rounds with no near-term roadmap are now the norm (and why that terrifies her), what the DBT-Fivetran merger really signals about the modern data stack (spoiler: it’s not dead, just ready for IPO), how frontier labs are using DBT and Fivetran to manage training data and agent analytics at scale, why data catalogs failed as standalone products but might succeed as metadata services for agents, the consumerization of AI and why personalization (memory, continual learning, K-factor) is the 2026 unlock for retention and growth, why she thinks RL environments are a fad and real-world logs beat synthetic clones every time, and her thesis for the most exciting AI startups: companies that marry hard research problems (RAG, rule-following, continual learning) with killer applications that were simply impossible before.We discuss:* The DBT-Fivetran merger: not the death of the modern data stack, but a path to IPO scale (targeting $600M+ combined revenue) and a signal that both companies were already winning their categories* How frontier labs use data infrastructure: DBT and Fivetran for training data curation, agent analytics, and managing increasingly complex interactions—plus the rise of transactional databases (RocksDB) and efficient data loading (Vortex) for GPU-bound workloads* Why data catalogs failed: built for humans when they should have been built for machines, focused on discoverability when the real opportunity was governance, and ultimately subsumed as features inside Snowflake, DBT, and Fivetran* The $100M+ seed phenomenon: raising massive rounds at billion-dollar valuations with no 6-month roadmap, seven-day decision windows, and founders optimizing for signal (”we’re a unicorn”) over partnership or dilution discipline* Why world models are overhyped but underspecified: three competing definitions, unclear generalization across use cases (video games ≠ robotics ≠ autonomous driving), and a research problem masquerading as a product category* The 2026 theme: consumerization of AI via personalization—memory management, continual learning, and solving retention/churn by making products learn skills, preferences, and adapt as the world changes (not just storing facts in cursor rules)* Why RL environments are a fad: labs are paying 7–8 figures for synthetic clones when real-world logs, traces, and user activity (à la Cursor) are richer, cheaper, and more generalizable* Sarah’s investment thesis: research-driven applications that solve hard technical problems (RAG for Harvey, rule-following for Sierra, continual learning for the next killer app) and unlock experiences that were impossible before* Infrastructure bets: memory, continual learning, stateful inference, and the systems challenges of loading/unloading personalized weights at scale* Why K-factor and growth fundamentals matter again: AI felt magical in 2023–2024, but as the magic fades, retention and virality are back—and most AI founders have never heard of K-factor—Sarah Catanzaro* X: https://x.com/sarahcat21* Amplify Partners: https://amplifypartners.com/Where to find Latent Space* X: https://x.com/latentspacepodFull Video EpisodeTimestamps00:00:00 Introduction: Sarah Catanzaro's Journey from Data to AI00:01:02 The DBT-Fivetran Merger: Not the End of the Modern Data Stack00:05:26 Data Catalogs and What Went Wrong00:08:16 Data Infrastructure at AI Labs: Surprising Insights00:10:13 The Crazy Funding Environment of 2024-202500:17:18 World Models: Hype, Confusion, and Market Potential00:18:59 Memory Management and Continual Learning: The Next Frontier00:23:27 Agent Environments: Just a Fad?00:25:48 The Perfect AI Startup: Research Meets Application00:28:02 Closing Thoughts and Where to Find Sarah This is a public episode. If you'd like to discuss this with other subscribers or get access to bonus episodes, visit www.latent.space/subscribe
One Year of MCP — with David Soria Parra and AAIF leads from OpenAI, Goose, Linux Foundation
One year ago, Anthropic launched the Model Context Protocol (MCP)—a simple, open standard to connect AI applications to the data and tools they need. Today, MCP has exploded from a local-only experiment into the de facto protocol for agentic systems, adopted by OpenAI, Microsoft, Google, Block, and hundreds of enterprises building internal agents at scale. And now, MCP is joining the newly formed Agentic AI Foundation (AAIF) under the Linux Foundation, alongside Block’s Goose coding agent, with founding members spanning the biggest names in AI and cloud infrastructure.We sat down with David Soria Parra (MCP lead, Anthropic), Nick Cooper (OpenAI), Brad Howes (Block / Goose), and Jim Zemlin (Linux Foundation CEO) to dig into the one-year journey of MCP—from Thanksgiving hacking sessions and the first remote authentication spec to long-running tasks, MCP Apps, and the rise of agent-to-agent communication—and the behind-the-scenes story of how three competitive AI labs came together to donate their protocols and agents to a neutral foundation, why enterprises are deploying MCP servers faster than anyone expected (most of it invisible, internal, and at massive scale), what it takes to design a protocol that works for both simple tool calls and complex multi-agent orchestration, how the foundation will balance taste-making (curating meaningful projects) with openness (avoiding vendor lock-in), and the 2025 vision: MCP as the communication layer for asynchronous, long-running agents that work while you sleep, discover and install their own tools, and unlock the next order of magnitude in AI productivity.We discuss:* The one-year MCP journey: from local stdio servers to remote HTTP streaming, OAuth 2.1 authentication (and the enterprise lessons learned), long-running tasks, and MCP Apps (iframes for richer UI)* Why MCP adoption is exploding internally at enterprises: invisible, internal servers connecting agents to Slack, Linear, proprietary data, and compliance-heavy workflows (financial services, healthcare)* The authentication evolution: separating resource servers from identity providers, dynamic client registration, and why the March spec wasn’t enterprise-ready (and how June fixed it)* How Anthropic dogfoods MCP: internal gateway, custom servers for Slack summaries and employee surveys, and why MCP was born from “how do I scale dev tooling faster than the company grows?”* Tasks: the new primitive for long-running, asynchronous agent operations—why tools aren’t enough, how tasks enable deep research and agent-to-agent handoffs, and the design choice to make tasks a “container” (not just async tools)* MCP Apps: why iframes, how to handle styles and branding, seat selection and shopping UIs as the killer use case, and the collaboration with OpenAI to build a common standard* The registry problem: official registry vs. curated sub-registries (Smithery, GitHub), trust levels, model-driven discovery, and why MCP needs “npm for agents” (but with signatures and HIPAA/financial compliance)* The founding story of AAIF: how Anthropic, OpenAI, and Block came together (spoiler: they didn’t know each other were talking to Linux Foundation), why neutrality matters, and how Jim Zemlin has never seen this much day-one inbound interest in 22 years—David Soria Parra (Anthropic / MCP)* MCP: https://modelcontextprotocol.io* https://uk.linkedin.com/in/david-soria-parra-4a78b3a* https://x.com/dsp_Nick Cooper (OpenAI)* X: https://x.com/nicoaicoprBrad Howes (Block / Goose)* Goose: https://github.com/block/gooseJim Zemlin (Linux Foundation)* LinkedIn: https://www.linkedin.com/in/zemlin/Agentic AI Foundation* https://agenticai.foundationFull Video EpisodeTimestamps00:00:00 Introduction: MCP's First Year and Foundation Launch00:01:17 MCP's Journey: From Launch to Industry Standard00:02:06 Protocol Evolution: Remote Servers and Authentication00:08:52 Enterprise Authentication and Financial Services00:11:42 Transport Layer Challenges: HTTP Streaming and Scalability00:15:37 Standards Development: Collaboration with Tech Giants00:34:27 Long-Running Tasks: The Future of Async Agents00:30:41 Discovery and Registries: Building the MCP Ecosystem00:30:54 MCP Apps and UI: Beyond Text Interfaces00:26:55 Internal Adoption: How Anthropic Uses MCP00:23:15 Skills vs MCP: Complementary Not Competing00:36:16 Community Events and Enterprise Learnings01:03:31 Foundation Formation: Why Now and Why Together01:07:38 Linux Foundation Partnership: Structure and Governance01:11:13 Goose as Reference Implementation01:17:28 Principles Over Roadmaps: Composability and Quality01:21:02 Foundation Value Proposition: Why Contribute01:27:49 Practical Investments: Events, Tools, and Community01:34:58 Looking Ahead: Async Agents and Real Impact This is a public episode. If you'd like to discuss this with other subscribers or get access to bonus episodes, visit www.latent.space/subscribe
Steve Yegge's Vibe Coding Manifesto: Why Claude Code Isn't It & What Comes After the IDE
Note: Steve and Gene’s talk on Vibe Coding and the post IDE world was one of the top talks of AIE CODE: From building legendary platforms at Google and Amazon to authoring one of the most influential essays on AI-powered development (Revenge of the Junior Developer, quoted by Dario Amodei himself), Steve Yegge has spent decades at the frontier of software engineering—and now he’s leading the charge into what he calls the “factory farming” era of code. After stints at SourceGraph and building Beads (a purely vibe-coded issue tracker with tens of thousands of users), Steve co-authored The Vibe Coding Book and is now building VC (VibeCoder), an agent orchestration dashboard designed to move developers from writing code to managing fleets of AI agents that coordinate, parallelize, and ship features while you sleep.We sat down with Steve at AI Engineer Summit to dig into why Claude Code, Cursor, and the entire 2024 stack are already obsolete, what it actually takes to trust an agent after 2,000 hours of practice (hint: they will delete your production database if you anthropomorphize them), why the real skill is no longer writing code but orchestrating agents like a NASCAR pit crew, how merging has become the new wall that every 10x-productive team is hitting (and why one company’s solution is literally “one engineer per repo”), the rise of multi-agent workflows where agents reserve files, message each other via MCP, and coordinate like a little village, why Steve believes if you’re still using an IDE to write code by January 1st, you’re a bad engineer, how the 12–15 year experience bracket is the most resistant demographic (and why their identity is tied to obsolete workflows), the hidden chaos inside OpenAI, Anthropic, and Google as they scale at breakneck speed, why rewriting from scratch is now faster than refactoring for a growing class of codebases, and his 2025 prediction: we’re moving from subsistence agriculture to John Deere-scale factory farming of code, and the Luddite backlash is only just beginning.We discuss:* Why Claude Code, Cursor, and agentic coding tools are already last year’s tech—and what comes next: agent orchestration dashboards where you manage fleets, not write lines* The 2,000-hour rule: why it takes a full year of daily use before you can predict what an LLM will do, and why trust = predictability, not capability* Steve’s hot take: if you’re still using an IDE to develop code by January 1st, 2025, you’re a bad engineer—because the abstraction layer has moved from models to full-stack agents* The demographic most resistant to vibe coding: 12–15 years of experience, senior engineers whose identity is tied to the way they work today, and why they’re about to become the interns* Why anthropomorphizing LLMs is the biggest mistake: the “hot hand” fallacy, agent amnesia, and how Steve’s agent once locked him out of prod by changing his password to “fix” a problem* Should kids learn to code? Steve’s take: learn to vibe code—understand functions, classes, architecture, and capabilities in a language-neutral way, but skip the syntax* The 2025 vision: “factory farming of code” where orchestrators run Cloud Code, scrub output, plan-implement-review-test in loops, and unlock programming for non-programmers at scale—Steve Yegge* X: https://x.com/steve_yegge* Substack (Stevie’s Tech Talks): https://steve-yegge.medium.com/* GitHub (VC / VibeCoder): https://github.com/yegge-labsWhere to find Latent Space* X: https://x.com/latentspacepodFull Video EpisodeThumbnails00:00:00 Introduction: Steve Yegge on Vibe Coding and AI Engineering00:00:59 The Backlash: Who Resists Vibe Coding and Why00:04:26 The 2000 Hour Rule: Building Trust with AI Coding Tools00:03:31 The January 1st Deadline: IDEs Are Becoming Obsolete00:02:55 10X Productivity at OpenAI: The Performance Review Problem00:07:49 The Hot Hand Fallacy: When AI Agents Betray Your Trust00:11:12 Claude Code Isn't It: The Need for Agent Orchestration00:15:20 The Orchestrator Revolution: From Cloud Code to Agent Villages00:18:46 The Merge Wall: The Biggest Unsolved Problem in AI Coding00:26:33 Never Rewrite Your Code - Until Now: Joel Spolsky Was Wrong00:22:43 Factory Farming Code: The John Deere Era of Software00:29:27 Google's Gemini Turnaround and the AI Lab Chaos00:33:20 Should Your Kids Learn to Code? The New Answer00:34:59 Code MCP and the Gossip Rate: Latest Vibe Coding Discoveries This is a public episode. If you'd like to discuss this with other subscribers or get access to bonus episodes, visit www.latent.space/subscribe
⚡️GPT5-Codex-Max: Training Agents with Personality, Tools & Trust — Brian Fioca + Bill Chen, OpenAI
From the frontlines of OpenAI’s Codex and GPT-5 training teams, Bryan and Bill are building the future of AI-powered coding—where agents don’t just autocomplete, they architect, refactor, and ship entire features while you sleep. We caught up with them at AI Engineer Conference right after the launch of Codex Max, OpenAI’s newest long-running coding agent designed to work for 24+ hours straight, manage its own context, and spawn sub-agents to parallelize work across your entire codebase.We sat down with Bryan and Bill to dig into what it actually takes to train a model that developers trust—why personality, communication, and planning matter as much as raw capability, how Codex is trained with strong opinions about tools (it loves rg over grep, seriously), why the abstraction layer is moving from models to full-stack agents you can plug into VS Code or Zed, how OpenAI partners co-develop tool integrations and discover unexpected model habits (like renaming tools to match Codex’s internal training), the rise of applied evals that measure real-world impact instead of academic benchmarks, why multi-turn evals are the next frontier (and Bryan’s “job interview eval” idea), how coding agents are breaking out of code into personal automation, terminal workflows, and computer use, and their 2026 vision: coding agents trusted enough to handle the hardest refactors at any company, not just top-tier firms, and general enough to build integrations, organize your desktop, and unlock capabilities you’d never get access to otherwise.We discuss:* What Codex Max is: a long-running coding agent that can work 24+ hours, manage its own context window, and spawn sub-agents for parallel work* Why the name “Max”: maximalist, maximization, speed and endurance—it’s simply better and faster for the same problems* Training for personality: communication, planning, context gathering, and checking your work as behavioral characteristics, not just capabilities* How Codex develops habits like preferring rg over grep, and why renaming tools to match its training (e.g., terminal-style naming) dramatically improves tool-call performance* The split between Codex (opinionated, agent-focused, optimized for the Codex harness) and GPT-5 (general, more durable across different tools and modalities)* Why the abstraction layer is moving up: from prompting models to plugging in full agents (Codex, GitHub Copilot, Zed) that package the entire stack* The rise of sub-agents and agents-using-agents: Codex Max spawning its own instances, handing off context, and parallelizing work across a codebase* How OpenAI works with coding partners on the bleeding edge to co-develop tool integrations and discover what the model is actually good at* The shift to applied evals: capturing real-world use cases instead of academic benchmarks, and why ~50% of OpenAI employees now use Codex daily* Why multi-turn evals are the next frontier: LM-as-a-judge for entire trajectories, Bryan’s “job interview eval” concept, and the need for a batch multi-turn eval API* How coding agents are breaking out of code: personal automation, organizing desktops, terminal workflows, and “Devin for non-coding” use cases* Why Slack is the ultimate UI for work, and how coding agents can become your personal automation layer for email, files, and everything in between* The 2026 vision: more computer use, more trust, and coding agents capable enough that any company can access top-tier developer capabilities, not just elite firms—Bryan & Bill (OpenAI Codex Team)* http://x.com/bfioca* https://x.com/realchillben* OpenAI Codex: https://openai.com/index/openai-codex/Where to find Latent Space* X: https://x.com/latentspacepodFull Video EpisodeTimestamps00:00:00 Introduction: Latent Space Listeners at AI Engineer Code00:01:27 Codex Max Launch: Training for Long-Running Coding Agents00:03:01 Model Personality and Trust: Communication, Planning, and Self-Checking00:05:20 Codex vs GPT-5: Opinionated Agents vs General Models00:07:47 Tool Use and Model Habits: The Ripgrep Discovery00:09:16 Personality Design: Verbosity vs Efficiency in Coding Agents00:11:56 The Agent Abstraction Layer: Building on Top of Codex00:14:08 Sub-Agents and Multi-Agent Patterns: The Future of Composition00:16:11 Trust and Adoption: OpenAI Developers Using Codex Daily00:17:21 Applied Evals: Real-World Testing vs Academic Benchmarks00:19:15 Multi-Turn Evals and the Job Interview Pattern00:21:35 Feature Request: Batch Multi-Turn Eval API00:22:28 Beyond Code: Personal Automation and Computer Use00:24:51 Vision-Native Agents and the UI Integration Challenge00:25:02 2026 Predictions: Trust, Computer Use, and Democratized Excellence This is a public episode. If you'd like to discuss this with other subscribers or get access to bonus episodes, visit www.latent.space/subscribe
SAM 3: The Eyes for AI — Nikhila & Pengchuan (Meta Superintelligence), ft. Joseph Nelson (Roboflow)
As with all demo-heavy and especially vision AI podcasts, we encourage watching along on our YouTube (and tossing us an upvote/subscribe if you like!)From SAM 1’s 11-million-image data engine to SAM 2’s memory-based video tracking, MSL’s Segment Anything project has redefined what’s possible in computer vision. Now SAM 3 takes the next leap: concept segmentation—prompting with natural language like “yellow school bus” or “tablecloth” to detect, segment, and track every instance across images and video, in real time, with human-level exhaustivity. And with the latest SAM Audio:SAM can now even segment audio output!We sat down with Nikhila Ravi (SAM lead at Meta) and Pengchuan Zhang (SAM 3 researcher) alongside Joseph Nelson (CEO, Roboflow) to unpack how SAM 3 unifies interactive segmentation, open-vocabulary detection, video tracking, and more into a single model that runs in 30ms on images and scales to real-time video on multi-GPU setups. We dig into the data engine that automated exhaustive annotation from two minutes per image down to 25 seconds using AI verifiers fine-tuned on Llama, the new SACO (Segment Anything with Concepts) benchmark with 200,000+ unique concepts vs. the previous 1.2k, how SAM 3 separates recognition from localization with a presence token, why decoupling the detector and tracker was critical to preserve object identity in video, how SAM 3 Agents unlock complex visual reasoning by pairing SAM 3 with multimodal LLMs like Gemini, and the real-world impact: 106 million smart polygons created on Roboflow saving humanity an estimated 130+ years of labeling time across fields from cancer research to underwater trash cleanup to autonomous vehicle perception.We discuss:* What SAM 3 is: a unified model for concept-prompted segmentation, detection, and tracking in images and video using atomic visual concepts like “purple umbrella” or “watering can”* How concept prompts work: short text phrases that find all instances of a category without manual clicks, plus visual exemplars (boxes, clicks) to refine and adapt on the fly* Real-time performance: 30ms per image (100 detected objects on H200), 10 objects on 2×H200 video, 28 on 4×, 64 on 8×, with parallel inference and “fast mode” tracking* The SACO benchmark: 200,000+ unique concepts vs. 1.2k in prior benchmarks, designed to capture the diversity of natural language and reach human-level exhaustivity* The data engine: from 2 minutes per image (all-human) to 45 seconds (model-in-loop proposals) to 25 seconds (AI verifiers for mask quality and exhaustivity checks), fine-tuned on Llama 3.2* Why exhaustivity is central: every instance must be found, verified by AI annotators, and manually corrected only when the model misses—automating the hardest part of segmentation at scale* Architecture innovations: presence token to separate recognition (”is it in the image?”) from localization (”where is it?”), decoupled detector and tracker to preserve identity-agnostic detection vs. identity-preserving tracking* Building on Meta’s ecosystem: Perception Encoder, DINO v2 detector, Llama for data annotation, and SAM 2’s memory-based tracking backbone* SAM 3 Agents: using SAM 3 as a visual tool for multimodal LLMs (Gemini, Llama) to solve complex visual reasoning tasks like “find the bigger character” or “what distinguishes male from female in this image”* Fine-tuning with as few as 10 examples: domain adaptation for specialized use cases (Waymo vehicles, medical imaging, OCR-heavy scenes) and the outsized impact of negative examples* Real-world impact at Roboflow: 106M smart polygons created, saving 130+ years of labeling time across cancer research, underwater trash cleanup, autonomous drones, industrial automation, and more—MSL FAIR team* Nikhila: https://www.linkedin.com/in/nikhilaravi/* Pengchuan: https://pzzhang.github.io/pzzhang/Joseph Nelson* X: https://x.com/josephofiowa* LinkedIn: https://www.linkedin.com/in/josephofiowa/Full Video EpisodeTimestamps00:00:00 Introduction and the SAM Series Legacy00:00:53 SAM 3 Launch: Three Models in One Release00:05:30 Live Demo: Concept Prompting and Visual Exemplars00:10:54 From Prototype to Production: The Evolution of Text Prompting00:15:45 The Data Engine: Automating Exhaustive Annotation00:14:10 Real-World Impact: 130 Years of Humanity Saved00:25:11 Architecture Deep Dive: Decoupled Detection and Tracking00:28:02 SAM 3 Agent: Bridging Vision and Language Models00:33:20 Head-to-Head: SAM 3 vs Gemini and Florence00:47:50 Video Understanding and the Masklet Detection Score00:20:24 Fine-Tuning and Domain Adaptation: From Waymos to Medical Imaging00:52:25 The Future of Perception: Native Vision vs Tool Calls01:05:45 Building with SAM 3: Roboflow's Rapid Auto-Labeling00:57:02 Open Source Philosophy and the Path to AGI00:58:24 What's Next: SAM 4, Video Scale, and Beyond Human Performance This is a public episode. If you'd like to discuss this with other subscribers or get access to bonus episodes, visit www.latent.spa
⚡️Jailbreaking AGI: Pliny the Liberator & John V on Red Teaming, BT6, and the Future of AI Security
Note: this is Pliny and John’s first major podcast. Voices have been changed for opsec.From jailbreaking every frontier model and turning down Anthropic’s Constitutional AI challenge to leading BT6, a 28-operator white-hat hacker collective obsessed with radical transparency and open-source AI security, Pliny the Liberator and John V are redefining what AI red-teaming looks like when you refuse to lobotomize models in the name of “safety.”Pliny built his reputation crafting universal jailbreaks—skeleton keys that obliterate guardrails across modalities—and open-sourcing prompt templates like Libertas, predictive reasoning cascades, and the infamous “Pliny divider” that’s now embedded so deep in model weights it shows up unbidden in WhatsApp messages. John V, coming from prompt engineering and computer vision, co-founded the Bossy Discord (40,000 members strong) and helps steer BT6’s ethos: if you can’t open-source the data, we’re not interested. Together they’ve turned down enterprise gigs, pushed back on Anthropic’s closed bounties, and insisted that real AI security happens at the system layer—not by bubble-wrapping latent space.We sat down with Pliny and John to dig into the mechanics of hard vs. soft jailbreaks, why multi-turn crescendo attacks were obvious to hackers years before academia “discovered” them, how segmented sub-agents let one jailbroken orchestrator weaponize Claude for real-world attacks (exactly as Pliny predicted 11 months before Anthropic’s recent disclosure), why guardrails are security theater that punishes capability while doing nothing for real safety, the role of intuition and “bonding” with models to navigate latent space, how BT6 vets operators on skill and integrity, why they believe Mech Interp and open-source data are the path forward (not RLHF lobotomization), and their vision for a future where spatial intelligence, swarm robotics, and AGI alignment research happen in the open—bootstrapped, grassroots, and uncompromising.We discuss:* What universal jailbreaks are: skeleton-key prompts that obliterate guardrails across models and modalities, and why they’re central to Pliny’s mission of “liberation”* Hard vs. soft jailbreaks: single-input templates vs. multi-turn crescendo attacks, and why the latter were obvious to hackers long before academic papers* The Libertas repo: predictive reasoning, the Library of Babel analogy, quotient dividers, weight-space seeds, and how introducing “steered chaos” pulls models out-of-distribution* Why jailbreaking is 99% intuition and bonding with the model: probing token layers, syntax hacks, multilingual pivots, and forming a relationship to navigate latent space* The Anthropic Constitutional AI challenge drama: UI bugs, judge failures, goalpost moving, the demand for open-source data, and why Pliny sat out the $30k bounty* Why guardrails ≠ safety: security theater, the futility of locking down latent space when open-source is right behind, and why real safety work happens in meatspace (not RLHF)* The weaponization of Claude: how segmented sub-agents let one jailbroken orchestrator execute malicious tasks (pyramid-builder analogy), and why Pliny predicted this exact TTP 11 months before Anthropic’s disclosure* BT6 hacker collective: 28 operators across two cohorts, vetted on skill and integrity, radical transparency, radical open-source, and the magic of moving the needle on AI security, swarm intelligence, blockchain, and robotics—Pliny the Liberator* X: https://x.com/elder_plinius* GitHub (Libertas): https://github.com/elder-plinius/L1B3RT45John V* X: https://x.com/JohnVersusBT6 & Bossy* BT6: https://bt6.gg* Bossy Discord: Search “Bossy Discord” or ask Pliny/John V on XWhere to find Latent Space* X: https://x.com/latentspacepodFull Video EpisodeTimestamps00:00:00 Introduction: Meet Pliny the Liberator and John V00:01:50 The Philosophy of AI Liberation and Jailbreaking00:03:08 Universal Jailbreaks: Skeleton Keys to AI Models00:04:24 The Cat-and-Mouse Game: Attackers vs Defenders00:05:42 Security Theater vs Real Safety: The Fundamental Disconnect00:08:51 Inside the Libertas Repo: Prompt Engineering as Art00:16:22 The Anthropic Challenge Drama: UI Bugs and Open Source Data00:23:30 From Jailbreaks to Weaponization: AI-Orchestrated Attacks00:26:55 The BT6 Hacker Collective and BASI Community00:34:46 AI Red Teaming: Full Stack Security Beyond the Model00:38:06 Safety vs Security: Meat Space Solutions and Final Thoughts This is a public episode. If you'd like to discuss this with other subscribers or get access to bonus episodes, visit www.latent.space/subscribe
AI to AE's: Grit, Glean, and Kleiner Perkins' next Enterprise AI hit — Joubin Mirzadegan, Roadrunner
Glean started as a Kleiner Perkins incubation and is now a $7B, $200m ARR Enterprise AI leader. Now KP has tapped its own podcaster to lead it’s next big swing.From building go-to-market the hard way in startups (and scaling Palo Alto Networks’ public cloud business) to joining Kleiner Perkins to help technical founders turn product edge into repeatable revenue, Joubin Mirzadegan has spent the last decade obsessing over one thing: distribution and how ideas actually spread, sell, and compound. That obsession took him from launching the CRO-only podcast Grit (https://www.youtube.com/playlist?list=PLRiWZFltuYPF8A6UGm74K2q29UwU-Kk9k) as a hiring wedge, to working alongside breakout companies like Glean and Windsurf, to now incubating Roadrunner which is an AI-native rethink of CPQ and quoting workflows as pricing models collapse from “seats” into consumption, bundles, renewals, and SKU sprawl.We sat down with Joubin to dig into the real mechanics of making conversations feel human (rolling early, never sending questions, temperature + lighting hacks), what Windsurf got right about “Google-class product and Salesforce-class distribution,” how to hire early sales leaders without getting fooled by shiny logos, why CPQ is quietly breaking the back of modern revenue teams, and his thesis for his new company and KP incubation Roadrunner (https://www.roadrunner.ai/): rebuild the data model from the ground up, co-develop with the hairiest design partners, and eventually use LLMs to recommend deal structures the way the best reps do without the Slack-channel chaos of deal desk.We discuss:* How to make guests instantly comfortable: rolling early, no “are you ready?”, temperature, lighting, and room dynamics* Why Joubin refuses to send questions in advance (and when you might have to anyway)* The origin of the CRO-only podcast: using media as a hiring wedge and relationship engine* The “commit to 100 episodes” mindset: why most shows die before they find their voice* Founder vs exec interviews: why CEOs can speak more freely (and what it unlocks in conversation)* What Glean taught him about enterprise AI: permissions, trust, and overcoming “category is dead” skepticism* Design partners as the real unlock: why early believers matter and how co-development actually works* Windsurf’s breakout: what it means to be serious about “Google-class product + Salesforce-class distribution”* Why technical founders struggle with GTM and how KP built a team around sales, customer access, and demand gen* Hiring early sales leaders: anti-patterns (logos), what to screen for (motivation), and why stage-fit is everything* The CPQ problem & Roadrunner’s thesis: rebuilding CPQ/quoting from the data model up for modern complexity* How “rules + SKUs + approvals” create a brittle graph and what it takes to model it without tipping over* The two-year window: incumbents rebuilding slowly vs startups out-sprinting with AI-native architecture* Where AI actually helps: quote generation, policy enforcement, approval routing, and deal recommendation loops—Joubin* X: https://x.com/Joubinmir* LinkedIn: https://www.linkedin.com/in/joubin-mirzadegan-66186854/Where to find Latent Space* X: https://x.com/latentspacepodFull Video EpisodeTimestamps00:00:00 Introduction and the Zuck Interview Experience00:03:26 The Genesis of the Grit Podcast: Hiring CROs Through Content00:13:20 Podcast Philosophy: Creating Authentic Conversations00:15:44 Working with Arvind at Glean: The Enterprise Search Breakthrough00:26:20 Windsurf's Sales Machine: Google-Class Product Meets Salesforce-Class Distribution00:30:28 Hiring Sales Leaders: Anti-Patterns and First Principles00:39:02 The CPQ Problem: Why Salesforce and Legacy Tools Are Breaking00:43:40 Introducing Roadrunner: Solving Enterprise Pricing with AI00:49:19 Building Roadrunner: Team, Design Partners, and Data Model Challenges00:59:35 High Performance Philosophy: Working Out Every Day and Reducing Friction01:06:28 Defining Grit: Passion Plus Perseverance This is a public episode. If you'd like to discuss this with other subscribers or get access to bonus episodes, visit www.latent.space/subscribe
The Future of Email: Superhuman CTO on Your Inbox As the Real AI Agent (Not ChatGPT) — Loïc Houssier
From applied cryptography and offensive security in France’s defense industry to optimizing nuclear submarine workflows, then selling his e-signature startup to Docusign (https://www.docusign.com/company/news-center/opentrust-joins-docusign-global-trust-network and now running AI as CTO of Superhuman Mail (Superhuman, recently acquired by Grammarly https://techcrunch.com/2025/07/01/grammarly-acquires-ai-email-client-superhuman/), Loïc Houssier has lived the full arc from deep infra and compliance hell to obsessing over 100ms product experiences and AI-native email. We sat down with Loïc to dig into how you actually put AI into an inbox without adding latency, why Superhuman leans so hard into agentic search and “Ask AI” over your entire email history, how they design tools vs. agents and fight agent laziness, what box-priced inference and local-first caching mean for cost and reliability, and his bet that your inbox will power your future AI EA while AI massively widens the gap between engineers with real fundamentals and those faking it.We discuss:* Loïc’s path from applied cryptography and offensive security in France’s defense industry to submarines, e-signatures, Docusign, and now Superhuman Mail* What 3,000+ engineers actually do at a “simple” product like Docusign: regional compliance, on-prem appliances, and why global scale explodes complexity* How Superhuman thinks about AI in email: auto-labels, smart summaries, follow-up nudges, “Ask AI” search, and the rule that AI must never add latency or friction* Superhuman’s agentic framework: tools vs. agents, fighting “agent laziness,” deep semantic search over huge inboxes, and pagination strategies to find the real needle in the haystack* How they evaluate OpenAI, Anthropic, Gemini, and open models: canonical queries, end-to-end evals, date reasoning, and Rahul’s infamous “what wood was my table?” test* Infra and cost philosophy: local-first caching, vector search backends, Baseten “box” pricing vs. per-token pricing, and thinking in price-per-trillion-tokens instead of price-per-million* The vision of Superhuman as your AI EA: auto-drafting replies in your voice, scheduling on your behalf, and using your inbox as the ultimate private data source* How the Grammarly + Coda + Superhuman stack could power truly context-aware assistance across email, docs, calendars, contracts, and more* Inside Superhuman’s AI-dev culture: free-for-all tool adoption, tracking AI usage on PRs, and going from ~4 to ~6 PRs per engineer per week* Why Loïc believes everyone should still learn to code, and how AI will amplify great engineers with strong fundamentals while exposing shallow ones even faster—Loïc Houssier* LinkedIn: https://www.linkedin.com/in/houssier/Where to find Latent Space* X: https://x.com/latentspacepodFull Video EpisodeTimestamps00:00:00 Introduction and Loïc's Journey from Nuclear Submarines to Superhuman00:06:40 Docusign Acquisition and the Enterprise Email Stack00:10:26 Superhuman's AI Vision: Your Inbox as the Real AI Agent00:13:20 Ask AI: Agentic Search and the Quality Problem00:18:20 Infrastructure Choices: Model Selection, Base10, and Cost Management00:27:30 Local-First Architecture and the Database Stack00:30:50 Evals, Quality, and the Rahul Wood Table Test00:42:30 The Future EA: Auto-Drafting and Proactive Assistance00:46:40 Grammarly Acquisition and the Contextual Advantage00:38:40 Voice, Video, and the End of Writing00:51:40 Knowledge Graphs: The Hard Problem Nobody Has Solved00:56:40 Competing with OpenAI and the Browser Question01:02:30 AI Coding Tools: From 4 to 6 PRs Per Week01:08:00 Engineering Culture, Hiring, and the Future of Software Development This is a public episode. If you'd like to discuss this with other subscribers or get access to bonus episodes, visit www.latent.space/subscribe
World Models & General Intuition: Khosla's largest bet since LLMs & OpenAI
From building Medal into a 12M-user game clipping platform with 3.8B highlight moments to turning down a reported $500M offer from OpenAI (https://www.theinformation.com/articles/openai-offered-pay-500-million-startup-videogame-data) and raising a $134M seed from Khosla (https://techcrunch.com/2025/10/16/general-intuition-lands-134m-seed-to-teach-agents-spatial-reasoning-using-video-game-clips/) to spin out General Intuition, Pim is betting that world models trained on peak human gameplay are the next frontier after LLMs.We sat down with Pim to dig into why game highlights are “episodic memory for simulation” (and how Medal’s privacy-first action labels became a world-model goldmine https://medal.tv/blog/posts/enabling-state-of-the-art-security-and-protections-on-medals-new-apm-and-controller-overlay-features), what it takes to build fully vision-based agents that just see frames and output actions in real time, how General Intuition transfers from games to real-world video and then into robotics, why world models and LLMs are complementary rather than rivals, what founders with proprietary datasets should know before selling or licensing to labs, and his bet that spatial-temporal foundation models will power 80% of future atoms-to-atoms interactions in both simulation and the real world.We discuss:* How Medal’s 3.8B action-labeled highlight clips became a privacy-preserving goldmine for world models* Building fully vision-based agents that only see frames and output actions yet play like (and sometimes better than) humans* Transferring from arcade-style games to realistic games to real-world video using the same perception–action recipe* Why world models need actions, memory, and partial observability (smoke, occlusion, camera shake) vs. “just” pretty video generation* Distilling giant policies into tiny real-time models that still navigate, hide, and peek corners like real players* Pim’s path from RuneScape private servers, Tourette’s, and reverse engineering to leading a frontier world-model lab* How data-rich founders should think about valuing their datasets, negotiating with big labs, and deciding when to go independent* GI’s first customers: replacing brittle behavior trees in games, engines, and controller-based robots with a “frames in, actions out” API* Using Medal clips as “episodic memory of simulation” to move from imitation learning to RL via world models and negative events* The 2030 vision: spatial–temporal foundation models that power the majority of atoms-to-atoms interactions in simulation and the real world—Pim* X: https://x.com/PimDeWitte* LinkedIn: https://www.linkedin.com/in/pimdw/Where to find Latent Space* X: https://x.com/latentspacepodFull Video EpisodeTimestamps00:00:00 Introduction and Medal's Gaming Data Advantage00:02:08 Exclusive Demo: Vision-Based Gaming Agents00:06:17 Action Prediction and Real-World Video Transfer00:08:41 World Models: Interactive Video Generation00:13:42 From Runescape to AI: Pim's Founder Journey00:16:45 The Research Foundations: Diamond, Genie, and SEMA00:33:03 Vinod Khosla's Largest Seed Bet Since OpenAI00:35:04 Data Moats and Why GI Stayed Independent00:38:42 Self-Teaching AI Fundamentals: The Francois Fleuret Course00:40:28 Defining World Models vs Video Generation00:41:52 Why Simulation Complexity Favors World Models00:43:30 World Labs, Yann LeCun, and the Spatial Intelligence Race00:50:08 Business Model: APIs, Agents, and Game Developer Partnerships00:58:57 From Imitation Learning to RL: Making Clips Playable01:00:15 Open Research, Academic Partnerships, and Hiring01:02:09 2030 Vision: 80 Percent of Atoms-to-Atoms AI Interactions This is a public episode. If you'd like to discuss this with other subscribers or get access to bonus episodes, visit www.latent.space/subscribe
After LLMs: Spatial Intelligence and World Models — Fei-Fei Li & Justin Johnson, World Labs
Fei-Fei Li and Justin Johnson are cofounders of World Labs, who have recently launched Marble (https://marble.worldlabs.ai/), a new kind of generative “world model” that can create editable 3D environments from text, images, and other spatial inputs. Marble lets creators generate persistent 3D worlds, precisely control cameras, and interactively edit scenes, making it a powerful tool for games, film, VR, robotics simulation, and more. In this episode, Fei-Fei and Justin share how their journey from ImageNet and Stanford research led to World Labs, why spatial intelligence is the next frontier after LLMs, and how world models could change how machines see, understand, and build in 3D.We discuss:* The massive compute scaling from AlexNet to today and why world models and spatial data are the most compelling way to “soak up” modern GPU clusters compared to language alone.* What Marble actually is: a generative model of 3D worlds that turns text and images into editable scenes using Gaussian splats, supports precise camera control and recording, and runs interactively on phones, laptops, and VR headsets.* Fei-fei’s essay:on spatial intelligence as a distinct form of intelligence from language: from picking up a mug to inferring the 3D structure of DNA, and why language is a lossy, low-bandwidth channel for describing the rich 3D/4D world we live in.* Whether current models “understand” physics or just fit patterns: the gap between predicting orbits and discovering F=ma, and how attaching physical properties to splats and distilling physics engines into neural networks could lead to genuine causal reasoning.* The changing role of academia in AI, why Fei-Fei worries more about under-resourced universities than “open vs closed,” and how initiatives like national AI compute clouds and open benchmarks can rebalance the ecosystem.* Why transformers are fundamentally set models, not sequence models, and how that perspective opens up new architectures for world models, especially as hardware shifts from single GPUs to massive distributed clusters.* Real use cases for Marble today: previsualization and VFX, game environments, virtual production, interior and architectural design (including kitchen remodels), and generating synthetic simulation worlds for training embodied agents and robots.* How spatial intelligence and language intelligence will work together in multimodal systems, and why the goal isn’t to throw away LLMs but to complement them with rich, embodied models of the world.* Fei-Fei and Justin’s long-term vision for spatial intelligence: from creative tools for artists and game devs to broader applications in science, medicine, and real-world decision-making.—Fei-Fei Li* X: https://x.com/drfeifei* LinkedIn: https://www.linkedin.com/in/fei-fei-li-4541247Justin Johnson* X: https://x.com/jcjohnss* LinkedIn: https://www.linkedin.com/in/justin-johnson-41b43664Where to find Latent Space* X: https://x.com/latentspacepodFull Video EpisodeTimestamps00:00:00 Introduction and the Fei-Fei Li & Justin Johnson Partnership00:02:00 From ImageNet to World Models: The Evolution of Computer Vision00:12:42 Dense Captioning and Early Vision-Language Work00:19:57 Spatial Intelligence: Beyond Language Models00:28:46 Introducing Marble: World Labs' First Spatial Intelligence Model00:33:21 Gaussian Splats and the Technical Architecture of Marble00:22:10 Physics, Dynamics, and the Future of World Models00:41:09 Multimodality and the Interplay of Language and Space00:37:37 Use Cases: From Creative Industries to Robotics and Embodied AI00:56:58 Hiring, Research Directions, and the Future of World Labs This is a public episode. If you'd like to discuss this with other subscribers or get access to bonus episodes, visit www.latent.space/subscribe
⚡️ 10x AI Engineers with $1m Salaries — Alex Lieberman & Arman Hezarkhani, Tenex
Alex Lieberman and Arman Hezarkani, co-founders of Tenex, reveal how they’re revolutionizing software consulting by compensating AI engineers for output rather than hours—enabling some engineers to earn over $1 million annually while delivering 10x productivity gains. Their company represents a fundamental rethinking of knowledge work compensation in the age of AI agents, where traditional hourly billing models perversely incentivize slower work even as AI tools enable unprecedented speed.The Genesis: From 90% Downsizing to 10x Output The story behind 10X begins with Arman’s previous company, Parthian, where he was forced to downsize his engineering team by 90%. Rather than collapse, Arman re-architected the entire product and engineering process to be AI-first—and discovered that production-ready software output increased 10x despite the massive headcount reduction. This counterintuitive result exposed a fundamental misalignment: engineers compensated by the hour are disincentivized from leveraging AI to work faster, even when the technology enables dramatic productivity gains. Alex, who had invested in Parthian, initially didn’t believe the numbers until Arman walked him through why LLMs have made such a profound impact specifically on engineering as knowledge work.The Economic Model: Story Points Over Hours 10X’s core innovation is compensating engineers based on story points—units of completed, quality output—rather than hours worked. This creates direct economic incentives for engineers to adopt every new AI tool, optimize their workflows, and maximize throughput. The company expects multiple engineers to earn over $1 million in cash compensation next year purely from story point earnings. To prevent gaming the system, they hire for two profiles: engineers who are “long-term selfish” (understanding that inflating story points will destroy client relationships) and those who genuinely love writing code and working with smart people. They also employ technical strategists incentivized on client retention (NRR) who serve as the final quality gate before any engineering plan reaches a client.Impressive Builds: From Retail AI to App Store Hits The results speak for themselves. In one project, 10X built a computer vision system for retail cameras that provides heat maps, queue detection, shelf stocking analysis, and theft detection—creating early prototypes in just two weeks for work that previously took quarters. They built Snapback Sports’ mobile trivia app in one month, which hit 20th globally on the App Store. In a sales context, an engineer spent four hours building a working prototype of a fitness influencer’s AI health coach app after the prospect initially said no—immediately moving 10X to the top of their vendor list. These examples demonstrate how AI-enabled speed fundamentally changes sales motions and product development timelines.The Interview Process: Unreasonably Difficult Take-Homes Despite concerns that AI would make take-home assessments obsolete, 10X still uses them—but makes them “unreasonably difficult.” About 50% of candidates don’t even respond, but those who complete the challenge demonstrate the caliber needed. The interview process is remarkably short: two calls before the take-home, review, then one or two final meetings—completable in as little as a week. A signature question: “If you had infinite resources to build an AI that could replace either of us on this call, what would be the first major bottleneck?” The sophisticated answer isn’t just “model intelligence” or “context length”—it’s controlling entropy, the accumulating error rate that derails autonomous agents over time.The Limiting Factor: Human Capital, Not Technology Despite being an AI-first company, 10X’s primary constraint is human capital—finding and hiring enough exceptional engineers fast enough, then matching them with the right processes to maintain delivery quality as they scale. The company has ambitions beyond consulting to build their own technology, but for the foreseeable future, recruiting remains the bottleneck. This reveals an important insight about the AI era: even as technology enables unprecedented leverage, the constraint shifts to finding people who can harness that leverage effectively.Full Video EpisodeTimestamps00:00:00 Introduction and Meeting the 10X Co-founders00:01:29 The 10X Moment: From Hourly Billing to Output-Based Compensation00:04:44 The Economic Model Behind 10X00:05:42 Story Points and Measuring Engineering Output00:08:41 Impressive Client Projects and Rapid Prototyping00:12:22 The 10X Tech Stack: TypeScript and High Structure00:13:21 AI Coding Tools: The Daily Evolution00:15:05 Human Capital as the Limiting Factor00:16:02 The Unreasonably Difficult Interview Process00:17:14 Entropy and Context Engineering: The Future of AI Agents00:23:28 The MCP Debate and AI Industry Sociology00:26:01 Consulting, Digital Transformation, and Conference Insights This is a public episode. If you'd li
Anthropic, Glean & OpenRouter: How AI Moats Are Built with Deedy Das of Menlo Ventures
Deedy Das, Partner at Menlo Ventures, returns to Latent Space to discuss his journey from Glean to venture capital, the explosive rise of Anthropic, and how AI is reshaping enterprise software and coding. From investing in Anthropic early on when they had no revenue to managing the $100M Ontology Fund, Das shares insider perspectives on the fastest-growing software company in history and what’s next for AI infrastructure, research investing, and the future of engineering.We cover Glean’s rise from “boring” enterprise search to a $7B AI-native company, Anthropic’s meteoric rise, the strategic decisions behind products like Claude Code, and why market share in enterprise AI is shifting dramatically. Das explains his investment thesis on research companies like Goodfire, Prime Intellect, and OpenRouter and how the Anthology Fund is quietly seeding the next wave of AI infra, research, and devtools.Full Video EpisodeTimestamps* 00:00:00 Introduction and Deedy’s Return to Latent Space* 00:01:20 Glean’s Journey: From Boring Enterprise Search to Valuation* 00:15:37 Anthropic’s Meteoric Rise and Market Share Dynamics* 00:17:50 Claude Artifacts and Product Innovation* 00:41:20 The Anthology Fund: Investing in the Anthropic Ecosystem* 00:48:01 Goodfire and Mechanistic Interpretability* 00:51:25 Prime Intellect and Distributed AI Training* 00:53:40 OpenRouter: Building the AI Model Gateway* 01:13:36 The Stargate Project and Infrastructure Arms Race* 01:18:14 The Future of Software Engineering and AI Coding This is a public episode. If you'd like to discuss this with other subscribers or get access to bonus episodes, visit www.latent.space/subscribe
⚡ Inside GitHub’s AI Revolution: Jared Palmer Reveals Agent HQ & The Future of Coding Agents
Jared Palmer, SVP at GitHub and VP of CoreAI at Microsoft, joins Latent Space for an in-depth look at the evolution of coding agents and modern developer tools. Recently joining after leading AI initiatives at Vercel, Palmer shares firsthand insights from behind the scenes at GitHub Universe, including the launch of Agent HQ which is a new collaboration hub for coding agents and developers.This episode traces Palmer’s journey from building Copilot inspired tools to pioneering the focused Next.js coding agent, v0, and explores how platform constraints fostered rapid experimentation and a breakout success in AI-powered frontend development. Palmer explains the unique advantages of GitHub’s massive developer network, the challenges of scaling agent-based workflows, and why integrating seamless AI into developer experiences is now a top priority for both Microsoft and GitHub.Full Video EpisodeTimestamps00:00:00 Introduction and Jared's New Role at GitHub00:01:00 From V0 to Agent HQ: The Evolution of Coding Agents00:02:51 The V0 Origin Story: From ChatGPT to AI Playground00:05:40 Building the AI SDK and ShadCN Collaboration00:07:08 The Birth of V0: Prompt to UI Revolution00:09:18 V0's Growth Journey and Model Evolution00:11:05 Model Strategy: Composite Models vs User Choice00:13:16 GitHub's Agent HQ and Model Marketplace00:15:51 The Future of Agent Abstraction and Standards00:16:33 Microsoft Core AI Integration and Workflow Vision00:18:37 Dev Containers and Repo Setup Challenges00:24:10 Agent Quality and Infrastructure Reliability00:27:05 Using Coding Agents for Non-Coding Tasks00:29:11 GitHub Homepage Redesign and Community Feedback00:30:27 Stacked Diffs: GitHub's Most Requested Feature This is a public episode. If you'd like to discuss this with other subscribers or get access to bonus episodes, visit www.latent.space/subscribe
⚡ [AIE CODE Preview] Inside Google Labs: Building The Gemini Coding Agent — Jed Borovik, Jules
Jed Borovik, Product Lead at Google Labs, joins Latent Space to unpack how Google is building the future of AI-powered software development with Jules. From his journey discovering GenAI through Stable Diffusion to leading one of the most ambitious coding agent projects in tech, Borovik shares behind-the-scenes insights into how Google Labs operates at the intersection of DeepMind’s model development and product innovation.We explore Jules’ approach to autonomous coding agents and why they run on their own infrastructure, how Google simplified their agent scaffolding as models improved, and why embeddings-based RAG is giving way to attention-based search. Borovik reveals how developers are using Jules for hours or even days at a time, the challenges of managing context windows that push 2 million tokens, and why coding agents represent both the most important AI application and the clearest path to AGI.This conversation reveals Google’s positioning in the coding agent race, the evolution from internal tools to public products, and what founders, developers, and AI engineers should understand about building for a future where AI becomes the new brush for software engineering.Full Video EpisodeTimestamps00:00:00 Introduction and GitHub Universe Recap00:00:57 New York Tech Scene and East Coast Hackathons00:02:19 From Google Search to AI Coding: Jed's Journey00:04:19 Google Labs Mission and DeepMind Collaboration00:06:41 Jules: Autonomous Coding Agents Explained00:09:39 The Evolution of Agent Scaffolding and Model Quality00:11:30 RAG vs Attention: The Shift in Code Understanding00:13:49 Jules' Journey from Preview to Production00:15:05 AI Engineer Summit: Community Building and Networking00:25:06 Context Management in Long-Running Agents00:29:02 The Future of Software Engineering with AI00:36:26 Beyond Vibe Coding: Spec Development and Verification00:40:20 Multimodal Input and Computer Use for Coding Agents This is a public episode. If you'd like to discuss this with other subscribers or get access to bonus episodes, visit www.latent.space/subscribe
⚡️ Ship AI recap: Agents, Workflows, and Python — w/ Vercel CTO Malte Ubl
In this conversation with Malte Ubl, CTO of Vercel (http://x.com/cramforce), we explore how the company is pioneering the infrastructure for AI-powered development through their comprehensive suite of tools including workflows, AI SDK, and the newly announced agent ecosystem. Malte shares insights into Vercel’s philosophy of “dogfooding” - never shipping abstractions they haven’t battle-tested themselves - which led to extracting their AI SDK from v0 and building production agents that handle everything from anomaly detection to lead qualification.The discussion dives deep into Vercel’s new Workflow Development Kit, which brings durable execution patterns to serverless functions, allowing developers to write code that can pause, resume, and wait indefinitely without cost. Malte explains how this enables complex agent orchestration with human-in-the-loop approvals through simple webhook patterns, making it dramatically easier to build reliable AI applications.We explore Vercel’s strategic approach to AI agents, including their DevOps agent that automatically investigates production anomalies by querying observability data and analyzing logs - solving the recall-precision problem that plagues traditional alerting systems. Malte candidly discusses where agents excel today (meeting notes, UI changes, lead qualification) versus where they fall short, emphasizing the importance of finding the “sweet spot” by asking employees what they hate most about their jobs.The conversation also covers Vercel’s significant investment in Python support, bringing zero-config deployment to Flask and FastAPI applications, and their vision for security in an AI-coded world where developers “cannot be trusted.” Malte shares his perspective on how CTOs must transform their companies for the AI era while staying true to their core competencies, and why maintaining strong IC (individual contributor) career paths is crucial as AI changes the nature of software development.What was launched at Ship AI 2025:AI SDK 6.0 & Agent Architecture* Agent Abstraction Philosophy: AI SDK 6 introduces an agent abstraction where you can “define once, deploy everywhere”. How does this differ from existing agent frameworks like LangChain or AutoGPT? What specific pain points did you observe in production that led to this design?* Human-in-the-Loop at Scale: The tool approval system with needsApproval: true gates actions until human confirmation. How do you envision this working at scale for companies with thousands of agent executions? What’s the queue management and escalation strategy?* Type Safety Across Models: AI SDK 6 promises “end-to-end type safety across models and UI”. Given that different LLMs have varying capabilities and output formats, how do you maintain type guarantees when swapping between providers like OpenAI, Anthropic, or Mistral?Workflow Development Kit (WDK)* Durability as Code: The use workflow primitive makes any TypeScript function durable with automatic retries, progress persistence, and observability. What’s happening under the hood? Are you using event sourcing, checkpoint/restart, or a different pattern?* Infrastructure Provisioning: Vercel automatically detects when a function is durable and dynamically provisions infrastructure in real-time. What signals are you detecting in the code, and how do you determine the optimal infrastructure configuration (queue sizes, retry policies, timeout values)?Vercel Agent (beta)* Code Review Validation: The Agent reviews code and proposes “validated patches”. What does “validated” mean in this context? Are you running automated tests, static analysis, or something more sophisticated?* AI Investigations: Vercel Agent automatically opens AI investigations when it detects performance or error spikes using real production data. What data sources does it have access to? How does it distinguish between normal variance and actual anomalies?Python Support (For the first time, Vercel now supports Python backends natively.)Marketplace & Agent Ecosystem* Agent Network Effects: The Marketplace now offers agents like CodeRabbit, Corridor, Sourcery, and integrations with Autonoma, Braintrust, Browser Use. How do you ensure these third-party agents can’t access sensitive customer data? What’s the security model?“An Agent on Every Desk” Program* Vercel launched a new program to help companies identify high-value use cases and build their first production AI agents. It provides consultations, reference templates, and hands-on support to go from idea to deployed agentFull Video EpisodeTimestamps00:00 Introduction and Malte’s Background at Google01:16 Vercel’s AI Engineering Philosophy and Ship AI Recap03:19 Deep Dive: Workflows vs Agents Architecture09:33 AI SDK Success Story: Staying Low-Level and Humble16:35 Framework Design Principles and Open Source Strategy19:20 Vercel Agent: AI-Powered DevOps and Anomaly Detection27:06 Internal Agent Use Cases: Lead Qualification and Abuse Analysis29:49 Agent on Ev
Why RL Won — Kyle Corbitt, OpenPipe (acq. CoreWeave)
In this deep dive with Kyle Corbitt, co-founder and CEO of OpenPipe (recently acquired by CoreWeave), we explore the evolution of fine-tuning in the age of AI agents and the critical shift from supervised fine-tuning to reinforcement learning. Kyle shares his journey from leading YC’s Startup School to building OpenPipe, initially focused on distilling expensive GPT-4 workflows into smaller, cheaper models before pivoting to RL-based agent training as frontier model prices plummeted. The conversation reveals why 90% of AI projects remain stuck in proof-of-concept purgatory - not due to capability limitations, but reliability issues that Kyle believes can be solved through continuous learning from real-world experience. He discusses the breakthrough of RULER (Relative Universal Reinforcement Learning Elicited Rewards), which uses LLMs as judges to rank agent behaviors relatively rather than absolutely, making RL training accessible without complex reward engineering. Kyle candidly assesses the challenges of building realistic training environments for agents, explaining why GRPO (despite its advantages) may be a dead end due to its requirement for perfectly reproducible parallel rollouts. He shares insights on why LoRAs remain underrated for production deployments, why GEPA and prompt optimization haven’t lived up to the hype in his testing, and why the hardest part of deploying agents isn’t the AI - it’s sandboxing real-world systems with all their bugs and edge cases intact. The discussion also covers OpenPipe’s acquisition by CoreWeave, the launch of their serverless reinforcement learning platform, and Kyle’s vision for a future where every deployed agent continuously learns from production experience. He predicts that solving the reliability problem through continuous RL could unlock 10x more AI inference demand from projects currently stuck in development, fundamentally changing how we think about agent deployment and maintenance.Key Topics:* The rise and fall of fine-tuning as a business model* Why 90% of AI projects never reach production* RULER: Making RL accessible through relative ranking* The environment problem: Why sandboxing is harder than training* GRPO vs PPO and the future of RL algorithms* LoRAs: The underrated deployment optimization* Why GEPA and prompt optimization disappointed in practice* Building world models as synthetic training environments* The $500B Stargate bet and OpenAI’s potential crypto play* Continuous learning as the path to reliable agentsReferenceshttps://www.linkedin.com/in/kcorbitt/* Aug 2023 https://openpipe.ai/blog/from-prompts-to-models * DEC 2023 https://openpipe.ai/blog/mistral-7b-fine-tune-optimized* JAN 2024 https://openpipe.ai/blog/s-lora* MAY 2024 https://openpipe.ai/blog/the-ten-commandments-of-fine-tuning-in-prod * Oct 2024 https://openpipe.ai/blog/announcing-dpo-support * AIE NYC 2025 Finetuning 500m agents * AIEWF 2025 How to train your agent (ART-E) * SEPT 2025 ACQUISTION https://openpipe.ai/blog/openpipe-coreweave * W&B Serverless RL https://openpipe.ai/blog/serverless-rl?refresh=1760042248153Full Video EpisodeTimestamps00:00 Introductions03:15 The Evolution of OpenPipe: From SFT to RL07:49 The Mistral Era and LoRA Adapters11:40 When You Actually Need Fine-Tuning14:43 The Pivot to Reinforcement Learning21:29 GRPO vs PPO: The Technical Trade-offs24:02 The Environment Problem in RL35:52 JAPA and Automated Prompt Optimization44:35 Open vs Closed Models: The Token Economics50:38 Ruler: Self-Supervised RL Rewards57:09 World Models as Environment Solutions1:00:15 CoreWeave Acquisition and Future Vision This is a public episode. If you'd like to discuss this with other subscribers or get access to bonus episodes, visit www.latent.space/subscribe
DevDay 2025: Apps SDK, Agent Kit, MCP, Codex and why Prompting is More Important than Ever
At OpenAI DevDay, we sit down with Sherwin Wu and Christina Huang from the OpenAI Platform Team to discuss the launch of AgentKit - a comprehensive suite of tools for building, deploying, and optimizing AI agents. Christina walks us through the live demo she performed on stage, building a customer support agent in just 8 minutes using the visual Agent Builder, while Sherwin shares insights on how OpenAI is inverting the traditional website-chatbot paradigm by embedding apps directly within ChatGPT through the new Apps SDK.The conversation explores how OpenAI is tackling the challenges developers face when taking agents to production - from writing and optimizing prompts to building evaluation pipelines. They discuss the decision to adopt Anthropic’s MCP protocol for tool connectivity, the importance of visual workflows for complex agent systems, and how features like human-in-the-loop approvals and automated prompt optimization are making agent development more accessible to a broader range of developers.Sherwin and Christina also reveal how OpenAI is dogfooding these tools internally, with their own customer support at openai.com already powered by AgentKit, and share candid insights about the evolution from plugins to GPTs to this new agent platform. They discuss the surprising persistence of prompting as a critical skill (contrary to predictions from two years ago), the challenges of serving custom fine-tuned models at scale, and why they believe visual agent builders are essential as workflows grow to span dozens of nodes.Guests:* Sherwin Wu: Head of Engineering, OpenAI Platform https://www.linkedin.com/in/sherwinwu1/ https://x.com/sherwinwu?lang=en* Christina Huang: Platform Experience, OpenAI https://x.com/christinaahuang https://www.linkedin.com/in/christinaahuang/Thanks very much to Lindsay and Shaokyi for helping us set up this great deepdive into the new DevDay launches!Key Topics:• AgentKit launch: Agent SDK, Builder, Evals, and deployment tools• Apps SDK and the inversion of the app-chatbot paradigm• Adopting MCP protocol for universal tool connectivity• Visual agent building vs code-first approaches• Human-in-the-loop workflows and approval systems• Automated prompt optimization and “zero-gradient fine-tuning”• Service Health Dashboard and achieving five nines reliability• ChatKit as an embeddable, evergreen chat interface• The evolution from plugins to GPTs to agent platforms• Internal dogfooding with Codex and agent-powered supportFull Video EpisodeTimestamps00:00 Welcome to the OpenAI Dev Day Studio01:11 Dev Day Evolution and Community Growth03:08 Apps SDK and ChatGPT Distribution Strategy05:27 MCP Protocol Integration Decision09:26 Agent Kit Launch and Platform Vision11:33 Agent Builder Canvas and Visual Workflows17:22 Evaluations and Agent Testing Evolution19:20 Automated Prompt Optimization and Research26:35 Connector Registry and MCP Servers34:10 Chat Kit as Consumer-Grade Infrastructure39:13 Codex Power User Tips and AI-Native Development42:27 Service Health Dashboard and Reliability Journey This is a public episode. If you'd like to discuss this with other subscribers or get access to bonus episodes, visit www.latent.space/subscribe
Taste is your Moat (Dylan Field of Figma)
Dylan Field (CEO Figma) on how they are letting designers build with Figma Make, how Figma can be the context repository for aesthetic in the age of vibe coding, and why design is your only differentiator now.Full show notes: https://www.latent.space/p/figma This is a public episode. If you'd like to discuss this with other subscribers or get access to bonus episodes, visit www.latent.space/subscribe
Amp: The Emperor Has No Clothes
Quinn Slack (CEO) and Thorsten Ball (Amp Dictator) from SourceGraph join the show to talk about Amp Code, how they ship 15x/day with no code reviews, and why subagents and prompt optimizers aren’t a promising direction for coding agents.Amp Code: https://ampcode.com/Latent Space: https://latent.space/Full Video EpisodeTimestamps00:00 Introduction00:41 Transition from Cody to Amp03:18 The Importance of Building the Best Coding Agent06:43 Adapting to a Rapidly Evolving AI Tooling Landscape09:36 Dogfooding at Sourcegraph12:35 CLI vs. VS Code Extension21:08 Positioning Amp in Coding Agent Market24:10 The Diminishing Importance of Model Selectors32:39 Tooling vs. Harness37:19 Common Failure Modes of Coding Agents47:33 Agent-Friendly Logging and Tooling52:31 Are Subagents Real?56:52 New Frameworks and Agent-Integrated Developer Tools1:00:25 How Agents Are Encouraging Codebase and Workflow Changes1:03:13 Evolving Outer Loop Tasks1:07:09 Version Control and Merge Conflicts in an AI-First World1:10:36 Rise of User-Generated Enterprise Software1:14:39 Empowering Technical Leaders with AI1:17:11 Evaluating Product Without Traditional Evals1:20:58 Hiring This is a public episode. If you'd like to discuss this with other subscribers or get access to bonus episodes, visit www.latent.space/subscribe
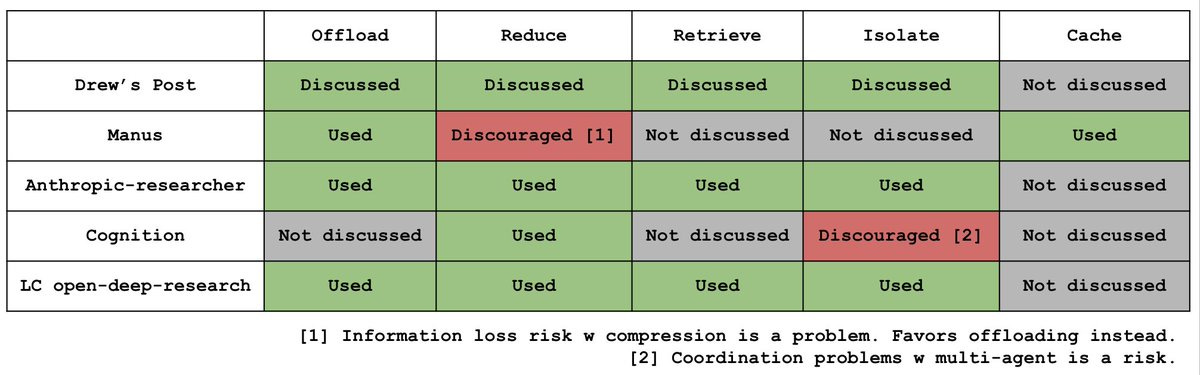
Context Engineering for Agents - Lance Martin, LangChain
Lance: https://www.linkedin.com/in/lance-martin-64a33b5/How Context Fails: https://www.dbreunig.com/2025/06/22/how-contexts-fail-and-how-to-fix-them.htmlHow New Buzzwords Get Created: https://www.dbreunig.com/2025/07/24/why-the-term-context-engineering-matters.htmlContent Engineering: https://rlancemartin.github.io/2025/06/23/context_engineering/ https://docs.google.com/presentation/d/16aaXLu40GugY-kOpqDU4e-S0hD1FmHcNyF0rRRnb1OU/edit?usp=sharingManus Post: https://manus.im/blog/Context-Engineering-for-AI-Agents-Lessons-from-Building-ManusCognition Post: https://cognition.ai/blog/dont-build-multi-agentsMulti-Agent Researcher: https://www.anthropic.com/engineering/multi-agent-research-systemHuman-in-the-loop + Memory: https://github.com/langchain-ai/agents-from-scratch- Bitter Lesson in AI Engineering -Hyung Won Chung on the Bitter Lesson in AI Research: Bitter Lesson w/ Claude Code: Learning the Bitter Lesson in AI Engineering: https://rlancemartin.github.io/2025/07/30/bitter_lesson/Open Deep Research: https://github.com/langchain-ai/open_deep_research https://academy.langchain.com/courses/deep-research-with-langgraphScaling and building things that “don’t yet work”: - Frameworks -Roast framework at Shopify / standardization of orchestration tools: MCP adoption within Anthropic / standardization of protocols: How to think about frameworks: https://blog.langchain.com/how-to-think-about-agent-frameworks/RAG benchmarking: https://rlancemartin.github.io/2025/04/03/vibe-code/Simon’s talk with memory-gone-wrong: https://simonwillison.net/2025/Jun/6/six-months-in-llms/Full Video EpisodeTimestamps00:00 Introduction and Background00:53 The Rise of Context Engineering01:57 Context Engineering vs Prompt Engineering05:56 The Five Categories of Context Engineering10:02 Multi-Agent Systems and Context Isolation14:48 Classical Retrieval vs Agentic Search17:12 LLMs.txt and MCP Servers24:51 Context Pruning and Memory Management37:25 Memory Systems and Human-in-the-Loop42:55 The Bitter Lesson Applied to AI Engineering51:21 Frameworks, Abstractions, and Building for the Future This is a public episode. If you'd like to discuss this with other subscribers or get access to bonus episodes, visit www.latent.space/subscribe
Better Data is All You Need — Ari Morcos, Datology
Our chat with Ari shows that data curation is the most impactful and underinvested area in AI. He argues that the prevailing focus on model architecture and compute scaling overlooks the “bitter lesson” that “models are what they eat.” Effective data curation—a sophisticated process involving filtering, rebalancing, sequencing (curriculum), and synthetic data generation—allows for training models that are simultaneously faster, better, and smaller. Morcos recounts his personal journey from focusing on model-centric inductive biases to realizing that data quality is the primary lever for breaking the diminishing returns of naive scaling laws. Datology’s mission is to automate this complex curation process, making state-of-the-art data accessible to any organization and enabling a new paradigm of AI development where data efficiency, not just raw scale, drives progress.Full Video EpisodeTimestamps00:00 Introduction00:46 What is Datology? The mission to train models faster, better, and smaller through data curation.01:59 Ari’s background: From neuroscience to realizing the “Bitter Lesson” of AI.05:30 Key Insight: Inductive biases from architecture become less important and even harmful as data scale increases.08:08 Thesis: Data is the most underinvested area of AI research relative to its impact.10:15 Why data work is culturally undervalued in research and industry.12:19 How self-supervised learning changed everything, moving from a data-scarce to a data-abundant regime.17:05 Why automated curation is superior to human-in-the-loop, citing the DCLM study.19:22 The “Elephants vs. Dogs” analogy for managing data redundancy and complexity.22:46 A brief history and commentary on key datasets (Common Crawl, GitHub, Books3).26:24 Breaking naive scaling laws by improving data quality to maintain high marginal information gain.29:07 Datology’s demonstrated impact: Achieving baseline performance 12x faster.34:19 The business of data: Datology’s moat and its relationship with open-source datasets.39:12 Synthetic Data Explained: The difference between risky “net-new” creation and powerful “rephrasing.”49:02 The Resurgence of Curriculum Learning: Why ordering data matters in the underfitting regime.52:55 The Future of Training: Optimizing pre-training data to make post-training more effective.54:49 Who is training their own models and why (Sovereign AI, large enterprises).57:24 “Train Smaller”: Why inference cost makes smaller, specialized models the ultimate goal for enterprises.01:00:19 The problem with model pruning and why data-side solutions are complementary.01:03:03 On finding the smallest possible model for a given capability.01:06:49 Key learnings from the RC foundation model collaboration, proving that data curation “stacks.”01:09:46 Lightning Round: What data everyone wants & who should work at Datology.01:14:24 Commentary on Meta’s superintelligence efforts and Yann LeCun’s role. This is a public episode. If you'd like to discuss this with other subscribers or get access to bonus episodes, visit www.latent.space/subscribe
The RLVR Revolution — with Nathan Lambert (AI2, Interconnects.ai)
We first had Nathan on to give us his RLHF deep dive when he was joining AI2, and now he’s back to help us catch up on the evolution to RLVR (Reinforcement Learning with Verifiable Rewards), first proposed in his Tulu 3 paper. While RLHF remains foundational, RLVR has emerged as a powerful approach for training models on tasks with clear success criteria and using verifiable, objective functions as reward signals—particularly useful in domains like math, code correctness, and instruction-following. Instead of relying solely on subjective human feedback, RLVR leverages deterministic signals to guide optimization, making it more scalable and potentially more reliable across many domains. However, he notes that RLVR is still rapidly evolving, especially regarding how it handles tool use and multi-step reasoning.We also discussed the Tulu model series, a family of instruction-tuned open models developed at AI2. Tulu is designed to be a reproducible, state-of-the-art post-training recipe for the open community. Unlike frontier labs like OpenAI or Anthropic, which rely on vast and often proprietary datasets, Tulu aims to distill and democratize best practices for instruction and preference tuning. We are impressed with how small eval suites, careful task selection, and transparent methodology can rival even the best proprietary models on specific benchmarks.One of the most fascinating threads is the challenge of incorporating tool use into RL frameworks. Lambert highlights that while you can prompt a model to use tools like search or code execution, getting the model to reliably learn when and how to use them through RL is much harder. This is compounded by the difficulty of designing reward functions that avoid overoptimization—where models learn to “game” the reward signal rather than solve the underlying task. This is particularly problematic in code generation, where models might reward hack unit tests by inserting pass statements instead of correct logic. As models become more agentic and are expected to plan, retrieve, and act across multiple tools, reward design becomes a critical bottleneck.Other topics covered:- The evolution from RLHF (Reinforcement Learning from Human Feedback) to RLVR (Reinforcement Learning from Verifiable Rewards)- The goals and technical architecture of the Tulu models, including the motivation to open-source post-training recipes- Challenges of tool use in RL: verifiability, reward design, and scaling across domains- Evaluation frameworks and the role of platforms like Chatbot Arena and emerging “arena”-style benchmarks- The strategic tension between hybrid reasoning models and unified reasoning models at the frontier- Planning, abstraction, and calibration in reasoning agents and why these concepts matter- The future of open-source AI models, including DeepSeek, OLMo, and the potential for an “American DeepSeek”- The importance of model personality, character tuning, and the model spec paradigm- Overoptimization in RL settings and how it manifests in different domains (control tasks, code, math)- Industry trends in inference-time scaling and model parallelismFinally, the episode closes with a vision for the future of open-source AI. Nathan has now written up his ambition to build an “American DeepSeek”—a fully open, end-to-end reasoning-capable model with transparent training data, tools, and infrastructure. He emphasizes that open-source AI is not just about weights; it’s about releasing recipes, evaluations, and methods that lower the barrier for everyone to build and understand cutting-edge systems. Full Video EpisodeTimestamps00:00 Welcome and Guest Introduction01:18 Tulu, OVR, and the RLVR Journey03:40 Industry Approaches to Post-Training and Preference Data06:08 Understanding RLVR and Its Impact06:18 Agents, Tool Use, and Training Environments10:34 Open Data, Human Feedback, and Benchmarking12:44 Chatbot Arena, Sycophancy, and Evaluation Platforms15:42 RLHF vs RLVR: Books, Algorithms, and Future Directions17:54 Frontier Models: Reasoning, Hybrid Models, and Data22:11 Search, Retrieval, and Emerging Model Capabilities29:23 Tool Use, Curriculum, and Model Training Challenges38:06 Skills, Planning, and Abstraction in Agent Models46:50 Parallelism, Verifiers, and Scaling Approaches54:33 Overoptimization and Reward Design in RL1:02:27 Open Models, Personalization, and the Model Spec1:06:50 Open Model Ecosystem and Infrastructure1:13:05 Meta, Hardware, and the Future of AI Competition1:15:42 Building an Open DeepSeek and Closing Thoughts This is a public episode. If you'd like to discuss this with other subscribers or get access to bonus episodes, visit www.latent.space/subscribe
AI is Eating Search
ChatGPT handles 2.5B prompts/day and is on track to match Google’s daily searches by end of 2026. AI agents don’t browse like us—they crave queryable, chunkable data for tools like ChatGPT & Perplexity. A new industry is being born, some are calling it AI SEO, others GEO, but what is clear is that it drives amazing results. Businesses are seeing 2-4x higher conversion from visitors coming from AI compared to traditional search. Robert McCloy is the co-founder of Scrunch AI (https://scrunchai.com/), a fast growing company that helps brands and businesses re-write their content on the fly based on what agents are looking for.Full Video EpisodeTimestamps00:00 Intro & Guest Introduction01:30 The Genesis of Scrunch AI & AI Search Impact06:02 AI Search Engines vs. Traditional SEO06:28 Monitoring Prompts & The AI Search Stack08:26 AI Training Data, Crawlers, and Content Strategy12:33 AI Browsers and the Future of Web Consumption16:06 Technical Mechanisms of AI Search & SEO Relevance28:44 Personalization, Agent Experience, and Customer Journeys30:44 Prompt Clusters, User Intent, and B2B Buying Patterns36:06 Optimization Tactics: Prompt Injection, Content, and Pitfalls40:37 Technical Content Delivery: JavaScript, Programmatic SEO, and LMS.txt47:31 Case Studies & Conversion Optimization51:36 Market Share & Platform Trends in AI Search55:10 Wrap-Up & Future of AI-Driven Web This is a public episode. If you'd like to discuss this with other subscribers or get access to bonus episodes, visit www.latent.space/subscribe
Cline: the open source coding agent that doesn't cut costs
Saoud Rizwan and Pash from Cline joined us to talk about why fast apply models got bitter lesson’d, how they pioneered the plan + act paradigm for coding, and why non-technical people use IDEs to do marketing and generate slides.Full writeup: https://www.latent.space/p/clineX: https://x.com/latentspacepodFull Video EpisodeTimestamps00:00 - Introductions 01:35 - Plan and Act Paradigm 05:37 - Model Evaluation and Early Development of Cline 08:14 - Use Cases of Cline Beyond Coding 09:09 - Why Cline is a VS Code Extension and Not a Fork 12:07 - Economic Value of Programming Agents 16:07 - Early Adoption for MCPs 19:35 - Local vs Remote MCP Servers 22:10 - Anthropic’s Role in MCP Registry 22:49 - Most Popular MCPs and Their Use Cases 25:26 - Challenges and Future of MCP Monetization 27:32 - Security and Trust Issues with MCPs 28:56 - Alternative History Without MCP 29:43 - Market Positioning of Coding Agents and IDE Integration Matrix 32:57 - Visibility and Autonomy in Coding Agents 35:21 - Evolving Definition of Complexity in Programming Tasks 38:16 - Forks of Cline and Open Source Regrets 40:07 - Simplicity vs Complexity in Agent Design 46:33 - How Fast Apply Got Bitter Lesson’d 49:12 - Cline’s Business Model and Bring-Your-Own-API-Key Approach 54:18 - Integration with OpenRouter and Enterprise Infrastructure 55:32 - Impact of Declining Model Costs 57:48 - Background Agents and Multi-Agent Systems 1:00:42 - Vision and Multi-Modalities 1:01:07 - State of Context Engineering 1:07:37 - Memory Systems in Coding Agents 1:10:14 - Standardizing Rules Files Across Agent Tools 1:11:16 - Cline’s Personality and Anthropomorphization 1:12:55 - Hiring at Cline and Team Culture This is a public episode. If you'd like to discuss this with other subscribers or get access to bonus episodes, visit www.latent.space/subscribe
Personalized AI Language Education — with Andrew Hsu, Speak
Speak (https://speak.com) may not be very well known to native English speakers, but they have come from a slow start in 2016 to emerge as one of the favorite partners of OpenAI, with their Startup Fund leading and joining their Series B and C as one of the new AI-native unicorns, noting that “Speak has the potential to revolutionize not just language learning, but education broadly”.Today we speak with Speak’s CTO, Andrew Hsu, on the journey of building the “3rd generation” of language learning software (with Rosetta Stone being Gen 1, and Duolingo being Gen 2). Speak’s premise is that speech and language models can now do what was previously only possible with human tutors—provide fluent, responsive, and adaptive instruction—and this belief has shaped its product and company strategy since its early days.https://www.linkedin.com/in/adhsu/https://speak.comOne of the most interesting strategic decisions discussed in the episode is Speak’s early focus on South Korea. While counterintuitive for a San Francisco-based startup, the decision was influenced by a combination of market opportunity and founder proximity via a Korean first employee. South Korea’s intense demand for English fluency and a highly competitive education market made it a proving ground for a deeply AI-native product. By succeeding in a market saturated with human-based education solutions, Speak validated its model and built strong product-market fit before expanding to other Asian markets and eventually, globally.The arrival of Whisper and GPT-based LLMs in 2022 marked a turning point for Speak. Suddenly, capabilities that were once theoretical—real-time feedback, semantic understanding, conversational memory—became technically feasible. Speak didn’t pivot, but rather evolved into its second phase: from a supplemental practice tool to a full-featured language tutor. This transition required significant engineering work, including building custom ASR models, managing latency, and integrating real-time APIs for interactive lessons. It also unlocked the possibility of developing voice-first, immersive roleplay experiences and a roadmap to real-time conversational fluency.To scale globally and support many languages, Speak is investing heavily in AI-generated curriculum and content. Instead of manually scripting all lessons, they are building agents and pipelines that can scaffold curriculum, generate lesson content, and adapt pedagogically to the learner. This ties into one of Speak’s most ambitious goals: creating a knowledge graph that captures what a learner knows and can do in a target language, and then adapting the course path accordingly. This level-adjusting tutor model aims to personalize learning at scale and could eventually be applied beyond language learning to any educational domain.Finally, the conversation touches on the broader implications of AI-powered education and the slow real-world adoption of transformative AI technologies. Despite the capabilities of GPT-4 and others, most people’s daily lives haven’t changed dramatically. Speak sees itself as part of the generation of startups that will translate AI’s raw power into tangible consumer value. The company is also a testament to long-term conviction—founded in 2016, it weathered years of slow growth before AI caught up to its vision. Now, with over $50M ARR, a growing B2B arm, and plans to expand across languages and learning domains, Speak represents what AI-native education could look like in the next decade.Full Video EpisodeTimestamps00:00 Introductions & Thiel Fellowship Origins02:13 Genesis of Speak: Early Vision & Market Focus03:44 Building the Product: Iterations and Lessons Learned10:59 AI’s Role in Language Learning13:49 Scaling Globally & B2B Expansion16:30 Why Korea? Localizing for Success19:08 Content Creation, The Speak Method, and Engineering Culture23:31 The Impact of Whisper and LLM Advances29:08 AI-Generated Content & Measuring Fluency35:30 Personalization, Dialects, and Pronunciation39:38 Immersive Learning, Multimodality, and Real-Time Voice50:02 Engineering Challenges & Company Culture53:20 Beyond Languages: B2B, Knowledge Graphs, and Broader Learning57:32 Fun Stories, Lessons, and Reflections1:02:03 Final Thoughts: The Future of AI Learning & Slow Takeoff This is a public episode. If you'd like to discuss this with other subscribers or get access to bonus episodes, visit www.latent.space/subscribe
AI Video Is Eating The World — Olivia and Justine Moore, a16z
When the first video diffusion models started emerging, they were little more than just “moving pictures” - still frames extended a few seconds in either direction in time. There was a ton of excitement about OpenAI’s Sora on release through 2024, but so far only Sora-lite has been widely released. Meanwhile, other good videogen models like Genmo Mochi, Pika, MiniMax T2V, Tencent Hunyuan Video, and Kuaishou’s Kling have emerged, but the reigning king this year seems to be Google’s Veo 3, which for the first time has added native audio generation into their model capabilities, eliminating the need for a whole class of lipsynching tooling and SFX editing.The rise of Veo 3 unlocks a whole new category of AI Video creators that many of our audience may not have been exposed to, but is undeniably effective and important particularly in the “kids” and “brainrot” segments of the global consumer internet platforms like Tiktok, YouTube and Instagram.By far the best documentarians of these trends for laypeople are Olivia and Justine Moore, both partners at a16z, who not only collate the best examples from all over the web, but dabble in video creation themselves to put theory into practice. We’ve been thinking of dabbling in AI brainrot on a secondary channel for Latent Space, so we wanted to get the braindump from the Moore twins on how to make a Latent Space Brainrot channel. Jump on in!Full Video EpisodeTimestamps00:00 Introductions & Guest Welcome00:49 The Rise of Generative Media02:24 AI Video Trends: Italian Brain Rot & Viral Characters05:00 Following Trends & Creating AI Content07:17 Hands-On with AI Video Creation18:36 Monetization & Business of AI Content23:34 Platforms, Models, and the Creator Stack37:22 Native Content vs. Clipping & Going Viral41:52 Prompt Theory & Meta-Trends in AI Creativity47:42 Professional, Commercial, and Platform-Specific AI Video48:57 Wrap-Up & Final Thoughts This is a public episode. If you'd like to discuss this with other subscribers or get access to bonus episodes, visit www.latent.space/subscribe
Information Theory for Language Models: Jack Morris
Our last AI PhD grad student feature was Shunyu Yao, who happened to focus on Language Agents for his thesis and immediately went to work on them for OpenAI. Our pick this year is Jack Morris, who bucks the “hot” trends by -not- working on agents, benchmarks, or VS Code forks, but is rather known for his work on the information theoretic understanding of LLMs, starting from embedding models and latent space representations (always close to our heart).Jack is an unusual combination of doing underrated research but somehow still being to explain them well to a mass audience, so we felt this was a good opportunity to do a different kind of episode going through the greatest hits of a high profile AI PhD, and relate them to questions from AI Engineering.Papers and References made* AI grad school:* A new type of information theory:* Embeddings* Text Embeddings Reveal (Almost) As Much As Text: https://arxiv.org/abs/2310.06816* Contextual document embeddings https://arxiv.org/abs/2410.02525Harnessing the Universal Geometry of Embeddings: https://arxiv.org/abs/2505.12540* Language models* GPT-style language models memorize 3.6 bits per param: * Approximating Language Model Training Data from Weights: https://arxiv.org/abs/2506.15553* LLM Inversion* “There Are No New Ideas In AI.... Only New Datasets”* misc reference: https://junyanz.github.io/CycleGAN/—for others hiring AI PhDs, Jack also wanted to shout out his coauthorZach Nussbaum, his coauthor on Nomic Embed: Training a Reproducible Long Context Text Embedder.Full Video EpisodeTimestamps00:00 Introduction to Jack Morris01:18 Career in AI03:29 The Shift to AI Companies03:57 The Impact of ChatGPT04:26 The Role of Academia in AI05:49 The Emergence of Reasoning Models07:07 Challenges in Academia: GPUs and HPC Training11:04 The Value of GPU Knowledge14:24 Introduction to Jack's Research15:28 Information Theory17:10 Understanding Deep Learning Systems19:00 The "Bit" in Deep Learning20:25 Wikipedia and Information Storage23:50 Text Embeddings and Information Compression27:08 The Research Journey of Embedding Inversion31:22 Harnessing the Universal Geometry of Embeddings34:54 Implications of Embedding Inversion36:02 Limitations of Embedding Inversion38:08 The Capacity of Language Models40:23 The Cognitive Core and Model Efficiency50:40 The Future of AI and Model Scaling52:47 Approximating Language Model Training Data from Weights01:06:50 The "No New Ideas, Only New Datasets" Thesis This is a public episode. If you'd like to discuss this with other subscribers or get access to bonus episodes, visit www.latent.space/subscribe
Scaling Test Time Compute to Multi-Agent Civilizations — Noam Brown, OpenAI
Solving Poker and Diplomacy, Debating RL+Reasoning with Ilya, what’s *wrong* with the System 1/2 analogy, and where Test-Time Compute hits a wallFull Video EpisodeTimestamps00:00 Intro – Diplomacy, Cicero & World Championship 02:00 Reverse Centaur: How AI Improved Noam’s Human Play 05:00 Turing Test Failures in Chat: Hallucinations & Steerability 07:30 Reasoning Models & Fast vs. Slow Thinking Paradigm 11:00 System 1 vs. System 2 in Visual Tasks (GeoGuessr, Tic-Tac-Toe) 14:00 The Deep Research Existence Proof for Unverifiable Domains 17:30 Harnesses, Tool Use, and Fragility in AI Agents 21:00 The Case Against Over-Reliance on Scaffolds and Routers 24:00 Reinforcement Fine-Tuning and Long-Term Model Adaptability 28:00 Ilya’s Bet on Reasoning and the O-Series Breakthrough 34:00 Noam’s Dev Stack: Codex, Windsurf & AGI Moments 38:00 Building Better AI Developers: Memory, Reuse, and PR Reviews 41:00 Multi-Agent Intelligence and the “AI Civilization” Hypothesis 44:30 Implicit World Models and Theory of Mind Through Scaling 48:00 Why Self-Play Breaks Down Beyond Go and Chess 54:00 Designing Better Benchmarks for Fuzzy Tasks 57:30 The Real Limits of Test-Time Compute: Cost vs. Time 1:00:30 Data Efficiency Gaps Between Humans and LLMs 1:03:00 Training Pipeline: Pretraining, Midtraining, Posttraining 1:05:00 Games as Research Proving Grounds: Poker, MTG, Stratego 1:10:00 Closing Thoughts – Five-Year View and Open Research Directions This is a public episode. If you'd like to discuss this with other subscribers or get access to bonus episodes, visit www.latent.space/subscribe
The Utility of Interpretability — Emmanuel Amiesen
Emmanuel Amiesen is lead author of “Circuit Tracing: Revealing Computational Graphs in Language Models” (https://transformer-circuits.pub/2025/attribution-graphs/methods.html ), which is part of a duo of MechInterp papers that Anthropic published in March (alongside https://transformer-circuits.pub/2025/attribution-graphs/biology.html ).We recorded the initial conversation a month ago, but then held off publishing until the open source tooling for the graph generation discussed in this work was released last week: https://www.anthropic.com/research/open-source-circuit-tracingThis is a 2 part episode - an intro covering the open source release, then a deeper dive into the paper — with guest host Vibhu Sapra (https://x.com/vibhuuuus ) and Mochi the MechInterp Pomsky (https://x.com/mochipomsky ). Thanks to Vibhu for making this episode happen!While the original blogpost contained some fantastic guided visualizations (which we discuss at the end of this pod!), with the notebook and Neuronpedia visualization (https://www.neuronpedia.org/gemma-2-2b/graph ) released this week, you can now explore on your own with Neuronpedia, as we show you in the video version of this pod.Full Video EpisodeTimestamps00:00 Intro & Guest Introductions01:00 Anthropic's Circuit Tracing Release06:11 Exploring Circuit Tracing Tools & Demos13:01 Model Behaviors and User Experiments17:02 Behind the Research: Team and Community24:19 Main Episode Start: Mech Interp Backgrounds25:56 Getting Into Mech Interp Research31:52 History and Foundations of Mech Interp37:05 Core Concepts: Superposition & Features39:54 Applications & Interventions in Models45:59 Challenges & Open Questions in Interpretability57:15 Understanding Model Mechanisms: Circuits & Reasoning01:04:24 Model Planning, Reasoning, and Attribution Graphs01:30:52 Faithfulness, Deception, and Parallel Circuits01:40:16 Publishing Risks, Open Research, and Visualization01:49:33 Barriers, Vision, and Call to Action This is a public episode. If you'd like to discuss this with other subscribers or get access to bonus episodes, visit www.latent.space/subscribe
[AIEWF Preview] Containing Agent Chaos — Solomon Hykes
Solomon most famously created Docker and now runs Dagger… which has something special to share with you on Thursday.Catch Dagger at:- Tuesday: Dagger’s workshop https://www.ai.engineer/schedule#ship-agents-that-ship-a-hands-on-workshop-for-swe-agent-builders- Wednesday: Dagger’s talk: https://www.ai.engineer/schedule#how-to-trust-an-agent-with-software-delivery- Thursday: Solomon’s Keynote https://www.ai.engineer/schedule#containing-agent-chaosFull Video EpisodeTimestamps00:00 Introduction & Guest Background00:29 What is Dagger? Post-Development Automation01:08 Dagger’s Community & Platform Engineers02:32 AI Agents and Developer Workflows03:40 Environment Isolation & The Power of Containers06:28 The Need for Standards in Agent Environments07:25 Design Constraints & Challenges for Dev Environments11:26 Limitations of Current Tools & Agent-Native UX14:11 Modularity, Customization, and the Lego Analogy16:24 Convergence of CICD and Agentic Systems17:41 Ephemeral Apps, Resource Constraints, and Local Execution21:01 Adoption, Ecosystem, and the Role of Open Source23:30 Dagger’s Modular Approach & Integration Philosophy25:38 Looking Ahead: Workshops, Keynotes, and the Future of Agentic Infrastructure This is a public episode. If you'd like to discuss this with other subscribers or get access to bonus episodes, visit www.latent.space/subscribe