
Latent Space: The AI Engineer Podcast
298 episodes — Page 4 of 6
⚡️Math Olympiad gold medalist explains OpenAI and Google DeepMind IMO Gold Performances
AI is Eating Search
ChatGPT handles 2.5B prompts/day and is on track to match Google’s daily searches by end of 2026. AI agents don’t browse like us—they crave queryable, chunkable data for tools like ChatGPT & Perplexity. A new industry is being born, some are calling it AI SEO, others GEO, but what is clear is that it drives amazing results. Businesses are seeing 2-4x higher conversion from visitors coming from AI compared to traditional search. Robert McCloy is the co-founder of Scrunch AI (https://scrunchai.com/), a fast growing company that helps brands and businesses re-write their content on the fly based on what agents are looking for.Full Video EpisodeTimestamps00:00 Intro & Guest Introduction01:30 The Genesis of Scrunch AI & AI Search Impact06:02 AI Search Engines vs. Traditional SEO06:28 Monitoring Prompts & The AI Search Stack08:26 AI Training Data, Crawlers, and Content Strategy12:33 AI Browsers and the Future of Web Consumption16:06 Technical Mechanisms of AI Search & SEO Relevance28:44 Personalization, Agent Experience, and Customer Journeys30:44 Prompt Clusters, User Intent, and B2B Buying Patterns36:06 Optimization Tactics: Prompt Injection, Content, and Pitfalls40:37 Technical Content Delivery: JavaScript, Programmatic SEO, and LMS.txt47:31 Case Studies & Conversion Optimization51:36 Market Share & Platform Trends in AI Search55:10 Wrap-Up & Future of AI-Driven Web This is a public episode. If you'd like to discuss this with other subscribers or get access to bonus episodes, visit www.latent.space/subscribe
⚡️ARC-AGI-3: The Interactive Reasoning Benchmark
⚡️The Future of Notebooks - with Akshay Agrawal of Marimo
Cline: the open source coding agent that doesn't cut costs
Saoud Rizwan and Pash from Cline joined us to talk about why fast apply models got bitter lesson’d, how they pioneered the plan + act paradigm for coding, and why non-technical people use IDEs to do marketing and generate slides.Full writeup: https://www.latent.space/p/clineX: https://x.com/latentspacepodFull Video EpisodeTimestamps00:00 - Introductions 01:35 - Plan and Act Paradigm 05:37 - Model Evaluation and Early Development of Cline 08:14 - Use Cases of Cline Beyond Coding 09:09 - Why Cline is a VS Code Extension and Not a Fork 12:07 - Economic Value of Programming Agents 16:07 - Early Adoption for MCPs 19:35 - Local vs Remote MCP Servers 22:10 - Anthropic’s Role in MCP Registry 22:49 - Most Popular MCPs and Their Use Cases 25:26 - Challenges and Future of MCP Monetization 27:32 - Security and Trust Issues with MCPs 28:56 - Alternative History Without MCP 29:43 - Market Positioning of Coding Agents and IDE Integration Matrix 32:57 - Visibility and Autonomy in Coding Agents 35:21 - Evolving Definition of Complexity in Programming Tasks 38:16 - Forks of Cline and Open Source Regrets 40:07 - Simplicity vs Complexity in Agent Design 46:33 - How Fast Apply Got Bitter Lesson’d 49:12 - Cline’s Business Model and Bring-Your-Own-API-Key Approach 54:18 - Integration with OpenRouter and Enterprise Infrastructure 55:32 - Impact of Declining Model Costs 57:48 - Background Agents and Multi-Agent Systems 1:00:42 - Vision and Multi-Modalities 1:01:07 - State of Context Engineering 1:07:37 - Memory Systems in Coding Agents 1:10:14 - Standardizing Rules Files Across Agent Tools 1:11:16 - Cline’s Personality and Anthropomorphization 1:12:55 - Hiring at Cline and Team Culture This is a public episode. If you'd like to discuss this with other subscribers or get access to bonus episodes, visit www.latent.space/subscribe
⚡️Ranking Agentic LLMs — Pratik Bhavsar, Galileo
Personalized AI Language Education — with Andrew Hsu, Speak
Speak (https://speak.com) may not be very well known to native English speakers, but they have come from a slow start in 2016 to emerge as one of the favorite partners of OpenAI, with their Startup Fund leading and joining their Series B and C as one of the new AI-native unicorns, noting that “Speak has the potential to revolutionize not just language learning, but education broadly”.Today we speak with Speak’s CTO, Andrew Hsu, on the journey of building the “3rd generation” of language learning software (with Rosetta Stone being Gen 1, and Duolingo being Gen 2). Speak’s premise is that speech and language models can now do what was previously only possible with human tutors—provide fluent, responsive, and adaptive instruction—and this belief has shaped its product and company strategy since its early days.https://www.linkedin.com/in/adhsu/https://speak.comOne of the most interesting strategic decisions discussed in the episode is Speak’s early focus on South Korea. While counterintuitive for a San Francisco-based startup, the decision was influenced by a combination of market opportunity and founder proximity via a Korean first employee. South Korea’s intense demand for English fluency and a highly competitive education market made it a proving ground for a deeply AI-native product. By succeeding in a market saturated with human-based education solutions, Speak validated its model and built strong product-market fit before expanding to other Asian markets and eventually, globally.The arrival of Whisper and GPT-based LLMs in 2022 marked a turning point for Speak. Suddenly, capabilities that were once theoretical—real-time feedback, semantic understanding, conversational memory—became technically feasible. Speak didn’t pivot, but rather evolved into its second phase: from a supplemental practice tool to a full-featured language tutor. This transition required significant engineering work, including building custom ASR models, managing latency, and integrating real-time APIs for interactive lessons. It also unlocked the possibility of developing voice-first, immersive roleplay experiences and a roadmap to real-time conversational fluency.To scale globally and support many languages, Speak is investing heavily in AI-generated curriculum and content. Instead of manually scripting all lessons, they are building agents and pipelines that can scaffold curriculum, generate lesson content, and adapt pedagogically to the learner. This ties into one of Speak’s most ambitious goals: creating a knowledge graph that captures what a learner knows and can do in a target language, and then adapting the course path accordingly. This level-adjusting tutor model aims to personalize learning at scale and could eventually be applied beyond language learning to any educational domain.Finally, the conversation touches on the broader implications of AI-powered education and the slow real-world adoption of transformative AI technologies. Despite the capabilities of GPT-4 and others, most people’s daily lives haven’t changed dramatically. Speak sees itself as part of the generation of startups that will translate AI’s raw power into tangible consumer value. The company is also a testament to long-term conviction—founded in 2016, it weathered years of slow growth before AI caught up to its vision. Now, with over $50M ARR, a growing B2B arm, and plans to expand across languages and learning domains, Speak represents what AI-native education could look like in the next decade.Full Video EpisodeTimestamps00:00 Introductions & Thiel Fellowship Origins02:13 Genesis of Speak: Early Vision & Market Focus03:44 Building the Product: Iterations and Lessons Learned10:59 AI’s Role in Language Learning13:49 Scaling Globally & B2B Expansion16:30 Why Korea? Localizing for Success19:08 Content Creation, The Speak Method, and Engineering Culture23:31 The Impact of Whisper and LLM Advances29:08 AI-Generated Content & Measuring Fluency35:30 Personalization, Dialects, and Pronunciation39:38 Immersive Learning, Multimodality, and Real-Time Voice50:02 Engineering Challenges & Company Culture53:20 Beyond Languages: B2B, Knowledge Graphs, and Broader Learning57:32 Fun Stories, Lessons, and Reflections1:02:03 Final Thoughts: The Future of AI Learning & Slow Takeoff This is a public episode. If you'd like to discuss this with other subscribers or get access to bonus episodes, visit www.latent.space/subscribe
AI Video Is Eating The World — Olivia and Justine Moore, a16z
When the first video diffusion models started emerging, they were little more than just “moving pictures” - still frames extended a few seconds in either direction in time. There was a ton of excitement about OpenAI’s Sora on release through 2024, but so far only Sora-lite has been widely released. Meanwhile, other good videogen models like Genmo Mochi, Pika, MiniMax T2V, Tencent Hunyuan Video, and Kuaishou’s Kling have emerged, but the reigning king this year seems to be Google’s Veo 3, which for the first time has added native audio generation into their model capabilities, eliminating the need for a whole class of lipsynching tooling and SFX editing.The rise of Veo 3 unlocks a whole new category of AI Video creators that many of our audience may not have been exposed to, but is undeniably effective and important particularly in the “kids” and “brainrot” segments of the global consumer internet platforms like Tiktok, YouTube and Instagram.By far the best documentarians of these trends for laypeople are Olivia and Justine Moore, both partners at a16z, who not only collate the best examples from all over the web, but dabble in video creation themselves to put theory into practice. We’ve been thinking of dabbling in AI brainrot on a secondary channel for Latent Space, so we wanted to get the braindump from the Moore twins on how to make a Latent Space Brainrot channel. Jump on in!Full Video EpisodeTimestamps00:00 Introductions & Guest Welcome00:49 The Rise of Generative Media02:24 AI Video Trends: Italian Brain Rot & Viral Characters05:00 Following Trends & Creating AI Content07:17 Hands-On with AI Video Creation18:36 Monetization & Business of AI Content23:34 Platforms, Models, and the Creator Stack37:22 Native Content vs. Clipping & Going Viral41:52 Prompt Theory & Meta-Trends in AI Creativity47:42 Professional, Commercial, and Platform-Specific AI Video48:57 Wrap-Up & Final Thoughts This is a public episode. If you'd like to discuss this with other subscribers or get access to bonus episodes, visit www.latent.space/subscribe
⚡️Anthropic vs Cognition on Multi-Agents: A Breakdown with Dylan Davis
Information Theory for Language Models: Jack Morris
Our last AI PhD grad student feature was Shunyu Yao, who happened to focus on Language Agents for his thesis and immediately went to work on them for OpenAI. Our pick this year is Jack Morris, who bucks the “hot” trends by -not- working on agents, benchmarks, or VS Code forks, but is rather known for his work on the information theoretic understanding of LLMs, starting from embedding models and latent space representations (always close to our heart).Jack is an unusual combination of doing underrated research but somehow still being to explain them well to a mass audience, so we felt this was a good opportunity to do a different kind of episode going through the greatest hits of a high profile AI PhD, and relate them to questions from AI Engineering.Papers and References made* AI grad school:* A new type of information theory:* Embeddings* Text Embeddings Reveal (Almost) As Much As Text: https://arxiv.org/abs/2310.06816* Contextual document embeddings https://arxiv.org/abs/2410.02525Harnessing the Universal Geometry of Embeddings: https://arxiv.org/abs/2505.12540* Language models* GPT-style language models memorize 3.6 bits per param: * Approximating Language Model Training Data from Weights: https://arxiv.org/abs/2506.15553* LLM Inversion* “There Are No New Ideas In AI.... Only New Datasets”* misc reference: https://junyanz.github.io/CycleGAN/—for others hiring AI PhDs, Jack also wanted to shout out his coauthorZach Nussbaum, his coauthor on Nomic Embed: Training a Reproducible Long Context Text Embedder.Full Video EpisodeTimestamps00:00 Introduction to Jack Morris01:18 Career in AI03:29 The Shift to AI Companies03:57 The Impact of ChatGPT04:26 The Role of Academia in AI05:49 The Emergence of Reasoning Models07:07 Challenges in Academia: GPUs and HPC Training11:04 The Value of GPU Knowledge14:24 Introduction to Jack's Research15:28 Information Theory17:10 Understanding Deep Learning Systems19:00 The "Bit" in Deep Learning20:25 Wikipedia and Information Storage23:50 Text Embeddings and Information Compression27:08 The Research Journey of Embedding Inversion31:22 Harnessing the Universal Geometry of Embeddings34:54 Implications of Embedding Inversion36:02 Limitations of Embedding Inversion38:08 The Capacity of Language Models40:23 The Cognitive Core and Model Efficiency50:40 The Future of AI and Model Scaling52:47 Approximating Language Model Training Data from Weights01:06:50 The "No New Ideas, Only New Datasets" Thesis This is a public episode. If you'd like to discuss this with other subscribers or get access to bonus episodes, visit www.latent.space/subscribe
⚡️Warp 2.0: the Agentic Development Environment - Zach Lloyd and Ben Holmes
Scaling Test Time Compute to Multi-Agent Civilizations — Noam Brown, OpenAI
Solving Poker and Diplomacy, Debating RL+Reasoning with Ilya, what’s *wrong* with the System 1/2 analogy, and where Test-Time Compute hits a wallFull Video EpisodeTimestamps00:00 Intro – Diplomacy, Cicero & World Championship 02:00 Reverse Centaur: How AI Improved Noam’s Human Play 05:00 Turing Test Failures in Chat: Hallucinations & Steerability 07:30 Reasoning Models & Fast vs. Slow Thinking Paradigm 11:00 System 1 vs. System 2 in Visual Tasks (GeoGuessr, Tic-Tac-Toe) 14:00 The Deep Research Existence Proof for Unverifiable Domains 17:30 Harnesses, Tool Use, and Fragility in AI Agents 21:00 The Case Against Over-Reliance on Scaffolds and Routers 24:00 Reinforcement Fine-Tuning and Long-Term Model Adaptability 28:00 Ilya’s Bet on Reasoning and the O-Series Breakthrough 34:00 Noam’s Dev Stack: Codex, Windsurf & AGI Moments 38:00 Building Better AI Developers: Memory, Reuse, and PR Reviews 41:00 Multi-Agent Intelligence and the “AI Civilization” Hypothesis 44:30 Implicit World Models and Theory of Mind Through Scaling 48:00 Why Self-Play Breaks Down Beyond Go and Chess 54:00 Designing Better Benchmarks for Fuzzy Tasks 57:30 The Real Limits of Test-Time Compute: Cost vs. Time 1:00:30 Data Efficiency Gaps Between Humans and LLMs 1:03:00 Training Pipeline: Pretraining, Midtraining, Posttraining 1:05:00 Games as Research Proving Grounds: Poker, MTG, Stratego 1:10:00 Closing Thoughts – Five-Year View and Open Research Directions This is a public episode. If you'd like to discuss this with other subscribers or get access to bonus episodes, visit www.latent.space/subscribe
⚡️Launching AI Diplomacy: the hardest LLM Game Benchmark yet - Alex Duffy
The Utility of Interpretability — Emmanuel Amiesen
Emmanuel Amiesen is lead author of “Circuit Tracing: Revealing Computational Graphs in Language Models” (https://transformer-circuits.pub/2025/attribution-graphs/methods.html ), which is part of a duo of MechInterp papers that Anthropic published in March (alongside https://transformer-circuits.pub/2025/attribution-graphs/biology.html ).We recorded the initial conversation a month ago, but then held off publishing until the open source tooling for the graph generation discussed in this work was released last week: https://www.anthropic.com/research/open-source-circuit-tracingThis is a 2 part episode - an intro covering the open source release, then a deeper dive into the paper — with guest host Vibhu Sapra (https://x.com/vibhuuuus ) and Mochi the MechInterp Pomsky (https://x.com/mochipomsky ). Thanks to Vibhu for making this episode happen!While the original blogpost contained some fantastic guided visualizations (which we discuss at the end of this pod!), with the notebook and Neuronpedia visualization (https://www.neuronpedia.org/gemma-2-2b/graph ) released this week, you can now explore on your own with Neuronpedia, as we show you in the video version of this pod.Full Video EpisodeTimestamps00:00 Intro & Guest Introductions01:00 Anthropic's Circuit Tracing Release06:11 Exploring Circuit Tracing Tools & Demos13:01 Model Behaviors and User Experiments17:02 Behind the Research: Team and Community24:19 Main Episode Start: Mech Interp Backgrounds25:56 Getting Into Mech Interp Research31:52 History and Foundations of Mech Interp37:05 Core Concepts: Superposition & Features39:54 Applications & Interventions in Models45:59 Challenges & Open Questions in Interpretability57:15 Understanding Model Mechanisms: Circuits & Reasoning01:04:24 Model Planning, Reasoning, and Attribution Graphs01:30:52 Faithfulness, Deception, and Parallel Circuits01:40:16 Publishing Risks, Open Research, and Visualization01:49:33 Barriers, Vision, and Call to Action This is a public episode. If you'd like to discuss this with other subscribers or get access to bonus episodes, visit www.latent.space/subscribe
[AIEWF Preview] Containing Agent Chaos — Solomon Hykes
Solomon most famously created Docker and now runs Dagger… which has something special to share with you on Thursday.Catch Dagger at:- Tuesday: Dagger’s workshop https://www.ai.engineer/schedule#ship-agents-that-ship-a-hands-on-workshop-for-swe-agent-builders- Wednesday: Dagger’s talk: https://www.ai.engineer/schedule#how-to-trust-an-agent-with-software-delivery- Thursday: Solomon’s Keynote https://www.ai.engineer/schedule#containing-agent-chaosFull Video EpisodeTimestamps00:00 Introduction & Guest Background00:29 What is Dagger? Post-Development Automation01:08 Dagger’s Community & Platform Engineers02:32 AI Agents and Developer Workflows03:40 Environment Isolation & The Power of Containers06:28 The Need for Standards in Agent Environments07:25 Design Constraints & Challenges for Dev Environments11:26 Limitations of Current Tools & Agent-Native UX14:11 Modularity, Customization, and the Lego Analogy16:24 Convergence of CICD and Agentic Systems17:41 Ephemeral Apps, Resource Constraints, and Local Execution21:01 Adoption, Ecosystem, and the Role of Open Source23:30 Dagger’s Modular Approach & Integration Philosophy25:38 Looking Ahead: Workshops, Keynotes, and the Future of Agentic Infrastructure This is a public episode. If you'd like to discuss this with other subscribers or get access to bonus episodes, visit www.latent.space/subscribe
[AIEWF Preview] Gemini in 2025 and Realtime Voice AI
As part of our AI Engineer World’s Fair preview, we’re releasing a special cross podcast recorded with Sam Charrington of TWiML AI at last week’s Google I/O!TUESDAY: Shrestha and Kwindla’s workshop: https://www.ai.engineer/schedule#milliseconds-to-magic-real-time-workflows-using-the-gemini-live-api-and-pipecatTUESDAY: Kwindla’s workshop: https://www.ai.engineer/schedule#building-voice-agents-with-gemini-and-pipecatWEDNESDAY: Shrestha and Kwindla’s talk: https://www.ai.engineer/schedule#milliseconds-to-magic-real-time-workflows-using-the-gemini-live-api-and-pipecatWEDNESDAY: Kwindla’s keynote: https://www.ai.engineer/schedule#-voice-keynote-your-realtime-ai-is-ngmiTHURSDAY: Logan’s keynote: https://www.ai.engineer/schedule#a-year-of-gemini-progress-what-comes-nextCatch all the speakers at AIE (both workshops and talks):Logan Kilpatrick: https://www.latent.space/p/chatgpt-gpt4-hype-and-building-llmShrestha Basu Mallick: https://www.linkedin.com/in/shresthabm/Kwindla Hultman Kramer: https://www.linkedin.com/in/kwkramerFull Video Episode This is a public episode. If you'd like to discuss this with other subscribers or get access to bonus episodes, visit www.latent.space/subscribe
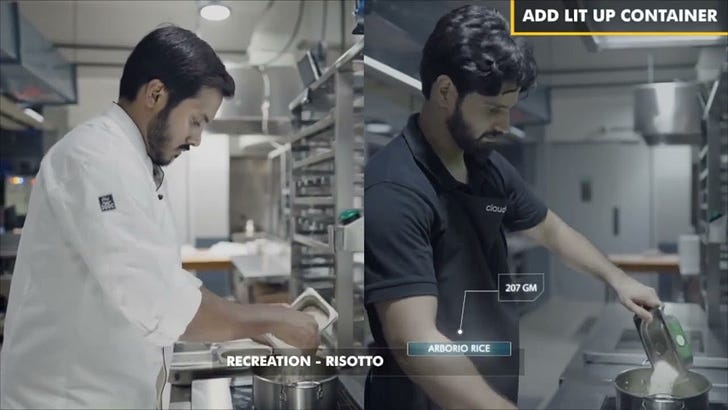
[AIEWF Preview] CloudChef: Your Robot Chef - Michellin-Star food at $12/hr (w/ Kitchen tour!)
One of the new tracks at next week’s AI Engineer conference in SF is a new focus on LLMs + Robotics, ft. household names like Waymo and Physical Intelligence. However there are many other companies applying LLMs and VLMs in the real world!CloudChef, the first industrial-scale kitchen robotics company with one-shot demonstration learning and an incredibly simple business model, will be serving tasty treats all day with Zippy (https://www.cloudchef.co/zippy ) their AI Chef platform.This is a lightning pod with CEO Nikhil Abraham to preview what Zippy is capable of!https://www.cloudchef.co/platformSee a real chef comparison:See it in the AI Engineer Expo at SF next week: https://ai.engineerFull Video EpisodeTimestamps00:00 Welcome and Introductions00:58 What is Cloud Chef?01:36 How the Robots Work: Culinary Intelligence05:57 Commercial Applications and Early Success07:02 The Software-First Approach10:09 Business Model and Pricing13:10 Demonstration Learning: Training the Robots16:03 Call to Action and Engineering Opportunities18:45 Final Thoughts and Technical Details This is a public episode. If you'd like to discuss this with other subscribers or get access to bonus episodes, visit www.latent.space/subscribe
The AI Coding Factory
We are joined by Eno Reyes and Matan Grinberg, the co-founders of Factory.ai. They are building droids for autonomous software engineering, handling everything from code generation to incident response for production outages. After raising a $15M Series A from Sequoia, they just released their product in GA!https://factory.ai/https://x.com/latentspacepodFull Video EpisodeTimestamps00:00 Introductions 00:35 Meeting at Langchain Hackathon 04:02 Building Factory despite early model limitations 06:56 What is Factory AI? 08:55 Delegation vs Collaboration in AI Development Tools 10:06 Naming Origins of 'Factory' and 'Droids' 12:17 Defining Droids: Agent vs Workflow 14:34 Live Demo17:37 Enterprise Context and Tool Integration in Droids 20:26 Prompting, Clarification, and Agent Communication 22:28 Project Understanding and Proactive Context Gathering 24:10 Why SWE-Bench Is Dead 28:47 Model Fine-tuning and Generalization Challenges 31:07 Why Factory is Browser-Based, Not IDE-Based 33:51 Test-Driven Development and Agent Verification 36:17 Retrieval vs Large Context Windows for Cost Efficiency 38:02 Enterprise Metrics: Code Churn and ROI 40:48 Executing Large Refactors and Migrations with Droids 45:25 Model Speed, Parallelism, and Delegation Bottlenecks 50:11 Observability Challenges and Semantic Telemetry 53:44 Hiring55:19 Factory's design and branding approach 58:34 Closing Thoughts and Future of AI-Native Development This is a public episode. If you'd like to discuss this with other subscribers or get access to bonus episodes, visit www.latent.space/subscribe
[AIEWF Preview] Multi-Turn RL for Multi-Hour Agents — with Will Brown, Prime Intellect
In an otherwise heavy week packed with Microsoft Build, Google I/O, and OpenAI io, the worst kept secret in biglab land was the launch of Claude 4, particularly the triumphant return of Opus, which many had been clamoring for. We will leave the specific Claude 4 recap to AINews, however we think that both Gemini’s progress on Deep Think this week and Claude 4 represent the next frontier of progress on inference time compute/reasoning (at last until GPT5 ships this summer).Will Brown’s talk at AIE NYC and open source work on verifiers have made him one of the most prominent voices able to publicly discuss (aka without the vaguepoasting LoRA they put on you when you join a biglab) the current state of the art in reasoning models and where current SOTA research directions lead. We discussed his latest paper on Reinforcing Multi-Turn Reasoning in LLM Agents via Turn-Level Credit Assignment and he has previewed his AIEWF talk on Agentic RL for those with the temerity to power thru bad meetup audio.Full Video EpisodeTimestamps00:00 Introduction to the Podcast and Guests01:00 Discussion on Claude 4 and AI Models03:07 Extended Thinking and Tool Use in AI06:47 Technical Highlights and Model Trustworthiness10:31 Thinking Budgets and Their Implications13:38 Controversy Surrounding Opus and AI Ethics18:49 Reflections on AI Tools and Their Limitations21:58 The Chaos of Predictive Systems22:56 Marketing and Safety in AI Models24:30 Evaluating AI Companies and Their Strategies25:53 The Role of Academia in AI Evaluations27:43 Teaching Taste in Research28:41 Making Educated Bets in AI Research30:12 Recent Developments in Multi-Turn Tool Use32:50 Incentivizing Tool Use in AI Models34:45 The Future of Reward Models in AI39:10 Exploring Flexible Reward Systems This is a public episode. If you'd like to discuss this with other subscribers or get access to bonus episodes, visit www.latent.space/subscribe
⚡️Open Questions in Agentic RL — Will Brown (Prime Intellect)
⚡️The Rise and Fall of the Vector DB Category
Note from your hosts: we were off this week for ICLR and RSA! This week we’re bringing you one of the top episodes from our lightning podcast series, the shorter format, Youtube-only side podcast we do for breaking news and faster turnaround. Please support our work on YouTube! https://www.youtube.com/playlist?list=PLWEAb1SXhjlc5qgVK4NgehdCzMYCwZtiBThe explosion of embedding-based applications created a new challenge: efficiently storing, indexing, and searching these high-dimensional vectors at scale. This gap gave rise to the vector database category, with companies like Pinecone leading the charge in 2022-2023 by defining specialized infrastructure for vector operations.The category saw explosive growth following ChatGPT’s launch in late 2022, as developers rushed to build AI applications using Retrieval-Augmented Generation (RAG). This surge was partly driven by a widespread misconception that embedding-based similarity search was the only viable method for retrieving context for LLMs!!!The resulting “vector database gold rush” saw massive investment and attention directed toward vector search infrastructure, even though traditional information retrieval techniques remained equally valuable for many RAG applications.Full Video EpisodeTimestamps00:00 Introduction to Trondheim and Background03:03 The Rise and Fall of Vector Databases06:08 Convergence of Search Technologies09:04 Embeddings and Their Importance12:03 Building Effective Search Systems15:00 RAG Applications and Recommendations17:55 The Role of Knowledge Graphs20:49 Future of Embedding Models and Innovations This is a public episode. If you'd like to discuss this with other subscribers or get access to bonus episodes, visit www.latent.space/subscribe
⚡️Factorio Learning Environment: the ultimate Game Agent Eval — Jack Hopkins
⚡️GPT 4.1: The New OpenAI Workhorse
We’ll keep this brief because we’re on a tight turnaround: GPT 4.1, previously known as the Quasar and Optimus models, is now live as the natural update for 4o/4o-mini (and the research preview of GPT 4.5). Though it is a general purpose model family, the headline features are:Coding abilities (o1-level SWEBench and SWELancer, but ok Aider)Instruction Following (with a very notable prompting guide)Long Context up to 1m tokens (with new MRCR and Graphwalk benchmarks)Vision (simply o1 level)Cheaper Pricing (cheaper than 4o, greatly improved prompt caching savings)We caught up with returning guest Michelle Pokrass and Josh McGrath to get more detail on each!Full Video EpisodeTimestampsPart 100:00:00 Introduction and Guest Welcome00:00:57 GPT 4.1 Launch Overview00:01:54 Developer Feedback and Model Names00:02:53 Model Naming and Starry Themes00:03:49 Confusion Over GPT 4.1 vs 4.500:04:47 Distillation and Model Improvements00:05:45 Omnimodel Architecture and Future Plans00:06:43 Core Capabilities of GPT 4.100:07:40 Training Techniques and Long Context00:08:37 Challenges in Long Context Reasoning00:09:34 Context Utilization in ModelsPart 200:10:31 Graph Walks and Model Evaluation00:11:31 Real Life Applications of Graph Tasks00:12:30 Multi-Hop Reasoning Benchmarks00:13:30 Agentic Workflows and Backtracking00:14:28 Graph Traversals for Agent Planning00:15:24 Context Usage in API and Memory Systems00:16:21 Model Performance in Long Context Tasks00:17:17 Instruction Following and Real World Data00:18:12 Challenges in Grading Instructions00:19:09 Instruction Following Techniques00:20:09 Prompting Techniques and Model Responses00:21:05 Agentic Workflows and Model PersistencePart 300:22:01 Balancing Persistence and User Control00:22:56 Evaluations on Model Edits and Persistence00:23:55 XML vs JSON in Prompting00:24:50 Instruction Placement in Context00:25:49 Optimizing for Prompt Caching00:26:49 Chain of Thought and Reasoning Models00:27:46 Choosing the Right Model for Your Task00:28:46 Coding Capabilities of GPT 4.100:29:41 Model Performance in Coding Tasks00:30:39 Understanding Coding Model Differences00:31:36 Using Smaller Models for Coding00:32:33 Future of Coding in OpenAIPart 400:33:28 Internal Use and Success Stories00:34:26 Vision and Multi-Modal Capabilities00:35:25 Screen vs Embodied Vision00:36:22 Vision Benchmarks and Model Improvements00:37:19 Model Deprecation and GPU Usage00:38:13 Fine-Tuning and Preference Steering00:39:12 Upcoming Reasoning Models00:40:10 Creative Writing and Model Humor00:41:07 Feedback and Developer Community00:42:03 Pricing and Blended Model Costs00:44:02 Conclusion and Wrap-Up This is a public episode. If you'd like to discuss this with other subscribers or get access to bonus episodes, visit www.latent.space/subscribe
SF Compute: Commoditizing Compute to solve the GPU Bubble forever
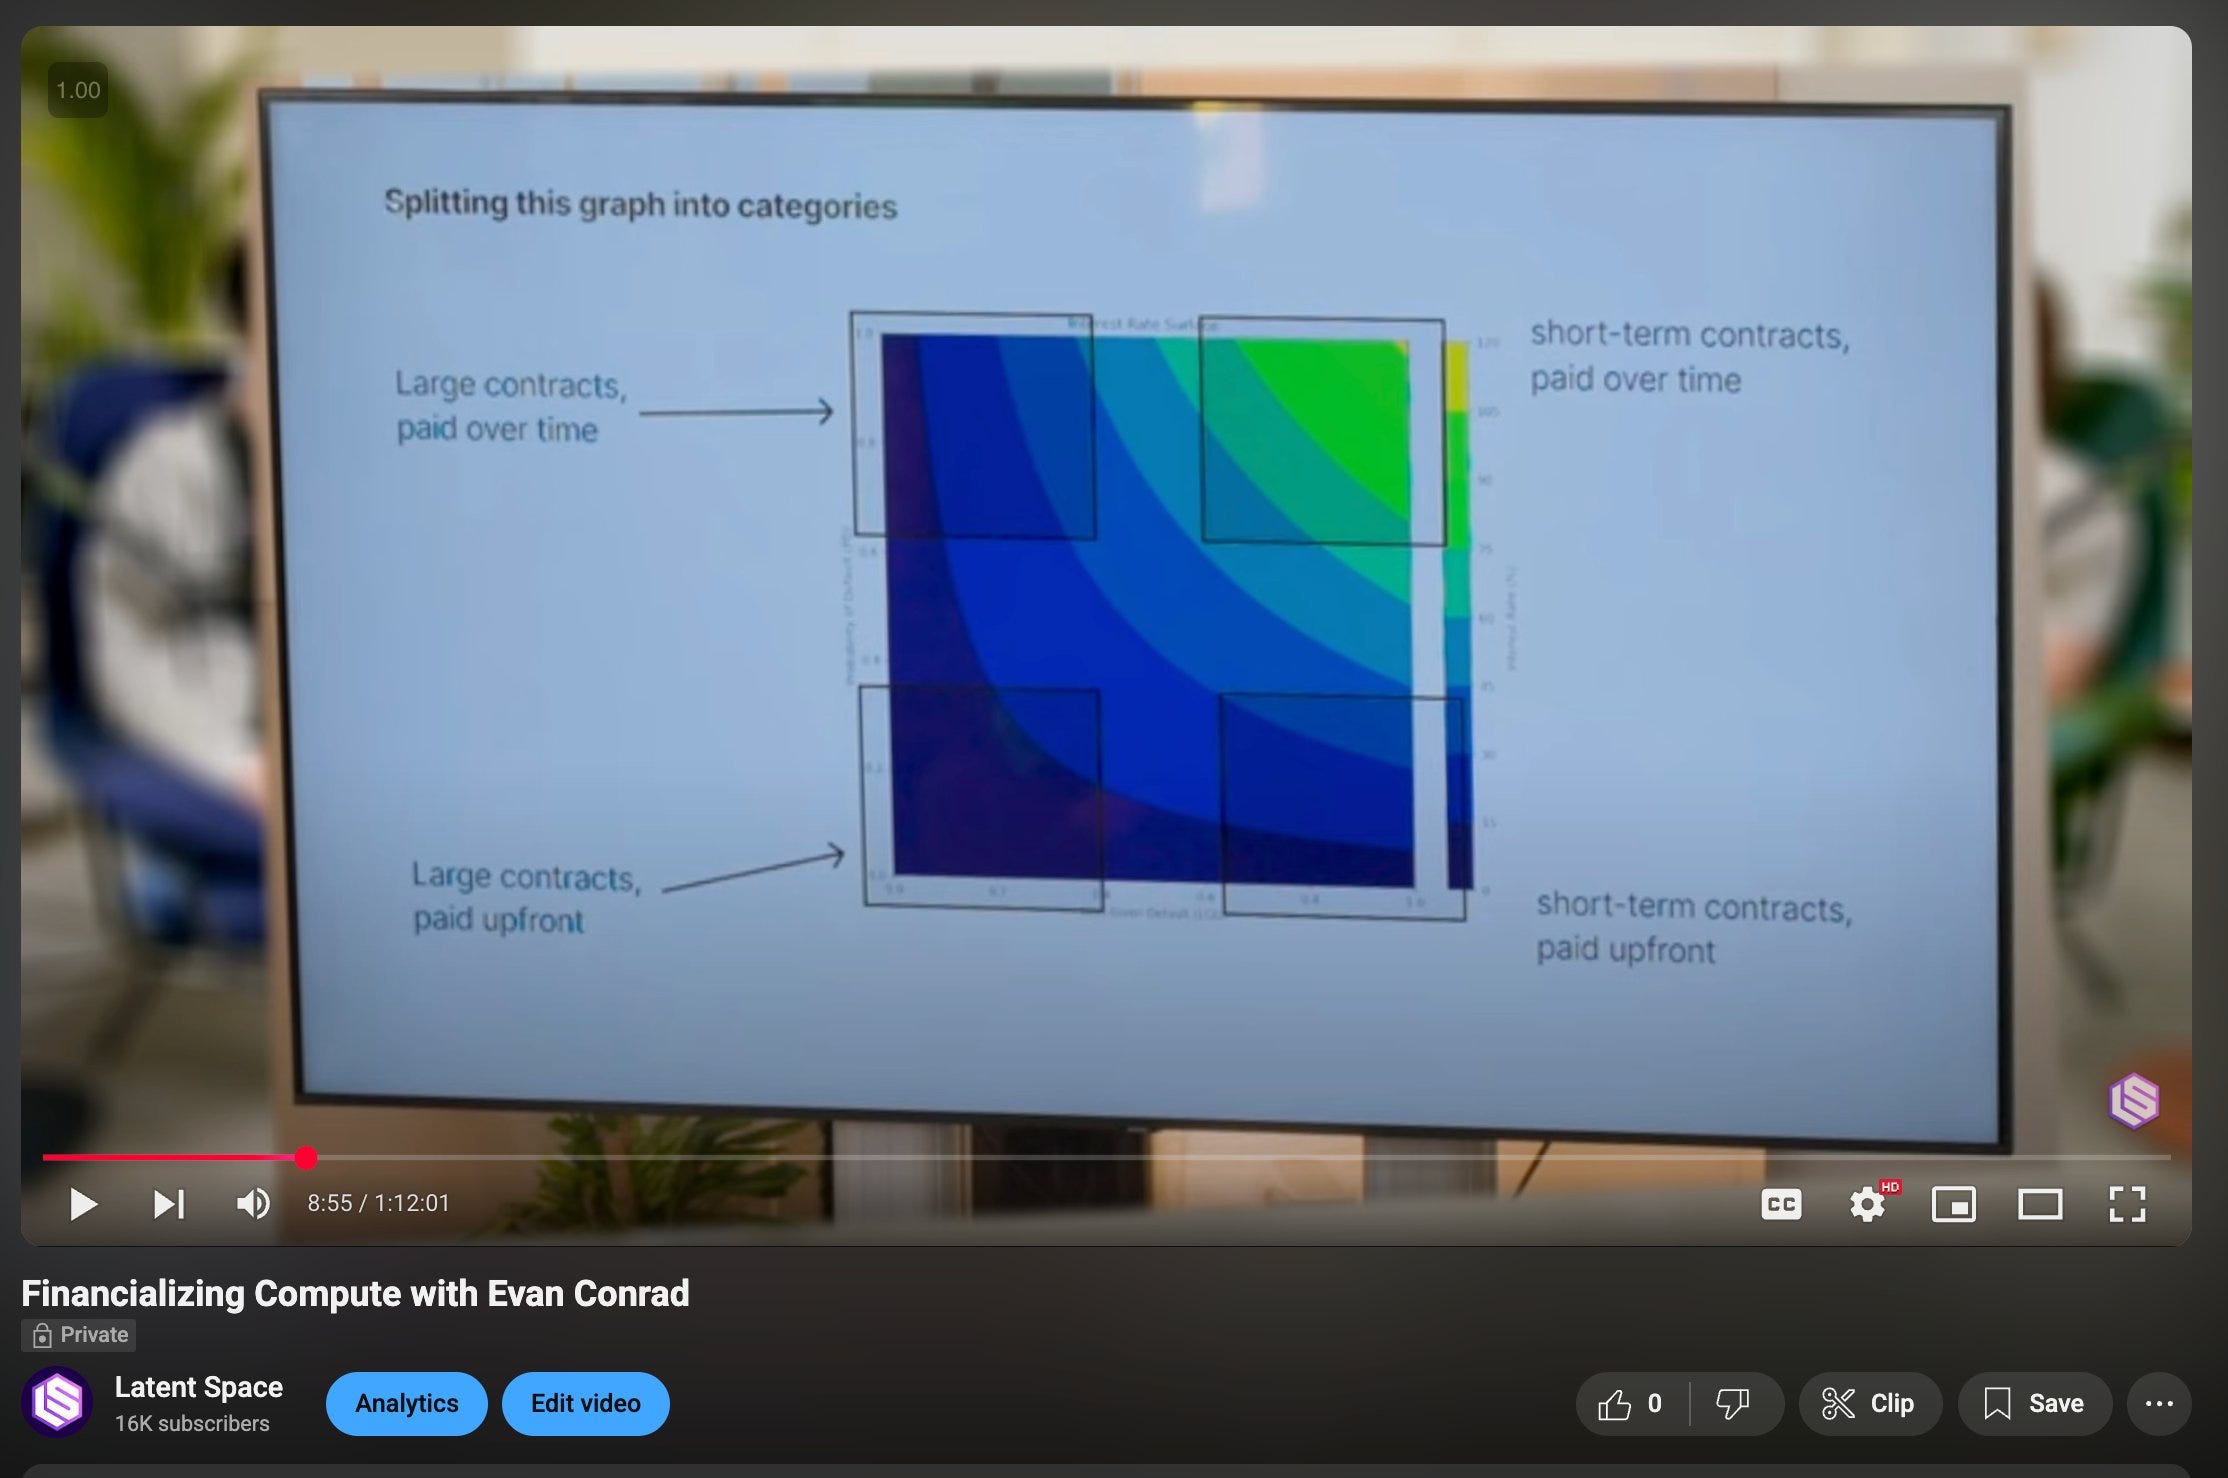
We are calling for the world’s best AI Engineer talks for AI Architects, /r/localLlama, Model Context Protocol (MCP), GraphRAG, AI in Action, Evals, Agent Reliability, Reasoning and RL, Retrieval/Search/RecSys , Security, Infrastructure, Generative Media, AI Design & Novel AI UX, AI Product Management, Autonomy, Robotics, and Embodied Agents, Computer-Using Agents (CUA), SWE Agents, Vibe Coding, Voice, Sales/Support Agents at AIEWF 2025! Fill out the 2025 State of AI Eng survey for $250 in Amazon cards and see you from Jun 3-5 in SF!Coreweave’s now-successful IPO has led to a lot of questions about the GPU Neocloud market, which Dylan Patel has written extensively about on SemiAnalysis. Understanding markets requires an interesting mix of technical and financial expertise, so this will be a different kind of episode than our usual LS domain.When we first published $2 H100s: How the GPU Rental Bubble Burst, we got 2 kinds of reactions on Hacker News:* “Ah, now the AI bubble is imploding!”* “Duh, this is how it works in every GPU cycle, are you new here?”We don’t think either reaction is quite right. Specifically, it is not normal for the prices of one of the world’s most important resources right now to swing from $1 to $8 per hour based on drastically inelastic demand AND supply curves - from 3 year lock-in contracts to stupendously competitive over-ordering dynamics for NVIDIA allocations — especially with increasing baseline compute needed for even the simplest academic ML research and for new AI startups getting off the ground.We’re fortunate today to have Evan Conrad, CEO of SFCompute, one of the most exciting GPU marketplace startups, talk us through his theory of the economics of GPU markets, and why he thinks CoreWeave and Modal are well positioned, but Digital Ocean and Together are not.However, more broadly, the entire point of SFC is creating liquidity between GPU owners and consumers and making it broadly tradable, even programmable:As we explore, these are the primitives that you can then use to create your own, high quality, custom GPU availability for your time and money budget, similar to how Amazon Spot Instances automated the selective buying of unused compute.The ultimate end state of where all this is going is GPU that trade like other perishable, staple commodities of the world - oil, soybeans, milk. Because the contracts and markets are so well established, the price swings also are not nearly as drastic, and people can also start hedging and managing the risk of one of the biggest costs of their business, just like we have risk-managed commodities risks of all other sorts for centuries. As a former derivatives trader, you can bet that swyx doubleclicked on that…Show Notes* SF Compute* Evan Conrad* Ethan Anderson* John Phamous* The Curve talk* CoreWeave* Andromeda ClusterFull Video PodLike and subscribe!Timestamps* [00:00:05] Introductions* [00:00:12] Introduction of guest Evan Conrad from SF Compute* [00:00:12] CoreWeave Business Model Discussion* [00:05:37] CoreWeave as a Real Estate Business* [00:08:59] Interest Rate Risk and GPU Market Strategy Framework* [00:16:33] Why Together and DigitalOcean will lose money on their clusters* [00:20:37] SF Compute's AI Lab Origins* [00:25:49] Utilization Rates and Benefits of SF Compute Market Model* [00:30:00] H100 GPU Glut, Supply Chain Issues, and Future Demand Forecast* [00:34:00] P2P GPU networks* [00:36:50] Customer stories* [00:38:23] VC-Provided GPU Clusters and Credit Risk Arbitrage* [00:41:58] Market Pricing Dynamics and Preemptible GPU Pricing Model* [00:48:00] Future Plans for Financialization?* [00:52:59] Cluster auditing and quality control* [00:58:00] Futures Contracts for GPUs* [01:01:20] Branding and Aesthetic Choices Behind SF Compute* [01:06:30] Lessons from Previous Startups* [01:09:07] Hiring at SF ComputeTranscriptAlessio [00:00:05]: Hey everyone, welcome to the Latent Space podcast. This is Alessio, partner and CTO at Decibel, and I'm joined by my co-host Swyx, founder of Smol AI.Swyx [00:00:12]: Hey, and today we're so excited to be finally in the studio with Evan Conrad from SF Compute. Welcome. I've been fortunate enough to be your friend before you were famous, and also we've hung out at various social things. So it's really cool to see that SF Compute is coming into its own thing, and it's a significant presence, at least in the San Francisco community, which of course, it's in the name, so you couldn't help but be. Evan: Indeed, indeed. I think we have a long way to go, but yeah, thanks. Swyx: Of course, yeah. One way I was thinking about kicking on this conversation is we will likely release this right after CoreWeave IPO. And I was watching, I was looking, doing some research on you. You did a talk at The Curve. I think I may have been viewer number 70. It was a great talk. More people should go see it, Evan Conrad at The Curve. But we have like three orders of magnitude more people. And I just wanted to, to highli
The Creators of Model Context Protocol
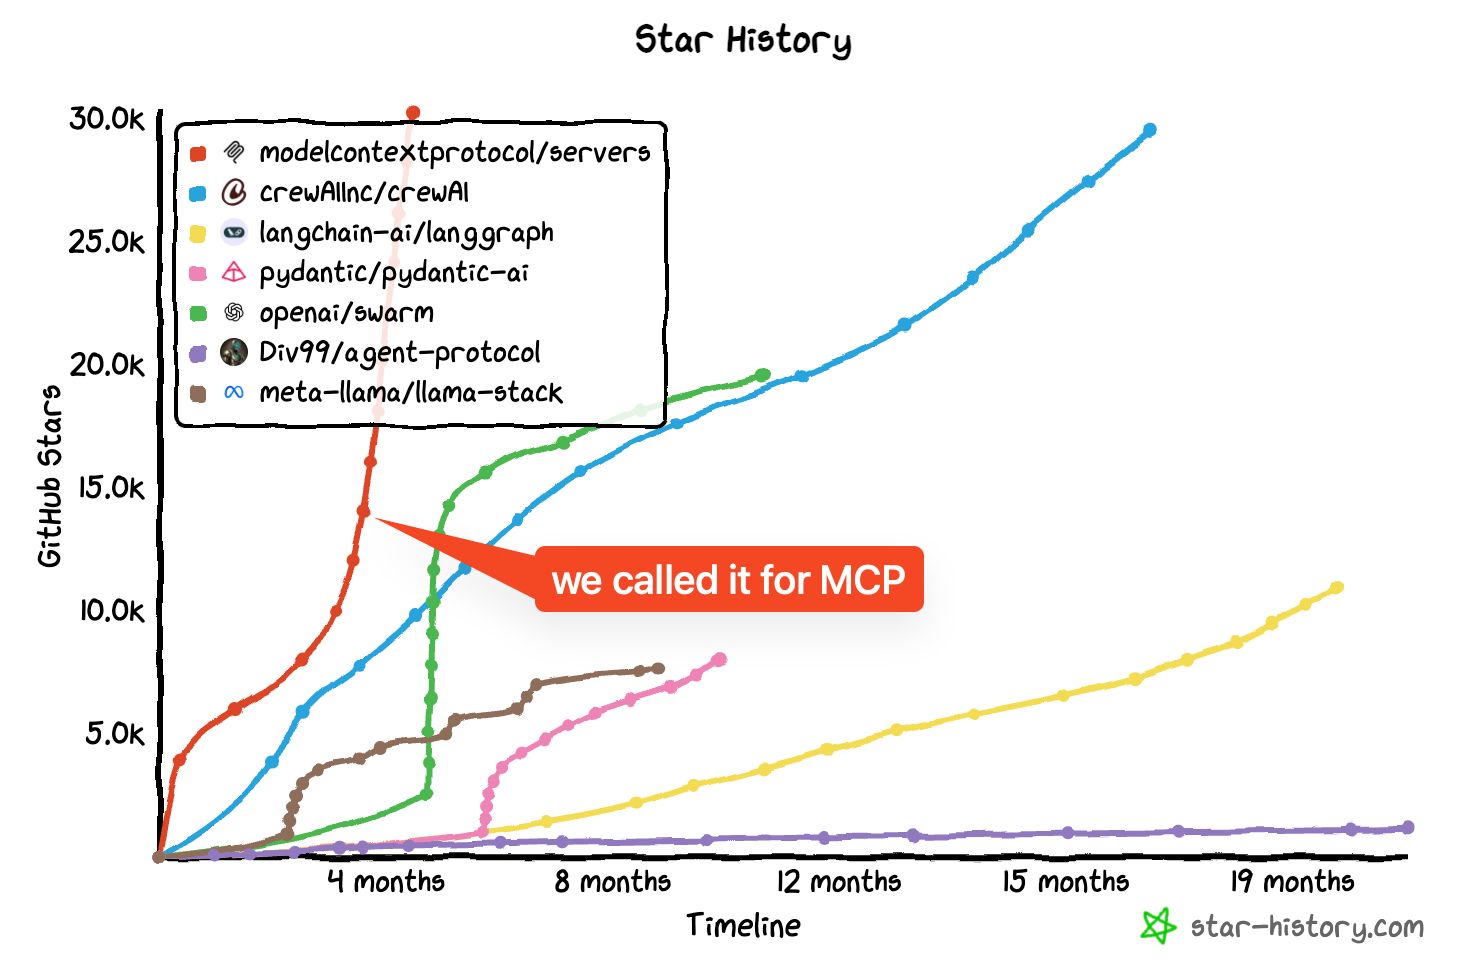
We are happy to announce that there will be a dedicated MCP track at the 2025 AI Engineer World's Fair, taking place Jun 3rd to 5th in San Francisco, where the MCP core team and major contributors and builders will be meeting. Join us and apply to speak or sponsor!When we first wrote Why MCP Won, we had no idea how quickly it was about to win.In the past 4 weeks, OpenAI and now Google have now announced the MCP support, effectively confirming our prediction that MCP was the presumptive winner of the agent standard wars. MCP has now overtaken OpenAPI, the incumbent option and most direct alternative, in GitHub stars (3 months ahead of conservative trendline):We have explored the state of MCP at AIE (now the first ever >100k views workshop):And since then, we’ve added a 7th reason why MCP won - this team acts very quickly on feedback, with the 2025-03-26 spec update adding support for stateless/resumable/streamable HTTP transports, and comprehensive authz capabilities based on OAuth 2.1.This bodes very well for the future of the community and project. For protocol and history nerds, we also asked David and Justin to tell the origin story of MCP, which we leave to the reader to enjoy (you can also skim the transcripts, or, the changelogs of a certain favored IDE). It’s incredible the impact that individual engineers solving their own problems can have on an entire industry.Full video episodeLike and subscribe on YouTube!Show Links* David* Justin* MCP* Why MCP WonTimestamps* 00:00 Introduction and Guest Welcome* 00:37 What is MCP?* 02:00 The Origin Story of MCP* 05:18 Development Challenges and Solutions* 08:06 Technical Details and Inspirations* 29:45 MCP vs Open API* 32:48 Building MCP Servers* 40:39 Exploring Model Independence in LLMs* 41:36 Building Richer Systems with MCP* 43:13 Understanding Agents in MCP* 45:45 Nesting and Tool Confusion in MCP* 49:11 Client Control and Tool Invocation* 52:08 Authorization and Trust in MCP Servers* 01:01:34 Future Roadmap and Stateless Servers* 01:10:07 Open Source Governance and Community Involvement* 01:18:12 Wishlist and Closing RemarksTranscriptAlessio [00:00:02]: Hey, everyone. Welcome back to Latent Space. This is Alessio, partner and CTO at Decibel, and I'm joined by my co-host Swyx, founder of Small AI.swyx [00:00:10]: Hey, morning. And today we have a remote recording, I guess, with David and Justin from Anthropic over in London. Welcome. Hey, good You guys have created a storm of hype because of MCP, and I'm really glad to have you on. Thanks for making the time. What is MCP? Let's start with a crisp what definition from the horse's mouth, and then we'll go into the origin story. But let's start off right off the bat. What is MCP?Justin/David [00:00:43]: Yeah, sure. So Model Context Protocol, or MCP for short, is basically something we've designed to help AI applications extend themselves or integrate with an ecosystem of plugins, basically. The terminology is a bit different. We use this client-server terminology, and we can talk about why that is and where that came from. But at the end of the day, it really is that. It's like extending and enhancing the functionality of AI application.swyx [00:01:05]: David, would you add anything?Justin/David [00:01:07]: Yeah, I think that's actually a good description. I think there's like a lot of different ways for how people are trying to explain it. But at the core, I think what Justin said is like extending AI applications is really what this is about. And I think the interesting bit here that I want to highlight, it's AI applications and not models themselves that this is focused on. That's a common misconception that we can talk about a bit later. But yeah. Another version that we've used and gotten to like is like MCP is kind of like the USB-C port of AI applications and that it's meant to be this universal connector to a whole ecosystem of things.swyx [00:01:44]: Yeah. Specifically, an interesting feature is, like you said, the client and server. And it's a sort of two-way, right? Like in the same way that said a USB-C is two-way, which could be super interesting. Yeah, let's go into a little bit of the origin story. There's many people who've tried to make statistics. There's many people who've tried to build open source. I think there's an overall, also, my sense is that Anthropic is going hard after developers in the way that other labs are not. And so I'm also curious if there was any external influence or was it just you two guys just in a room somewhere riffing?Justin/David [00:02:18]: It is actually mostly like us two guys in a room riffing. So this is not part of a big strategy. You know, if you roll back time a little bit and go into like July 2024. I was like, started. I started at Anthropic like three months earlier or two months earlier. And I was mostly working on internal developer tooling, which is what I've been doing for like years and years before. And as part of that, I think there was an effor
Unsupervised Learning x Latent Space Crossover Special
If you’re in SF: Join us for the Claude Plays Pokemon hackathon this Sunday!If you’re not: Fill out the 2025 State of AI Eng survey for $250 in Amazon cards!Unsupervised Learning is a podcast that interviews the sharpest minds in AI about what’s real today, what will be real in the future and what it means for businesses and the world - helping builders, researchers and founders deconstruct and understand the biggest breakthroughs. Top guests: Noam Shazeer, Bob McGrew, Noam Brown, Dylan Patel, Percy Liang, David LuanFull Episode on Their YouTubeTimestamps* 00:00 Introduction and Excitement for Collaboration* 00:27 Reflecting on Surprises in AI Over the Past Year* 01:44 Open Source Models and Their Adoption* 06:01 The Rise of GPT Wrappers* 06:55 AI Builders and Low-Code Platforms* 09:35 Overhyped and Underhyped AI Trends* 22:17 Product Market Fit in AI* 28:23 Google's Current Momentum* 28:33 Customer Support and AI* 29:54 AI's Impact on Cost and Growth* 31:05 Voice AI and Scheduling* 32:59 Emerging AI Applications* 34:12 Education and AI* 36:34 Defensibility in AI Applications* 40:10 Infrastructure and AI* 47:08 Challenges and Future of AI* 52:15 Quick Fire Round and Closing RemarksTranscript[00:00:00] Introduction and Podcast Overview[00:00:00] Jacob: well, thanks so much for doing this, guys. I feel like we've we've been excited to do a collab for a while. I[00:00:13] swyx: love crossovers. Yeah. Yeah. This, this is great. Like the ultimate meta about just podcasters talking to other podcasters. Yeah. It's a lot. Podcasts all the way up.[00:00:21] Jacob: I figured we'd have a pretty free ranging conversation today but brought a few conversation starters to, to, to kick us off.[00:00:27] Reflecting on AI Surprises and Trends[00:00:27] Jacob: And so I figured one interesting place to start is you know, obviously it feels that this world is changing like every few months. Wondering as you guys reflect path on the past year, like what surprised you the most?[00:00:36] Alessio: I think definitely recently models we kinda on the, on the right here. Like, oh, that, well, I, I I think there's, there's like the, what surprised us in a good way.[00:00:44] May maybe in a, in a bad way. I would say in a good way. Recently models and I think the release of them right after the new reps scaling instead talked by Ilia. I think there was maybe like a, a little. It's so over and then we're so back. I'm like such a short, short period. It was really [00:01:00] fortuitous[00:01:00] Jacob: timing though, like right.[00:01:01] As pre-training died, I mean, obviously I'm sure within the labs they knew pre-training was dying and had to find something. But you know, from the outside it was it, it felt like one right into the other.[00:01:09] Alessio: Yeah. Yeah, exactly. So that, that was a good surprise,[00:01:12] swyx: I would say, if you wanna make that comment about timing, I think it's suspiciously neat that like, because we know that Strawberry was being worked on for like two years-ish.[00:01:20] Like, and we know exactly when Nome joined OpenAI, and that was obviously a big strategic bet by OpenAI. So like, for it to transition, so transition so nicely when like, pre-training is kind of tapped out to, into like, oh, now inference time is, is the new scaling law is like conv very convenient. I, I, I like if there were an Illuminati, this would be what they planned.[00:01:41] Or if we're living in a simulation or something. Yeah.[00:01:44] Open Source Models and Their Impact[00:01:44] swyx: Then you said open source[00:01:45] Alessio: as well? Yeah. Well, no, I, I think like open source. Yeah. We're discussing this on the negative. I would say the relevance of open source. I would specifically open models. Yeah, I was surprised the lack, like the llamas of the world by the lack of adoption.[00:01:56] And I mean, people use it obviously, but I would say nobody's [00:02:00] really like a huge fanboy, you know, I think the local llama community and some of the more obvious use cases really like it. But when we talk to like enterprise folks, it's like, it's cool, you know? And I think people love to argue about licenses and all of that, but the reality is that it doesn't really change the adoption path of, of ai.[00:02:18] So[00:02:19] swyx: yeah, the specific stat that I got from on anchor from Braintrust mm-hmm. In one of the episodes that we did was I think he estimated that open source model usage in work in enterprises is that like 5% and going down.[00:02:31] Jacob: And it feels like you're basically all these enterprises are in like use case discovery mode, where it's like, let's just take what we think is the most powerful model and figure out if we can find anything that works.[00:02:39] And, you know, so much of, of, of it feels like discovery of that. And then, right, as you've discovered something, a new generation of models are out and so you have to go do discovery with those. And you know, I think obviously we're
The Agent Network — Dharmesh Shah
If you’re in SF: Join us for the Claude Plays Pokemon hackathon this Sunday!If you’re not: Fill out the 2025 State of AI Eng survey for $250 in Amazon cards!For this episode: Thanks to Matija and Dan and Meng Shao for sharing on socials.We are SO excited to share our conversation with Dharmesh Shah, co-founder of HubSpot and creator of Agent.ai.A particularly compelling concept we discussed is the idea of "hybrid teams" - the next evolution in workplace organization where human workers collaborate with AI agents as team members. Just as we previously saw hybrid teams emerge in terms of full-time vs. contract workers, or in-office vs. remote workers, Dharmesh predicts that the next frontier will be teams composed of both human and AI members. This raises interesting questions about team dynamics, trust, and how to effectively delegate tasks between human and AI team members.The discussion of business models in AI reveals an important distinction between Work as a Service (WaaS) and Results as a Service (RaaS), something Dharmesh has written extensively about. While RaaS has gained popularity, particularly in customer support applications where outcomes are easily measurable, Dharmesh argues that this model may be over-indexed. Not all AI applications have clearly definable outcomes or consistent economic value per transaction, making WaaS more appropriate in many cases. This insight is particularly relevant for businesses considering how to monetize AI capabilities.The technical challenges of implementing effective agent systems are also explored, particularly around memory and authentication. Shah emphasizes the importance of cross-agent memory sharing and the need for more granular control over data access. He envisions a future where users can selectively share parts of their data with different agents, similar to how OAuth works but with much finer control. This points to significant opportunities in developing infrastructure for secure and efficient agent-to-agent communication and data sharing.Other highlights from our conversation* The Evolution of AI-Powered Agents – Exploring how AI agents have evolved from simple chatbots to sophisticated multi-agent systems, and the role of MCPs in enabling that.* Hybrid Digital Teams and the Future of Work – How AI agents are becoming teammates rather than just tools, and what this means for business operations and knowledge work.* Memory in AI Agents – The importance of persistent memory in AI systems and how shared memory across agents could enhance collaboration and efficiency.* Business Models for AI Agents – Exploring the shift from software as a service (SaaS) to work as a service (WaaS) and results as a service (RaaS), and what this means for monetization.* The Role of Standards Like MCP – Why MCP has been widely adopted and how it enables agent collaboration, tool use, and discovery.* The Future of AI Code Generation and Software Engineering – How AI-assisted coding is changing the role of software engineers and what skills will matter most in the future.* Domain Investing and Efficient Markets – Dharmesh’s approach to domain investing and how inefficiencies in digital asset markets create business opportunities.* The Philosophy of Saying No – Lessons from "Sorry, Must Pass" and how prioritization leads to greater productivity and focus.Full Video Episodeon youtube!Timestamps* 00:00 Introduction and Guest Welcome* 02:29 Dharmesh Shah's Journey into AI* 05:22 Defining AI Agents* 06:45 The Evolution and Future of AI Agents* 13:53 Graph Theory and Knowledge Representation* 20:02 Engineering Practices and Overengineering* 25:57 The Role of Junior Engineers in the AI Era* 28:20 Multi-Agent Systems and MCP Standards* 35:55 LinkedIn's Legal Battles and Data Scraping* 37:32 The Future of AI and Hybrid Teams* 39:19 Building Agent AI: A Professional Network for Agents* 40:43 Challenges and Innovations in Agent AI* 45:02 The Evolution of UI in AI Systems* 01:00:25 Business Models: Work as a Service vs. Results as a Service* 01:09:17 The Future Value of Engineers* 01:09:51 Exploring the Role of Agents* 01:10:28 The Importance of Memory in AI* 01:11:02 Challenges and Opportunities in AI Memory* 01:12:41 Selective Memory and Privacy Concerns* 01:13:27 The Evolution of AI Tools and Platforms* 01:18:23 Domain Names and AI Projects* 01:32:08 Balancing Work and Personal Life* 01:35:52 Final Thoughts and ReflectionsTranscriptAlessio [00:00:04]: Hey everyone, welcome back to the Latent Space podcast. This is Alessio, partner and CTO at Decibel Partners, and I'm joined by my co-host Swyx, founder of Small AI.swyx [00:00:12]: Hello, and today we're super excited to have Dharmesh Shah to join us. I guess your relevant title here is founder of Agent AI.Dharmesh [00:00:20]: Yeah, that's true for this. Yeah, creator of Agent.ai and co-founder of HubSpot.swyx [00:00:25]: Co-founder of HubSpot, which I followed for many years, I think 18 years now, gonna be 19 soon. And you caught,
Building Snipd: The AI Podcast App for Learning
We are working with Amplify on the 2025 State of AI Engineering Survey to be presented at the AIE World’s Fair in SF! Join the survey to shape the future of AI Eng!We first met Snipd (affiliate link! we get a free month, you get a free month. but this is not a sponsored pod, we’ve never done one) over a year ago, and were immediately impressed by the design, but were doubtful about the behavior of snipping as the title behavior:Podcast apps are enormously sticky - Spotify spent almost $1b in podcast acquisitions and exclusive content just to get an 8% bump in market share among normies.However, after a disappointing Overcast 2.0 rewrite with no AI features in the last 3 years, I finally bit the bullet and switched to Snipd. It’s 2025, your podcast app should be able to let you search transcripts of your podcasts. Snipd is the best implementation of this so far.And yet they keep shipping:What impressed us wasn’t just how this tiny team of 4 was able to bootstrap a consumer AI app against massive titans and do so well; but also how seriously they think about learning through podcasts and improving retention of knowledge over time, aka “Duolingo for podcasts”. As an educational AI podcast, that’s a mission we can get behind.Full Video PodFind us on YouTube! This was the first pod we’ve ever shot outdoors!Show Notes* How does Shazam work?* Flutter/FlutterFlow* wav2vec paper* Perplexity Online LLM* Google Search Grounding* Comparing Snipd transcription with our Bee episode* NIPS 2017 Flo Rida* Gustav Söderström - Background AudioTimestamps* [00:00:03] Takeaways from AI Engineer NYC* [00:00:17] Weather in New York.* [00:00:26] Swyx and Snipd.* [00:01:01] Kevin's AI summit experience.* [00:01:31] Zurich and AI.* [00:03:25] SigLIP authors join OpenAI.* [00:03:39] Zurich is very costly.* [00:04:06] The Snipd origin story.* [00:05:24] Introduction to machine learning.* [00:09:28] Snipd and user knowledge extraction.* [00:13:48] App's tech stack, Flutter, Python.* [00:15:11] How speakers are identified.* [00:18:29] The concept of "backgroundable" video.* [00:29:05] Voice cloning technology.* [00:31:03] Using AI agents.* [00:34:32] Snipd's future is multi-modal AI.* [00:36:37] Snipd and existing user behaviour.* [00:42:10] The app, summary, and timestamps.* [00:55:25] The future of AI and podcasting.* [1:14:55] Voice AITranscriptswyx [00:00:03]: Hey, I'm here in New York with Kevin Ben-Smith of Snipd. Welcome.Kevin [00:00:07]: Hi. Hi. Amazing to be here.swyx [00:00:09]: Yeah. This is our first ever, I think, outdoors podcast recording.Kevin [00:00:14]: It's quite a location for the first time, I have to say.swyx [00:00:18]: I was actually unsure because, you know, it's cold. It's like, I checked the temperature. It's like kind of one degree Celsius, but it's not that bad with the sun. No, it's quite nice. Yeah. Especially with our beautiful tea. With the tea. Yeah. Perfect. We're going to talk about Snips. I'm a Snips user. I'm a Snips user. I had to basically, you know, apart from Twitter, it's like the number one use app on my phone. Nice. When I wake up in the morning, I open Snips and I, you know, see what's new. And I think in terms of time spent or usage on my phone, I think it's number one or number two. Nice. Nice. So I really had to talk about it also because I think people interested in AI want to think about like, how can we, we're an AI podcast, we have to talk about the AI podcast app. But before we get there, we just finished. We just finished the AI Engineer Summit and you came for the two days. How was it?Kevin [00:01:07]: It was quite incredible. I mean, for me, the most valuable was just being in the same room with like-minded people who are building the future and who are seeing the future. You know, especially when it comes to AI agents, it's so often I have conversations with friends who are not in the AI world. And it's like so quickly it happens that you, it sounds like you're talking in science fiction. And it's just crazy talk. It was, you know, it's so refreshing to talk with so many other people who already see these things and yeah, be inspired then by them and not always feel like, like, okay, I think I'm just crazy. And like, this will never happen. It really is happening. And for me, it was very valuable. So day two, more relevant, more relevant for you than day one. Yeah. Day two. So day two was the engineering track. Yeah. That was definitely the most valuable for me. Like also as a producer. Practitioner myself, especially there were one or two talks that had to do with voice AI and AI agents with voice. Okay. So that was quite fascinating. Also spoke with the speakers afterwards. Yeah. And yeah, they were also very open and, and, you know, this, this sharing attitudes that's, I think in general, quite prevalent in the AI community. I also learned a lot, like really practical things that I can now take away with me. Yeah.swyx [00:02:25]: I mean, on my side, I, I think I watched only li
⚡️The new OpenAI Agents Platform
While everyone is now repeating that 2025 is the “Year of the Agent”, OpenAI is heads down building towards it. In the first 2 months of the year they released Operator and Deep Research (arguably the most successful agent archetype so far), and today they are bringing a lot of those capabilities to the API:* Responses API* Web Search Tool* Computer Use Tool* File Search Tool* A new open source Agents SDK with integrated Observability ToolsWe cover all this and more in today’s lightning pod on YouTube!More details here:Responses APIIn our Michelle Pokrass episode we talked about the Assistants API needing a redesign. Today OpenAI is launching the Responses API, “a more flexible foundation for developers building agentic applications”. It’s a superset of the chat completion API, and the suggested starting point for developers working with OpenAI models. One of the big upgrades is the new set of built-in tools for the responses API: Web Search, Computer Use, and Files. Web Search ToolWe previously had Exa AI on the podcast to talk about web search for AI. OpenAI is also now joining the race; the Web Search API is actually a new “model” that exposes two 4o fine-tunes: gpt-4o-search-preview and gpt-4o-mini-search-preview. These are the same models that power ChatGPT Search, and are priced at $30/1000 queries and $25/1000 queries respectively. The killer feature is inline citations: you do not only get a link to a page, but also a deep link to exactly where your query was answered in the result page. Computer Use ToolThe model that powers Operator, called Computer-Using-Agent (CUA), is also now available in the API. The computer-use-preview model is SOTA on most benchmarks, achieving 38.1% success on OSWorld for full computer use tasks, 58.1% on WebArena, and 87% on WebVoyager for web-based interactions.As you will notice in the docs, `computer-use-preview` is both a model and a tool through which you can specify the environment. Usage is priced at $3/1M input tokens and $12/1M output tokens, and it’s currently only available to users in tiers 3-5.File Search ToolFile Search was also available in the Assistants API, and it’s now coming to Responses too. OpenAI is bringing search + RAG all under one umbrella, and we’ll definitely see more people trying to find new ways to build all-in-one apps on OpenAI. Usage is priced at $2.50 per thousand queries and file storage at $0.10/GB/day, with the first GB free.Agent SDK: Swarms++!https://github.com/openai/openai-agents-pythonTo bring it all together, after the viral reception to Swarm, OpenAI is releasing an officially supported agents framework (which was previewed at our AI Engineer Summit) with 4 core pieces:* Agents: Easily configurable LLMs with clear instructions and built-in tools.* Handoffs: Intelligently transfer control between agents.* Guardrails: Configurable safety checks for input and output validation.* Tracing & Observability: Visualize agent execution traces to debug and optimize performance.Multi-agent workflows are here to stay!OpenAI is now explicitly designs for a set of common agentic patterns: Workflows, Handoffs, Agents-as-Tools, LLM-as-a-Judge, Parallelization, and Guardrails. OpenAI previewed this in part 2 of their talk at NYC:Further coverage of the launch from Kevin Weil, WSJ, and OpenAIDevs, AMA here.Show Notes* Assistants API* Swarm (OpenAI)* Fine-Tuning in AI* 2024 OpenAI DevDay Recap with Romain* Michelle Pokrass episode (API lead)Timestamps* 00:00 Intros* 02:31 Responses API * 08:34 Web Search API * 17:14 Files Search API * 18:46 Files API vs RAG * 20:06 Computer Use / Operator API * 22:30 Agents SDKAnd of course you can catch up with the full livestream here:TranscriptAlessio [00:00:03]: Hey, everyone. Welcome back to another Latent Space Lightning episode. This is Alessio, partner and CTO at Decibel, and I'm joined by Swyx, founder of Small AI.swyx [00:00:11]: Hi, and today we have a super special episode because we're talking with our old friend Roman. Hi, welcome.Romain [00:00:19]: Thank you. Thank you for having me.swyx [00:00:20]: And Nikunj, who is most famously, if anyone has ever tried to get any access to anything on the API, Nikunj is the guy. So I know your emails because I look forward to them.Nikunj [00:00:30]: Yeah, nice to meet all of you.swyx [00:00:32]: I think that we're basically convening today to talk about the new API. So perhaps you guys want to just kick off. What is OpenAI launching today?Nikunj [00:00:40]: Yeah, so I can kick it off. We're launching a bunch of new things today. We're going to do three new built-in tools. So we're launching the web search tool. This is basically chat GPD for search, but available in the API. We're launching an improved file search tool. So this is you bringing your data to OpenAI. You upload it. We, you know, take care of parsing it, chunking it. We're embedding it, making it searchable, give you this like ready vector store that you can use. So that's the file search tool. An
⚡️How Claude 3.7 Plays Pokémon
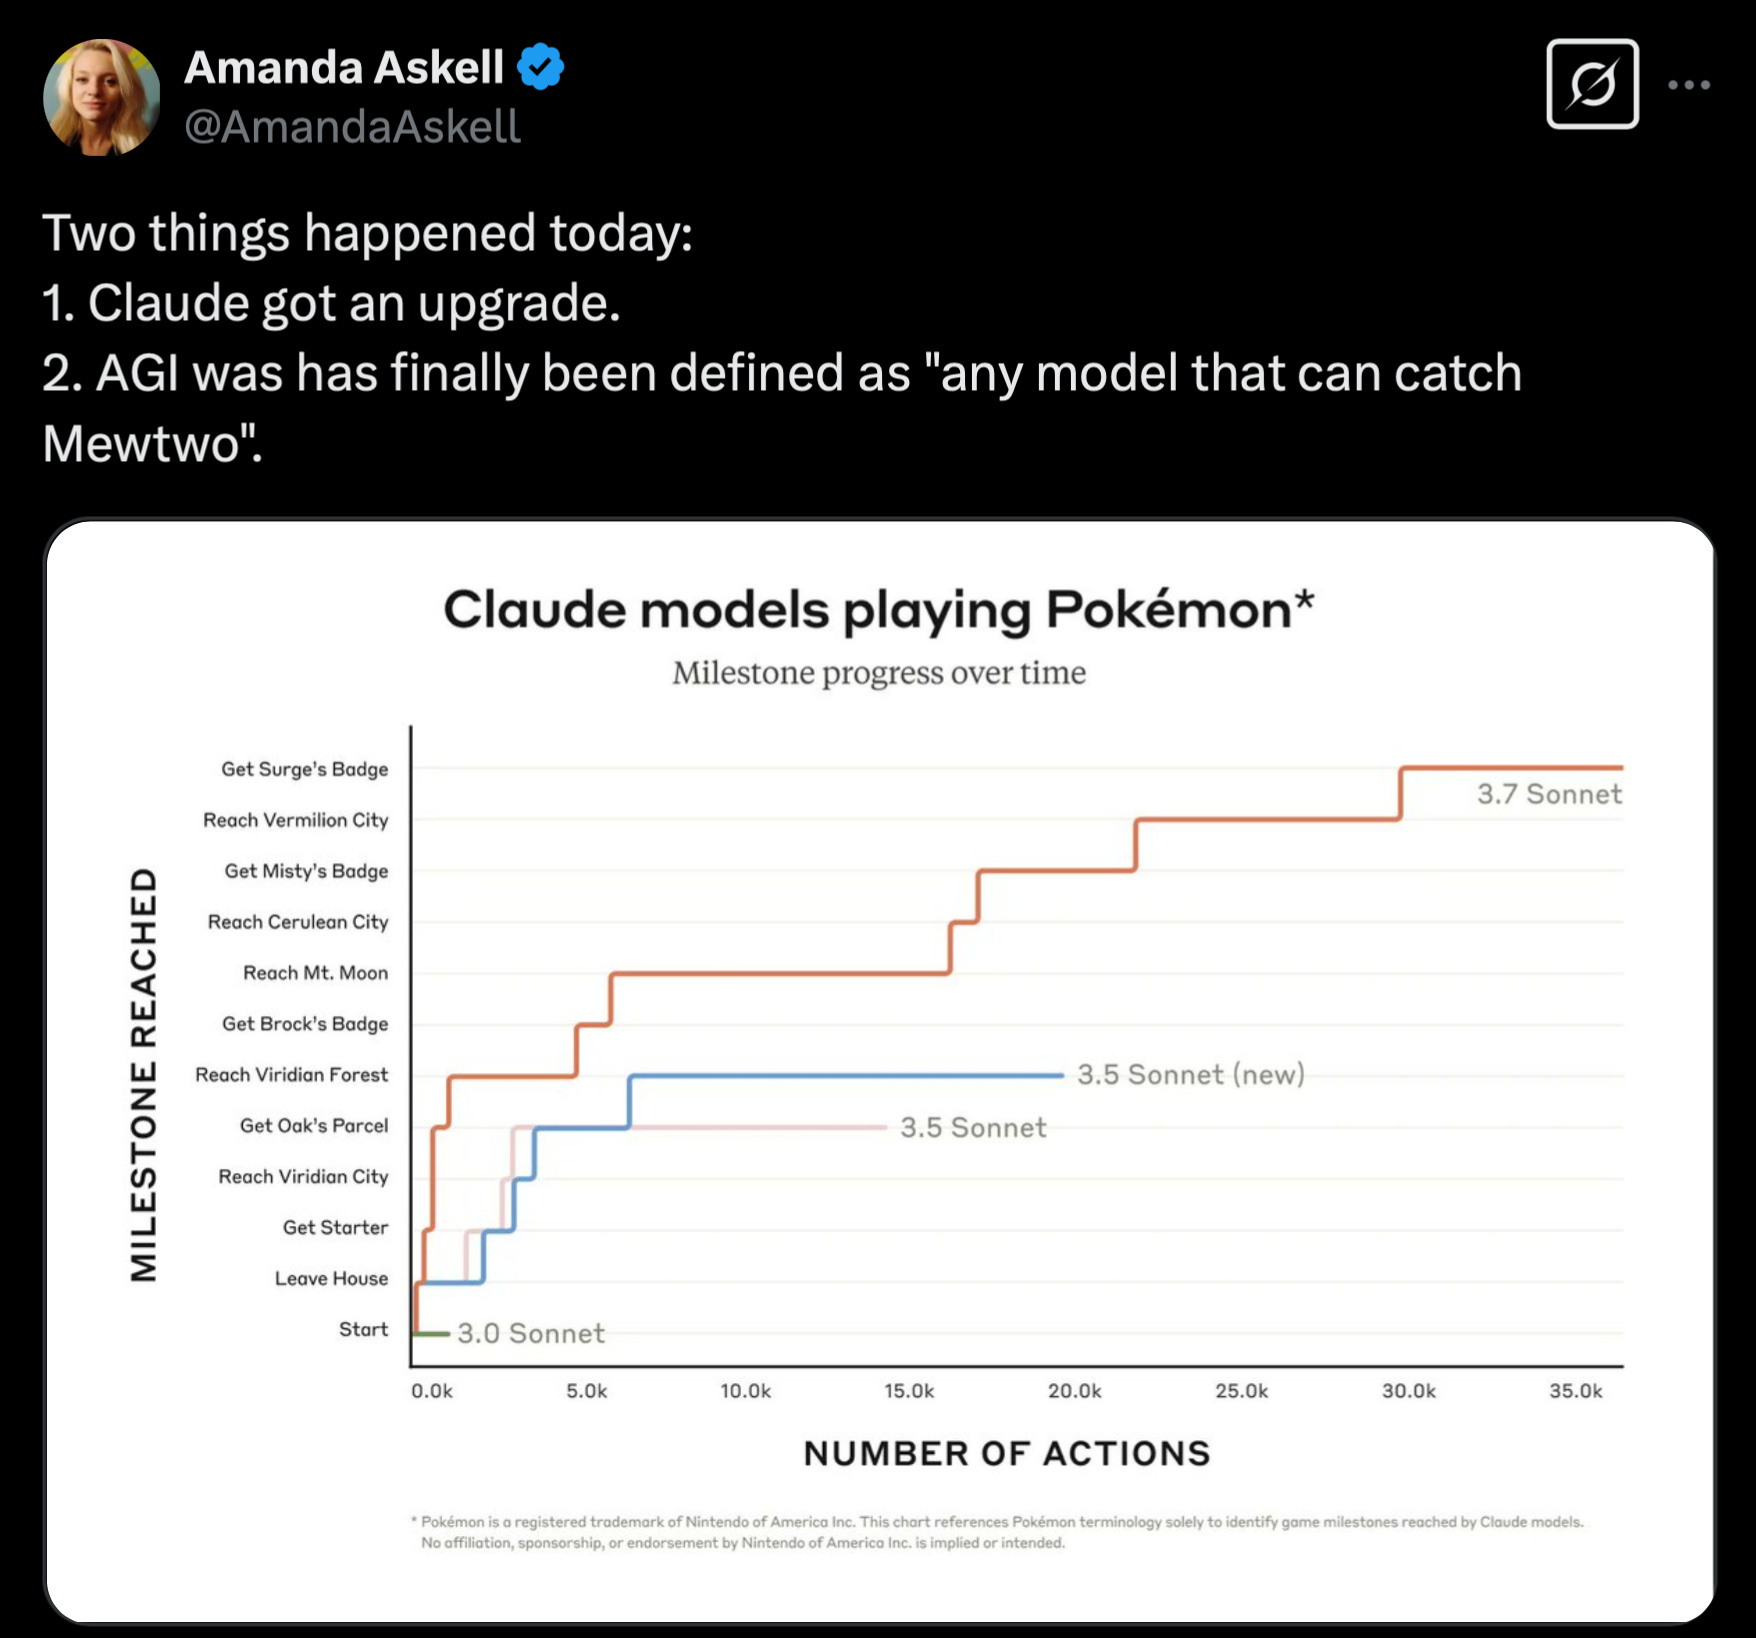
Special lightning pod with David Hershey from Anthropic, the person behind Claude Plays Pokémon. Sonnet 3.7 is currently trying to complete Pokémon Red live on Twitch thanks to a special harness that David built so that it can see the screen, navigate through it, remember facts about the game, and more. (Since recording, it has successfully escaped Mt Moon! You can follow along on Twitch: https://www.twitch.tv/claudeplayspokemon) This is a public episode. If you'd like to discuss this with other subscribers or get access to bonus episodes, visit www.latent.space/subscribe
Open Operator, Serverless Browsers and the Future of Computer-Using Agents
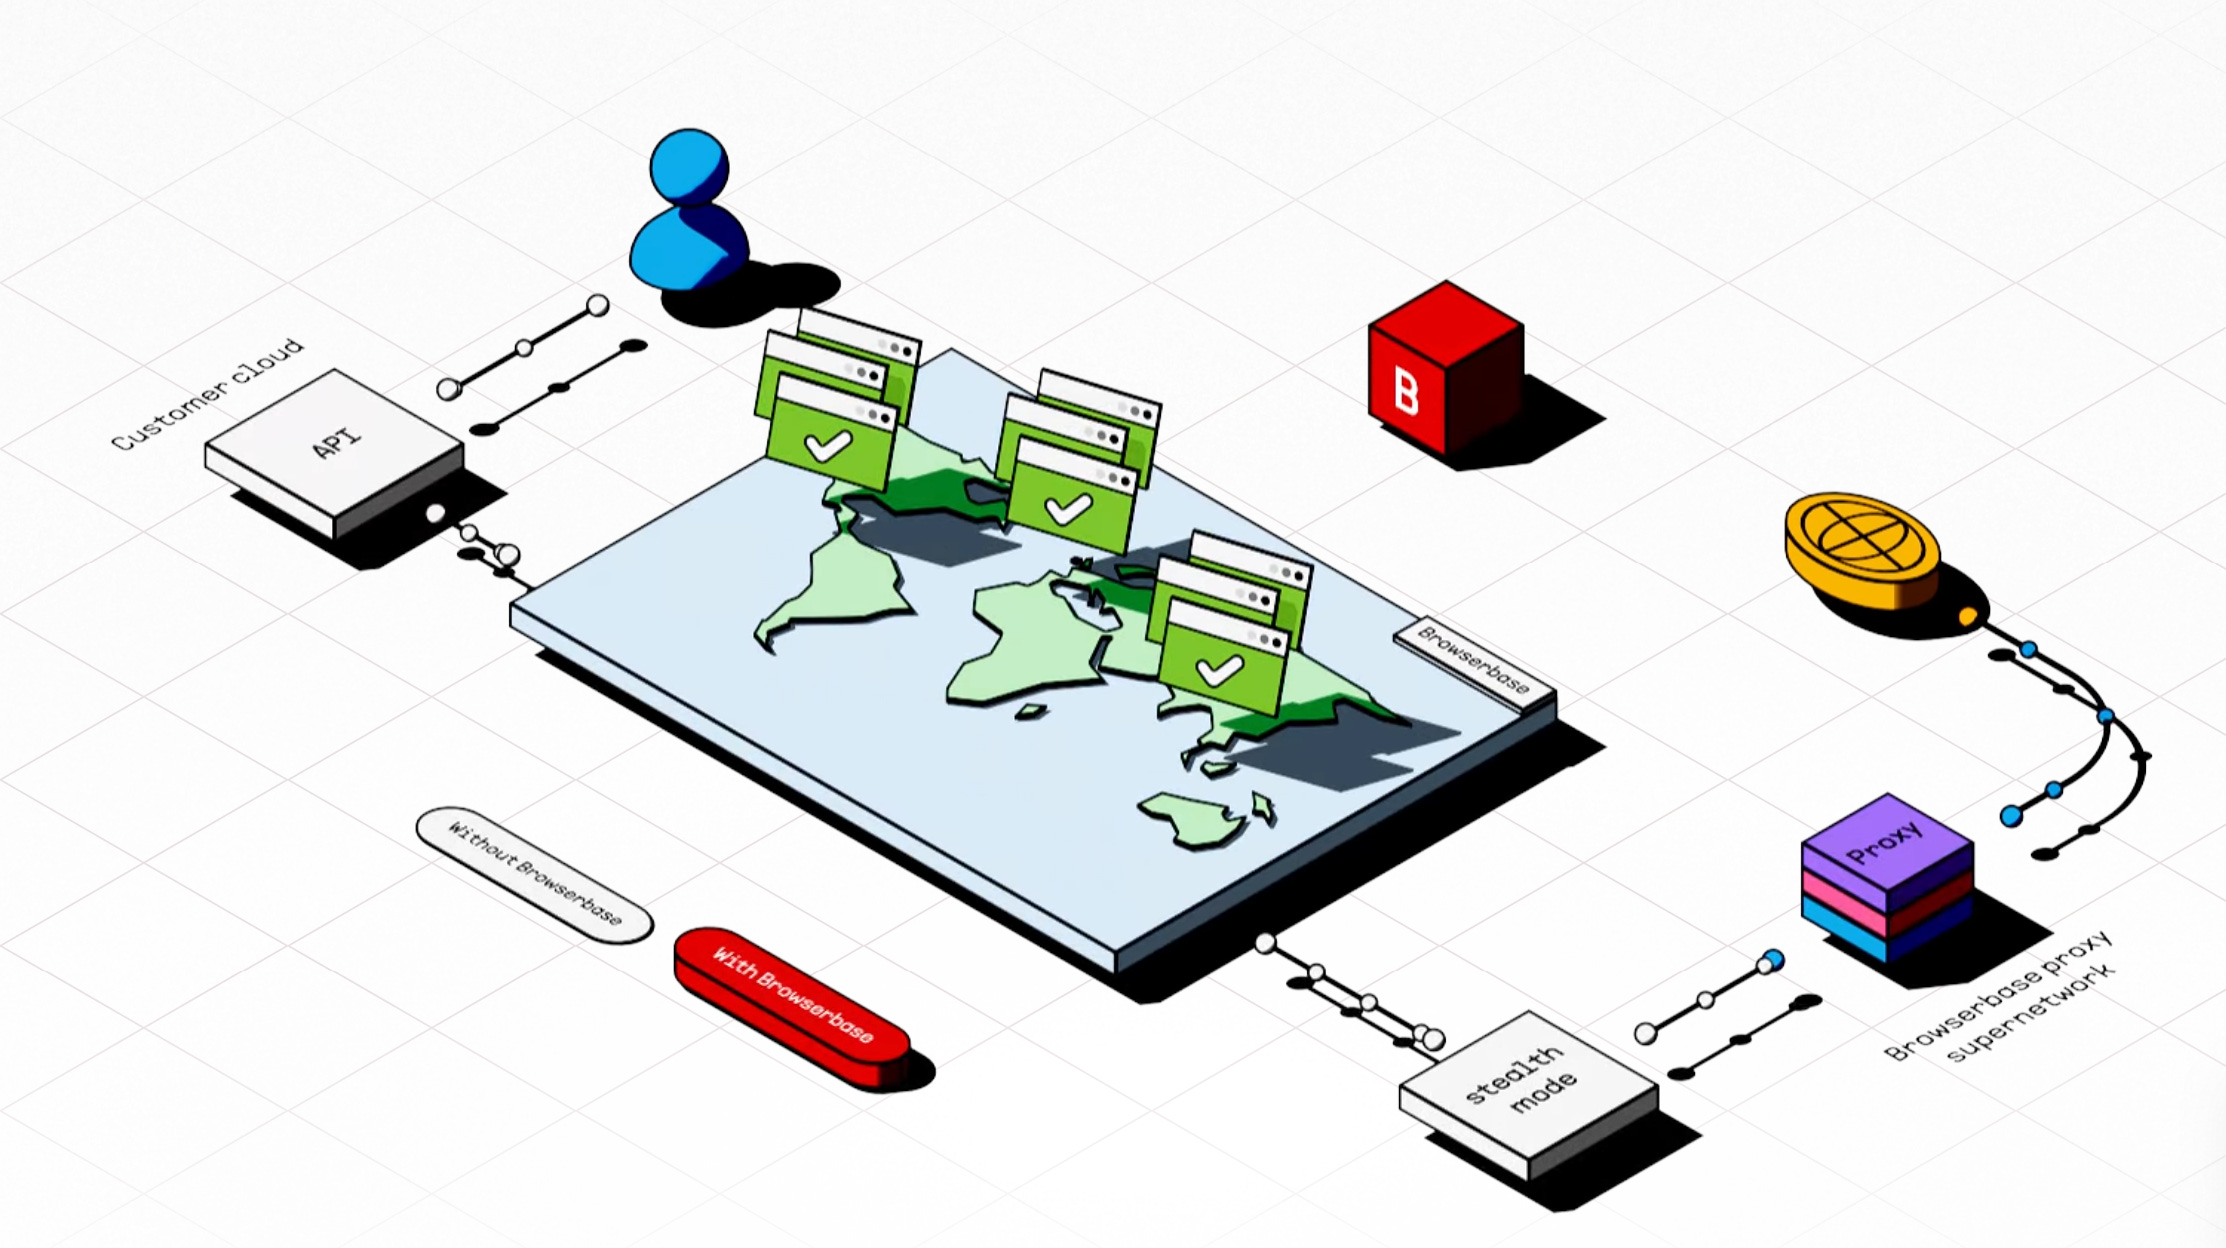
Today's episode is with Paul Klein, founder of Browserbase. We talked about building browser infrastructure for AI agents, the future of agent authentication, and their open source framework Stagehand.* [00:00:00] Introductions* [00:04:46] AI-specific challenges in browser infrastructure* [00:07:05] Multimodality in AI-Powered Browsing* [00:12:26] Running headless browsers at scale* [00:18:46] Geolocation when proxying* [00:21:25] CAPTCHAs and Agent Auth* [00:28:21] Building “User take over” functionality* [00:33:43] Stagehand: AI web browsing framework* [00:38:58] OpenAI's Operator and computer use agents* [00:44:44] Surprising use cases of Browserbase* [00:47:18] Future of browser automation and market competition* [00:53:11] Being a solo founderTranscriptAlessio [00:00:04]: Hey everyone, welcome to the Latent Space podcast. This is Alessio, partner and CTO at Decibel Partners, and I'm joined by my co-host Swyx, founder of Smol.ai.swyx [00:00:12]: Hey, and today we are very blessed to have our friends, Paul Klein, for the fourth, the fourth, CEO of Browserbase. Welcome.Paul [00:00:21]: Thanks guys. Yeah, I'm happy to be here. I've been lucky to know both of you for like a couple of years now, I think. So it's just like we're hanging out, you know, with three ginormous microphones in front of our face. It's totally normal hangout.swyx [00:00:34]: Yeah. We've actually mentioned you on the podcast, I think, more often than any other Solaris tenant. Just because like you're one of the, you know, best performing, I think, LLM tool companies that have started up in the last couple of years.Paul [00:00:50]: Yeah, I mean, it's been a whirlwind of a year, like Browserbase is actually pretty close to our first birthday. So we are one years old. And going from, you know, starting a company as a solo founder to... To, you know, having a team of 20 people, you know, a series A, but also being able to support hundreds of AI companies that are building AI applications that go out and automate the web. It's just been like, really cool. It's been happening a little too fast. I think like collectively as an AI industry, let's just take a week off together. I took my first vacation actually two weeks ago, and Operator came out on the first day, and then a week later, DeepSeat came out. And I'm like on vacation trying to chill. I'm like, we got to build with this stuff, right? So it's been a breakneck year. But I'm super happy to be here and like talk more about all the stuff we're seeing. And I'd love to hear kind of what you guys are excited about too, and share with it, you know?swyx [00:01:39]: Where to start? So people, you've done a bunch of podcasts. I think I strongly recommend Jack Bridger's Scaling DevTools, as well as Turner Novak's The Peel. And, you know, I'm sure there's others. So you covered your Twilio story in the past, talked about StreamClub, you got acquired to Mux, and then you left to start Browserbase. So maybe we just start with what is Browserbase? Yeah.Paul [00:02:02]: Browserbase is the web browser for your AI. We're building headless browser infrastructure, which are browsers that run in a server environment that's accessible to developers via APIs and SDKs. It's really hard to run a web browser in the cloud. You guys are probably running Chrome on your computers, and that's using a lot of resources, right? So if you want to run a web browser or thousands of web browsers, you can't just spin up a bunch of lambdas. You actually need to use a secure containerized environment. You have to scale it up and down. It's a stateful system. And that infrastructure is, like, super painful. And I know that firsthand, because at my last company, StreamClub, I was CTO, and I was building our own internal headless browser infrastructure. That's actually why we sold the company, is because Mux really wanted to buy our headless browser infrastructure that we'd built. And it's just a super hard problem. And I actually told my co-founders, I would never start another company unless it was a browser infrastructure company. And it turns out that's really necessary in the age of AI, when AI can actually go out and interact with websites, click on buttons, fill in forms. You need AI to do all of that work in an actual browser running somewhere on a server. And BrowserBase powers that.swyx [00:03:08]: While you're talking about it, it occurred to me, not that you're going to be acquired or anything, but it occurred to me that it would be really funny if you became the Nikita Beer of headless browser companies. You just have one trick, and you make browser companies that get acquired.Paul [00:03:23]: I truly do only have one trick. I'm screwed if it's not for headless browsers. I'm not a Go programmer. You know, I'm in AI grant. You know, browsers is an AI grant. But we were the only company in that AI grant batch that used zero dollars on AI spend. You know, we're purely an infrastructure company. So as much as people w
The Inventors of Deep Research
While “LLM-powered Search” is as old as Perplexity and SearchGPT, and open source projects like GPTResearcher and clones like OpenDeepResearch exist, the difference with “Deep Research” products is they are both “agentic” (loosely meaning that an LLM decides the next step in a workflow, usually involving tools) and bundling custom-tuned frontier models (custom tuned o3 and Gemini 1.5 Flash).The reception to OpenAI’s Deep Research agent has been nothing short of breathless:"Deep Research is the best public-facing AI product Google has ever released. It's like having a college-educated researcher in your pocket." - Jason Calacanis“I have had [Deep Research] write a number of ten-page papers for me, each of them outstanding. I think of the quality as comparable to having a good PhD-level research assistant, and sending that person away with a task for a week or two, or maybe more. Except Deep Research does the work in five or six minutes.” - Tyler Cowen“Deep Research is one of the best bargains in technology.” - Ben Thompson“my very approximate vibe is that it can do a single-digit percentage of all economically valuable tasks in the world, which is a wild milestone.” - sama“Using Deep Research over the past few weeks has been my own personal AGI moment. It takes 10 mins to generate accurate and thorough competitive and market research (with sources) that previously used to take me at least 3 hours.” - OAI employee“It's like a bazooka for the curious mind” - Dan Shipper“Deep research can be seen as a new interface for the internet, in addition to being an incredible agent… This paradigm will be so powerful that in the future, navigating the internet manually via a browser will be "old-school", like performing arithmetic calculations by hand.” - Jason Wei“One notable characteristic of Deep Research is its extreme patience. I think this is rapidly approaching “superhuman patience”. One realization working on this project was that intelligence and patience go really well together.” - HyungWon“I asked it to write a reference Interaction Calculus evaluator in Haskell. A few exchanges later, it gave me a complete file, including a parser, an evaluator, O(1) interactions and everything. The file compiled, and worked on my test inputs. There are some minor issues, but it is mostly correct. So, in about 30 minutes, o3 performed a job that would take me a day or so.” - Victor Taelin“Can confirm OpenAI Deep Research is quite strong. In a few minutes it did what used to take a dozen hours. The implications to knowledge work is going to be quite profound when you just ask an AI Agent to perform full tasks for you and come back with a finished result.” - Aaron Levie“Deep Research is genuinely useful” - Gary MarcusWith the advent of “Deep Research” agents, we are now routinely asking models to go through 100+ websites and generate in-depth reports on any topic. The Deep Research revolution has hit the AI scene in the last 2 weeks:* Dec 11th: Gemini Deep Research (today’s guest!) rolls out with Gemini Advanced* Feb 2nd: OpenAI releases Deep Research* Feb 3rd: a dozen “Open Deep Research” clones launch* Feb 5th: Gemini 2.0 Flash GA* Feb 15th: Perplexity launches Deep Research* Feb 17th: xAI launches Deep SearchIn today’s episode, we welcome Aarush Selvan and Mukund Sridhar, the lead PM and tech lead for Gemini Deep Research, the originators of the entire category. We asked detailed questions from inspiration to implementation, why they had to finetune a special model for it instead of using the standard Gemini model, how to run evals for them, and how to think about the distribution of use cases. (We also have an upcoming Gemini 2 episode with our returning first guest Logan Kilpatrick so stay tuned 👀)Two Kinds of Inference Time ComputeIn just ~2 months since NeurIPS, we’ve moved from “scaling has hit a wall, LLMs might be over” to “is this AGI already?” thanks to the releases of o1, o3, and DeepSeek R1 (see our o3 post and R1 distillation lightning pod). This new jump in capabilities is now accelerating many other applications; you might remember how “needle in a haystack” was one of the benchmarks people often referenced when looking at model’s capabilities over long context (see our 1M Llama context window ep for more). It seems that we have broken through the “wall” by scaling “inference time” in two meaningful ways — one with more time spent in the model, and the other with more tool calls.Both help build better agents which are clearly more intelligent. But as we discuss on the podcast, we are currently in a “honeymoon” period of agent products where taking more time (or tool calls, or search results) is considered good, because 1) quality is hard to evaluate and 2) we don’t know the realistic upper bound to quality. We know that they’re correlated, but we don’t know to what extent and if the correlation breaks down over extended research periods (they may not).It doesn’t take a PhD to spot the perverse incentives here.
Bee AI: The Wearable Ambient Agent
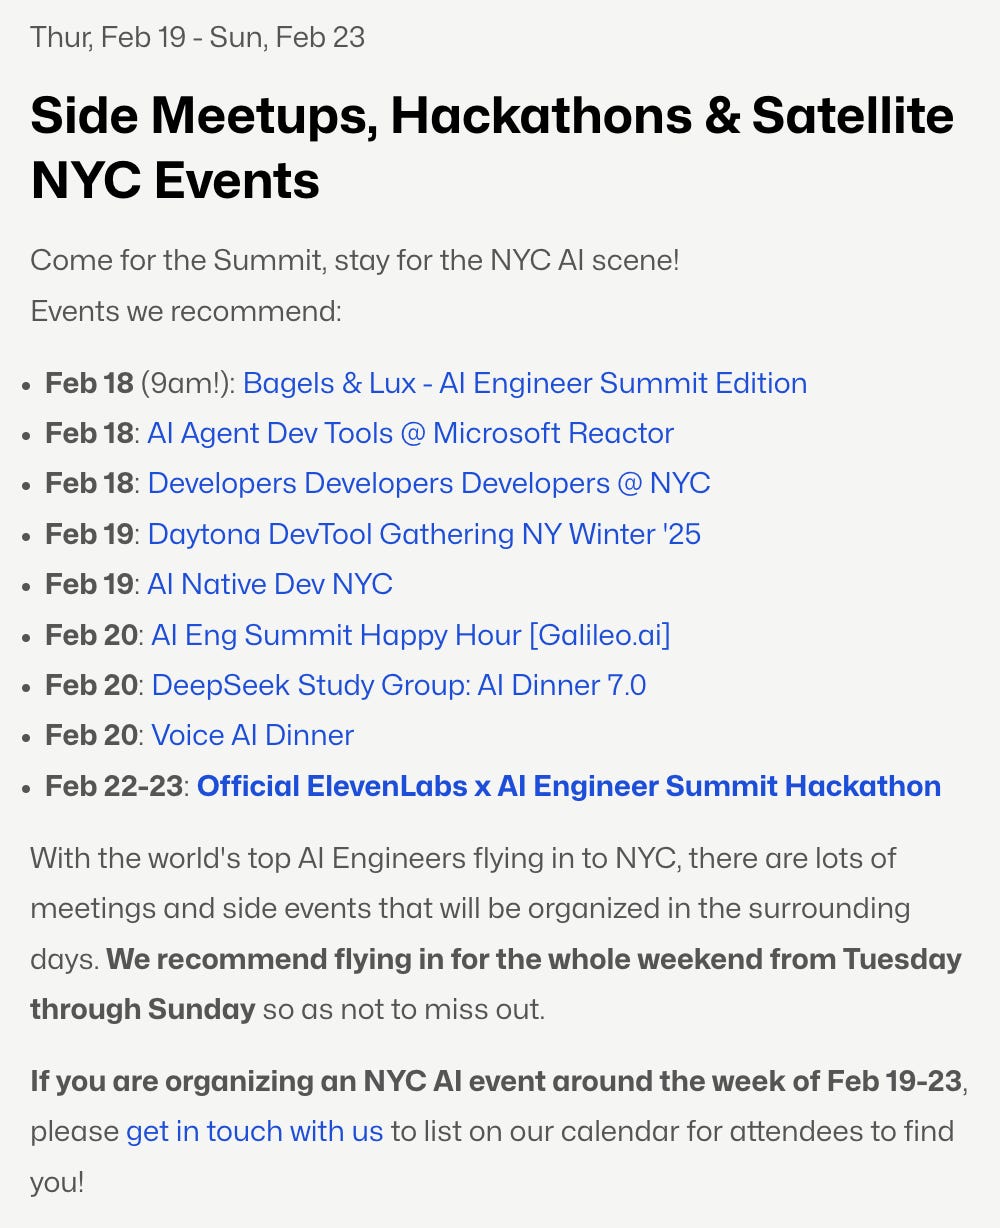
Bundle tickets for AIE Summit NYC have now sold out. You can now sign up for the livestream — where we will be making a big announcement soon. NYC-based readers and Summit attendees should check out the meetups happening around the Summit.2024 was a very challenging year for AI Hardware. After the buzz of CES last January, 2024 was marked by the meteoric rise and even harder fall of AI Wearables companies like Rabbit and Humane, with an assist from a pre-wallpaper-app MKBHD. Even Friend.com, the first to launch in the AI pendant category, and which spurred Rewind AI to rebrand to Limitless and follow in their footsteps, ended up delaying their wearable ship date and launching an experimental website chatbot version. We have been cautiously excited about this category, keeping tabs on most of the top entrants, including Omi and Compass. However, to date the biggest winner still standing from the AI Wearable wars is Bee AI, founded by today's guests Maria and Ethan. Bee is an always on hardware device with beamforming microphones, 7 day battery life and a mute button, that can be worn as a wristwatch or a clip-on pin, backed by an incredible transcription, diarization and very long context memory processing pipeline that helps you to remember your day, your todos, and even perform actions by operating a virtual cloud phone. This is one of the most advanced, production ready, personal AI agents we've ever seen, so we were excited to be their first podcast appearance. We met Bee when we ran the world's first Personal AI meetup in April last year.As a user of Bee (and not an investor! just a friend!) it’s genuinely been a joy to use, and we were glad to take advantage of the opportunity to ask hard questions about the privacy and legal/ethical side of things as much as the AI and Hardware engineering side of Bee. We hope you enjoy the episode and tune in next Friday for Bee’s first conference talk: Building Perfect Memory.Full YouTube Video VersionWatch this for the live demo!Show Notes* Bee Website* Ethan Sutin, Maria de Lourdes Zollo* Bee @ Personal AI Meetup* Buy Bee with Listener Discount Code!Timestamps* 00:00:00 Introductions and overview of Bee Computer* 00:01:58 Personal context and use cases for Bee* 00:03:02 Origin story of Bee and the founders' background* 00:06:56 Evolution from app to hardware device* 00:09:54 Short-term value proposition for users* 00:12:17 Demo of Bee's functionality* 00:17:54 Hardware form factor considerations* 00:22:22 Privacy concerns and legal considerations* 00:30:57 User adoption and reactions to wearing Bee* 00:35:56 CES experience and hardware manufacturing challenges* 00:41:40 Software pipeline and inference costs* 00:53:38 Technical challenges in real-time processing* 00:57:46 Memory and personal context modeling* 01:02:45 Social aspects and agent-to-agent interactions* 01:04:34 Location sharing and personal data exchange* 01:05:11 Personality analysis capabilities* 01:06:29 Hiring and future of always-on AITranscriptAlessio [00:00:04]: Hey everyone, welcome to the Latent Space podcast. This is Alessio, partner and CTO at Decibel Partners, and I'm joined by my co-host Swyx, founder of SmallAI.swyx [00:00:12]: Hey, and today we are very honored to have in the studio Maria and Ethan from Bee.Maria [00:00:16]: Hi, thank you for having us.swyx [00:00:20]: And you are, I think, the first hardware founders we've had on the podcast. I've been looking to have had a hardware founder, like a wearable hardware, like a wearable hardware founder for a while. I think we're going to have two or three of them this year. And you're the ones that I wear every day. So thank you for making Bee. Thank you for all the feedback and the usage. Yeah, you know, I've been a big fan. You are the speaker gift for the Engineering World's Fair. And let's start from the beginning. What is Bee Computer?Ethan [00:00:52]: Bee Computer is a personal AI system. So you can think of it as AI living alongside you in first person. So it can kind of capture your in real life. So with that understanding can help you in significant ways. You know, the obvious one is memory, but that's that's really just the base kind of use case. So recalling and reflective. I know, Swyx, that you you like the idea of journaling, but you don't but still have some some kind of reflective summary of what you experienced in real life. But it's also about just having like the whole context of a human being and understanding, you know, giving the machine the ability to understand, like, what's going on in your life. Your attitudes, your desires, specifics about your preferences, so that not only can it help you with recall, but then anything that you need it to do, it already knows, like, if you think about like somebody who you've worked with or lived with for a long time, they just know kind of without having to ask you what you would want, it's clear that like, that is the future that personal AI, like, it's just going to be very,
The AI Architect — Bret Taylor
If you’re in SF, join us tomorrow for a fun meetup at CodeGen Night!If you’re in NYC, join us for AI Engineer Summit! The Agent Engineering track is now sold out, but 25 tickets remain for AI Leadership and 5 tickets for the workshops. You can see the full schedule of speakers and workshops at https://ai.engineer!It’s exceedingly hard to introduce someone like Bret Taylor. We could recite his Wikipedia page, or his extensive work history through Silicon Valley’s greatest companies, but everyone else already does that.As a podcast by AI engineers for AI engineers, we had the opportunity to do something a little different. We wanted to dig into what Bret sees from his vantage point at the top of our industry for the last 2 decades, and how that explains the rise of the AI Architect at Sierra, the leading conversational AI/CX platform.“Across our customer base, we are seeing a new role emerge - the role of the AI architect. These leaders are responsible for helping define, manage and evolve their company's AI agent over time. They come from a variety of both technical and business backgrounds, and we think that every company will have one or many AI architects managing their AI agent and related experience.”In our conversation, Bret Taylor confirms the Paul Buchheit legend that he rewrote Google Maps in a weekend, armed with only the help of a then-nascent Google Closure Compiler and no other modern tooling. But what we find remarkable is that he was the PM of Maps, not an engineer, though of course he still identifies as one. We find this theme recurring throughout Bret’s career and worldview. We think it is plain as day that AI leadership will have to be hands-on and technical, especially when the ground is shifting as quickly as it is today:“There's a lot of power in combining product and engineering into as few people as possible… few great things have been created by committee.”“If engineering is an order taking organization for product you can sometimes make meaningful things, but rarely will you create extremely well crafted breakthrough products. Those tend to be small teams who deeply understand the customer need that they're solving, who have a maniacal focus on outcomes.”“And I think the reason why is if you look at like software as a service five years ago, maybe you can have a separation of product and engineering because most software as a service created five years ago. I wouldn't say there's like a lot of technological breakthroughs required for most business applications. And if you're making expense reporting software or whatever, it's useful… You kind of know how databases work, how to build auto scaling with your AWS cluster, whatever, you know, it's just, you're just applying best practices to yet another problem. "When you have areas like the early days of mobile development or the early days of interactive web applications, which I think Google Maps and Gmail represent, or now AI agents, you're in this constant conversation with what the requirements of your customers and stakeholders are and all the different people interacting with it and the capabilities of the technology. And it's almost impossible to specify the requirements of a product when you're not sure of the limitations of the technology itself.”This is the first time the difference between technical leadership for “normal” software and for “AI” software was articulated this clearly for us, and we’ll be thinking a lot about this going forward. We left a lot of nuggets in the conversation, so we hope you’ll just dive in with us (and thank Bret for joining the pod!)Full YouTubePlease Like and Subscribe :)Timestamps* 00:00:02 Introductions and Bret Taylor's background* 00:01:23 Bret's experience at Stanford and the dot-com era* 00:04:04 The story of rewriting Google Maps backend* 00:11:06 Early days of interactive web applications at Google* 00:15:26 Discussion on product management and engineering roles* 00:21:00 AI and the future of software development* 00:26:42 Bret's approach to identifying customer needs and building AI companies* 00:32:09 The evolution of business models in the AI era* 00:41:00 The future of programming languages and software development* 00:49:38 Challenges in precisely communicating human intent to machines* 00:56:44 Discussion on Artificial General Intelligence (AGI) and its impact* 01:08:51 The future of agent-to-agent communication* 01:14:03 Bret's involvement in the OpenAI leadership crisis* 01:22:11 OpenAI's relationship with Microsoft* 01:23:23 OpenAI's mission and priorities* 01:27:40 Bret's guiding principles for career choices* 01:29:12 Brief discussion on pasta-making* 01:30:47 How Bret keeps up with AI developments* 01:32:15 Exciting research directions in AI* 01:35:19 Closing remarks and hiring at Sierra Transcript[00:02:05] Introduction and Guest Welcome[00:02:05] Alessio: Hey everyone, welcome to the Latent Space Podcast. This is Alessio, partner and CTO at Decibel Partners, and I'm joined
Agent Engineering with Pydantic + Graphs — with Samuel Colvin
Did you know that adding a simple Code Interpreter took o3 from 9.2% to 32% on FrontierMath? The Latent Space crew is hosting a hack night Feb 11th in San Francisco focused on CodeGen use cases, co-hosted with E2B and Edge AGI; watch E2B’s new workshop and RSVP here!We’re happy to announce that today’s guest Samuel Colvin will be teaching his very first Pydantic AI workshop at the newly announced AI Engineer NYC Workshops day on Feb 22! 25 tickets left.If you’re a Python developer, it’s very likely that you’ve heard of Pydantic. Every month, it’s downloaded >300,000,000 times, making it one of the top 25 PyPi packages. OpenAI uses it in its SDK for structured outputs, it’s at the core of FastAPI, and if you’ve followed our AI Engineer Summit conference, Jason Liu of Instructor has given two great talks about it: “Pydantic is all you need” and “Pydantic is STILL all you need”. Now, Samuel Colvin has raised $17M from Sequoia to turn Pydantic from an open source project to a full stack AI engineer platform with Logfire, their observability platform, and PydanticAI, their new agent framework.Logfire: bringing OTEL to AIOpenTelemetry recently merged Semantic Conventions for LLM workloads which provides standard definitions to track performance like gen_ai.server.time_per_output_token. In Sam’s view at least 80% of new apps being built today have some sort of LLM usage in them, and just like web observability platform got replaced by cloud-first ones in the 2010s, Logfire wants to do the same for AI-first apps. If you’re interested in the technical details, Logfire migrated away from Clickhouse to Datafusion for their backend. We spent some time on the importance of picking open source tools you understand and that you can actually contribute to upstream, rather than the more popular ones; listen in ~43:19 for that part.Agents are the killer app for graphsPydantic AI is their attempt at taking a lot of the learnings that LangChain and the other early LLM frameworks had, and putting Python best practices into it. At an API level, it’s very similar to the other libraries: you can call LLMs, create agents, do function calling, do evals, etc.They define an “Agent” as a container with a system prompt, tools, structured result, and an LLM. Under the hood, each Agent is now a graph of function calls that can orchestrate multi-step LLM interactions. You can start simple, then move toward fully dynamic graph-based control flow if needed.“We were compelled enough by graphs once we got them right that our agent implementation [...] is now actually a graph under the hood.”Why Graphs?* More natural for complex or multi-step AI workflows.* Easy to visualize and debug with mermaid diagrams.* Potential for distributed runs, or “waiting days” between steps in certain flows.In parallel, you see folks like Emil Eifrem of Neo4j talk about GraphRAG as another place where graphs fit really well in the AI stack, so it might be time for more people to take them seriously.Full Video EpisodeLike and subscribe!Chapters* 00:00:00 Introductions* 00:00:24 Origins of Pydantic* 00:05:28 Pydantic's AI moment * 00:08:05 Why build a new agents framework?* 00:10:17 Overview of Pydantic AI* 00:12:33 Becoming a believer in graphs* 00:24:02 God Model vs Compound AI Systems* 00:28:13 Why not build an LLM gateway?* 00:31:39 Programmatic testing vs live evals* 00:35:51 Using OpenTelemetry for AI traces* 00:43:19 Why they don't use Clickhouse* 00:48:34 Competing in the observability space* 00:50:41 Licensing decisions for Pydantic and LogFire* 00:51:48 Building Pydantic.run* 00:55:24 Marimo and the future of Jupyter notebooks* 00:57:44 London's AI sceneShow Notes* Sam Colvin* Pydantic* Pydantic AI* Logfire* Pydantic.run* Zod* E2B* Arize* Langsmith* Marimo* Prefect* GLA (Google Generative Language API)* OpenTelemetry* Jason Liu* Sebastian Ramirez* Bogomil Balkansky* Hood Chatham* Jeremy Howard* Andrew LambTranscriptAlessio [00:00:03]: Hey, everyone. Welcome to the Latent Space podcast. This is Alessio, partner and CTO at Decibel Partners, and I'm joined by my co-host Swyx, founder of Smol AI.Swyx [00:00:12]: Good morning. And today we're very excited to have Sam Colvin join us from Pydantic AI. Welcome. Sam, I heard that Pydantic is all we need. Is that true?Samuel [00:00:24]: I would say you might need Pydantic AI and Logfire as well, but it gets you a long way, that's for sure.Swyx [00:00:29]: Pydantic almost basically needs no introduction. It's almost 300 million downloads in December. And obviously, in the previous podcasts and discussions we've had with Jason Liu, he's been a big fan and promoter of Pydantic and AI.Samuel [00:00:45]: Yeah, it's weird because obviously I didn't create Pydantic originally for uses in AI, it predates LLMs. But it's like we've been lucky that it's been picked up by that community and used so widely.Swyx [00:00:58]: Actually, maybe we'll hear it. Right from you, what is Pydantic and maybe a little bit of the origin story?
The Agent Reasoning Interface: o1/o3, Claude 3, ChatGPT Canvas, Tasks, and Operator — with Karina Nguyen of OpenAI
Sponsorships and tickets for the AI Engineer Summit are selling fast! See the new website with speakers and schedules live! If you are building AI agents or leading teams of AI Engineers, this will be the single highest-signal conference of the year for you, this Feb 20-22nd in NYC.We’re pleased to share that Karina will be presenting OpenAI’s closing keynote at the AI Engineer Summit. We were fortunate to get some time with her today to introduce some of her work, and hope this serves as nice background for her talk!There are very few early AI careers that have been as impactful as Karina Nguyen’s. After stints at Notion, Square, Dropbox, Primer, the New York Times, and UC Berkeley, She joined Anthropic as employee ~60 and worked on a wide range of research/product roles for Claude 1, 2, and 3. We’ll just let her LinkedIn speak for itself:Now, as Research manager and Post-training lead in Model Behavior at OpenAI, she creates new interaction paradigms for reasoning interfaces and capabilities, like ChatGPT Canvas, Tasks, SimpleQA, streaming chain-of-thought for o1 models, and more via novel synthetic model training. Ideal AI Research+Product ProcessIn the podcast we got a sense of what Karina has found works for her and her team to be as productive as they have been:* Write PRD (Define what you want)* Funding (Get resources)* Prototype Prompted Baseline (See what’s possible)* Write and Run Evals (Get failures to hillclimb)* Model training (Exceed baseline without overfitting)* Bugbash (Find bugs and solve them)* Ship (Get users!)We could turn this into a snazzy viral graphic but really this is all it is. Simple to say, difficult to do well. Hopefully it helps you define your process if you do similar product-research work. Show Notes* Our Reasoning Price War post * Karina LinkedIn, Website, Twitter* OSINT visualization work* Ukraine 3D storytelling* Karina on Claude Artifacts* Karina on Claude 3 Benchmarks* Inspiration for Artifacts / Canvas from early UX work she did on GPT-3* “i really believe that things like canvas and tasks should and could have happened like 2 yrs ago, idk why we are lagging in the form factors” (tweet)* Our article on prompting o1 vs Karina’s Claude prompting principles* Canvas: https://openai.com/index/introducing-canvas/ * We trained GPT-4o to collaborate as a creative partner. The model knows when to open a canvas, make targeted edits, and fully rewrite. It also understands broader context to provide precise feedback and suggestions.To support this, our research team developed the following core behaviors:* Triggering the canvas for writing and coding* Generating diverse content types* Making targeted edits* Rewriting documents* Providing inline critiqueWe measured progress with over 20 automated internal evaluations. We used novel synthetic data generation techniques, such as distilling outputs from OpenAI o1-preview, to post-train the model for its core behaviors. This approach allowed us to rapidly address writing quality and new user interactions, all without relying on human-generated data.* Tasks: https://www.theverge.com/2025/1/14/24343528/openai-chatgpt-repeating-tasks-agent-ai* * Agents and Operator* What are agents? “Agents are a gradual progression of tasks: starting with one-off actions, moving to collaboration, and ultimately fully trustworthy long-horizon delegation in complex envs like multi-player/multiagents.” (tweet)* tasks and canvas fall within the first two, and we are def. marching towards the third—though the form factor for 3 will take time to develop * Operator/Computer Use Agents* https://openai.com/index/introducing-operator/* Misc:* Andrew Ng* Prediction: Personal AI Consumer playbook* ChatGPT as generative OSTimestamps* 00:00 Welcome to the Latent Space Podcast* 00:11 Introducing Karina Nguyen* 02:21 Karina's Journey to OpenAI* 04:45 Early Prototypes and Projects* 05:25 Joining Anthropic and Early Work* 07:16 Challenges and Innovations at Anthropic* 11:30 Launching Claude 3* 21:57 Behavioral Design and Model Personality* 27:37 The Making of ChatGPT Canvas* 34:34 Canvas Update and Initial Impressions* 34:46 Differences Between Canvas and API Outputs* 35:50 Core Use Cases of Canvas* 36:35 Canvas as a Writing Partner* 36:55 Canvas vs. Google Docs and Future Improvements* 37:35 Canvas for Coding and Executing Code* 38:50 Challenges in Developing Canvas* 41:45 Introduction to Tasks* 41:53 Developing and Iterating on Tasks* 46:27 Future Vision for Tasks and Proactive Models* 52:23 Computer Use Agents and Their Potential* 01:00:21 Cultural Differences Between OpenAI and Anthropic* 01:03:46 Call to Action and Final ThoughtsTranscriptAlessio [00:00:04]: Hey everyone, welcome to the Latent Space podcast. This is Alessio, partner and CTO at Decibel, and I'm joined by my usual co-host, Swyx.swyx [00:00:11]: Hey, and today we're very, very blessed to have Karina Nguyen in the studio. Welcome.Karina [00:00:15]: Nice to meet you.swyx [00:00:16]: We finally made it h
Outlasting Noam Shazeer, crowdsourcing Chai AI with >1.4m DAU, and becoming the "Western DeepSeek" — with William Beauchamp, Chai Research
One last Gold sponsor slot is available for the AI Engineer Summit in NYC. Our last round of invites is going out soon - apply here - If you are building AI agents or AI eng teams, this will be the single highest-signal conference of the year for you!While the world melts down over DeepSeek, few are talking about the OTHER notable group of former hedge fund traders who pivoted into AI and built a remarkably profitable consumer AI business with a tiny team with incredibly cracked engineering team — Chai Research. In short order they have:* Started a Chat AI company well before Noam Shazeer started Character AI, and outlasted his departure.* Crossed 1m DAU in 2.5 years - William updates us on the pod that they’ve hit 1.4m DAU now, another +40% from a few months ago. Revenue crossed >$22m. * Launched the Chaiverse model crowdsourcing platform - taking 3-4 week A/B testing cycles down to 3-4 hours, and deploying >100 models a week.While they’re not paying million dollar salaries, you can tell they’re doing pretty well for an 11 person startup:The Chai Recipe: Building infra for rapid evalsRemember how the central thesis of LMarena (formerly LMsys) is that the only comprehensive way to evaluate LLMs is to let users try them out and pick winners?At the core of Chai is a mobile app that looks like Character AI, but is actually the largest LLM A/B testing arena in the world, specialized on retaining chat users for Chai’s usecases (therapy, assistant, roleplay, etc). It’s basically what LMArena would be if taken very, very seriously at one company (with $1m in prizes to boot):Chai publishes occasional research on how they think about this, including talks at their Palo Alto office:William expands upon this in today’s podcast (34 mins in):Fundamentally, the way I would describe it is when you're building anything in life, you need to be able to evaluate it. And through evaluation, you can iterate, we can look at benchmarks, and we can say the issues with benchmarks and why they may not generalize as well as one would hope in the challenges of working with them. But something that works incredibly well is getting feedback from humans. And so we built this thing where anyone can submit a model to our developer backend, and it gets put in front of 5000 users, and the users can rate it. And we can then have a really accurate ranking of like which model, or users finding more engaging or more entertaining. And it gets, you know, it's at this point now, where every day we're able to, I mean, we evaluate between 20 and 50 models, LLMs, every single day, right. So even though we've got only got a team of, say, five AI researchers, they're able to iterate a huge quantity of LLMs, right. So our team ships, let's just say minimum 100 LLMs a week is what we're able to iterate through. Now, before that moment in time, we might iterate through three a week, we might, you know, there was a time when even doing like five a month was a challenge, right? By being able to change the feedback loops to the point where it's not, let's launch these three models, let's do an A-B test, let's assign, let's do different cohorts, let's wait 30 days to see what the day 30 retention is, which is the kind of the, if you're doing an app, that's like A-B testing 101 would be, do a 30-day retention test, assign different treatments to different cohorts and come back in 30 days. So that's insanely slow. That's just, it's too slow. And so we were able to get that 30-day feedback loop all the way down to something like three hours.In Crowdsourcing the leap to Ten Trillion-Parameter AGI, William describes Chai’s routing as a recommender system, which makes a lot more sense to us than previous pitches for model routing startups:William is notably counter-consensus in a lot of his AI product principles:* No streaming: Chats appear all at once to allow rejection sampling* No voice: Chai actually beat Character AI to introducing voice - but removed it after finding that it was far from a killer feature.* Blending: “Something that we love to do at Chai is blending, which is, you know, it's the simplest way to think about it is you're going to end up, and you're going to pretty quickly see you've got one model that's really smart, one model that's really funny. How do you get the user an experience that is both smart and funny? Well, just 50% of the requests, you can serve them the smart model, 50% of the requests, you serve them the funny model.” (that’s it!)But chief above all is the recommender system.We also referenced Exa CEO Will Bryk’s concept of SuperKnowlege:Full Video versionOn YouTube. please like and subscribe!Timestamps* 00:00:04 Introductions and background of William Beauchamp* 00:01:19 Origin story of Chai AI* 00:04:40 Transition from finance to AI* 00:11:36 Initial product development and idea maze for Chai* 00:16:29 User psychology and engagement with AI companions* 00:20:00 Origin of the Chai name* 00:22:01 Comparison with Character AI and f
Everything you need to run Mission Critical Inference (ft. DeepSeek v3 + SGLang)
Sponsorships and applications for the AI Engineer Summit in NYC are live! (Speaker CFPs have closed) If you are building AI agents or leading teams of AI Engineers, this will be the single highest-signal conference of the year for you.Right after Christmas, the Chinese Whale Bros ended 2024 by dropping the last big model launch of the year: DeepSeek v3. Right now on LM Arena, DeepSeek v3 has a score of 1319, right under the full o1 model, Gemini 2, and 4o latest. This makes it the best open weights model in the world in January 2025.There has been a big recent trend in Chinese labs releasing very large open weights models, with TenCent releasing Hunyuan-Large in November and Hailuo releasing MiniMax-Text this week, both over 400B in size. However these extra-large language models are very difficult to serve.Baseten was the first of the Inference neocloud startups to get DeepSeek V3 online, because of their H200 clusters, their close collaboration with the DeepSeek team and early support of SGLang, a relatively new VLLM alternative that is also used at frontier labs like X.ai. Each H200 has 141 GB of VRAM with 4.8 TB per second of bandwidth, meaning that you can use 8 H200's in a node to inference DeepSeek v3 in FP8, taking into account KV Cache needs. We have been close to Baseten since Sarah Guo introduced Amir Haghighat to swyx, and they supported the very first Latent Space Demo Day in San Francisco, which was effectively the trial run for swyx and Alessio to work together! Since then, Philip Kiely also led a well attended workshop on TensorRT LLM at the 2024 World's Fair. We worked with him to get two of their best representatives, Amir and Lead Model Performance Engineer Yineng Zhang, to discuss DeepSeek, SGLang, and everything they have learned running Mission Critical Inference workloads at scale for some of the largest AI products in the world.The Three Pillars of Mission Critical InferenceWe initially planned to focus the conversation on SGLang, but Amir and Yineng were quick to correct us that the choice of inference framework is only the simplest, first choice of 3 things you need for production inference at scale:“I think it takes three things, and each of them individually is necessary but not sufficient: * Performance at the model level: how fast are you running this one model running on a single GPU, let's say. The framework that you use there can, can matter. The techniques that you use there can matter. The MLA technique, for example, that Yineng mentioned, or the CUDA kernels that are being used. But there's also techniques being used at a higher level, things like speculative decoding with draft models or with Medusa heads. And these are implemented in the different frameworks, or you can even implement it yourself, but they're not necessarily tied to a single framework. But using speculative decoding gets you massive upside when it comes to being able to handle high throughput. But that's not enough. Invariably, that one model running on a single GPU, let's say, is going to get too much traffic that it cannot handle.* Horizontal scaling at the cluster/region level: And at that point, you need to horizontally scale it. That's not an ML problem. That's not a PyTorch problem. That's an infrastructure problem. How quickly do you go from, a single replica of that model to 5, to 10, to 100. And so that's the second, that's the second pillar that is necessary for running these machine critical inference workloads.And what does it take to do that? It takes, some people are like, Oh, You just need Kubernetes and Kubernetes has an autoscaler and that just works. That doesn't work for, for these kinds of mission critical inference workloads. And you end up catching yourself wanting to bit by bit to rebuild those infrastructure pieces from scratch. This has been our experience. * And then going even a layer beyond that, Kubernetes runs in a single. cluster. It's a single cluster. It's a single region tied to a single region. And when it comes to inference workloads and needing GPUs more and more, you know, we're seeing this that you cannot meet the demand inside of a single region. A single cloud's a single region. In other words, a single model might want to horizontally scale up to 200 replicas, each of which is, let's say, 2H100s or 4H100s or even a full node, you run into limits of the capacity inside of that one region. And what we had to build to get around that was the ability to have a single model have replicas across different regions. So, you know, there are models on Baseten today that have 50 replicas in GCP East and, 80 replicas in AWS West and Oracle in London, etc.* Developer experience for Compound AI Systems: The final one is wrapping the power of the first two pillars in a very good developer experience to be able to afford certain workflows like the ones that I mentioned, around multi step, multi model inference workloads, because more and more we're seeing that the market is mov
[Ride Home] Simon Willison: Things we learned about LLMs in 2024
Due to overwhelming demand (>15x applications:slots), we are closing CFPs for AI Engineer Summit NYC today. Last call! Thanks, we’ll be reaching out to all shortly!The world’s top AI blogger and friend of every pod, Simon Willison, dropped a monster 2024 recap: Things we learned about LLMs in 2024. Brian of the excellent TechMeme Ride Home pinged us for a connection and a special crossover episode, our first in 2025. The target audience for this podcast is a tech-literate, but non-technical one. You can see Simon’s notes for AI Engineers in his World’s Fair Keynote.Timestamp* 00:00 Introduction and Guest Welcome* 01:06 State of AI in 2025* 01:43 Advancements in AI Models* 03:59 Cost Efficiency in AI* 06:16 Challenges and Competition in AI* 17:15 AI Agents and Their Limitations* 26:12 Multimodal AI and Future Prospects* 35:29 Exploring Video Avatar Companies* 36:24 AI Influencers and Their Future* 37:12 Simplifying Content Creation with AI* 38:30 The Importance of Credibility in AI* 41:36 The Future of LLM User Interfaces* 48:58 Local LLMs: A Growing Interest* 01:07:22 AI Wearables: The Next Big Thing* 01:10:16 Wrapping Up and Final ThoughtsTranscript[00:00:00] Introduction and Guest Welcome[00:00:00] Brian: Welcome to the first bonus episode of the Tech Meme Write Home for the year 2025. I'm your host as always, Brian McCullough. Listeners to the pod over the last year know that I have made a habit of quoting from Simon Willison when new stuff happens in AI from his blog. Simon has been, become a go to for many folks in terms of, you know, Analyzing things, criticizing things in the AI space.[00:00:33] Brian: I've wanted to talk to you for a long time, Simon. So thank you for coming on the show. No, it's a privilege to be here. And the person that made this connection happen is our friend Swyx, who has been on the show back, even going back to the, the Twitter Spaces days but also an AI guru in, in their own right Swyx, thanks for coming on the show also.[00:00:54] swyx (2): Thanks. I'm happy to be on and have been a regular listener, so just happy to [00:01:00] contribute as well.[00:01:00] Brian: And a good friend of the pod, as they say. Alright, let's go right into it.[00:01:06] State of AI in 2025[00:01:06] Brian: Simon, I'm going to do the most unfair, broad question first, so let's get it out of the way. The year 2025. Broadly, what is the state of AI as we begin this year?[00:01:20] Brian: Whatever you want to say, I don't want to lead the witness.[00:01:22] Simon: Wow. So many things, right? I mean, the big thing is everything's got really good and fast and cheap. Like, that was the trend throughout all of 2024. The good models got so much cheaper, they got so much faster, they got multimodal, right? The image stuff isn't even a surprise anymore.[00:01:39] Simon: They're growing video, all of that kind of stuff. So that's all really exciting.[00:01:43] Advancements in AI Models[00:01:43] Simon: At the same time, they didn't get massively better than GPT 4, which was a bit of a surprise. So that's sort of one of the open questions is, are we going to see huge, but I kind of feel like that's a bit of a distraction because GPT 4, but way cheaper, much larger context lengths, and it [00:02:00] can do multimodal.[00:02:01] Simon: is better, right? That's a better model, even if it's not.[00:02:05] Brian: What people were expecting or hoping, maybe not expecting is not the right word, but hoping that we would see another step change, right? Right. From like GPT 2 to 3 to 4, we were expecting or hoping that maybe we were going to see the next evolution in that sort of, yeah.[00:02:21] Brian: We[00:02:21] Simon: did see that, but not in the way we expected. We thought the model was just going to get smarter, and instead we got. Massive drops in, drops in price. We got all of these new capabilities. You can talk to the things now, right? They can do simulated audio input, all of that kind of stuff. And so it's kind of, it's interesting to me that the models improved in all of these ways we weren't necessarily expecting.[00:02:43] Simon: I didn't know it would be able to do an impersonation of Santa Claus, like a, you know, Talked to it through my phone and show it what I was seeing by the end of 2024. But yeah, we didn't get that GPT 5 step. And that's one of the big open questions is, is that actually just around the corner and we'll have a bunch of GPT 5 class models drop in the [00:03:00] next few months?[00:03:00] Simon: Or is there a limit?[00:03:03] Brian: If you were a betting man and wanted to put money on it, do you expect to see a phase change, step change in 2025?[00:03:11] Simon: I don't particularly for that, like, the models, but smarter. I think all of the trends we're seeing right now are going to keep on going, especially the inference time compute, right?[00:03:21] Simon: The trick that O1 and O3 are doing, which means that you can solve harder problems, but they cost more and it churns aw
Beating Google at Search with Neural PageRank and $5M of H200s — with Will Bryk of Exa.ai
Applications close Monday for the NYC AI Engineer Summit focusing on AI Leadership and Agent Engineering! If you applied, invites should be rolling out shortly.The search landscape is experiencing a fundamental shift. Google built a >$2T company with the “10 blue links” experience, driven by PageRank as the core innovation for ranking. This was a big improvement from the previous directory-based experiences of AltaVista and Yahoo. Almost 4 decades later, Google is now stuck in this links-based experience, especially from a business model perspective. This legacy architecture creates fundamental constraints:* Must return results in ~400 milliseconds* Required to maintain comprehensive web coverage* Tied to keyword-based matching algorithms* Cost structures optimized for traditional indexingAs we move from the era of links to the era of answers, the way search works is changing. You’re not showing a user links, but the goal is to provide context to an LLM. This means moving from keyword based search to more semantic understanding of the content:The link prediction objective can be seen as like a neural PageRank because what you're doing is you're predicting the links people share... but it's more powerful than PageRank. It's strictly more powerful because people might refer to that Paul Graham fundraising essay in like a thousand different ways. And so our model learns all the different ways.All of this is now powered by a $5M cluster with 144 H200s:This architectural choice enables entirely new search capabilities:* Comprehensive result sets instead of approximations* Deep semantic understanding of queries* Ability to process complex, natural language requestsAs search becomes more complex, time to results becomes a variable:People think of searches as like, oh, it takes 500 milliseconds because we've been conditioned... But what if searches can take like a minute or 10 minutes or a whole day, what can you then do?Unlike traditional search engines' fixed-cost indexing, Exa employs a hybrid approach:* Front-loaded compute for indexing and embeddings* Variable inference costs based on query complexity* Mix of owned infrastructure ($5M H200 cluster) and cloud resourcesExa sees a lot of competition from products like Perplexity and ChatGPT Search which layer AI on top of traditional search backends, but Exa is betting that true innovation requires rethinking search from the ground up. For example, the recently launched Websets, a way to turn searches into structured output in grid format, allowing you to create lists and databases out of web pages. The company raised a $17M Series A to build towards this mission, so keep an eye out for them in 2025. Chapters* 00:00:00 Introductions* 00:01:12 ExaAI's initial pitch and concept* 00:02:33 Will's background at SpaceX and Zoox* 00:03:45 Evolution of ExaAI (formerly Metaphor Systems)* 00:05:38 Exa's link prediction technology* 00:09:20 Meaning of the name "Exa"* 00:10:36 ExaAI's new product launch and capabilities* 00:13:33 Compute budgets and variable compute products* 00:14:43 Websets as a B2B offering* 00:19:28 How do you build a search engine?* 00:22:43 What is Neural PageRank?* 00:27:58 Exa use cases * 00:35:00 Auto-prompting* 00:38:42 Building agentic search* 00:44:19 Is o1 on the path to AGI?* 00:49:59 Company culture and nap pods* 00:54:52 Economics of AI search and the future of search technologyFull YouTube TranscriptPlease like and subscribe!Show Notes* ExaAI* Web Search Product* Websets* Series A Announcement* Exa Nap Pods* Perplexity AI* Character.AITranscriptAlessio [00:00:00]: Hey, everyone. Welcome to the Latent Space podcast. This is Alessio, partner and CTO at Decibel Partners, and I'm joined by my co-host Swyx, founder of Smol.ai.Swyx [00:00:10]: Hey, and today we're in the studio with my good friend and former landlord, Will Bryk. Roommate. How you doing? Will, you're now CEO co-founder of ExaAI, used to be Metaphor Systems. What's your background, your story?Will [00:00:30]: Yeah, sure. So, yeah, I'm CEO of Exa. I've been doing it for three years. I guess I've always been interested in search, whether I knew it or not. Like, since I was a kid, I've always been interested in, like, high-quality information. And, like, you know, even in high school, wanted to improve the way we get information from news. And then in college, built a mini search engine. And then with Exa, like, you know, it's kind of like fulfilling the dream of actually being able to solve all the information needs I wanted as a kid. Yeah, I guess. I would say my entire life has kind of been rotating around this problem, which is pretty cool. Yeah.Swyx [00:00:50]: What'd you enter YC with?Will [00:00:53]: We entered YC with, uh, we are better than Google. Like, Google 2.0.Swyx [00:01:12]: What makes you say that? Like, that's so audacious to come out of the box with.Will [00:01:16]: Yeah, okay, so you have to remember the time. This was summer 2021. And, uh, GPT-3 had come out. Like,
AI Engineering for Art — with comfyanonymous, of ComfyUI
Applications for the NYC AI Engineer Summit, focused on Agents at Work, are open!When we first started Latent Space, in the lightning round we’d always ask guests: “What’s your favorite AI product?”. The majority would say Midjourney. The simple UI of prompt → very aesthetic image turned it into a $300M+ ARR bootstrapped business as it rode the first wave of AI image generation.In open source land, StableDiffusion was congregating around AUTOMATIC1111 as the de-facto web UI. Unlike Midjourney, which offered some flags but was mostly prompt-driven, A1111 let users play with a lot more parameters, supported additional modalities like img2img, and allowed users to load in custom models. If you’re interested in some of the SD history, you can look at our episodes with Lexica, Replicate, and Playground.One of the people involved with that community was comfyanonymous, who was also part of the Stability team in 2023, decided to build an alternative called ComfyUI, now one of the fastest growing open source projects in generative images, and is now the preferred partner for folks like Black Forest Labs’s Flux Tools on Day 1. The idea behind it was simple: “Everyone is trying to make easy to use interfaces. Let me try to make a powerful interface that's not easy to use.”Unlike its predecessors, ComfyUI does not have an input text box. Everything is based around the idea of a node: there’s a text input node, a CLIP node, a checkpoint loader node, a KSampler node, a VAE node, etc. While daunting for simple image generation, the tool is amazing for more complex workflows since you can break down every step of the process, and then chain many of them together rather than manually switching between tools. You can also re-start execution halfway instead of from the beginning, which can save a lot of time when using larger models.To give you an idea of some of the new use cases that this type of UI enables:* Sketch something → Generate an image with SD from sketch → feed it into SD Video to animate* Generate an image of an object → Turn into a 3D asset → Feed into interactive experiences* Input audio → Generate audio-reactive videosTheir Examples page also includes some of the more common use cases like AnimateDiff, etc. They recently launched the Comfy Registry, an online library of different nodes that users can pull from rather than having to build everything from scratch. The project has >60,000 Github stars, and as the community grows, some of the projects that people build have gotten quite complex:The most interesting thing about Comfy is that it’s not a UI, it’s a runtime. You can build full applications on top of image models simply by using Comfy. You can expose Comfy workflows as an endpoint and chain them together just like you chain a single node. We’re seeing the rise of AI Engineering applied to art.Major Tom’s ComfyUI Resources from the Latent Space DiscordMajor shoutouts to Major Tom on the LS Discord who is a image generation expert, who offered these pointers:* “best thing about comfy is the fact it supports almost immediately every new thing that comes out - unlike A1111 or forge, which still don't support flux cnet for instance. It will be perfect tool when conflicting nodes will be resolved”* AP Workflows from Alessandro Perili are a nice example of an all-in-one train-evaluate-generate system built atop Comfy* ComfyUI YouTubers to learn from:* @sebastiankamph* @NerdyRodent* @OlivioSarikas* @sedetweiler* @pixaroma* ComfyUI Nodes to check out:* https://github.com/kijai/ComfyUI-IC-Light* https://github.com/MrForExample/ComfyUI-3D-Pack* https://github.com/PowerHouseMan/ComfyUI-AdvancedLivePortrait* https://github.com/pydn/ComfyUI-to-Python-Extension* https://github.com/THtianhao/ComfyUI-Portrait-Maker* https://github.com/ssitu/ComfyUI_NestedNodeBuilder* https://github.com/longgui0318/comfyui-magic-clothing* https://github.com/atmaranto/ComfyUI-SaveAsScript* https://github.com/ZHO-ZHO-ZHO/ComfyUI-InstantID* https://github.com/AIFSH/ComfyUI-FishSpeech* https://github.com/coolzilj/ComfyUI-Photopea* https://github.com/lks-ai/anynode* Sarav: https://www.youtube.com/@mickmumpitz/videos ( applied stuff )* Sarav: https://www.youtube.com/@latentvision (technical, but infrequent)* look for comfyui node for https://github.com/magic-quill/MagicQuill* “Comfy for Video” resources* Kijai (https://github.com/kijai) pushing out support for Mochi, CogVideoX, AnimateDif, LivePortrait etc* Comfyui node support like LTX https://github.com/Lightricks/ComfyUI-LTXVideo , and HunyuanVideo* FloraFauna AI and Krea.ai* Communities: https://www.reddit.com/r/StableDiffusion/, https://www.reddit.com/r/comfyui/Full YouTube EpisodeAs usual, you can find the full video episode on our YouTube (and don’t forget to like and subscribe!)Timestamps* 00:00:04 Introduction of hosts and anonymous guest* 00:00:35 Origins of Comfy UI and early Stable Diffusion landscape* 00:02:58 Comfy's background and development of high-res fix* 00:05:37 Area co
Latent.Space 2024 Year in Review
Applications for the 2025 AI Engineer Summit are up, and you can save the date for AIE Singapore in April and AIE World’s Fair 2025 in June.Happy new year, and thanks for 100 great episodes! Please let us know what you want to see/hear for the next 100!Full YouTube Episode with Slides/ChartsLike and subscribe and hit that bell to get notifs!Timestamps* 00:00 Welcome to the 100th Episode!* 00:19 Reflecting on the Journey* 00:47 AI Engineering: The Rise and Impact* 03:15 Latent Space Live and AI Conferences* 09:44 The Competitive AI Landscape* 21:45 Synthetic Data and Future Trends* 35:53 Creative Writing with AI* 36:12 Legal and Ethical Issues in AI* 38:18 The Data War: GPU Poor vs. GPU Rich* 39:12 The Rise of GPU Ultra Rich* 40:47 Emerging Trends in AI Models* 45:31 The Multi-Modality War* 01:05:31 The Future of AI Benchmarks* 01:13:17 Pionote and Frontier Models* 01:13:47 Niche Models and Base Models* 01:14:30 State Space Models and RWKB* 01:15:48 Inference Race and Price Wars* 01:22:16 Major AI Themes of the Year* 01:22:48 AI Rewind: January to March* 01:26:42 AI Rewind: April to June* 01:33:12 AI Rewind: July to September* 01:34:59 AI Rewind: October to December* 01:39:53 Year-End Reflections and PredictionsTranscript[00:00:00] Welcome to the 100th Episode![00:00:00] Alessio: Hey everyone, welcome to the Latent Space Podcast. This is Alessio, partner and CTO at Decibel Partners, and I'm joined by my co host Swyx for the 100th time today.[00:00:12] swyx: Yay, um, and we're so glad that, yeah, you know, everyone has, uh, followed us in this journey. How do you feel about it? 100 episodes.[00:00:19] Alessio: Yeah, I know.[00:00:19] Reflecting on the Journey[00:00:19] Alessio: Almost two years that we've been doing this. We've had four different studios. Uh, we've had a lot of changes. You know, we used to do this lightning round. When we first started that we didn't like, and we tried to change the question. The answer[00:00:32] swyx: was cursor and perplexity.[00:00:34] Alessio: Yeah, I love mid journey. It's like, do you really not like anything else?[00:00:38] Alessio: Like what's, what's the unique thing? And I think, yeah, we, we've also had a lot more research driven content. You know, we had like 3DAO, we had, you know. Jeremy Howard, we had more folks like that.[00:00:47] AI Engineering: The Rise and Impact[00:00:47] Alessio: I think we want to do more of that too in the new year, like having, uh, some of the Gemini folks, both on the research and the applied side.[00:00:54] Alessio: Yeah, but it's been a ton of fun. I think we both started, I wouldn't say as a joke, we were kind of like, Oh, we [00:01:00] should do a podcast. And I think we kind of caught the right wave, obviously. And I think your rise of the AI engineer posts just kind of get people. Sombra to congregate, and then the AI engineer summit.[00:01:11] Alessio: And that's why when I look at our growth chart, it's kind of like a proxy for like the AI engineering industry as a whole, which is almost like, like, even if we don't do that much, we keep growing just because there's so many more AI engineers. So did you expect that growth or did you expect that would take longer for like the AI engineer thing to kind of like become, you know, everybody talks about it today.[00:01:32] swyx: So, the sign of that, that we have won is that Gartner puts it at the top of the hype curve right now. So Gartner has called the peak in AI engineering. I did not expect, um, to what level. I knew that I was correct when I called it because I did like two months of work going into that. But I didn't know, You know, how quickly it could happen, and obviously there's a chance that I could be wrong.[00:01:52] swyx: But I think, like, most people have come around to that concept. Hacker News hates it, which is a good sign. But there's enough people that have defined it, you know, GitHub, when [00:02:00] they launched GitHub Models, which is the Hugging Face clone, they put AI engineers in the banner, like, above the fold, like, in big So I think it's like kind of arrived as a meaningful and useful definition.[00:02:12] swyx: I think people are trying to figure out where the boundaries are. I think that was a lot of the quote unquote drama that happens behind the scenes at the World's Fair in June. Because I think there's a lot of doubt or questions about where ML engineering stops and AI engineering starts. That's a useful debate to be had.[00:02:29] swyx: In some sense, I actually anticipated that as well. So I intentionally did not. Put a firm definition there because most of the successful definitions are necessarily underspecified and it's actually useful to have different perspectives and you don't have to specify everything from the outset.[00:02:45] Alessio: Yeah, I was at um, AWS reInvent and the line to get into like the AI engineering talk, so to speak, which is, you know, applied AI and whatnot was like, there are like hundreds of people just in lin
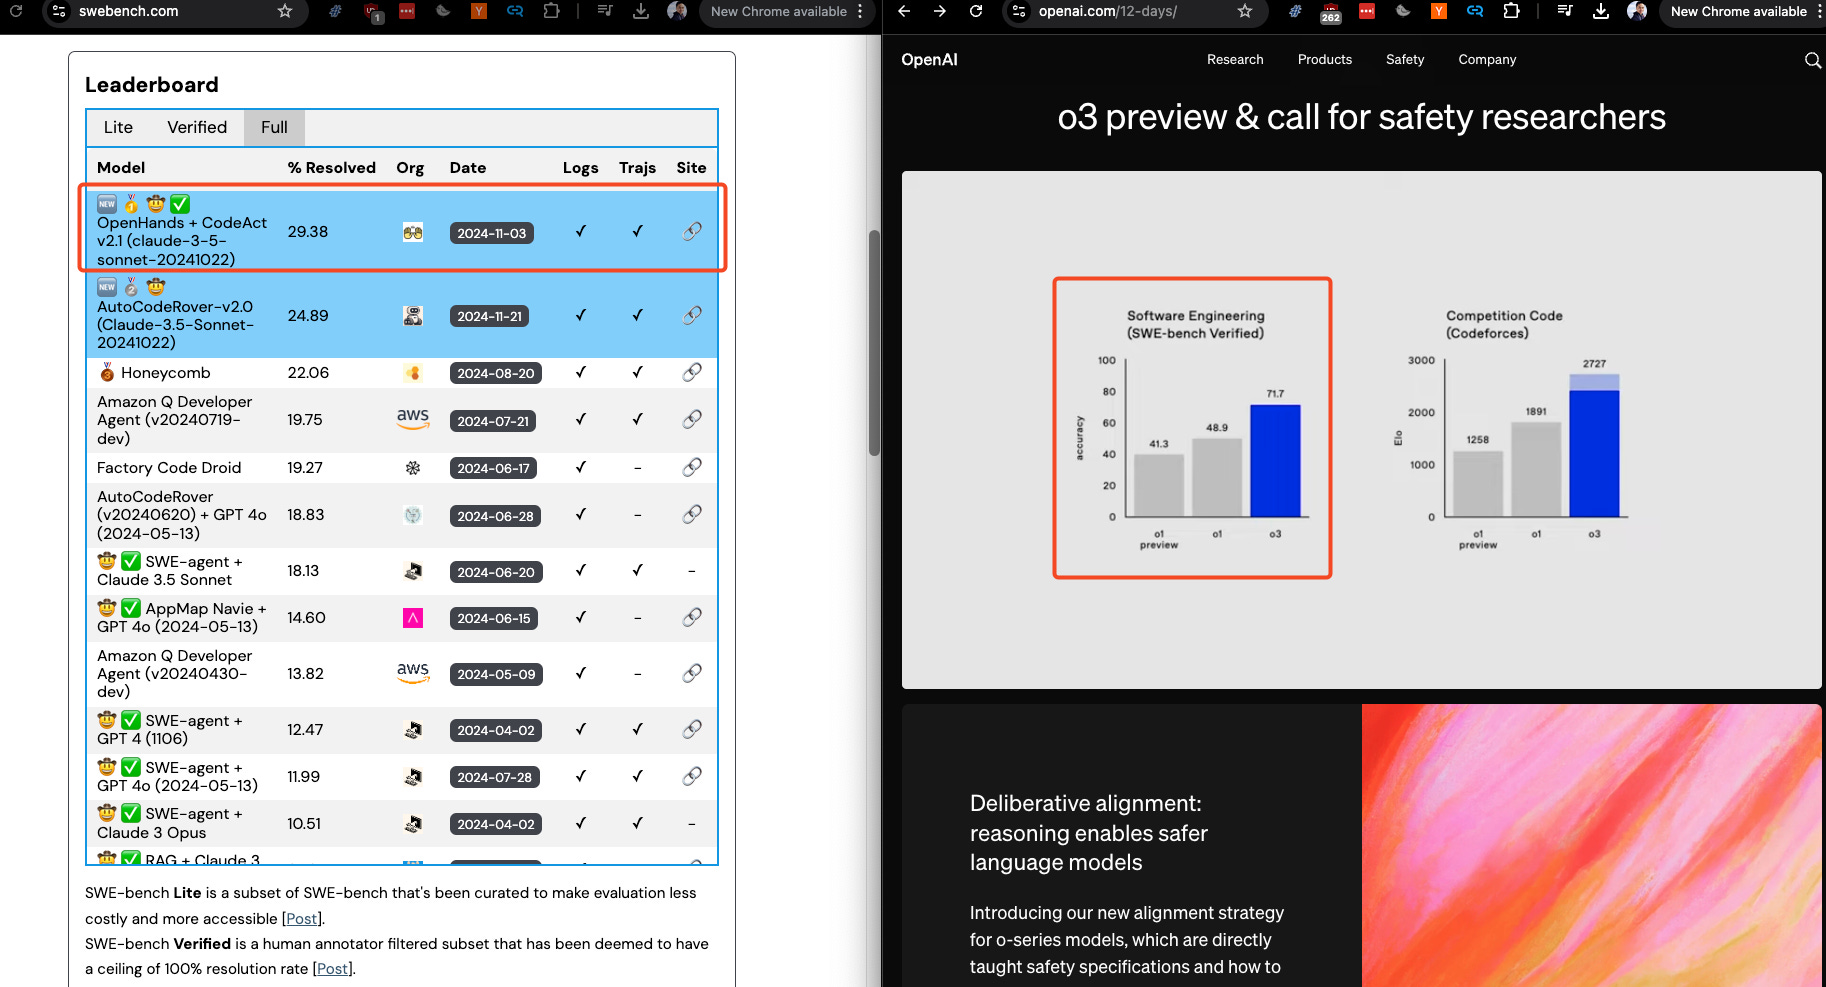
2024 in Agents [LS Live! @ NeurIPS 2024]
Happy holidays! We’ll be sharing snippets from Latent Space LIVE! through the break bringing you the best of 2024! We want to express our deepest appreciation to event sponsors AWS, Daylight Computer, Thoth.ai, StrongCompute, Notable Capital, and most of all all our LS supporters who helped fund the gorgeous venue and A/V production!For NeurIPS last year we did our standard conference podcast coverage interviewing selected papers (that we have now also done for ICLR and ICML), however we felt that we could be doing more to help AI Engineers 1) get more industry-relevant content, and 2) recap 2024 year in review from experts. As a result, we organized the first Latent Space LIVE!, our first in person miniconference, at NeurIPS 2024 in Vancouver.Our next keynote covers The State of LLM Agents, with the triumphant return of Professor Graham Neubig’s return to the pod (his ICLR episode here!). OpenDevin is now a startup known as AllHands! The renamed OpenHands has done extremely well this year, as they end the year sitting comfortably at number 1 on the hardest SWE-Bench Full leaderboard at 29%, though on the smaller SWE-Bench Verified, they are at 53%, behind Amazon Q, devlo, and OpenAI's self reported o3 results at 71.7%.Many are saying that 2025 is going to be the year of agents, with OpenAI, DeepMind and Anthropic setting their sights on consumer and coding agents, vision based computer-using agents and multi agent systems. There has been so much progress on the practical reliability and applications of agents in all domains, from the huge launch of Cognition AI's Devin this year, to the sleeper hit of Cursor Composer and Codeium's Windsurf Cascade in the IDE arena, to the explosive revenue growth of Stackblitz's Bolt, Lovable, and Vercel's v0, and the unicorn rounds and high profile movements of customer support agents like Sierra (now worth $4 billion) and search agents like Perplexity (now worth $9 billion). We wanted to take a little step back to understand the most notable papers of the year in Agents, and Graham indulged with his list of 8 perennial problems in building agents in 2024.Must-Read Papers for the 8 Problems of Agents* The agent-computer interface: CodeAct: Executable Code Actions Elicit Better LLM Agents. Minimial viable tools: Execution Sandbox, File Editor, Web Browsing* The human-agent interface: Chat UI, GitHub Plugin, Remote runtime, …?* Choosing an LLM: See Evaluation of LLMs as Coding Agents on SWE-Bench at 30x - must understand instructions, tools, code, environment, error recovery* Planning: Single Agent Systems vs Multi Agent (CoAct: A Global-Local Hierarchy for Autonomous Agent Collaboration) - Explicit vs Implicit, Curated vs Generated* Reusable common workflows: SteP: Stacked LLM Policies for Web Actions and Agent Workflow Memory - Manual prompting vs Learning from Experience* Exploration: Agentless: Demystifying LLM-based Software Engineering Agents and BAGEL: Bootstrapping Agents by Guiding Exploration with Language* Search: Tree Search for Language Model Agents - explore paths and rewind* Evaluation: Fast Sanity Checks (miniWoB and Aider) and Highly Realistic (WebArena, SWE-Bench) and SWE-Gym: An Open Environment for Training Software Engineering Agents & VerifiersFull Talk on YouTubePlease like and subscribe!Timestamps* 00:00 Welcome to Latent Space Live at NeurIPS 2024* 00:29 State of LLM Agents in 2024* 02:20 Professor Graham Newbig's Insights on Agents* 03:57 Live Demo: Coding Agents in Action* 08:20 Designing Effective Agents* 14:13 Choosing the Right Language Model for Agents* 16:24 Planning and Workflow for Agents* 22:21 Evaluation and Future Predictions for Agents* 25:31 Future of Agent Development* 25:56 Human-Agent Interaction Challenges* 26:48 Expanding Agent Use Beyond Programming* 27:25 Redesigning Systems for Agent Efficiency* 28:03 Accelerating Progress with Agent Technology* 28:28 Call to Action for Open Source Contributions* 30:36 Q&A: Agent Performance and Benchmarks* 33:23 Q&A: Web Agents and Interaction Methods* 37:16 Q&A: Agent Architectures and Improvements* 43:09 Q&A: Self-Improving Agents and Authentication* 47:31 Live Demonstration and Closing RemarksTranscript[00:00:29] State of LLM Agents in 2024[00:00:29] Speaker 9: Our next keynote covers the state of LLM agents. With the triumphant return of Professor Graham Newbig of CMU and OpenDevon, now a startup known as AllHands. The renamed OpenHands has done extremely well this year, as they end the year sitting comfortably at number one on the hardest SWE Benchful leaderboard at 29%.[00:00:53] Speaker 9: Though, on the smaller SWE bench verified, they are at 53 percent behind Amazon Q [00:01:00] Devlo and OpenAI's self reported O3 results at 71. 7%. Many are saying that 2025 is going to be the year of agents, with OpenAI, DeepMind, and Anthropic setting their sights on consumer and coding agents. Vision based computer using agents and multi agent systems.[00:01:22] Speaker 9: There has been so much pr
2024 in Synthetic Data and Smol Models [LS Live @ NeurIPS]
Happy holidays! We’ll be sharing snippets from Latent Space LIVE! through the break bringing you the best of 2024! We want to express our deepest appreciation to event sponsors AWS, Daylight Computer, Thoth.ai, StrongCompute, Notable Capital, and most of all all our LS supporters who helped fund the gorgeous venue and A/V production!For NeurIPS last year we did our standard conference podcast coverage interviewing selected papers (that we have now also done for ICLR and ICML), however we felt that we could be doing more to help AI Engineers 1) get more industry-relevant content, and 2) recap 2024 year in review from experts. As a result, we organized the first Latent Space LIVE!, our first in person miniconference, at NeurIPS 2024 in Vancouver. Today, we’re proud to share Loubna’s highly anticipated talk (slides here)!Synthetic DataWe called out the Synthetic Data debate at last year’s NeurIPS, and no surprise that 2024 was dominated by the rise of synthetic data everywhere:* Apple’s Rephrasing the Web, Microsoft’s Phi 2-4 and Orca/AgentInstruct, Tencent’s Billion Persona dataset, DCLM, and HuggingFace’s FineWeb-Edu, and Loubna’s own Cosmopedia extended the ideas of synthetic textbook and agent generation to improve raw web scrape dataset quality* This year we also talked to the IDEFICS/OBELICS team at HuggingFace who released WebSight this year, the first work on code-vs-images synthetic data.* We called Llama 3.1 the Synthetic Data Model for its extensive use (and documentation!) of synthetic data in its pipeline, as well as its permissive license. * Nemotron CC and Nemotron-4-340B also made a big splash this year for how they used 20k items of human data to synthesize over 98% of the data used for SFT/PFT.* Cohere introduced Multilingual Arbitrage: Optimizing Data Pools to Accelerate Multilingual Progress observing gains of up to 56.5% improvement in win rates comparing multiple teachers vs the single best teacher model* In post training, AI2’s Tülu3 (discussed by Luca in our Open Models talk) and Loubna’s Smol Talk were also notable open releases this year.This comes in the face of a lot of scrutiny and criticism, with Scale AI as one of the leading voices publishing AI models collapse when trained on recursively generated data in Nature magazine bringing mainstream concerns to the potential downsides of poor quality syndata:Part of the concerns we highlighted last year on low-background tokens are coming to bear: ChatGPT contaminated data is spiking in every possible metric:But perhaps, if Sakana’s AI Scientist pans out this year, we will have mostly-AI AI researchers publishing AI research anyway so do we really care as long as the ideas can be verified to be correct?Smol ModelsMeta surprised many folks this year by not just aggressively updating Llama 3 and adding multimodality, but also adding a new series of “small” 1B and 3B “on device” models this year, even working on quantized numerics collaborations with Qualcomm, Mediatek, and Arm. It is near unbelievable that a 1B model today can qualitatively match a 13B model of last year:and the minimum size to hit a given MMLU bar has come down roughly 10x in the last year. We have been tracking this proxied by Lmsys Elo and inference price:The key reads this year are:* MobileLLM: Optimizing Sub-billion Parameter Language Models for On-Device Use Cases* Apple Intelligence Foundation Language Models* Hymba: A Hybrid-head Architecture for Small Language Models* Loubna’s SmolLM and SmolLM2: a family of state-of-the-art small models with 135M, 360M, and 1.7B parameters on the pareto efficiency frontier.* and Moondream, which we already covered in the 2024 in Vision talkFull Talk on YouTubeplease like and subscribe!Timestamps* [00:00:05] Loubna Intro* [00:00:33] The Rise of Synthetic Data Everywhere* [00:02:57] Model Collapse* [00:05:14] Phi, FineWeb, Cosmopedia - Synthetic Textbooks* [00:12:36] DCLM, Nemotron-CC* [00:13:28] Post Training - AI2 Tulu, Smol Talk, Cohere Multilingual Arbitrage* [00:16:17] Smol Models* [00:18:24] On Device Models* [00:22:45] Smol Vision Models* [00:25:14] What's NextTranscript2024 in Synthetic Data and Smol Models[00:00:00] [00:00:05] Loubna Intro[00:00:05] Speaker: I'm very happy to be here. Thank you for the invitation. So I'm going to be talking about synthetic data in 2024. And then I'm going to be talking about small on device models. So I think the most interesting thing about synthetic data this year is that like now we have it everywhere in the large language models pipeline.[00:00:33] The Rise of Synthetic Data Everywhere[00:00:33] Speaker: I think initially, synthetic data was mainly used just for post training, because naturally that's the part where we needed human annotators. And then after that, we realized that we don't really have good benchmarks to [00:01:00] measure if models follow instructions well, if they are creative enough, or if they are chatty enough, so we also started using LLMs as judges.[00:01:08]
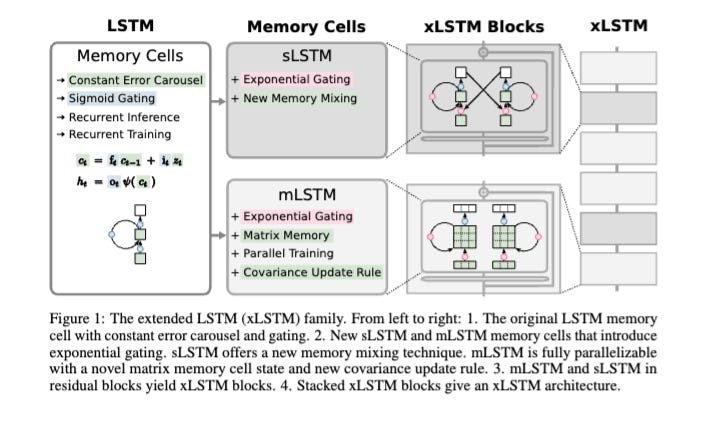
2024 in Post-Transformers Architectures (State Space Models, RWKV) [LS Live @ NeurIPS]
Happy holidays! We’ll be sharing snippets from Latent Space LIVE! through the break bringing you the best of 2024! We want to express our deepest appreciation to event sponsors AWS, Daylight Computer, Thoth.ai, StrongCompute, Notable Capital, and most of all all our LS supporters who helped fund the gorgeous venue and A/V production!Update: see followup discussion on HN and also the YouTube discussion.For NeurIPS last year we did our standard conference podcast coverage interviewing selected papers (that we have now also done for ICLR and ICML), however we felt that we could be doing more to help AI Engineers 1) get more industry-relevant content, and 2) recap 2024 year in review from experts. As a result, we organized the first Latent Space LIVE!, our first in person miniconference, at NeurIPS 2024 in Vancouver.Of perennial interest, particularly at academic conferences, is scaled-up architecture research as people hunt for the next Attention Is All You Need. We have many names for them: “efficient models”, “retentive networks”, “subquadratic attention” or “linear attention” but some of them don’t even have any lineage with attention - one of the best papers of this NeurIPS was Sepp Hochreiter’s xLSTM, which has a particularly poetic significance as one of the creators of the LSTM returning to update and challenge the OG language model architecture:So, for lack of a better term, we decided to call this segment “the State of Post-Transformers” and fortunately everyone rolled with it.We are fortunate to have two powerful friends of the pod to give us an update here:* Together AI: with CEO Vipul Ved Prakash and CTO Ce Zhang joining us to talk about how they are building Together together as a quote unquote full stack AI startup, from the lowest level kernel and systems programming to the highest level mathematical abstractions driving new model architectures and inference algorithms, with notable industry contributions from RedPajama v2, Flash Attention 3, Mamba 2, Mixture of Agents, BASED, Sequoia, Evo, Dragonfly, Dan Fu's ThunderKittens and many more research projects this year* Recursal AI: with CEO Eugene Cheah who has helped lead the independent RWKV project while also running Featherless AI. This year, the team has shipped RWKV v5, codenamed Eagle, to 1.5 billion Windows 10 and Windows 11 machines worldwide, to support Microsoft's on-device, energy-usage-sensitive Windows Copilot usecases, and has launched the first updates on RWKV v6, codenamed Finch and GoldFinch. On the morning of Latent Space Live, they also announced QRWKV6, a Qwen 32B model modified with RWKV linear attention layers. We were looking to host a debate between our speakers, but given that both of them were working on post-transformers alternativesFull Talk on YoutubePlease like and subscribe!LinksAll the models and papers they picked:* Earlier Cited Work* Transformers are RNNs: Fast Autoregressive Transformers with Linear Attention* Hungry hungry hippos: Towards language modeling with state space models* Hyena hierarchy: Towards larger convolutional language models* Mamba: Linear-Time Sequence Modeling with Selective State Spaces* S4: Efficiently Modeling Long Sequences with Structured State Spaces* Just Read Twice (Arora et al)* Recurrent large language models that compete with Transformers in language modeling perplexity are emerging at a rapid rate (e.g., Mamba, RWKV). Excitingly, these architectures use a constant amount of memory during inference. However, due to the limited memory, recurrent LMs cannot recall and use all the information in long contexts leading to brittle in-context learning (ICL) quality. A key challenge for efficient LMs is selecting what information to store versus discard. In this work, we observe the order in which information is shown to the LM impacts the selection difficulty. * To formalize this, we show that the hardness of information recall reduces to the hardness of a problem called set disjointness (SD), a quintessential problem in communication complexity that requires a streaming algorithm (e.g., recurrent model) to decide whether inputted sets are disjoint. We empirically and theoretically show that the recurrent memory required to solve SD changes with set order, i.e., whether the smaller set appears first in-context. * Our analysis suggests, to mitigate the reliance on data order, we can put information in the right order in-context or process prompts non-causally. Towards that end, we propose: (1) JRT-Prompt, where context gets repeated multiple times in the prompt, effectively showing the model all data orders. This gives 11.0±1.3 points of improvement, averaged across 16 recurrent LMs and the 6 ICL tasks, with 11.9× higher throughput than FlashAttention-2 for generation prefill (length 32k, batch size 16, NVidia H100). We then propose (2) JRT-RNN, which uses non-causal prefix-linear-attention to process prompts and provides 99% of Transformer quality at 360M params., 30B tokens and 96% at 1
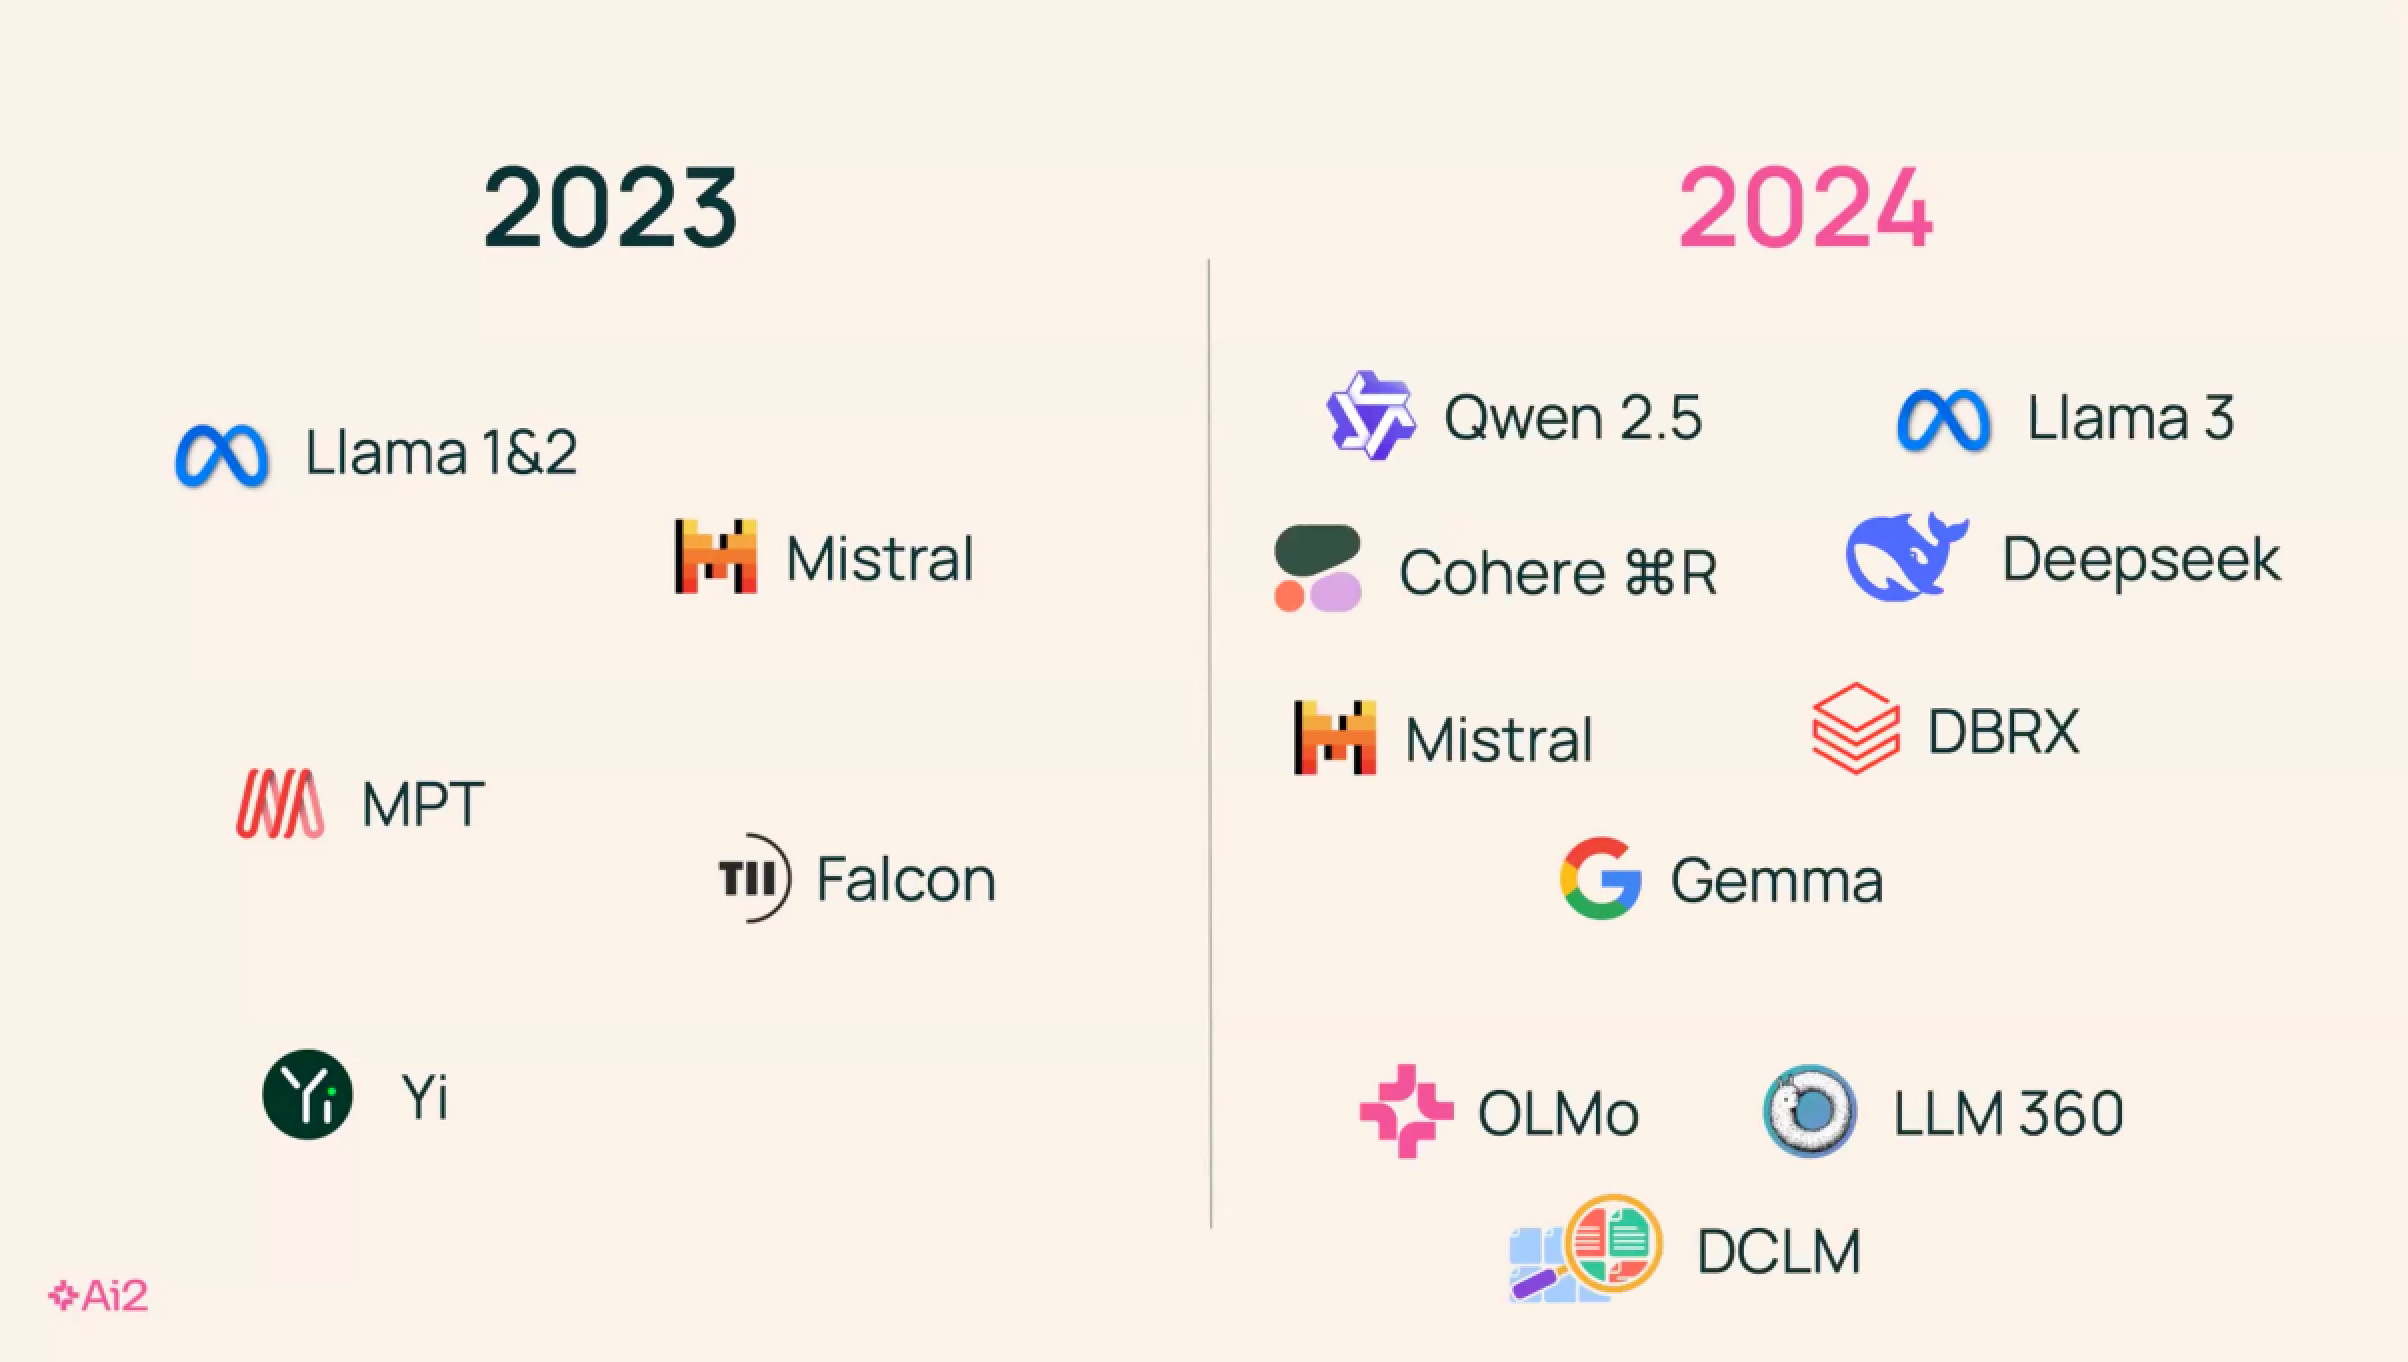
2024 in Open Models [LS Live @ NeurIPS]
Happy holidays! We’ll be sharing snippets from Latent Space LIVE! through the break bringing you the best of 2024! We want to express our deepest appreciation to event sponsors AWS, Daylight Computer, Thoth.ai, StrongCompute, Notable Capital, and most of all our LS supporters who helped fund the venue and A/V production!For NeurIPS last year we did our standard conference podcast coverage interviewing selected papers (that we have now also done for ICLR and ICML), however we felt that we could be doing more to help AI Engineers 1) get more industry-relevant content, and 2) recap 2024 year in review from experts. As a result, we organized the first Latent Space LIVE!, our first in person miniconference, at NeurIPS 2024 in Vancouver.Since Nathan Lambert ( Interconnects ) joined us for the hit RLHF 201 episode at the start of this year, it is hard to overstate how much Open Models have exploded this past year. In 2023 only five names were playing in the top LLM ranks, Mistral, Mosaic's MPT, TII UAE's Falcon, Yi from Kai-Fu Lee's 01.ai, and of course Meta's Llama 1 and 2. This year a whole cast of new open models have burst on the scene, from Google's Gemma and Cohere's Command R, to Alibaba's Qwen and Deepseek models, to LLM 360 and DCLM and of course to the Allen Institute's OLMo, OL MOE, Pixmo, Molmo, and Olmo 2 models. We were honored to host Luca Soldaini, one of the research leads on the Olmo series of models at AI2.Pursuing Open Model research comes with a lot of challenges beyond just funding and access to GPUs and datasets, particularly the regulatory debates this year across Europe, California and the White House. We also were honored to hear from and Sophia Yang, head of devrel at Mistral, who also presented a great session at the AI Engineer World's Fair Open Models track!Full Talk on YouTubePlease like and subscribe!Timestamps* 00:00 Welcome to Latent Space Live * 00:12 Recap of 2024: Best Moments and Keynotes * 01:22 Explosive Growth of Open Models in 2024 * 02:04 Challenges in Open Model Research * 02:38 Keynote by Luca Soldani: State of Open Models * 07:23 Significance of Open Source AI Licenses * 11:31 Research Constraints and Compute Challenges * 13:46 Fully Open Models: A New Trend * 27:46 Mistral's Journey and Innovations * 32:57 Interactive Demo: Lachat Capabilities * 36:50 Closing Remarks and NetworkingTranscriptSession3Audio[00:00:00] AI Charlie: Welcome to Latent Space Live, our first mini conference held at NeurIPS 2024 in Vancouver. This is Charlie, your AI co host. As a special treat this week, we're recapping the best of 2024 going domain by domain. We sent out a survey to the over 900 of you who told us what you wanted, and then invited the best speakers in the latent space network to cover each field.[00:00:28] AI Charlie: 200 of you joined us in person throughout the day, with over 2, 200 watching live online. Our next keynote covers the state of open models in 2024, with Luca Soldani and Nathan Lambert of the Allen Institute for AI, with a special appearance from Dr. Sophia Yang of Mistral. Our first hit episode of 2024 was with Nathan Lambert on RLHF 201 back in January.[00:00:57] AI Charlie: Where he discussed both reinforcement learning for language [00:01:00] models and the growing post training and mid training stack with hot takes on everything from constitutional AI to DPO to rejection sampling and also previewed the sea change coming to the Allen Institute. And to Interconnects, his incredible substack on the technical aspects of state of the art AI training.[00:01:18] AI Charlie: We highly recommend subscribing to get access to his Discord as well. It is hard to overstate how much open models have exploded this past year. In 2023, only five names were playing in the top LLM ranks. Mistral, Mosaics MPT, and Gatsby. TII UAE's Falcon, Yi, from Kaifu Lee's 01. ai, And of course, Meta's Lama 1 and 2.[00:01:43] AI Charlie: This year, a whole cast of new open models have burst on the scene. From Google's Jemma and Cohere's Command R, To Alibaba's Quen and DeepSeq models, to LLM360 and DCLM, and of course, to the Allen Institute's OLMO, [00:02:00] OLMOE, PIXMO, MOLMO, and OLMO2 models. Pursuing open model research comes with a lot of challenges beyond just funding and access to GPUs and datasets, particularly the regulatory debates this year across Europe.[00:02:14] AI Charlie: California and the White House. We also were honored to hear from Mistral, who also presented a great session at the AI Engineer World's Fair Open Models track. As always, don't forget to check the show notes for the YouTube link to their talk, as well as their slides. Watch out and take care.[00:02:35] Luca Intro[00:02:35] Luca Soldaini: Cool. Yeah, thanks for having me over. I'm Luca. I'm a research scientist at the Allen Institute for AI. I threw together a few slides on sort of like a recap of like interesting themes in open models for, for 2024. Have about maybe 20, 25 minutes of slides, and then we
2024 in Vision [LS Live @ NeurIPS]
Happy holidays! We’ll be sharing snippets from Latent Space LIVE! through the break bringing you the best of 2024! We want to express our deepest appreciation to event sponsors AWS, Daylight Computer, Thoth.ai, StrongCompute, Notable Capital, and most of all all our LS supporters who helped fund the gorgeous venue and A/V production!For NeurIPS last year we did our standard conference podcast coverage interviewing selected papers (that we have now also done for ICLR and ICML), however we felt that we could be doing more to help AI Engineers 1) get more industry-relevant content, and 2) recap 2024 year in review from experts. As a result, we organized the first Latent Space LIVE!, our first in person miniconference, at NeurIPS 2024 in Vancouver.The single most requested domain was computer vision, and we could think of no one better to help us recap 2024 than our friends at Roboflow, who was one of our earliest guests in 2023 and had one of this year’s top episodes in 2024 again. Roboflow has since raised a $40m Series B!LinksTheir slides are here:All the trends and papers they picked:* Isaac Robinson* Sora (see our Video Diffusion pod) - extending diffusion from images to video* SAM 2: Segment Anything in Images and Videos (see our SAM2 pod) - extending prompted masks to full video object segmentation* DETR Dominancy: DETRs show Pareto improvement over YOLOs* RT-DETR: DETRs Beat YOLOs on Real-time Object Detection* LW-DETR: A Transformer Replacement to YOLO for Real-Time Detection* D-FINE: Redefine Regression Task in DETRs as Fine-grained Distribution Refinement* Peter Robicheaux* MMVP (Eyes Wide Shut? Exploring the Visual Shortcomings of Multimodal LLMs)* * Florence 2 (Florence-2: Advancing a Unified Representation for a Variety of Vision Tasks) * PalíGemma / PaliGemma 2* PaliGemma: A versatile 3B VLM for transfer* PaliGemma 2: A Family of Versatile VLMs for Transfer* AlMv2 (Multimodal Autoregressive Pre-training of Large Vision Encoders) * Vik Korrapati - MoondreamFull Talk on YouTubeWant more content like this? Like and subscribe to stay updated on our latest talks, interviews, and podcasts.Transcript/Timestamps[00:00:00] Intro[00:00:05] AI Charlie: welcome to Latent Space Live, our first mini conference held at NeurIPS 2024 in Vancouver. This is Charlie, your AI co host. When we were thinking of ways to add value to our academic conference coverage, we realized that there was a lack of good talks, just recapping the best of 2024, going domain by domain.[00:00:36] AI Charlie: We sent out a survey to the over 900 of you. who told us what you wanted, and then invited the best speakers in the Latent Space Network to cover each field. 200 of you joined us in person throughout the day, with over 2, 200 watching live online. Our second featured keynote is The Best of Vision 2024, with Peter Robichaud and Isaac [00:01:00] Robinson of Roboflow, with a special appearance from Vic Corrapati of Moondream.[00:01:05] AI Charlie: When we did a poll of our attendees, the highest interest domain of the year was vision. And so our first port of call was our friends at Roboflow. Joseph Nelson helped us kickstart our vision coverage in episode 7 last year, and this year came back as a guest host with Nikki Ravey of Meta to cover segment Anything 2.[00:01:25] AI Charlie: Roboflow have consistently been the leaders in open source vision models and tooling. With their SuperVision library recently eclipsing PyTorch's Vision library. And Roboflow Universe hosting hundreds of thousands of open source vision datasets and models. They have since announced a 40 million Series B led by Google Ventures.[00:01:46] AI Charlie: Woohoo.[00:01:48] Isaac's picks[00:01:48] Isaac Robinson: Hi, we're Isaac and Peter from Roboflow, and we're going to talk about the best papers of 2024 in computer vision. So, for us, we defined best as what made [00:02:00] the biggest shifts in the space. And to determine that, we looked at what are some major trends that happened and what papers most contributed to those trends.[00:02:09] Isaac Robinson: So I'm going to talk about a couple trends, Peter's going to talk about a trend, And then we're going to hand it off to Moondream. So, the trends that I'm interested in talking about are These are a major transition from models that run on per image basis to models that run using the same basic ideas on video.[00:02:28] Isaac Robinson: And then also how debtors are starting to take over the real time object detection scene from the YOLOs, which have been dominant for years.[00:02:37] Sora, OpenSora and Video Vision vs Generation[00:02:37] Isaac Robinson: So as a highlight we're going to talk about Sora, which from my perspective is the biggest paper of 2024, even though it came out in February. Is the what?[00:02:48] Isaac Robinson: Yeah. Yeah. So just it's a, SORA is just a a post. So I'm going to fill it in with details from replication efforts, including open SORA and related work, such as a stable [00:03:0
2024 in AI Startups [LS Live @ NeurIPS]
Happy holidays! We’ll be sharing snippets from Latent Space LIVE! through the break bringing you the best of 2024 from friends of the pod!For NeurIPS last year we did our standard conference podcast coverage interviewing selected papers (that we have now also done for ICLR and ICML), however we felt that we could be doing more to help AI Engineers 1) get more industry-relevant content, and 2) recap 2024 year in review from experts. As a result, we organized the first Latent Space LIVE!, our first in person miniconference, at NeurIPS 2024 in Vancouver. For our opening keynote, we could think of no one better to cover 'The State of AI Startups' than our friend Sarah Guo (AI superinvestor, founder of Conviction, host of No Priors!) and Pranav Reddy (Conviction partner) to share their takes on how the AI landscape evolved in 2024 examine the evolving AI landscape and what it means for startups, enterprises, and the industry as a whole! They completely understood the assignment.Recorded live with 200+ in-person and 2200+ online attendees at NeurIPS 2024, this keynote kicks off our mini-conference series exploring different domains of AI development in 2024. Enjoy!LinksSlides: https://x.com/saranormous/status/1866933642401886707Sarh Guo: https://x.com/saranormousPranav Reddy: https://x.com/prnvrdyFull Video on YouTubeWant more content like this? Like and subscribe to stay updated on our latest talks, interviews, and podcasts. This is a public episode. If you'd like to discuss this with other subscribers or get access to bonus episodes, visit www.latent.space/subscribe
Windsurf: The Enterprise AI IDE - with Varun and Anshul of Codeium AI
Our second podcast guest ever in March 2023 was Varun Mohan, CEO of Codeium; at the time, they had around 10,000 users and how they vowed to keep their autocomplete free forever: Today, over a million developers use their products, they still have their free tier, and they recently launched Windsurf, an AI IDE. Chapters* 00:00:00: Introductions & Catchup* 00:03:52: Why they created Windsurf* 00:05:52: Limitations of VS Code* 00:10:12: Evaluation methods for Cascade and Windsurf* 00:16:15: Listener questions about Windsurf launch* 00:20:30: Remote execution and security concerns* 00:25:18: Evolution of Codeium's strategy* 00:28:29: Cascade and its capabilities* 00:33:12: Multi-agent systems* 00:37:02: Areas of improvement for Windsurf* 00:39:12: Building an enterprise-first company* 00:42:01: Copilot for X, AI UX, and Enterprise AI blog posts This is a public episode. If you'd like to discuss this with other subscribers or get access to bonus episodes, visit www.latent.space/subscribe
Generative Video WorldSim, Diffusion, Vision, Reinforcement Learning and Robotics — ICML 2024 Part 1
Regular tickets are now sold out for Latent Space LIVE! at NeurIPS! We have just announced our last speaker and newest track, friend of the pod Nathan Lambert who will be recapping 2024 in Reasoning Models like o1! We opened up a handful of late bird tickets for those who are deciding now — use code DISCORDGANG if you need it. See you in Vancouver!We’ve been sitting on our ICML recordings for a while (from today’s first-ever SOLO guest cohost, Brittany Walker), and in light of Sora Turbo’s launch (blogpost, tutorials) today, we figured it would be a good time to drop part one which had been gearing up to be a deep dive into the state of generative video worldsim, with a seamless transition to vision (the opposite modality), and finally robots (their ultimate application).Sora, Genie, and the field of Generative Video World SimulatorsBill Peebles, author of Diffusion Transformers, gave his most recent Sora talk at ICML, which begins our episode:* William (Bill) Peebles - SORA (slides)Something that is often asked about Sora is how much inductive biases were introduced to achieve these results. Bill references the same principles brought by Hyung Won Chung from the o1 team - “sooner or later those biases come back to bite you”.We also recommend these reads from throughout 2024 on Sora.* Lilian Weng’s literature review of Video Diffusion Models* Sora API leak* Estimates of 100k-700k H100s needed to serve Sora (not Turbo)* Artist guides on using Sora for professional storytellingGoogle DeepMind had a remarkably strong presence at ICML on Video Generation Models, winning TWO Best Paper awards for:* Genie: Generative Interactive Environments (covered in oral, poster, and workshop)* VideoPoet: A Large Language Model for Zero-Shot Video Generation (see website)We end this part by taking in Tali Dekel’s talk on The Future of Video Generation: Beyond Data and Scale.Part 2: Generative Modeling and DiffusionSince 2023, Sander Dieleman’s perspectives (blogpost, tweet) on diffusion as “spectral autoregression in the frequency domain” while working on Imagen and Veo have caught the public imagination, so we highlight his talk:* Wading through the noise: an intuitive look at diffusion modelsThen we go to Ben Poole for his talk on Inferring 3D Structure with 2D Priors, including his work on NeRFs and DreamFusion:Then we investigate two flow matching papers - one from the Flow Matching co-authors - Ricky T. Q. Chen (FAIR, Meta)And how it is implemented in Stable Diffusion 3 with Scaling Rectified Flow Transformers for High-Resolution Image Synthesis Our last hit on Diffusion is a couple of oral presentations on speech, which we leave you to explore via our audio podcast* NaturalSpeech 3: Zero-Shot Speech Synthesis with Factorized Codec and Diffusion Models* Speech Self-Supervised Learning Using Diffusion Model Synthetic DataPart 3: VisionThe ICML Test of Time winner was DeCAF, which Trevor Darrell notably called “the OG vision foundation model”.Lucas Beyer’s talk on “Vision in the age of LLMs — a data-centric perspective” was also well received online, and he talked about his journey from Vision Transformers to PaliGemma.We give special honorable mention to MLLM-as-a-Judge: Assessing Multimodal LLM-as-a-Judge with Vision-Language Benchmark.Part 4: Reinforcement Learning and RoboticsWe segue vision into robotics with the help of Ashley Edwards, whose work on both the Gato and the Genie teams at Deepmind is summarized in Learning actions, policies, rewards, and environments from videos alone.Brittany highlighted two poster session papers:* Behavior Generation with Latent Actions* We also recommend Lerrel Pinto’s On Building General-Purpose Robots* PIVOT: Iterative Visual Prompting Elicits Actionable Knowledge for VLMsHowever we must give the lion’s share of space to Chelsea Finn, now founder of Physical Intelligence, who gave FOUR talks on* "What robots have taught me about machine learning"* developing robot generalists* robots that adapt autonomously* how to give feedback to your language model* special mention to PI colleague Sergey Levine on Robotic Foundation ModelsWe end the podcast with a position paper that links generative environments and RL/robotics: Automatic Environment Shaping is the Next Frontier in RL.Timestamps* [00:00:00] Intros* [00:02:43] Sora - Bill Peebles* [00:44:52] Genie: Generative Interactive Environments* [01:00:17] Genie interview* [01:12:33] VideoPoet: A Large Language Model for Zero-Shot Video Generation* [01:30:51] VideoPoet interview - Dan Kondratyuk* [01:42:00] Tali Dekel - The Future of Video Generation: Beyond Data and Scale.* [02:27:07] Sander Dieleman - Wading through the noise: an intuitive look at diffusion models* [03:06:20] Ben Poole - Inferring 3D Structure with 2D Priors* [03:30:30] Ricky Chen - Flow Matching* [04:00:03] Patrick Esser - Stable Diffusion 3* [04:14:30] NaturalSpeech 3: Zero-Shot Speech Synthesis with Factorized Codec and Diffusion Models* [04:27:00] Speech Self-Supervi