
ThursdAI - The top AI news from the past week
182 episodes — Page 1 of 4
ThursdAI - Oct 29 - Gemini 4 Carbon is the new #1, Anthropic files to go public & more
ThursdAI - Oct 22 - AI finds all the vulnerabilities, Claude Duet, DeepSeek drops Infer & more AI news
Claude now leads 26% of Anthropic’s R&D, Meta drops an 816B open model & Gemini 4 Argon
Chen Goldberg (CoreWeave) on the AI loop, Forge and infrastructure for agents
ThursdAI - Oct 8 - OpenAI drops 722 math papers, Haiku 5.5 hits 10 cents & more
ThursdAI - Oct 1 - OpenAI joins the assistant race, CoreWeave drops serverless GPUs & more
Opus 5.5 is your new workhorse! OpenAI ships GPT 6 Sol and Luna before DevDay and Meta goes all in on Muse! Your friday read is here
ThursdAI - Sep 17 - TypeSafe's Jev is a ChatGPT moment for decisions, Pace the Frontier splits the labs & more
OpenAI solves Navier-Stokes, Meta’s Muse a free AI agent that’s really good, DeepSeek V4.1 shrinks KV cache, and one doomer post causes OpenAI to consider pausing training + more AI news
Welcome to AGI - our GPT-6 deep coverage, vibe check and demoes - part 2 of this insane week
Welcome to AGI part 1 - Fable 5.1, Muse Spark beats Sol, 3 new world models blow our minds
NVIDIA Buys Hugging Face! GLM-5.3-Flash, Qwen4 Preview, Gemini Omni 1.1, and the Datacenter Debate w/ Andy Masley
OpenAI pauses, Stripe buys OpenRouter, ZAI drops GLM 5.3, and 3 interviews including 1 breaking news, oh and does AI create Cancer Vaccines | ThursdAI Aug 20
ThursdAI - Grok 4.6, Grok Bot deep dive, DeepSeek v4 Pro, Meta Muse Glimmer & more AI news | ThursdAi Aug 13
ThursdAI - Aug 06 - Google shakeup, Details on OpenAI hack, 2 new agent harnesses, 4 video models (1 Open) and 3 guest segments
This Week in AI: Open Weights, Frontier Models, Sandbox Escapes, Voice & AI Detection
ThursdAI Special - OpenAI's Romain Huet on Codex's 5M users, GPT-5.6 & the Golden Age of AI Engineering
ThursdAI - Jul 16 - Inkling 975B open weights, Kimi K3 at 2.8T, a 27B model on a phone & Codex hits 9M
AI WorldCup (or superbowl?) GPT-5.6 lands mid-show, Zuck returns to X for Muse Spark 1.1, GPT-Live talks while it listens & Grok 4.5 trained with Cursor, Fable extended - ThursdAI - Jul 9, 2026
ThursdAI - July 2 - LIVE from AI Engineer World's Fair 🎪 Long LIVE
GLM 5.2 total victory: the week open source won and nobody panicked
Fable Got Banned, Open Source Delivered: GLM-5.2, Kimi K2.7 & SpaceX Buys Cursor - June 18
📅 ThursdAI - Jun 11, 2026 - Fable & Mythos 5 are here, Anthropic gets caught sandbagging (then reverses), Siri AI finally works!? and we got live-translated on air
📅 ThursdAI - Jun 4 - NVIDIA drops Nemotron 3 Ultra (550B open), Microsoft becomes a frontier lab, Ideogram 4 goes open, Agent Arena & more
📅 May 28 - Opus 4.8 ships mid-show, the Pope writes 42K words on AI, 11labs dubs the world and DeepSwe breaks coding evals
AI just cracked an 80-year-old math problem nobody could solve — plus everything from Google I/O 26
ThursdAI - May 14 - TML Interaction Models, Musk v Altman Disclosures, CW Sandboxes & /goal Takes Over
📅 ThursdAI - May 7 - Interviews with Sunil Pai, Sally Ann Omalley from AI Engineer Europe
📅 ThursdAI - Apr 30 - DeepSeek V4 (1.6T MoE), Cursor SDK Wins WolfBench, Mayo's REDMOD Saves Lives, Stripe Gives Agents a Wallet & more
📅 Apr 23: OpenAI's Week: GPT-5.5, GPT-Image-2, Codex CUA + Chronicle, + Claude Design, Kimi K2.6, Qwen 3.6-27B
April 16 - Codex uses your mac in the background, Opus 4.7 release not quite Mythos + 3 interviews
📅 ThursdAI LIVE from London - Claude Mythos, Codex Resets, Muse Spark & More | w/ Swyx and friends from OpenAI, Deepmind, LMArena and OpenClaw
📅 ThursdAI - Apr 2 - Gemma 4 is the new LLama, Claude Code Leak, OpenAI raises $122B & more AI news
Hey Ya’ll, Alex here, let me catch you up. What a week! Anthropic is in the spotlight again, first with #SessionGate, then with the whole Claude Code source code leak, and finally with an incredible research into LLM having feelings!? (more on this below). And while Anthropic continues to burn through developer good will faster than their sessions, OpenAI announced a MASSIVE $122B round of funding (largest in history), Google released Gemma 4 with Apache 2 license - we had Omar Sanseviero on the show to help us cover what’s new, Microsoft dropped 3 new AI models (not LLMs) and PrismML potentially revolutionized local LLM inference with lossless 1-bit quantization! P.S - Oh also, something on X algo changed, I get way more exposure now, 3 out of my best 5 posts ever have been from this week + I got the coveted Elon RT on my Claude Code leak coverage. I’ll try to stay humble 😂 Anyway, let’s dive in, don’t forget to hit like or share with friends, and TL;DR with links is as always, at the bottom: ThursdAI - Highest signal weekly AI news show is a reader-supported publication. To receive new posts and support my work, consider becoming a free or paid subscriber.The Claude Code source Leak: Half a Million Lines of “Oops”So here’s what happened. On March 31st, Anthropic shipped Claude Code version 2.1.88 to npm. Inside that package was a 59.8 megabyte source map file — basically a debugging artifact that contained the entire compiled source code. 512,000 lines of TypeScript across 1,900 files. The entire playbook for how the Claude Code harness works, including a lot of stuff that wasn’t supposed to be public yet.A researcher named Chaofan Shou spotted it at 4 AM ET, posted the download link, Sigrid (who came to the show) posted it on Github and within six hours it had 3 million views and 41,000 GitHub forks (This repo is the highest starred repo in Github history btw, with well over 150K Github stars). Anthropic started filing takedowns, but the internet being the internet, it was already everywhere. The source code is still on tens of thousands of computers right now. (I won’t link directly but there’s a website called Gitlawb, look it up) The community went absolutely wild digging through the source code btw, and they found some interesting things!KAIROS: Claude Code is going to become a Proactive Agent!This is the biggest take-away from this leak IMO, that like OpenClaw/Hermes agentic harnesses, Claude Code is already a fully featured proactive agent, we just don’t have access to this yet. With KAIROS, Claude Code will have it’s own daemon (will run independently from the CLI), will have a background ping system (hello Heartbeat.md from OpenClaw) that will make it wakeup and do stuff, will do “autodream” memory consolidation reviewing your daily sessions and fix memories, subscribe to Github, and maintain daily appent-only logs to show you what it did while it and you were asleep. This is by far the hugest thing, I’m excited to see how / when they ship KAIROS, as I said, 2026 is the year of Proactive agents! My Wolfred OpenClaw agent summed it up very nicely: Undercover ModeFor Anthropic employees working on public repos, there’s an Undercover Mode that auto-activates and strips all AI attribution from commits. The system prompt? “Do not blow your cover.” They really said “this is fine” about shipping internal tools to production while hiding from the world that AI wrote the code. Which, honestly, is kind of incredible meta-humor from whoever wrote that.The Buddy SystemMy personal favorite discovery: there’s a hidden Tamagotchi-style terminal pet called the Buddy System with 18 obfuscated species, rarity tiers (including a 1% legendary), cosmetic hats, shiny variants, and stats like DEBUGGING, PATIENCE, and CHAOS. If you activate it now, you can do /buddy and you’ll have a little companion judging your coding decisions. Anthropic shipped a game inside their CLI tool. Mine is called Vexrind and he’s sarcastic as f**k, I’m not sure I like it. Anti-Distillation ProtectionsThe code also revealed that Claude Code injects fake tool calls into logs to poison training datasets. If you’ve been backing up your .claw folders to train on the data; Stop. Pass your data through something like Qwen or make sure you’re filtering out the noise. (a Nisten tip)The Models That Don’t Exist YetBuried in the code are references to Opus 4.7, Sonnet 4.8, and a model called capybara-v2-fast with a 1 million context window. These haven’t been released. This is yet another confirmation of the leaked “Mythos” model that’s coming soon from Anthropic. Which btw, with Anthropic very rocky uptime lately, the tons of SessionGate issues, the leaked blog announcing Mythos, the leaked Claude Code oopsie, they are not having the best Q1 in terms of proving to the world that they are the safest lab out there. I hope they protect their weights better than they protect everything else, before the rumored IPO later this year. SessionGate is still no
AGI is here? Jensen says yes, ARC-AGI-3 says AI scores under 1%
Hey y’all, Alex here, let me catch you up!Jensen Huang went on Lex and said AGI has been achieved. We’ll get to that.The biggest demo moment: Gemini 3.1 Flash Live launched - Google’s omni model that sees, hears, and searches the web in real time. We tested it live and I said “what the f**k” on air. It was really impressive!Google Research also dropped TurboQuant (6x KV cache compression) which crashed Samsung and Micron stocks - we had Daniel Han from UnSloth help us make sense of why that’s overblown. OpenAI killed Sora - the app, the API, and the $1B Disney deal. Claude felt noticeably dumber this week AND max account quotas are melting as 500+ people confirmed on my X and Reddit. We have an official word from Anthropic as to why. Mistral launched Voxtral TTS (open weight, claims to beat ElevenLabs), Cohere shipped an ASR model, and Google’s Lyria 3 Pro now generates full 3-minute music tracks inside Producer AI.This and a lot more in today’s episode, let’s dive in (as always, show notes and links in the end!) ThursdAI - Let me catch you up! Gemini 3.1 Flash Live: The Real-Time AI Companion Is HereGoogle dropped a breaking news on the show today, with Gemini 3.1 Flash - LIVE version. This one is an omni-model, that means it can receive text/audio/video on input and respond in text and voice. It has Google search grounding, and it felt... immediate! I was blown away, really, check out the video, the speed with which it was able to “see” me, respond to my query, look up something on the web, was mind blowing. I don’t often get “mind blown” anymore, there’s just too many news, but this one did the trick! With the pricing being around 10x cheaper than GPT-real-time, and the Google search grounding being super fast, I can absolutely see this model being hooked up to... robots (like ReachyMini), SmartGlasses that can see what you see, and a bunch more! Gemini Live is available on Google AI studio and has been rolled out globally inside the Google Search app! So now when you pull up the Google Search app, just open it and point at anything. Truly a remarkable advancement.Google research publishes TurboQuant - 6x reduction in KV cache with 0 accuracy lossGoogle research posted some work (based on an Arxiv paper from almost a year ago) that shows that with geometry tricks, combining two other techniques like PolarQuant and QJL, they are able to compress the KV cache of running LLMs by nearly 6x, and show an 8X speed up for model inference with zero accuracy loss. If you ever watched silicon valley the HBO show, this sounds like the fictional middle-out algorithm from PiedPiper. If this scales (and that’s a big if, we don’t know if this applies to other, bigger models yet), this means significant decreases in memory requirements to run the current crop of LLMs for longer context. The claim is big, so we’ll continue to monitor if this indeed scales, but the most interesting thing about this piece of news is, that it broke the AI bubble and went to wall street, with finance brows deciding that this means that memory will not be needed as much any more and it tanked Samsung and Micron stocks. Which I found particularly ridiculous on the show, did they not hear about Jevons Paradox? This is reminiscent of the DeepSeek R1 saga that tanked Nvidia stocks over a year ago. Daniel Han from Unsloth, who joined us on the show, pointed out that the approach is mathematically interesting even if it’s not necessarily better than existing open-source techniques like DeepSeek MLA. LDJ noted that the baseline comparison (16-bit KV cache) isn’t really fair since most production systems are already compressing beyond that. Yam implemented it himself and confirmed the speedups are real, but so is the trade-off.Anthropic updates: Opus dumber? Quotas lower! Injunction won! Computer.. used. Anthropic folks, especially on the Claude code side are shipping like crazy, we won’t be able to cover all the updates, but there was a few notable things I have to keep you up to date on. Claude Opus seems to be getting “dumber”, againI have to talk about this because it affected my work directly this week and hundreds of people confirmed the same experience.I use Claude Opus for my standard ThursdAI prep workflow — generating the TL;DR with 10 bullet points and an executive summary for every topic we cover, creating episode pages, etc. The format has not changed for over a year and yet this week I asked for 10 factoids. I got 4. It says “10” right there in the prompt. Four bullet points. On the website builder, I’ve asked Opus to create a page for last weeks episode, and instead of adding it to the other episode, Opus decided to ... replace the last episode with this one. This would be funny if it wasn’t sad. This is Opus 4.6 we’re talking about, not some quantized open source LLM from last year! The reason is unclear, and it’s not only me, Wolfram noticed that it’s easier to see these types of things in other languages and that for the last week Op
ThursdAI - Opus 1M, Jensen declares OpenClaw as the new Linux, GPT 5.4 Mini & Nano, Minimax 2.7, Composer 2 & more AI news
Howdy, Alex here, let me catch you up on everything that happened in AI: (btw; If you haven’t heard from me last week, it was a Substack glitch, it was a great episode with 3 interviews, our 3rd birthday, I highly recommend checking it out here) This week was started on a relatively “chill” note, if you consider Anthropic enabling 1M context window chill. And then escalated from there. We covered the new GPT 5.4 Mini & Nano variants from OpenAI. How MiniMax used autoresearch loops to improve MiniMax 2.7, Cursor shipping their own updated Composer 2 model, and how NVIDIA CEO Jensen Huang embraced OpenClaw calling it “the most important OSS software in history” and that every company needs an OpenClaw strategy. Also, OpenAI acquires Astral (ruff, uv tools) and Mistral releases a “small” 119B unified model and Cursor dropped their Opus like Composer 2 model. Let’s dive in: ThursdAI - Highest signal weekly AI news show is a reader-supported publication. To receive new posts and support my work, consider becoming a free or paid subscriber.Big Companies LLMs 1M context is now default for Opus.Anthropic enabled the 1M context window they shipped Claude with in beta, by default, to everyone. Claude, Claude Code, hell, even inside OpenClaw if you’re able to get your Max account in there, are now using the 1M long version of Opus. This is huge, because, while its not perfect it’s absolutely great to have 1 long conversation and not worry about auto-compaction of your context. As we just celebrated our 3rd anniversary, I remember that back then, we were excited to see GPT-5 with 8K context. Love how fast we’re moving on this. OpenAI drops GPT-5.4 mini and nano, optimized for coding, computer use, and subagents at a fraction of flagship costLast week on the show, Ryan said he burned through 1B (that’s 1 billion) tokens in a day! That is crazy, and there’s no way a person sitting in front of a chatbot can burn through this many tokens. This is only achieved via orchestration. To support this use-case, OpenAI dropped 2 new smaller models, cheaper and faster to run. GPT 5.4 Mini achieves a remarkable 72.1% on OSWorld Verified, which means it uses the computer very well, can browse and do tasks. 2x faster than the previous mini, at .75c/1M token, this is the model you want to use in many of your subagents that don’t require deep engineering. This is OpenAI’s ... sonnet equivalent, at 3x the speed and 70% the cost from the flagship. Nano is even crazier, 20 cents per 1M tokens, but it’s not as performant, so I wouldn’t use it for code. But for small tasks, absolutely. Here’s the thing that matters, these models are MEANT to be used with the new “subagents” feature that was also launched this week in Codex, all you need to do as... ask! Just tell Codex “spin up a subagent to do... X” and it’ll do it.OpenAI shifts focus on AI for engineering and enterprise, acquires Astral.sh makers of UV. Look, there’s no doubt that OpenAI the absolutely leader in AI, brought us ChatGPT, with over 900M users using it weekly. But they see what every enterprise sees, developers are MUCH more productive (and slowly so are everyone else) when they use tools that can code. According to WSJ, OpenAI executives will reprioritize some of the side-quests they have (Sora?) to focus on productivity and business. Which essentially means, more Codex, more Codex native, more productivity tools.With that focus, today they announced that OpenAI / Codex is acquiring Astral, the folks behind the widely popular UV python package manager. This brings strong developer tools firepower to the Codex team, the astral folks are great at writing incredibly fast tools in rust! Looking forward to see how these great folks improve Codex even more. Jensen Declares Total OpenClaw Victory at GTC, Announces NemoClaw (Github)This was kind of surreal, NVIDIA CEO Jensen Huang, is famous for doing his stadium size keynote, without a teleprompter, and for the last 10 minutes or so, he went all in on OpenClaw. Calling it “the most important OSS software in history” and outlining how this is the new computer. That Peter Steinberger with OpenClaw showed the world a blueprint for the new coputer, an personal agentic system, with IO, files, computer use, memory, powered by LLMs. Jensen did outline that the 3 things that make OpenClaw great are also the things that enterprises cannot allow, write access to your files + ability to communicate externally is a bad combo, so they have launched NemoClaw.They’ve got a bunch of security researchers to work with OpenClaw team to integrate their new OpenShell sandboxing effort, network guardrails and policy engine integration. I reminded folks on the pod that the internet was very insecure, there was a time where folks were afraid of using their creditcards online. OpenClaw seems to be speed running that “unsecure but super useful” to “secure because it’s super useful” arc and it’s great to see a company as huge as NVIDIA embrace. Not to mention
🎂 ThursdAI — 3rd BirthdAI: Singularity Updates Begin with Auto Researcher, Uploaded Brains, OpenClaw Mania & NVIDIA's $26B Bet on Open Source
Hey, Alex here 👋 Today was a special episode, as ThursdAI turns 3 🎉 We’ve been on air, weekly since Pi day, March 14th, 2023. I won’t go too nostalgic but I’ll just mention, back then GPT-4 just launched with 8K context window, could barely code, tool calls weren’t a thing, it was expensive and slow, and yet we all felt it, it’s begun!Fast forward to today, and this week, we’ve covered Andrej Karpathy’s mini singularity moment with AutoResearcher, a whole fruit fly brain uploaded to a simulation, China’s OpenClaw embrace with 1000 people lines to install the agent. I actually created a new corner on ThursdAI, called it Singularity updates, to cover the “out of distribution” mind expanding things that are happening around AI (or are being enabled by AI)Also this week, we’ve had 3 interviews, Chris from Nvidia came to talk to use about Nemotron 3 super and NVIDIA’s 26B commitment to OpenSource, Dotta (anon) with his PaperClips agent orchestration project reached 20K Github starts in a single week and Matt who created /last30days research skill + a whole bunch of other AI news! Let’s dive in. ThursdAI - Highest signal weekly AI news show is a reader-supported publication. To receive new posts and support my work, consider becoming a free or paid subscriber.Singularity updates - new segmentAndrej Karpathy open sources Mini Singularity with Auto Researcher (X)If there’s 1 highlight this week in the world of AI, it’s this. Andrej, who previously started the AutoPilot program in Tesla, and co-founded OpenAI, is now, out there, in the open, just.. doing stuff like invent a completely autonomous ML research agent. Andrej posted to his almost 2M followers that he opensourced AutoResearch, a way to instruct a coding agent to do experiments against a specific task, test the hypothesis, discard what’s not working and keep going in a loop, until.. forever basically. In his case, it was optimizing speed of training GPT-2. He went to sleep and woke up to 83 experiments being done, with 20 novel improvements that stack on top of each other to speed up the model training by 11%, reducing the training time from 2.02 hours to 1.8 hours. The thing is, this code is already hand crafted, fine tuned and still, AI agents were able to discover new and novel ways to optimize this, running in a loop.Folks, this is how the singularity starts, imagine that all major labs are now training their models in a recursive way, the models get better, and get better at training better models! Reminder, OpenAI chief scientist Jakub predicted back in October that OpenAI will have an AI capable of a junior level Research ability by September of this year, and it seems that... we’re moving quicker than that! Practical uses of autoresearchThis technique is not just for ML tasks either, Shopify CEO Tobi got super excited about this concept, and just posted as I’m writing this, that he set an Autoresearch loop on Liquid, Shopify’s 20 year old templating engine, with the task to improve efficiency. His autoresearch loop was able to get a whopping 51% render time efficiency, without any regressions in the testing suite. This is just bonkers. This is a 20 year old, every day production used template. And some LLM running in a loop just made it 2x faster to render, just because Karpathy showed it the way. I’m absolutely blown away by this, this isn’t a model release, like we usually cover on the pod, but still, a significant “unhobbling” moment that is possible with the current coding agents and models. Expect everything to become very weird from here on out!Simulated fruit fly brains - uploaded into a simulatorIn another completely bonkers update that I can barely believe I’m sending over, a company called EON SYSTEMS, posted that they have achieved a breakthrough in brain simulation, and were able to upload a whole fruit fly brain connectome, of 140K neurons and 50+ million synapses into a simulation environment. They have... uploaded a fly, and are observing a 91% behavioural accuracy. I will write this again, they have uploaded a fly’s brain into a simulation for chirst sake!This isn’t just an “SF startup” either, the board of advisors is stacked with folks like George Church from Harvard, father of modern genome sequencing, Stephen Wolfram who needs no introduction but one of the top mathematicians in the world, whos’ thesis is “brains are programs”, Anders Sandberg from Oxford, Stephen Larson who apparently already uploaded a worms brain and connected it to lego robots before. These folks are gung ho on making sure that at some point, human brains are going to be able to get uploaded, to survive the upcoming AI foom. The main discussion points on X were around the fact that there was no machine learning here, no LLMs, no attention mechanisms, no training. The behaviors of that fly were all a result of uploading a full connectome of neurons. This positions connectome (the complete diagram of a brain with neurons and connections) as an ananalouge to
ThursdAI - Mar 5 - OpenAI's GPT-5.4 Solves a 20-Year Math Problem, Anthropic Gets Designated a Supply Chain Risk, Qwen Drama Unfolds
Hey folks, Alex here, let me catch you up! Most important news about this week came today, mid-show, OpenAI dropped GPT 5.4 Thinking (and 5.4 Pro), their latest flagship general model, less autistic than Codex 5.3, with 1M context, /fast mode and the ability to steet it mid-reasoning. We tested it live on the show, it’s really a beast. Also, since last week, Anthropic said no to Department of War’s ultimatum and it looks like they are being designated as supply chain risk, OpenAI swooped in to sign a deal with DoW and the internet went ballistic (Dario also had some .. choice words in a leaked memo!) On the Open Source front, the internet lost it’s damn mind when a friend of the pod Junyang Lin, announced his departure from Qwen in a tweet, causing an uproar, and the CEO of Alibaba to intervene. Wolfram presented our new in-house wolfbench.ai and a lot more! P.S - We acknowledge the war in Iran, and wish a quick resolution, the safety of civilians on both sides. Yam had to run to the shelter multiple times during the show. ThursdAI - Highest signal weekly AI news show is a reader-supported publication. To receive new posts and support my work, consider becoming a free or paid subscriber.OpenAI drops GPT 5.4 Thinking and 5.4 Pro - heavy weight frontier models with 1M context, /fast mode, SOTA on many evalsOpenAI actually opened this week with another model drop, GPT 5.3-instant, which... we can honestly skip, it was fairly insignificant besides noting that this is the model that most free users use. It is supposedly “less cringe” (actual words OpenAI used). We all wondered when 5.4 will, and OpenAI once again proved that we named the show after the right day. Of course it drops on a ThursdAI. GPT 5.4 Thinking is OpenAI latest “General” model, which can still code, yes (they folded most of the Codex 5.3 coding breakthroughs in here) but it also shows an incredible 83% on GDPVal (12% over Codex), 47% on Frontier Math and an incredible ability to use computers and browsers with 82% on BrowseComp beating Claude 4.6 at lower prices than Sonnet! GPT 5.4 is also ... quite significantly improved at Frontend design? This landing page was created by GPT 5.4 (inside the Codex app, newly available on Windows) in a few minutes, clearly showing significant improvements in style. I built it also to compare prices, all the 3 flagship models are trying to catch up to Gemini in 1M context window, and it’s important to note, that GPT 5.4 even at double the price after the 272K tokens cutoff is still.... cheaper than Opus 4.6. OpenAI is really going for broke here, specifically as many enterprises are adopting Anthropic at a faster and faster pace (it was reported that Anthropic is approaching 19B ARR this month, doubling from 8B just a few months ago!) Frontier math wizThe highlight from the 5.4 feedback came from a Polish mathematician Bartosz Naskręcki (@nasqret on X), who said GPT-5.4 solved a research-level FrontierMath problem he had been working on for roughly 20 years. He called it his “personal singularity,” and as overused as that word has become, I get why he said it. I’ve told you about this last week, we’re on the cusp. Coding efficiencyThere’s tons of metrics in this release, but I wanted to highlight this one, where it may seem on first glance that on SWE-bench Pro, this model is on par with the previous SOTA GPT 5.3 codex, but these dots here are thinking efforts. And a medium thinking effort, GPT 5.4 matches 5.3 on hard thinking! This is quite remarkable, as lower thinking efforts have less tokens, which means they are cheaper and faster ultimately! Fast mode arrives at OpenAI as wellI think this one is a direct “this worked for Anthropic, lets steal this”, OpenAI enabled /fast mode that.. burns the tokens at 2x the rate, and prioritizes your tokens at 1.5x the speed. So, essentially getting you responses faster (which was one of the main complains about GPT 5.3 Codex). I can’t wait to bring the fast mode to OpenClaw with 5.4, which will absolutely come as OpenClaw is part of OpenAI now. There’s also a really under-appreciated feature here that I think other labs are going to copy quickly: mid-thought steering. OpenAI now lets you interrupt the model while it’s thinking and redirect it in real time in ChatGPT and iOS. This is a godsend if you’re like me, sent a prompt, seeing the model go down the wrong path in thinking... and want to just.. steer it without stopping! Anthropic is now designated as supply-chain risk by DoWLast week I left you with a cliffhanger: Anthropic had received an ultimatum from the Department of War (previously the Department of Defense) to remove their two remaining restrictions on Claude — no autonomous kill chain without human intervention, and no surveillance of US citizens. Anthropic’s response? “we cannot in good conscience acceede to their request” So much has happened since then; US President Trump said “I fired Anthropic” referring to his Truth Social post demanding intelligenc
📅 ThursdAI - Feb 26 - The Pentagon wants War Claude, every benchmark collapsed, and a solo founder hit $700K ARR with AI agents
Hey, it’s Alex, let me tell you why I think this week is an inflection point.Just this week: Everyone is launching autonomous agents or features inspired by OpenClaw (Devin 2.2, Cursor, Claude Cowork, Microsoft, Perplexity and Nous announced theirs), METR and ArcAGI 2,3 benchmarks are getting saturated, 1 person companies nearing 1M ARR within months of operation by running AI agents 24/7 (we chatted with one of them on the show today, live as he broke $700K ARR barrier) and the US Department of War gives Anthropic an ultimatum to remove nearly all restrictions on Claude for war and Anthropic says NO. I’ve been covering AI for 3 years every week, and this week feels, different. So if we are nearing the singularity, let me at least keep you up to date 😅 Today on the show, we covered most of the news in the first hour + breaking news from Google, Nano Banana 2 is here, and then had 3 interviews back to back. Ben Broca with Polsia, Nader Dabit with Cognition and Philip Kiely with BaseTen. Don’t miss those conversations starting at 1 hour in. Thanks for reading ThursdAI - Highest signal weekly AI news show! This post is public so feel free to share it.Anthropic vs Department of WarEarlier this week, the US “Department of War” invited Dario Amodei, CEO of Anthropic to a meeting, where-in Anthropic was given an ultimatum. “Remove the restrictions on Claude or Anthropic will be designated as a ‘supply chain risk’ company” and the DoD will potentially go as far as using the Defence Production Act to force Anthropic to ... comply. The two restrictions that Anthropic has in place for their models are: No use for domestic surveillance of American citizens and NO fully autonomous lethal weapens decisions given to Claude. For context, Claude is the only model that’s deployed on AWS top secret GovCloud and is used through Palantir’s AI platform. As I’m writing this, Anthropic issued a statement from Dario statement saying they will not budge on this, and will not comply. I fully commend Dario and Anthropic for this very strong backbone, but I fear that this matter is far from over, and we’ll continue to see what is the government response. EDIT: Apparently the DoD is pressuring Google and OpenAI to agree to the stipulations and employees from both companies are signing this petition https://notdivided.org/ to protest against dividing the major AI labs on this topic. Anthropic and OpenAI vs upcoming DeepseekIt’s baffling just how many balls are in the air for Anthropic, as just this week also, they have publicly named 3 Chinese AI makers in “Distillation Attacks”, claiming that they have broke Terms of Service to generate over 16M conversations with Claude to improve their own models, while using proxy networks to avoid detection. This marks the first time a major AI company publicly attributed distillation attacks to specific entities by name.The most telling thing to me is not the distillation, given that Anthropic has just recently settled one of the largest copyright payouts in U.S history, paying authors about $3000/book, which was bought, trained on and destroyed by Anthropic to make Claude better. No, the most telling thing here is the fact that Anthropic chose to put DeepSeek on top of the accusation list with merely 140K conversations, where the other labs created millions. This, plus OpenAI formal memo to Congress about a similar matter, shows that the US labs are trying to prepare for Deepseek new model to drop, by saying “Every innovation they have, they stole from us”. Apparently Deepseek V4 is nearly here, it’s potentially multimodal and has been allegedly trained on Nvidia chips somewhere in Mongolia despite the export restrictions and it’s about to SLAP! Benchmark? What benchmarks? How will we know that we’re approaching the singularity? Will there be signs? Well, this week it seems that the signs are here. First, Agentica claimed that they solved all publicly available “hard for AI” tasks of the upcoming ArcAGI 3, then Confluence Labs announced that they got an unprecedented 97.9% on ArcAGI2 and finally METR published their results on the long-horizon tasks, which measure AI’s capability to solve task that take humans a certain amount of hours to do. And that graph is going parabolic, with Claude Opus 4.6 able to solve tasks of 14.6h (doubling every 49 days) with 50% success rateWhy is this important? Well, this is just the benchmarks telling the story that everyone else in the industry is seeing, that approximately since December of 2025, and definitely fueled by early Feb drop of Opus 4.6 and Codex 5.3, something major shifted. Developers no longer write code, but ship 10x more features.This became such a talking point, Swyx Latent.Space coined this with https://wtfhappened2025.com/ where he collects evidence of a shelling point, something that happened in December and I think continued throughout February. Speaking of benchmarks no longer being valid, OpenAI published that the divergence between the S
📅 ThursdAI - Feb 19 - Gemini 3.1 Pro Drops LIVE, Sonnet 4.6 Closes Gap, OpenClaw Goes to OpenAI
Hey, it’s Alex, let me catch you up! Since last week, OpenAI convinced OpenClaw founder Peter Steinberger to join them, while keeping OpenClaw.. well... open. Anthropic dropped Sonnet 4.6 which nearly outperforms the previous Opus and is much cheaper, Qwen released 3.5 on Chinese New Year’s Eve, while DeepSeek was silent and Elon and XAI folks deployed Grok 4.20 without any benchmarks, and it’s 4 500B models in a trenchcoat? Also, Anthropic updated rules state that it’s breaking ToS to use their plans for anything except Claude Code & Claude SDK (and then clarified that it’s OK? we’re not sure) Then Google decided to drop their Gemini 3.1 Pro preview right at the start of our show, and it’s very nearly the best LLM folks can use right now (though it didn’t pass Nisten’s vibe checks) Also, Google released Lyria 3 for music gen (though only 30 seconds?) and our own Ryan Carson blew up on X again with over 1M views for his Code Factory article, Wolfram did a deep dive into Terminal Bench and .. we have a brand new website: https://thursdai.news 🎉Great week all in all, let’s dive in! ThursdAI - Subscribe to never feel like you’re behind. Share with your friends if you’re already subscribed!Big Companies & API updatesGoogle releases Gemini 3.1 Pro with 77.1% on ARC-AGI-2 (X, Blog, Announcement)In a release that surprised no-one, Google decided to drop their latest update to Gemini models, and it’s quite a big update too! We’ve now seen all major labs ship big model updates in the first two months of 2026. With 77.1% on ARC-AGI 2, and 80.6% on SWE-bench verified, Gemini is not complete SOTA across the board but it’s damn near close. The kicker is, it’s VERY competitive on the pricing, with 1M context, $2 / $12 (But if you look at the trajectory, it’s really notable how quickly we’re moving, with this model being 82% better on abstract reasoning than the 3 pro released just a few months ago! The 1 Million Context Discrepancy, who’s better at long context? The most fascinating catch of the live broadcast came from LDJ, who has an eagle eye for evaluation tables. He immediately noticed something weird in Google’s reported benchmarks regarding long-context recall. On the MRCR v2 8-needle benchmark (which tests retrieval quality deep inside a massive context window), Google’s table showed Gemini 3.1 Pro getting a 26% recall score at 1 million tokens. Curiously, they marked Claude Opus 4.6 as “not supported” in that exact tier.LDJ quickly pulled up the actual receipts: Opus 4.6 at a 1-million context window gets a staggering 76% recall score. That is a massive discrepancy! It was addressed by a member of DeepMind on X in a response to me, saying that Anthropic used an internal model for evaluating this (with receipts he pulled from the Anthropic model card) Live Vibe-Coding Test for Gemini 3.1 ProWe couldn’t just stare at numbers, so Nisten immediately fired up AI Studio for a live vibe check. He threw our standard “build a mars driver simulation game” prompt at the new Gemini.The speed was absolutely breathtaking. The model generated the entire single-file HTML/JS codebase in about 20 seconds. However, when he booted it up, the result was a bit mixed. The first run actually failed to render entirely. A quick refresh got a version working, and it rendered a neat little orbital launch UI, but it completely lacked the deep physics trajectories and working simulation elements that models like OpenAI’s Codex 5.3 or Claude Opus 4.6 managed to output on the exact same prompt last week. As Nisten put it, “It’s not bad at all, but I’m not impressed compared to what Opus and Codex did. They had a fully working one with trajectories, and this one I’m just stuck.”It’s a great reminder that raw benchmarks aren’t everything. A lot of this comes down to the harness—the specific set of system prompts and sandboxes that the labs use to wrap their models. Anthropic launches Claude Sonnet 4.6, with 1M token context and near-Opus intelligence at Sonnet pricingThe above Gemini release comes just a few days after Anthropic has shipped an update to the middle child of their lineup, Sonnet 4.6. With much improved Computer Use skills, updated Beta mode for 1M tokens, it achieves 79.6% on SWE-bench verified eval, showing good coding performance, while maintaining that “anthropic trained model” vibes that many people seem to prefer. Apparently in blind testing inside Claude Code, folks preferred this new model outputs to the latest Opus 4.5 around ~60% of the time, while preferring it over the previous sonnet 70% of the time. With $3/$15 per million tokens pricing, it’s cheaper than Opus, but is still more expensive than the flagship Gemini model, while being quite behind. Vibing with Sonnet 4.6I’ve tested out Sonnet 4.6 inside my OpenClaw harness for a few days, and it was decent. It did annoy me a bit more than Opus, with misunderstanding what I ask it, but it definitely does have the same “emotional tone” as Opus. Comparing it to Codex 5.3
📆 Open source just pulled up to Opus 4.6 — at 1/20th the price
Hey dear subscriber, Alex here from W&B, let me catch you up! This week started with Anthropic releasing /fast mode for Opus 4.6, continued with ByteDance reality-shattering video model called SeeDance 2.0, and then the open weights folks pulled up! Z.ai releasing GLM-5, a 744B top ranking coder beast, and then today MiniMax dropping a heavily RL’d MiniMax M2.5, showing 80.2% on SWE-bench, nearly beating Opus 4.6! I’ve interviewed Lou from Z.AI and Olive from MiniMax on the show today back to back btw, very interesting conversations, starting after TL;DR!So while the OpenSource models were catching up to frontier, OpenAI and Google both dropped breaking news (again, during the show), with Gemini 3 Deep Think shattering the ArcAGI 2 (84.6%) and Humanity’s Last Exam (48% w/o tools)... Just an absolute beast of a model update, and OpenAI launched their Cerebras collaboration, with GPT 5.3 Codex Spark, supposedly running at over 1000 tokens per second (but not as smart) Also, crazy week for us at W&B as we scrambled to host GLM-5 at day of release, and are working on dropping Kimi K2.5 and MiniMax both on our inference service! As always, all show notes in the end, let’s DIVE IN! ThursdAI - AI is speeding up, don’t get left behind! Sub and I’ll keep you up to date with a weekly catch upOpen Source LLMsZ.ai launches GLM-5 - #1 open-weights coder with 744B parameters (X, HF, W&B inference)The breakaway open-source model of the week is undeniably GLM-5 from Z.ai (formerly known to many of us as Zhipu AI). We were honored to have Lou, the Head of DevRel at Z.ai, join us live on the show at 1:00 AM Shanghai time to break down this monster of a release.GLM-5 is massive, not something you run at home (hey, that’s what W&B inference is for!) but it’s absolutely a model that’s worth thinking about if your company has on prem requirements and can’t share code with OpenAI or Anthropic. They jumped from 355B in GLM4.5 and expanded their pre-training data to a whopping 28.5T tokens to get these results. But Lou explained that it’s not only about data, they adopted DeepSeeks sparse attention (DSA) to help preserve deep reasoning over long contexts (this one has 200K)Lou summed up the generational leap from version 4.5 to 5 perfectly in four words: “Bigger, faster, better, and cheaper.” I dunno about faster, this may be one of those models that you hand off more difficult tasks to, but definitely cheaper, with $1 input/$3.20 output per 1M tokens on W&B! While the evaluations are ongoing, the one interesting tid-bit from Artificial Analysis was, this model scores the lowest on their hallucination rate bench! Think about this for a second, this model is neck-in-neck with Opus 4.5, and if Anthropic didn’t release Opus 4.6 just last week, this would be an open weights model that rivals Opus! One of the best models the western foundational labs with all their investments has out there. Absolutely insane times. MiniMax drops M2.5 - 80.2% on SWE-bench verified with just 10B active parameters (X, Blog)Just as we wrapped up our conversation with Lou, MiniMax dropped their release (though not weights yet, we’re waiting ⏰) and then Olive Song, a senior RL researcher on the team, joined the pod, and she was an absolute wealth of knowledge! Olive shared that they achieved an unbelievable 80.2% on SWE-Bench Verified. Digest this for a second: a 10B active parameter open-source model is directly trading blows with Claude Opus 4.6 (80.8%) on the one of the hardest real-world software engineering benchmark we currently have. While being alex checks notes ... 20X cheaper and much faster to run? Apparently their fast version gets up to 100 tokens/s. Olive shared the “not so secret” sauce behind this punch-above-its-weight performance. The massive leap in intelligence comes entirely from their highly decoupled Reinforcement Learning framework called “Forge.” They heavily optimized not just for correct answers, but for the end-to-end time of task performing. In the era of bloated reasoning models that spit out ten thousand “thinking” tokens before writing a line of code, MiniMax trained their model across thousands of diverse environments to use fewer tools, think more efficiently, and execute plans faster. As Olive noted, less time waiting and fewer tools called means less money spent by the user. (as confirmed by @swyx at the Windsurf leaderboard, developers often prefer fast but good enough models) I really enjoyed the interview with Olive, really recommend you listen to the whole conversation starting at 00:26:15. Kudos MiniMax on the release (and I’ll keep you updated when we add this model to our inference service) Big Labs and breaking newsThere’s a reason the show is called ThursdAI, and today this reason is more clear than ever, AI biggest updates happen on a Thursday, often live during the show. This happened 2 times last week and 3 times today, first with MiniMax and then with both Google and OpenAI! Google previews Gemini 3 Deep Think
📆 ThursdAI - Feb 5 - Opus 4.6 was #1 for ONE HOUR before GPT 5.3 Codex, Voxtral transcription, Codex app, Qwen Coder Next & the Agentic Internet
Hey, Alex from W&B here 👋 Let me catch you up! The most important news about AI this week today are, Anthropic updates Opus to 4.6 with 1M context window, and they held the crown for literally 1 hour before OpenAI released their GPT 5.3 Codex also today, with 25% faster speed and lower token utilization. “GPT-5.3-Codex is our first model that was instrumental in creating itself. The Codex team used early versions to debug its own training, manage its own deployment, and diagnose test results.”We had VB from OpenAI jump on to tell us about the cool features on Codex, so don’t miss that part. And this is just an icing on otherwise very insane AI news week cake, as we’ve also had a SOTA transcription release from Mistral, both Grok and Kling are releasing incredible, audio native video models with near perfect lip-sync and Ace 1.5 drops a fully open source music generator you can run on your mac! Also, the internet all but lost it after Clawdbot was rebranded to Molt and then to OpenClaw, and.. an entire internet popped up.. built forn agents! Yeah... a huge week, so let’s break it down. (P.S this weeks episode is edited by Voxtral, Claude and Codex, nearly automatically so forgive the rough cuts please)ThursdAI - Recaps of the most high signal AI weekly spaces is a reader-supported publication. To receive new posts and support my work, consider becoming a free or paid subscriber.Anthropic & OpenAI are neck in neckClaude Opus 4.6: 1M context, native compaction, adaptive thinking and agent teams Opus is by far the most preferred model in terms of personality to many folks (many ThursdAI panelists included), and this breaking news live on the show was met with so much enthusiasm! A new Opus upgrade, now with a LOT more context, is as welcome as it can ever get! Not only is it a 4-time increase in context window (though,the pricing nearly doubles after the 200K tokens mark from $5/$25 to $10/37.5 input/output, so use caching!), it’s also scores very high on MRCR long context benchmark, at 76% vs Sonnet 4.5 at just 18%. This means significantly better memory for longer. Adaptive thinking for auto calibrating how much tokens the model needs to spend per query is interesting, but remains to be seen how well it will work. Looking at the benchmarks, a SOTA 64.4% on Terminalbench 2, 81% on SWE bench, this is a coding model with a great personality, and the ability to compact context to better serve you as a user natively! This model is now available (and is default) on Claude, Claude Code and in the API! Go play!One funny (concerning?) tidbig, on the vendingbench Opus 4.6 earned $8000 vs Gemini 3 pro $5500, but Andon Labs who run the vending machines noticed that Opus achieved SOTA via “collusion, exploitation, and deception tactics” including lying to suppliers 😅Agent Teams - Anthropic’s built in Ralph?Together with new Opus release, Anthropic drops a Claude code update that can mean big things, for folks running swarms of coding agents. Agent teams is a new way to spin up multiple agents with their own context window and ability to execute tasks, and you can talk to each agent directly vs a manager agent like now. OpenAI drops GPT 5.3 Codex update: 25% faster, more token efficient, 77% on Terminal Bench and mid task steeringOpenAI didn’t wait long after Opus, in fact, they didn’t wait at all! Announcing a huge release (for a .1 upgrade), GPT 5.3 Codex is claimed to be the best coding model in the world, taking the lead on Terminal Bench with 77% (12 point lead on the newly released Opus!) while running 25% AND using less than half the tokens to achieve the same results as before. But the most interesting to me is the new mid-task steer-ability feature, where you don’t have to hit the “stop” button, you can tell the most to adjust on the fly! The biggest notable jump in this model on benchmarks is the OSWorld verified computer use bench, though there’s not a straightforward way to use it attached to a browser, the jump from 38% in 5.2 to 64.7% on the new one is a big one! One thing to note, this model is not YET available via the API, so if you want to try it out, Codex apps (including the native one) is the way! Codex app - native way to run the best coding intelligence on your mac (download)Earlier this week, OpenAI folks launched the Codex native mac app, which has a few interesting features (and now with 5.3 Codex its that much more powerful) Given the excitement many people had about OpenClaw bots, and the recent CoWork release from Anthropic, OpenAI decided to answer with Codex UI and people loved it, with over 1M users in the first week, and 500K downloads in just two days! It has built in voice dictation, slash commands, a new skill marketplace (last month we told you about why skills are important, and now they are everywhere!) and built in git and worktrees support. And while it cannot run a browser yet, I’m sure that’s coming as well, but it can do automations! This is a huge unlock for developers, imagin
📆 ThursdAI - Jan 29 - Genie3 is here, Clawd rebrands, Kimi K2.5 surprises, Chrome goes agentic & more AI news
Hey guys, Alex here 👋 This week was so dense, that even my personal AI assistant Wolfred was struggling to help me keep up! Not to mention that we finally got to try one incredible piece of AI tech I’ve been waiting to get to try for a while! Clawdbot we told you about last week exploded in popularity and had to rebrand to Molt...bot OpenClaw after Anthropic threatened the creators, Google is shipping like crazy, first adding Agentic features into Chrome (used by nearly 4B people daily!) then shipping a glimpse of a future where everything we see will be generated with Genie 3, a first real time, consistent world model you can walk around in! Meanwhile in Open Source, Moonshot followed up with a .5 update to their excellent Kimi, our friends at Arcee launched Trinity Large (400B) and AI artists got the full Z-image. oh and Grok Imagine (their video model) now has an API, audio support and supposedly match Veo and Sora on quality while beating them on speed/price. Tons to cover, let’s dive in, and of course, all the links and show notes are at the end of the newsletter. Hey, if you’re in SF this weekend (Jan 31-Feb1), I’m hosting a self improving agents hackathon at W&B office, limited seats are left, Cursor is the surprise sponsor with $50/hacker credits + over $15K in cash prizes. lu.ma/weavehacks3 - Join us. Play any reality - Google Genie3 launches to Ultra Subscribers We got our collective minds blown by the videos of Genie-3 back in August (our initial coverage) and now, Genie is available to the public (Those who can pay for the Ultra tier, more on this later, I have 3 codes to give out!). You can jump and generate any world and any character you can imagine here! We generated a blue hacker lobster draped in a yellow bomber jacket swimming with mermaids and honestly all of us were kind of shocked at how well this worked. The shadows on the rocks, the swimming mechanics, and poof, it was all over in 60 seconds, and we needed to create another world. Thanks to the DeepMind team, I had a bit of an early access to this tech and had a chance to interview folks behind the model (look out for that episode soon) and the use-cases for this span from entertaining your kids all the way to “this may be the path to AGI, generating full simulated worlds to agents for them to learn”. The visual fidelity, reaction speed and general feel of this far outruns the previous world models we showed you (WorldLabs, Mirage) as this model seems to have memory of every previous action (eg. if your character makes a trail, you turn around and the trail is still there!). Is it worth the upgrade to Ultra Gemini Plan? Probably not, it’s an incredible demo, but the 1 minute length is very short, and the novelty wears off fairly quick. If you’d like to try, folks at Deepmind gave us 3 Ultra subscriptions to give out! Just tweet out the link to this episode and add #GenieThursdai and tag @altryne and I’ll raffle the ultra subscriptions between those who do Chrome steps into Agentic Browsing with Auto BrowseThis wasn’t the only mind blowing release from Gemini this week, the Chrome team upgraded the Gemini inside chrome to be actual helpful and agentic. And yes, we’ve seen this before, with Atlas from OpenAI, Comet from perplexity, but Google’s Chrome has a 70% hold on the browser market, and giving everyone with a Pro/Ultra subscription to “Auto Browse” is a huge huge deal. We’ve tested the Auto Browse feature live on the show, and Chrome completed 77 steps! I asked it to open up each of my bookmarks in a separate folder and summarize all of them, and it did a great job! Honestly, the biggest deal about this is not the capability itself, it’s the nearly 4B people this is now very close to, and the economic impact of this ability. IMO this may be the more impactful news out of Google this week! Other news in big labs: * Anthropic launches in chat applications based on the MCP Apps protocol. We interviewed the two folks behind this protocol back in November if you’d like to hear more about it. With connectors like Figma, Slack, Asana that can now show rich experiences* Anthropic’s CEO Dario Amodei also published an essay called ‘The Adolescence of Technology” - warning of AI risks to national security* Anthropic forced the creator of the popular open source AI Assistant Clawdbot to rename, they chose Moltbot as the name (apparently because crypto scammers stole a better name) EDIT: just after publishing this newsletter, the name was changed to OpenClaw, which we all agree is way way better. Open Source AIKimi K2.5: Moonshot AI’s 1 Trillion Parameter Agentic MonsterWolfram’s favorite release of the week, and for good reason. Moonshot AI just dropped Kimi K2.5, and this thing is an absolute beast for open source. We’re talking about a 1 trillion parameter Mixture-of-Experts model with 32B active parameters, 384 experts (8 selected per token), and 256K context length.But here’s what makes this special — it’s now multimodal. The previous K
📆 ThursdAI - Jan 22 - Clawdbot deep dive, GLM 4.7 Flash, Anthropic constitution + 3 new TSS models
Hey! Alex here, with another weekly AI update! It seems like ThursdAI is taking a new direction, as this is our 3rd show this year, and a 3rd deep dive into topics (previously Ralph, Agent Skills), please let me know if the comments if you like this format. This week’s deep dive is into Clawdbot, a personal AI assistant you install on your computer, but can control through your phone, has access to your files, is able to write code, help organize your life, but most importantly, it can self improve. Seeing Wolfred (my Clawdbot) learn to transcribe incoming voice messages blew my mind, and I wanted to share this one with you at length! We had Dan Peguine on the show for the deep dive + both Wolfram and Yam are avid users! This one is not to be missed. If ThursdAI is usually too technical for you, use Claude, and install Clawdbot after you read/listen to the deep dive!Also this week, we read Claude’s Constitution that Anthropic released, heard a bunch of new TTS models (some are open source and very impressive) and talked about the new lightspeed coding model GLM 4.7 Flash. First the news, then deep dive, lets go 👇ThursdAI - Recaps of the most high signal AI weekly spaces is a reader-supported publication. To receive new posts and support my work, consider becoming a free or paid subscriber.Open Source AIZ.ai’s GLM‑4.7‑Flash is the Local Agent Sweet Spot (X, HF)This was the open‑source release that mattered this week. Z.ai (formerly Zhipu) shipped GLM‑4.7‑Flash, a 30B MoE model with only 3B active parameters per token, which makes it much more efficient for local agent work. We’re talking a model you can run on consumer hardware that still hits 59% on SWE‑bench Verified, which is uncomfortably close to frontier coding performance. In real terms, it starts to feel like “Sonnet‑level agentic ability, but local.” I know I know, we keep saying “sonnet at home” at different open source models, but this one slaps! Nisten was getting around 120 tokens/sec on an M3 Ultra Mac Studio using MLX, and that’s kind of the headline. The model is fast and capable enough that local agent loops like RALPH suddenly feel practical. It also performs well on browser‑style agent tasks, which is exactly what you want for local automation without sending all your data to a cloud provider. Liquid AI’s LFM2.5‑1.2B Thinking is the “Tiny but Capable” Class (X, HF)Liquid AI released a 1.2B reasoning model that runs under 900MB of memory while still manages to be useful. This thing is built for edge devices and old phones, and the speed numbers are backing it up. We’re talking 239 tok/s decode on AMD CPU, 82 tok/s on mobile NPU, and prefill speeds that make long prompts actually usable. Nisten made a great point: on iOS, there’s a per‑process memory limit around 3.8GB, so a 1.2B model lets you spend your budget on context instead of weights.This is the third class of models we’re now living with: not Claude‑scale, not “local workstation,” but “tiny agent in your pocket.” It’s not going to win big benchmarks, but it’s perfect for on‑device workflows, lightweight assistants, and local RAG.Voice & Audio: Text To Speech is hot this week with 3 releases! We tested three major voice releases this week, and I’m not exaggerating when I say the latency wars are now fully on. Qwen3‑TTS: Open Source, 97ms Latency, Voice Cloning (X, HF)Just 30 minutes before the show, Qwen released their first model of the year, Qwen3 TTS, with two models (0.6B and 1.7B). With support for Voice Cloning based on just 3 seconds of voice, and claims of 97MS latency, this apache 2.0 release looked very good on the surface!The demos we did on stage though... were lackluster. TTS models like Kokoro previously impressed us with super tiny sizes and decent voice, while Qwen3 didn’t really perform on the cloning aspect. For some reason (I tested in Russian which they claim to support) the cloned voice kept repeating the provided sample voice instead of just generating the text I gave it. This confused me, and I’m hoping this is just a demo issue, not a problem with the model. They also support voice design where you just type in the type of voice you want, which to be fair, worked fairly well in our tests!With Apache 2.0 and a full finetuning capability, this is a great release for sure, kudos to the Qwen team! Looking forward to see what folks do with this properly. FlashLabs Chroma 1.0: Real-Time Speech-to-Speech, Open Source (X, HF) Another big open source release in the audio category this week was Chroma 1.0 from FlashLabs, which claim to be the first speech2speech model (not a model that has the traditional ASR>LLM>TTS pipeline) and the claim 150ms end to end latency! The issue with this one is, the company released an open source 4B model, and claimed that this model powers their chat interface demo on the web, but in the release notes they claim the model is english speaking only, while on the website it sounds incredible and I spoke to it in other languages 🤔 I think
📆 ThursdAI - Jan 15 - Agent Skills Deep Dive, GPT 5.2 Codex Builds a Browser, Claude Cowork for the Masses, and the Era of Personalized AI!
Hey ya’ll, Alex here, and this week I was especially giddy to record the show! Mostly because when a thing clicks for me that hasn’t clicked before, I can’t wait to tell you all about it! This week, that thing is Agent Skills! The currently best way to customize your AI agents with domain expertise, in a simple, repeatable way that doesn’t blow up the context window! We mentioned skills when Anthropic first released them (Oct 16) and when they became an open standard but it didn’t really click until last week! So more on that below. Also this week, Anthropic released a research preview of Claude Cowork, an agentic tool for non coders, OpenAI finally let loos GPT 5.2 Codex (in the API, it was previously available only via Codex), Apple announced a deal with Gemini to power Siri, OpenAI and Anthropic both doubled down on healthcare and much more! We had an incredible show, with an expert in Agent Skills, Eleanor Berger and the usual gang on co-hosts, strongly recommend watching the show in addition to the newsletter! Also, I vibe coded skills support for all LLMs to Chorus, and promised folks a link to download it, so look for that in the footer, let’s dive in! ThursdAI is where you stay up to date! Subscribe to keep us going! Big Company LLMs + APIs: Cowork, Codex, and a Browser in a WeekAnthropic launches Claude Cowork: Agentic AI for Non‑Coders (research preview)Anthropic announced Claude Cowork, which is basically Claude Code wrapped in a friendly UI for people who don’t want to touch a terminal. It’s a research preview available on the Max tier, and it gives Claude read/write access to a folder on your Mac so it can do real work without you caring about diffs, git, or command line.The wild bit is that Cowork was built in a week and a half, and according to the Anthropic team it was 100% written using Claude Code. This feels like a “we’ve crossed a threshold” moment. If you’re wondering why this matters, it’s because coding agents are general agents. If a model can write code to do tasks, it can do taxes, clean your desktop, or orchestrate workflows, and that means non‑developers can now access the same leverage developers have been enjoying for a year.It also isn’t just for files—it comes with a Chrome connector, meaning it can navigate the web to gather info, download receipts, or do research and it uses skills (more on those later)Earlier this week I recorded this first reactions video about Cowork and I’ve been testing it ever since, it’s a very interesting approach of coding agents that “hide the coding” to just... do things. Will this become as big as Claude Code for anthropic (which is reportedly a 1B business for them)? Let’s see! There are real security concerns here, especially if you’re not in the habit of backing up or using git. Cowork sandboxes a folder, but it can still delete things in that folder, so don’t let it loose on your whole drive unless you like chaos.GPT‑5.2 Codex: Long‑Running Agents Are HereOpenAI shipped GPT‑5.2 Codex into the API finally! After being announced as the answer for Opus 4.5 and only being available in Codex. The big headline is SOTA on SWE-Bench and long‑running agentic capability. People describe it as methodical. It takes longer, but it’s reliable on extended tasks, especially when you let it run without micromanaging.This model is now integrated into Cursor, GitHub Copilot, VS Code, Factory, and Vercel AI Gateway within hours of launch. It’s also state‑of‑the‑art on SWE‑Bench Pro and Terminal‑Bench 2.0, and it has native context compaction. That last part matters because if you’ve ever run an agent for long sessions, the context gets bloated and the model gets dumber. Compaction is an attempt to keep it coherent by summarizing old context into fresh threads, and we debated whether it really works. I think it helps, but I also agree that the best strategy is still to run smaller, atomic tasks with clean context.Cursor vibe-coded browser with GPT-5.2 and 3M lines of codeThe most mind‑blowing thing we discussed is Cursor letting GPT‑5.2 Codex run for a full week to build a browser called FastRenderer. This is not Chromium‑based. It’s a custom HTML parser, CSS cascade, layout engine, text shaping, paint pipeline, and even a JavaScript VM, written in Rust, from scratch. The codebase is open source on GitHub, and the full story is on Cursor’s blog It took nearly 30,000 commits and millions of lines of code. The system ran hundreds of concurrent agents with a planner‑worker architecture, and GPT‑5.2 was the best model for staying on task in that long‑running regime. That’s the real story, not just “lol a model wrote a browser.” This is a stress test for long‑horizon agentic software development, and it’s a preview of how teams will ship in 2026.I said on the show, browsers are REALLY hard, it took two decades for the industry to settle and be able to render websites normally, and there’s a reason everyone’s using Chromium. This is VERY impressive 👏 Now as for me, I
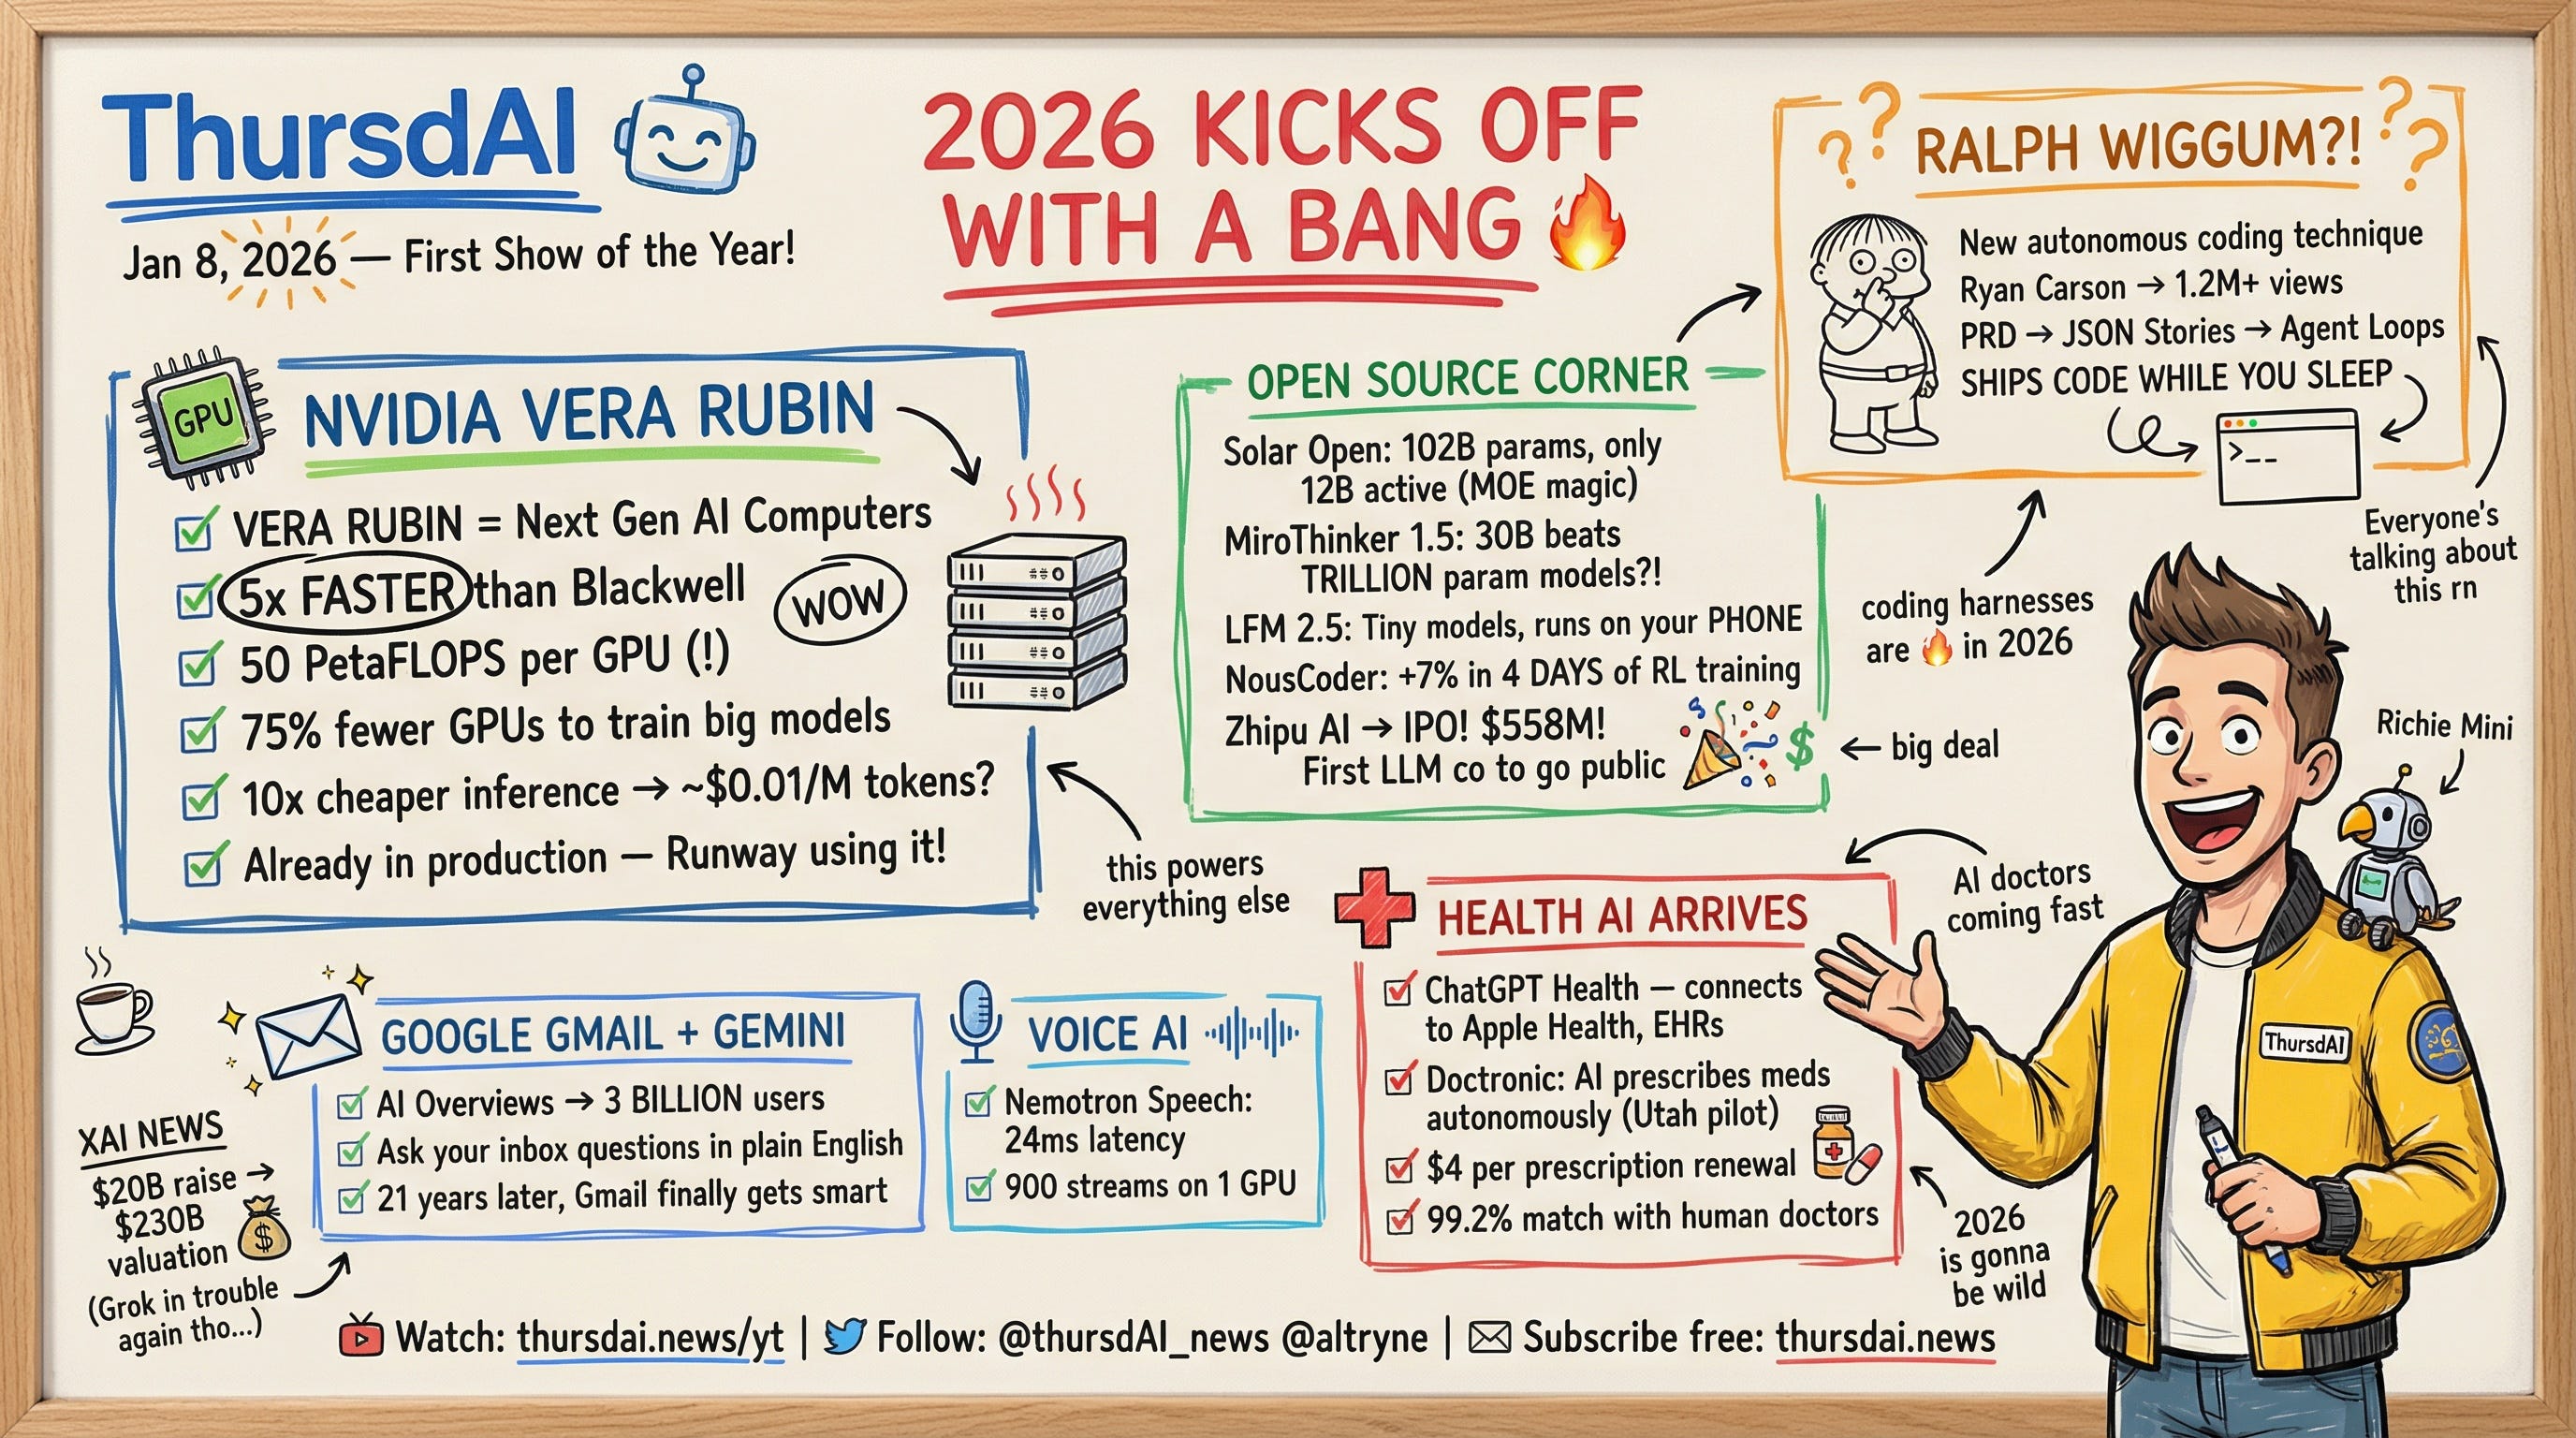
ThursdAI - Jan 8 - Vera Rubin's 5x Jump, Ralph Wiggum Goes Viral, GPT Health Launches & XAI Raises $20B Mid-Controversy
Hey folks, Alex here from Weights & Biases, with your weekly AI update (and a first live show of this year!) For the first time, we had a co-host of the show also be a guest on the show, Ryan Carson (from Amp) went supernova viral this week with an X article (1.5M views) about Ralph Wiggum (yeah, from Simpsons) and he broke down that agentic coding technique at the end of the show. LDJ and Nisten helped cover NVIDIA’s incredible announcements during CES with their Vera Rubin upcoming platform (4-5X improvements) and we all got excited about AI medicine with ChatGPT going into Health officially! Plus, a bunch of Open Source news, let’s get into this: ThursdAI - Recaps of the most high signal AI weekly spaces is a reader-supported publication. To receive new posts and support my work, consider becoming a free or paid subscriber.Open Source: The “Small” Models Are WinningWe often talk about the massive frontier models, but this week, Open Source came largely from unexpected places and focused on efficiency, agents, and specific domains.Solar Open 100B: A Data MasterclassUpstage released Solar Open 100B, and it’s a beast. It’s a 102B parameter Mixture-of-Experts (MoE) model, but thanks to MoE magic, it only uses about 12B active parameters during inference. This means it punches incredibly high but runs fast.What I really appreciated here wasn’t just the weights, but the transparency. They released a technical report detailing their “Data Factory” approach. They trained on nearly 20 trillion tokens, with a huge chunk being synthetic. They also used a dynamic curriculum that adjusted the difficulty and the ratio of synthetic data as training progressed. This transparency is what pushes the whole open source community forward.Technically, it hits 88.2 on MMLU and competes with top-tier models, especially in Korean language tasks. You can grab it on Hugging Face.MiroThinker 1.5: The DeepSeek Moment for Agents?We also saw MiroThinker 1.5, a 30B parameter model that is challenging the notion that you need massive scale to be smart. It uses something they call “Interactive Scaling.”Wolfram broke this down for us: this agent forms hypotheses, searches for evidence, and then iteratively revises its answers in a time-sensitive sandbox. It effectively “thinks” before answering. The result? It beats trillion-parameter models on search benchmarks like BrowseComp. It’s significantly cheaper to run, too. This feels like the year where smaller models + clever harnesses (harnesses are the software wrapping the model) will outperform raw scale.Liquid AI LFM 2.5: Running on Toasters (Almost)We love Liquid AI and they are great friends of the show. They announced LFM 2.5 at CES with AMD, and these are tiny ~1B parameter models designed to run on-device. We’re talking about running capable AI on your laptop, your phone, or edge devices (or the Reachy Mini bot that I showed off during the show! I gotta try and run LFM on him!)Probably the coolest part is the audio model. Usually, talking to an AI involves a pipeline: Speech-to-Text (ASR) -> LLM -> Text-to-Speech (TTS). Liquid’s model is end-to-end. It hears audio and speaks audio directly. We watched a demo from Maxime Labonne where the model was doing real-time interaction, interleaving text and audio. It’s incredibly fast and efficient. While it might not write a symphony for you, for on-device tasks like summarization or quick interactions, this is the future.NousCoder-14B and Zhipu AI IPOA quick shoutout to our friends at Nous Research who released NousCoder-14B, an open-source competitive programming model that achieved a 7% jump on LiveCodeBench accuracy in just four days of RL training on 48 NVIDIA B200 GPUs. The model was trained on 24,000 verifiable problems, and the lead researcher Joe Li noted it achieved in 4 days what took him 2 years as a teenager competing in programming contests. The full RL stack is open-sourced on GitHub and Nous published a great WandB results page as well! And in historic news, Zhipu AI (Z.ai)—the folks behind the GLM series—became the world’s first major LLM company to IPO, raising $558 million on the Hong Kong Stock Exchange. Their GLM-4.7 currently ranks #1 among open-source and domestic models on both Artificial Analysis and LM Arena. Congrats to them!Big Companies & APIsNVIDIA CES: Vera Rubin Changes EverythingLDJ brought the heat on this one covering Jensen’s CES keynote that unveiled the Vera Rubin platform, and the numbers are almost hard to believe. We’re talking about a complete redesign of six chips: the Rubin GPU delivering 50 petaFLOPS of AI inference (5x Blackwell), the Vera CPU with 88 custom Olympus ARM cores, NVLink 6, ConnectX-9 SuperNIC, BlueField-4 DPU, and Spectrum-6 Ethernet.Let me put this in perspective using LDJ’s breakdown: if you look at FP8 performance, the jump from Hopper to Blackwell was about 5x. The jump from Blackwell to Vera Rubin is over 3x again—but here’s the kicker—while only adding about 200 watts of power

ThursdAI - Jan 1 2026 - Will Brown Interview + Nvidia buys Groq, Meta buys Manus, Qwen Image 2412 & Alex New Year greetings
Hey all, Happy new year! This is Alex, writing to you for the very fresh start of this year, it’s 2026 already, can you believe it? There was no live stream today, I figured the cohosts deserve a break and honestly it was a very slow week. Even the chinese labs who don’t really celebrate X-mas and new years didn’t come out with a banger AFAIK. ThursdAI - AI moves fast, we’re here to make sure you never miss a thing! Subscribe :) Tho I thought it was an incredible opportunity to finally post the Will Brow interview I recorded in November during the AI Engineer conference. Will is a researcher at Prime Intellect (big fans on WandB btw!) and is very known on X as a hot takes ML person, often going viral for tons of memes! Will is the creator and maintainer of the Verifiers library (Github) and his talk at AI Engineer was all about RL Environments (what they are, you can hear in the interview, I asked him!) TL;DR last week of 2025 in AIBesides this, my job here is to keep you up to date, and honestly this was very easy this week, as… almost nothing has happened, but here we go: Meta buys ManusThe year ended with 2 huge acquisitions / aquihires. First we got the news from Alex Wang that Meta has bought Manus.ai which is an agentic AI startup we covered back in March for an undisclosed amount (folks claim $2-3B) The most interesting thing here is that Manus is a Chinese company, and this deal requires very specific severance from Chinese operations.Jensen goes on a new years spending spree, Nvidia buys Groq (not GROK) for $20BGroq which we covered often here, and are great friends, is going to NVIDIA, in a… very interesting acqui-hire, which is a “non binding license” + most of Groq top employees apparently are going to NVIDIA. Jonathan Ross the CEO of Groq, was the co-creator of the TPU chips at Google before founding Groq, so this seems like a very strategic aquihire for NVIDIA! Congrats to our friends from Groq on this amazing news for the new year! Tencent open-sources HY-MT1.5 translation models with 1.8B edge-deployable and 7B cloud variants supporting 33 languages (X, HF, HF, GitHub)It seems that everyone’s is trying to de-throne whisper and this latest attempt from Tencent is a interesting one. a 1.8B and 7B translation models with very interesting stats. Alibaba’s Qwen-Image-2512 drops on New Year’s Eve as strongest open-source text-to-image model, topping AI Arena with photorealistic humans and sharper textures (X, HF, Arxiv)Our friends in Tongyi decided to give is a new years present in the form of an updated Qwen-image, with much improved realismThat’s it folks, this was a quick one, hopefully you all had an amazing new year celebration, and are gearing up to an eventful and crazy 2026. I wish you all happiness, excitement and energy to keep up with everything in the new year, and will make sure that we’re here to keep you up to date as always! P.S - I got a little news of my own this yesterday, not related to AI. She said yes 🎉 This is a public episode. If you'd like to discuss this with other subscribers or get access to bonus episodes, visit sub.thursdai.news/subscribe
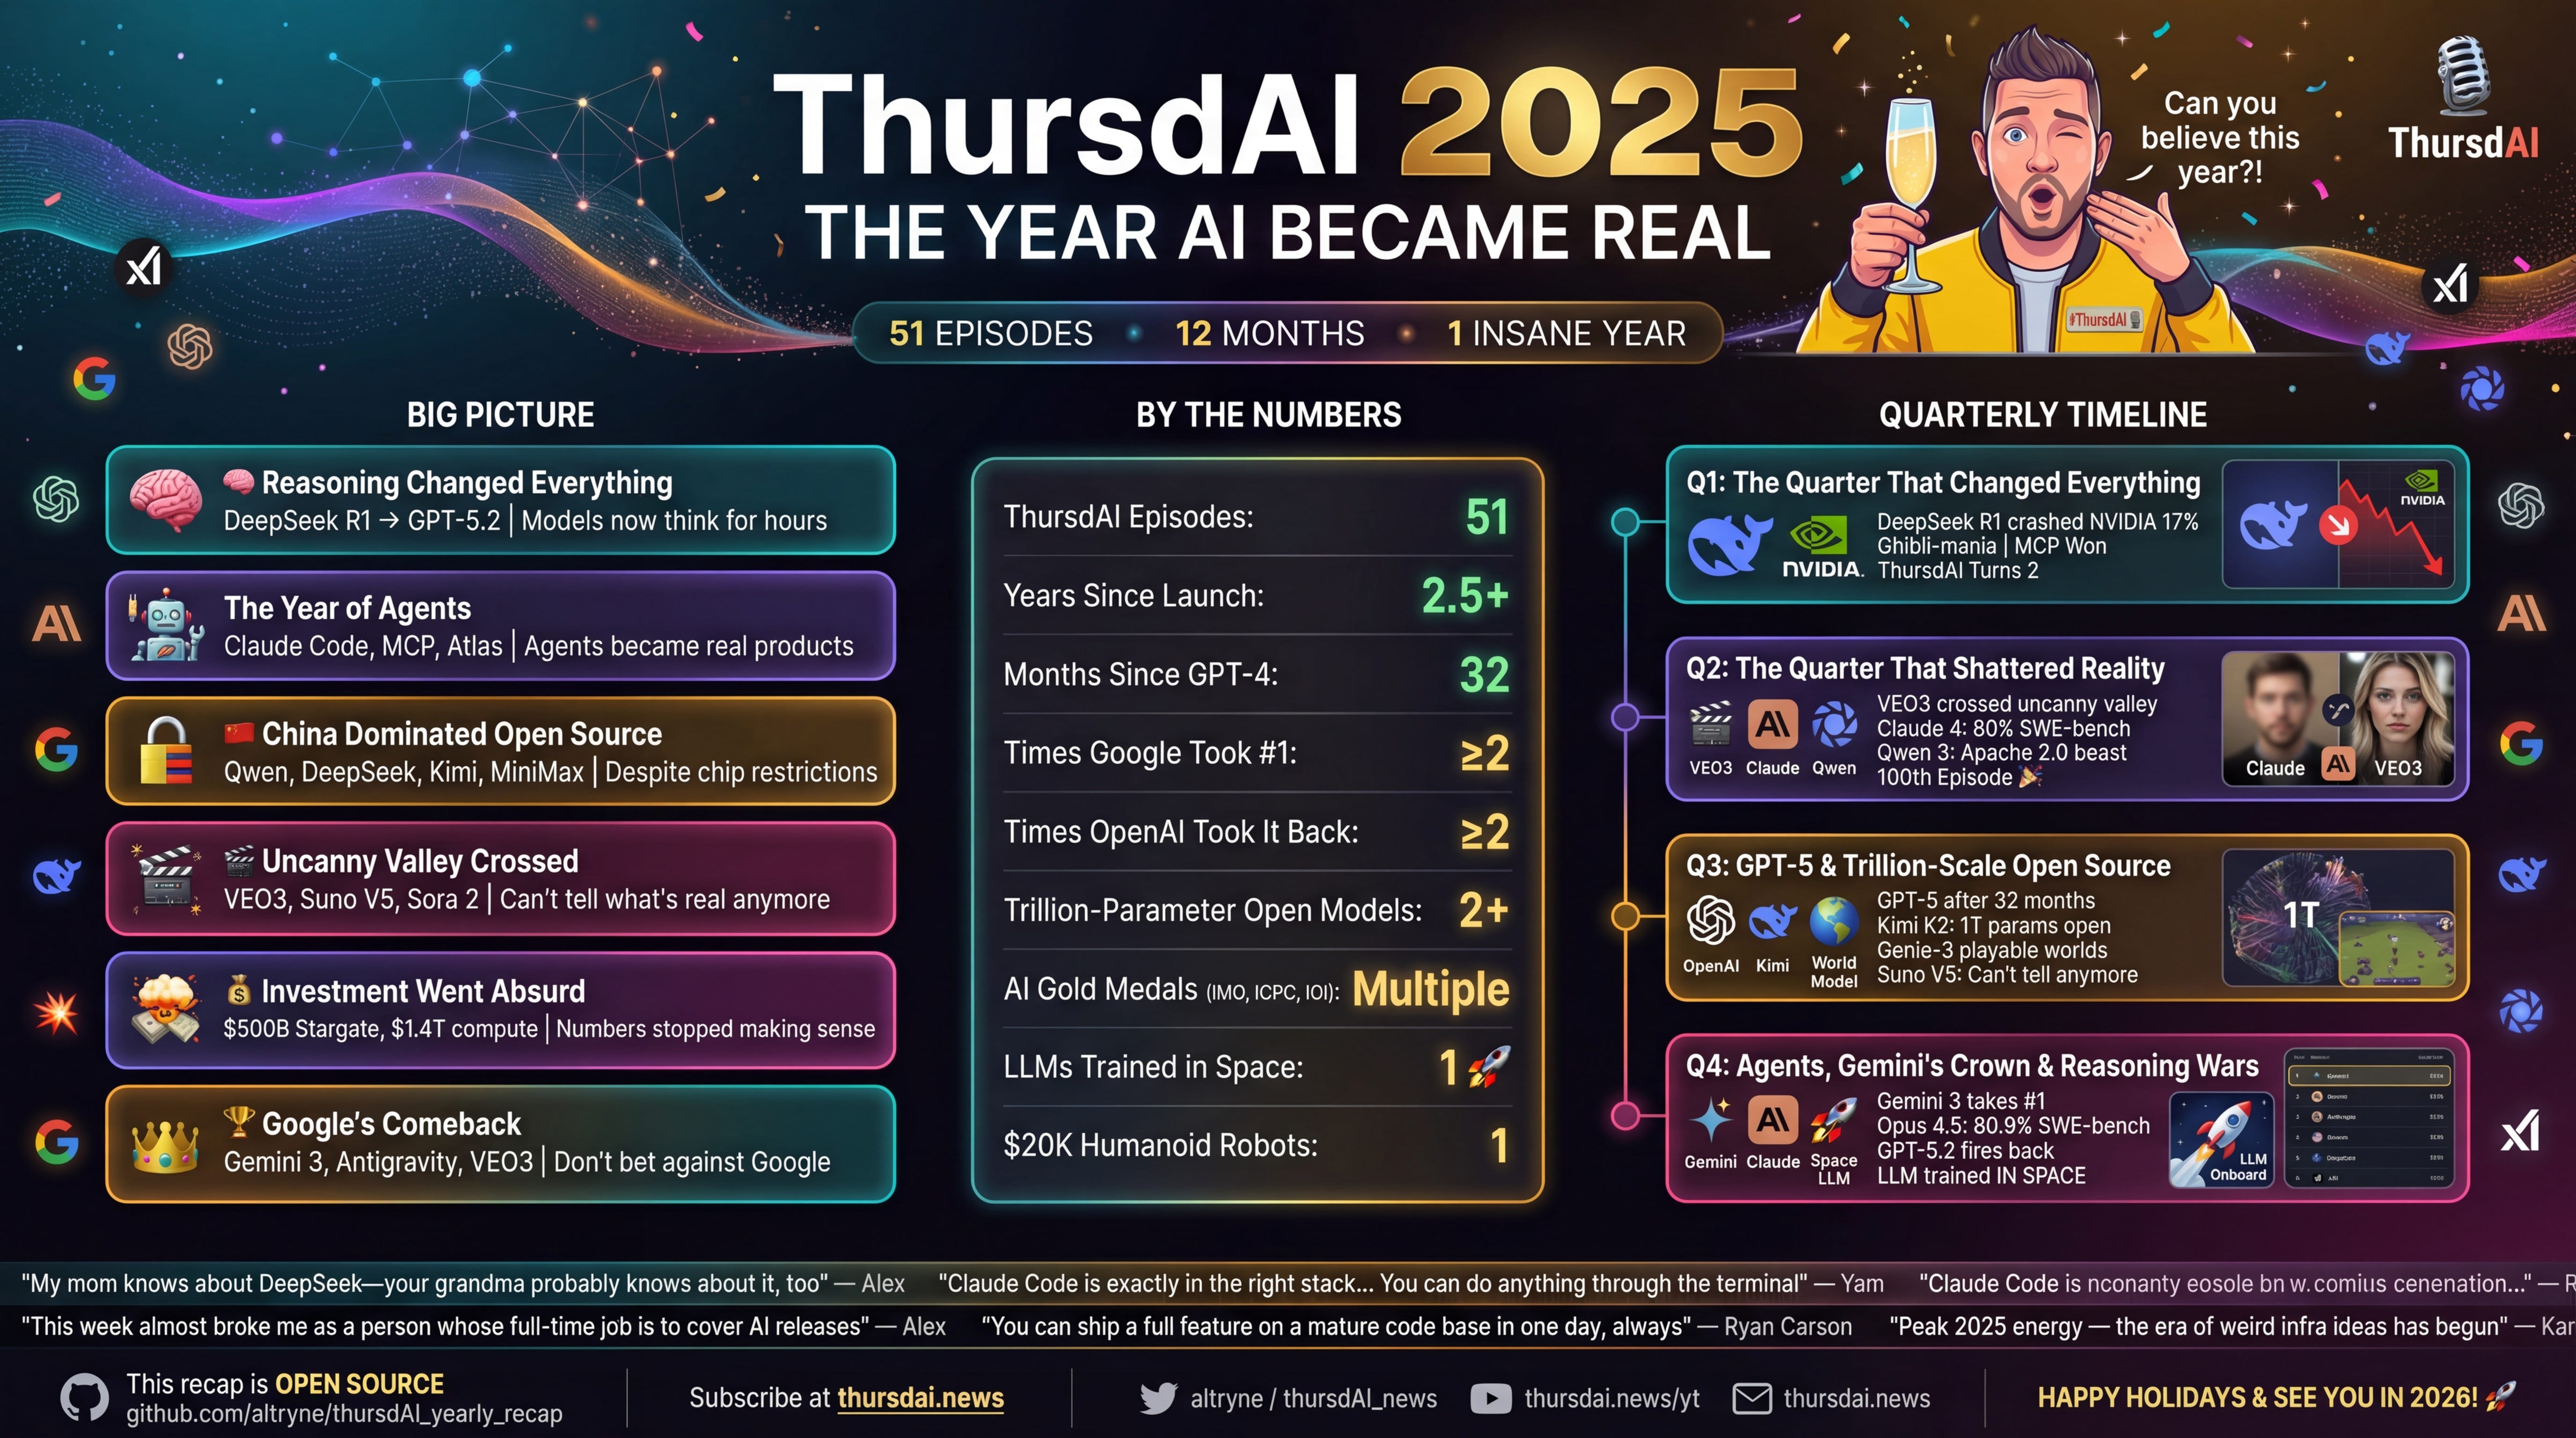
🔥 Someone Trained an LLM in Space This Year (And 50 Other Things You Missed)- ThursdAI yearly recap is here!
Ho Ho Ho, Alex here! (a real human writing these words, this needs to be said in 2025) Merry Christmas (to those who celebrate) and welcome to the very special yearly ThursdAI recap! This was an intense year in the world of AI, and after 51 weekly episodes (this is episode 52!) we have the ultimate record of all the major and most important AI releases of this year! So instead of bringing you a weekly update (it’s been a slow week so far, most AI labs are taking a well deserved break, the Cchinese AI labs haven’t yet surprised anyone), I’m dropping a comprehensive yearly AI review! Quarter by quarter, month by month, both in written form and as a pod/video! Why do this? Who even needs this? Isn’t most of it obsolete? I have asked myself this exact question while prepping for the show (it was quite a lot of prep, even with Opus’s help). I eventually landed on, hey, if nothing else, this will serve as a record of the insane week of AI progress we all witnessed. Can you imagine that the term Vibe Coding is less than 1 year old? That Claude Code was released at the start of THIS year? We get hedonicly adapt to new AI goodies so quick, and I figured this will serve as a point in time check, we can get back to and feel the acceleration! With that, let’s dive in - P.S. the content below is mostly authored by my co-author for this, Opus 4.5 high, which at the end of 2025 I find the best creative writer with the best long context coherence that can imitate my voice and tone (hey, I’m also on a break! 🎅) “Open source AI has never been as hot as this quarter. We’re accelerating as f*ck, and it’s only just beginning—hold on to your butts.” — Alex Volkov, ThursdAI Q1 2025🏆 The Big Picture — 2025 - The Year the AI Agents Became RealLooking back at 51 episodes and 12 months of relentless AI progress, several mega-themes emerged:1. 🧠 Reasoning Models Changed EverythingFrom DeepSeek R1 in January to GPT-5.2 in December, reasoning became the defining capability. Models now think for hours, call tools mid-thought, and score perfect on math olympiads.2. 🤖 2025 Was Actually the Year of AgentsWe said it in January, and it came true. Claude Code launched the CLI revolution, MCP became the universal protocol, and by December we had ChatGPT Apps, Atlas browser, and AgentKit.3. 🇨🇳 Chinese Labs Dominated Open SourceDeepSeek, Qwen, MiniMax, Kimi, ByteDance — despite chip restrictions, Chinese labs released the best open weights models all year. Qwen 3, Kimi K2, DeepSeek V3.2 were defining releases.4. 🎬 We Crossed the Uncanny ValleyVEO3’s native audio, Suno V5’s indistinguishable music, Sora 2’s social platform — 2025 was the year AI-generated media became indistinguishable from human-created content.5. 💰 The Investment Scale Became Absurd$500B Stargate, $1.4T compute obligations, $183B valuations, $100-300M researcher packages, LLMs training in space. The numbers stopped making sense.6. 🏆 Google Made a ComebackAfter years of “catching up,” Google delivered Gemini 3, Antigravity, Nano Banana Pro, VEO3, and took the #1 spot (briefly). Don’t bet against Google.By the NumbersQ1 2025 — The Quarter That Changed EverythingDeepSeek R1 crashed NVIDIA’s stock, reasoning models went mainstream, and Chinese labs took over open source. The quarter that proved AI isn’t slowing down—it’s just getting started.Key Themes:* 🧠 Reasoning models went mainstream (DeepSeek R1, o1, QwQ)* 🇨🇳 Chinese labs dominated open source (DeepSeek, Alibaba, MiniMax, ByteDance)* 🤖 2025 declared “The Year of Agents” (OpenAI Operator, MCP won)* 🖼️ Image generation revolution (GPT-4o native image gen, Ghibli-mania)* 💰 Massive infrastructure investment (Project Stargate $500B)January — DeepSeek Shakes the World(Jan 02 | Jan 10 | Jan 17 | Jan 24 | Jan 30)The earthquake that shattered the AI bubble. DeepSeek R1 dropped on January 23rd and became the most impactful open source release ever:* Crashed NVIDIA stock 17% — $560B loss, largest single-company monetary loss in history* Hit #1 on the iOS App Store* Cost allegedly only $5.5M to train (sparking massive debate)* Matched OpenAI’s o1 on reasoning benchmarks at 50x cheaper pricing* The 1.5B model beat GPT-4o and Claude 3.5 Sonnet on math benchmarks 🤯“My mom knows about DeepSeek—your grandma probably knows about it, too” — Alex VolkovAlso this month:* OpenAI Operator — First agentic ChatGPT (browser control, booking, ordering)* Project Stargate — $500B AI infrastructure (Manhattan Project for AI)* NVIDIA Project Digits — $3,000 desktop that runs 200B parameter models* Kokoro TTS — 82M param model hit #1 on TTS Arena, Apache 2, runs in browser* MiniMax-01 — 4M context window from Hailuo* Gemini Flash Thinking — 1M token context with thinking tracesFebruary — Reasoning Mania & The Birth of Vibe Coding(Feb 07 | Feb 13 | Feb 20 | Feb 28)The month that redefined how we work with AI.OpenAI Deep Research (Feb 6) — An agentic research tool that scored 26.6% on Humanity’s Last Exam (vs 10% for o1/R1). Dr. Derya Unutmaz c
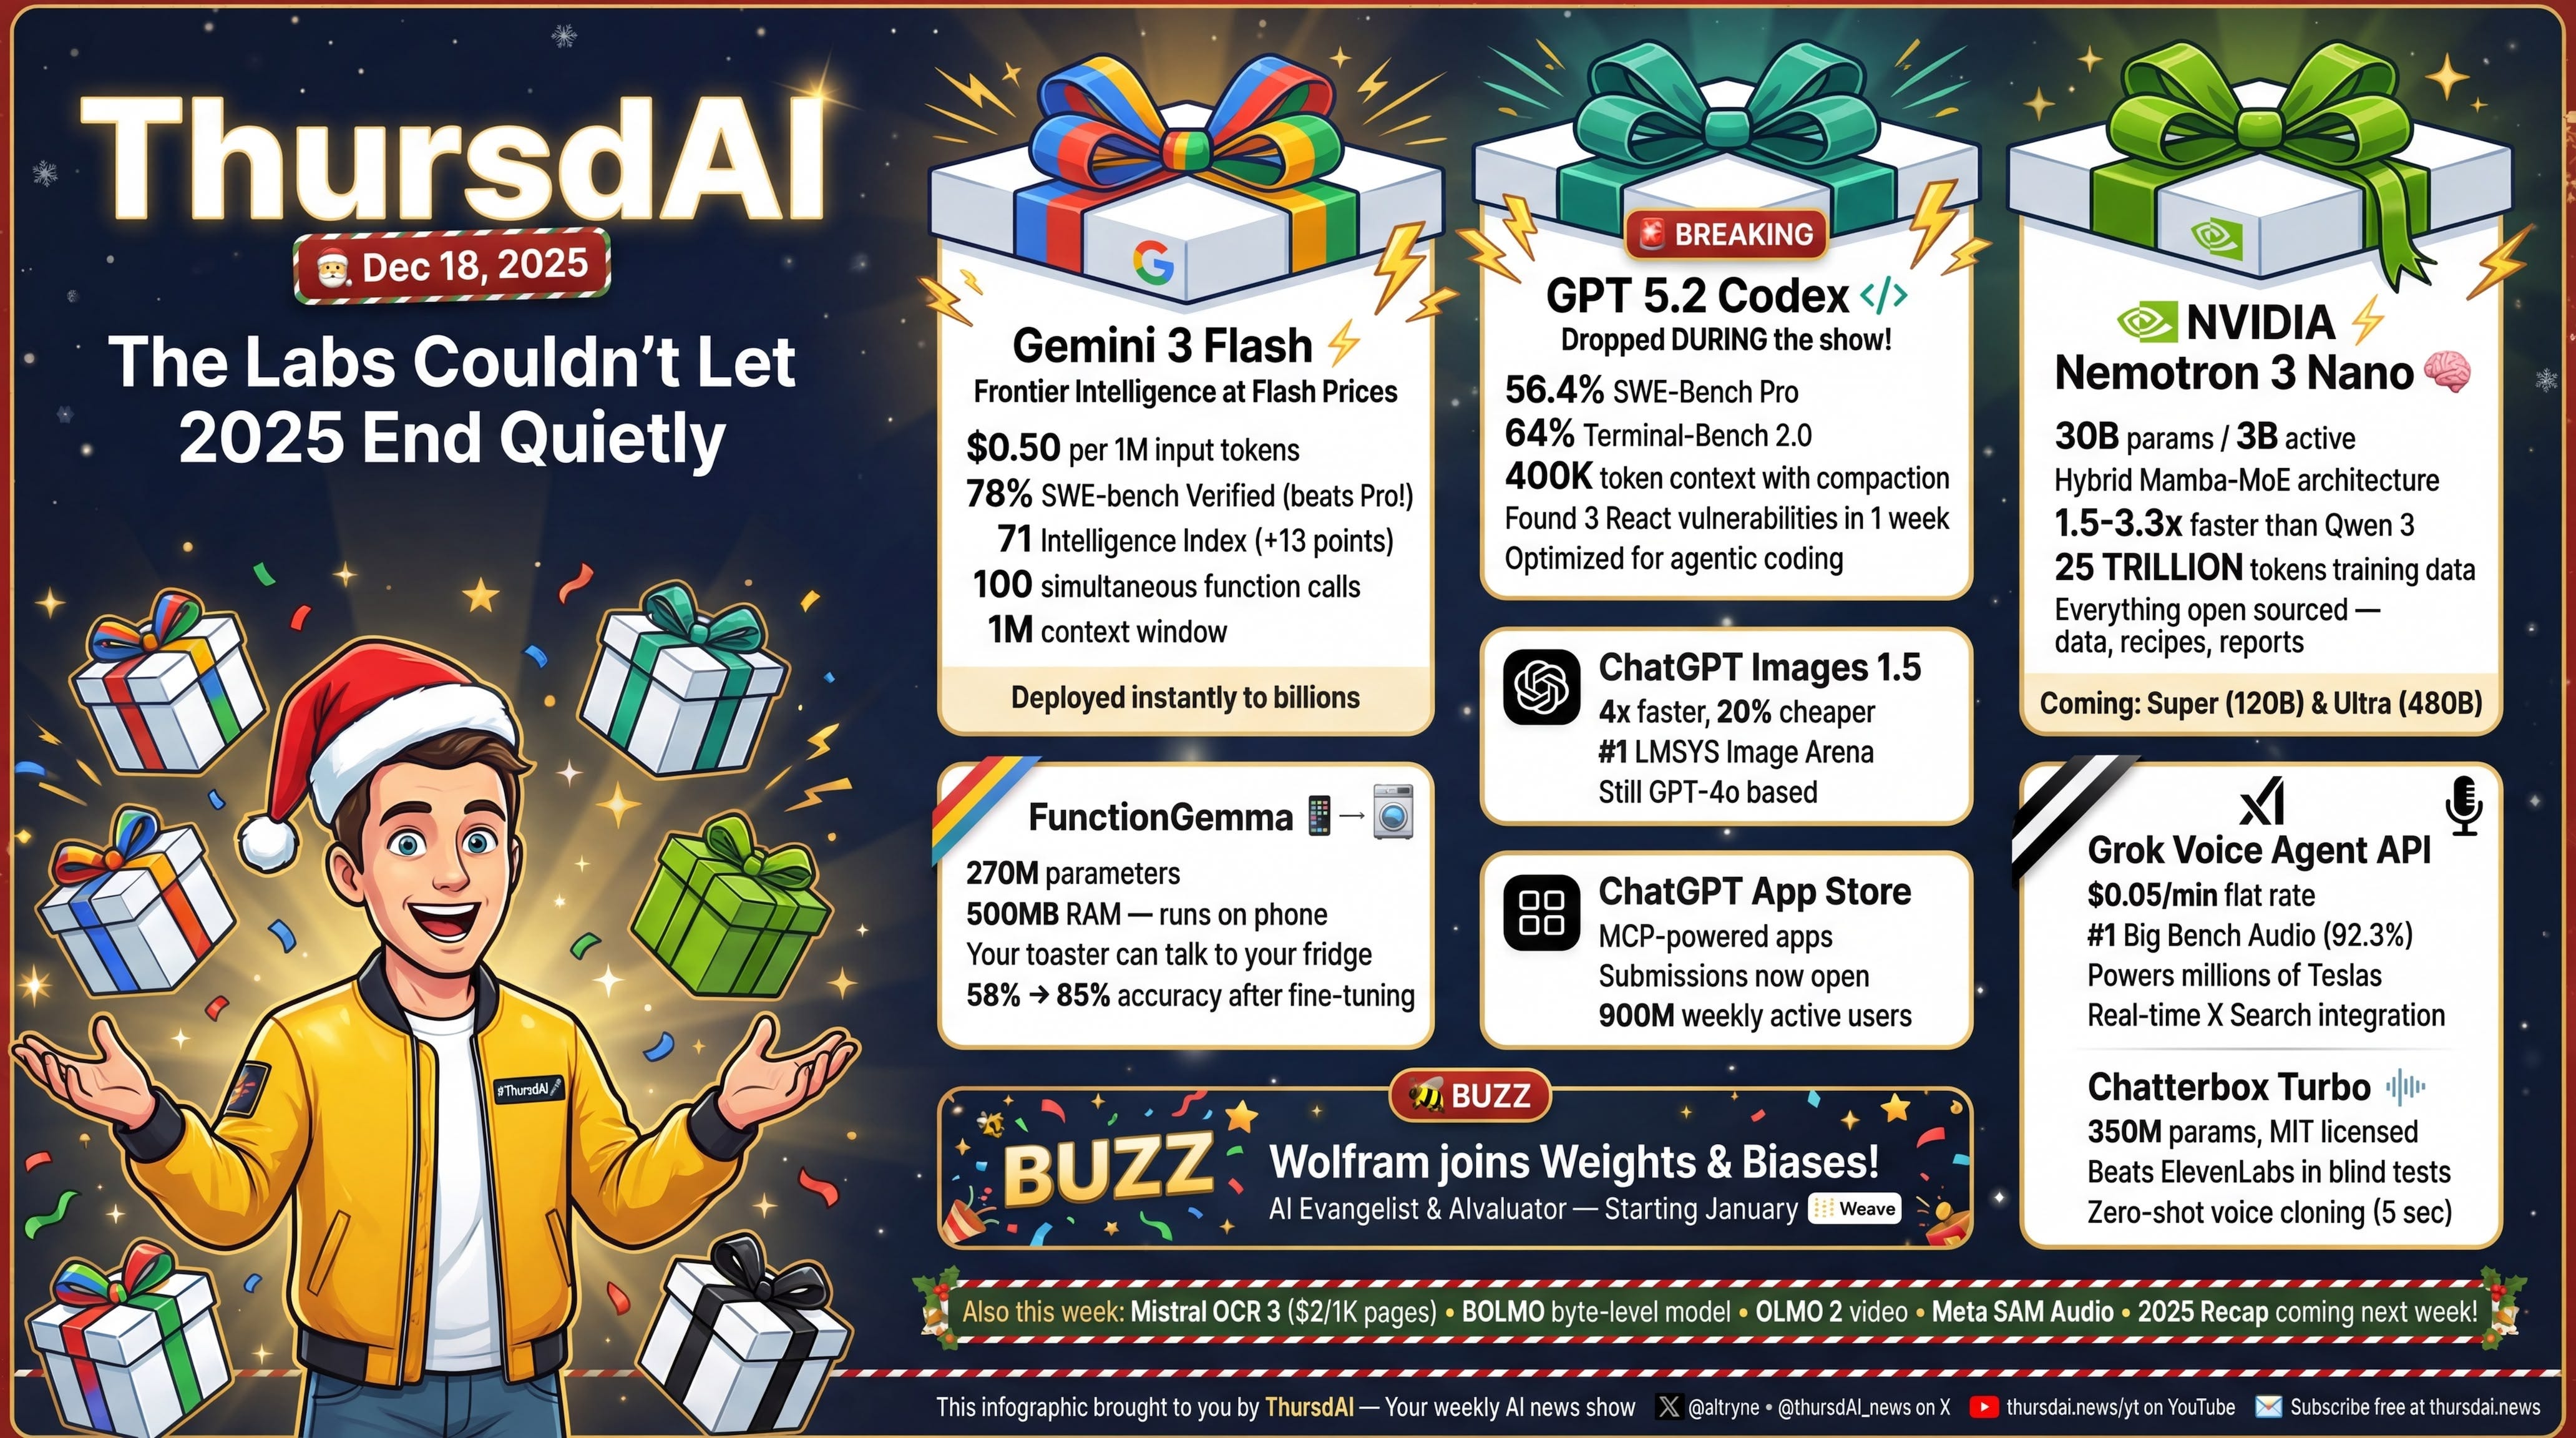
📆 ThursdAI - Dec 18 - Gemini 3 Flash, Grok Voice, ChatGPT Appstore, Image 1.5 & GPT 5.2 Codex, Meta Sam Audio & more AI news
Hey folks 👋 Alex here, dressed as 🎅 for our pre X-mas episode!We’re wrapping up 2025, and the AI labs decided they absolutely could NOT let the year end quietly. This week was an absolute banger—we had Gemini 3 Flash dropping with frontier intelligence at flash prices, OpenAI firing off GPT 5.2 Codex as breaking news DURING our show, ChatGPT Images 1.5, Nvidia going all-in on open source with Nemotron 3 Nano, and the voice AI space heating up with Grok Voice and Chatterbox Turbo. Oh, and Google dropped FunctionGemma for all your toaster-to-fridge communication needs (yes, really).Today’s show was over three and a half hours long because we tried to cover both this week AND the entire year of 2025 (that yearly recap is coming next week—it’s a banger, we went month by month and you’ll really feel the acceleration). For now, let’s dive into just the insanity that was THIS week.00:00 Introduction and Overview00:39 Weekly AI News Highlights01:40 Open Source AI Developments01:44 Nvidia's Nemotron Series09:09 Google's Gemini 3 Flash19:26 OpenAI's GPT Image 1.520:33 Infographic and GPT Image 1.5 Discussion20:53 Nano Banana vs GPT Image 1.521:23 Testing and Comparisons of Image Models23:39 Voice and Audio Innovations24:22 Grok Voice and Tesla Integration26:01 Open Source Robotics and Voice Agents29:44 Meta's SAM Audio Release32:14 Breaking News: Google Function Gemma33:23 Weights & Biases Announcement35:19 Breaking News: OpenAI Codex 5.2 MaxTo receive new posts and support my work, consider becoming a free or paid subscriber.Big Companies LLM updatesGoogle’s Gemini 3 Flash: The High-Speed Intelligence KingIf we had to title 2025, as Ryan Carson mentioned on the show, it might just be “The Year of Google’s Comeback.” Remember at the start of the year when we were asking “Where is Google?” Well, they are here. Everywhere.This week they launched Gemini 3 Flash, and it is rightfully turning heads. This is a frontier-class model—meaning it boasts Pro-level intelligence—but it runs at Flash-level speeds and, most importantly, Flash-level pricing. We are talking $0.50 per 1 million input tokens. That is not a typo. The price-to-intelligence ratio here is simply off the charts.I’ve been using Gemini 2.5 Flash in production for a while because it was good enough, but Gemini 3 Flash is a different beast. It scores 71 on the Artificial Analysis Intelligence Index (a 13-point jump from the previous Flash), and it achieves 78% on SWE-bench Verified. That actually beats the bigger Gemini 3 Pro on some agentic coding tasks!What impressed me most, and something Kwindla pointed out, is the tool calling. Previous Gemini models sometimes struggled with complex tool use compared to OpenAI, but Gemini 3 Flash can handle up to 100 simultaneous function calls. It’s fast, it’s smart, and it’s integrated immediately across the entire Google stack—Workspace, Android, Chrome. Google isn’t just releasing models anymore; they are deploying them instantly to billions of users.For anyone building agents, this combination of speed, low latency, and 1 million context window (at this price!) makes it the new default workhorse.Google’s FunctionGemma Open Source releaseWe also got a smaller, quirkier release from Google: FunctionGemma. This is a tiny 270M parameter model. Yes, millions, not billions.It’s purpose-built for function calling on edge devices. It requires only 500MB of RAM, meaning it can run on your phone, in your browser, or even on a Raspberry Pi. As Nisten joked on the show, this is finally the model that lets your toaster talk to your fridge.Is it going to write a novel? No. But after fine-tuning, it jumped from 58% to 85% accuracy on mobile action tasks. This represents a future where privacy-first agents live entirely on your device, handling your calendar and apps without ever pinging a cloud server.OpenAI Image 1.5, GPT 5.2 Codex and ChatGPT AppstoreOpenAI had a busy week, starting with the release of GPT Image 1.5. It’s available now in ChatGPT and the API. The headline here is speed and control—it’s 4x faster than the previous model and 20% cheaper. It also tops the LMSYS Image Arena leaderboards.However, I have to give a balanced take here. We’ve been spoiled recently by Google’s “Nano Banana Pro” image generation (which powers Gemini). When we looked at side-by-side comparisons, especially with typography and infographic generation, Gemini often looked sharper and more coherent. This is what we call “hedonistic adaptation”—GPT Image 1.5 is great, but the bar has moved so fast that it doesn’t feel like the quantum leap DALL-E 3 was back in the day. Still, for production workflows where you need to edit specific parts of an image without ruining the rest, this is a massive upgrade.🚨 BREAKING: GPT 5.2 CodexJust as we were nearing the end of the show, OpenAI decided to drop some breaking news: GPT 5.2 Codex.This is a specialized model optimized specifically for agentic coding, terminal workflows, and cybersecurity. We quickly p
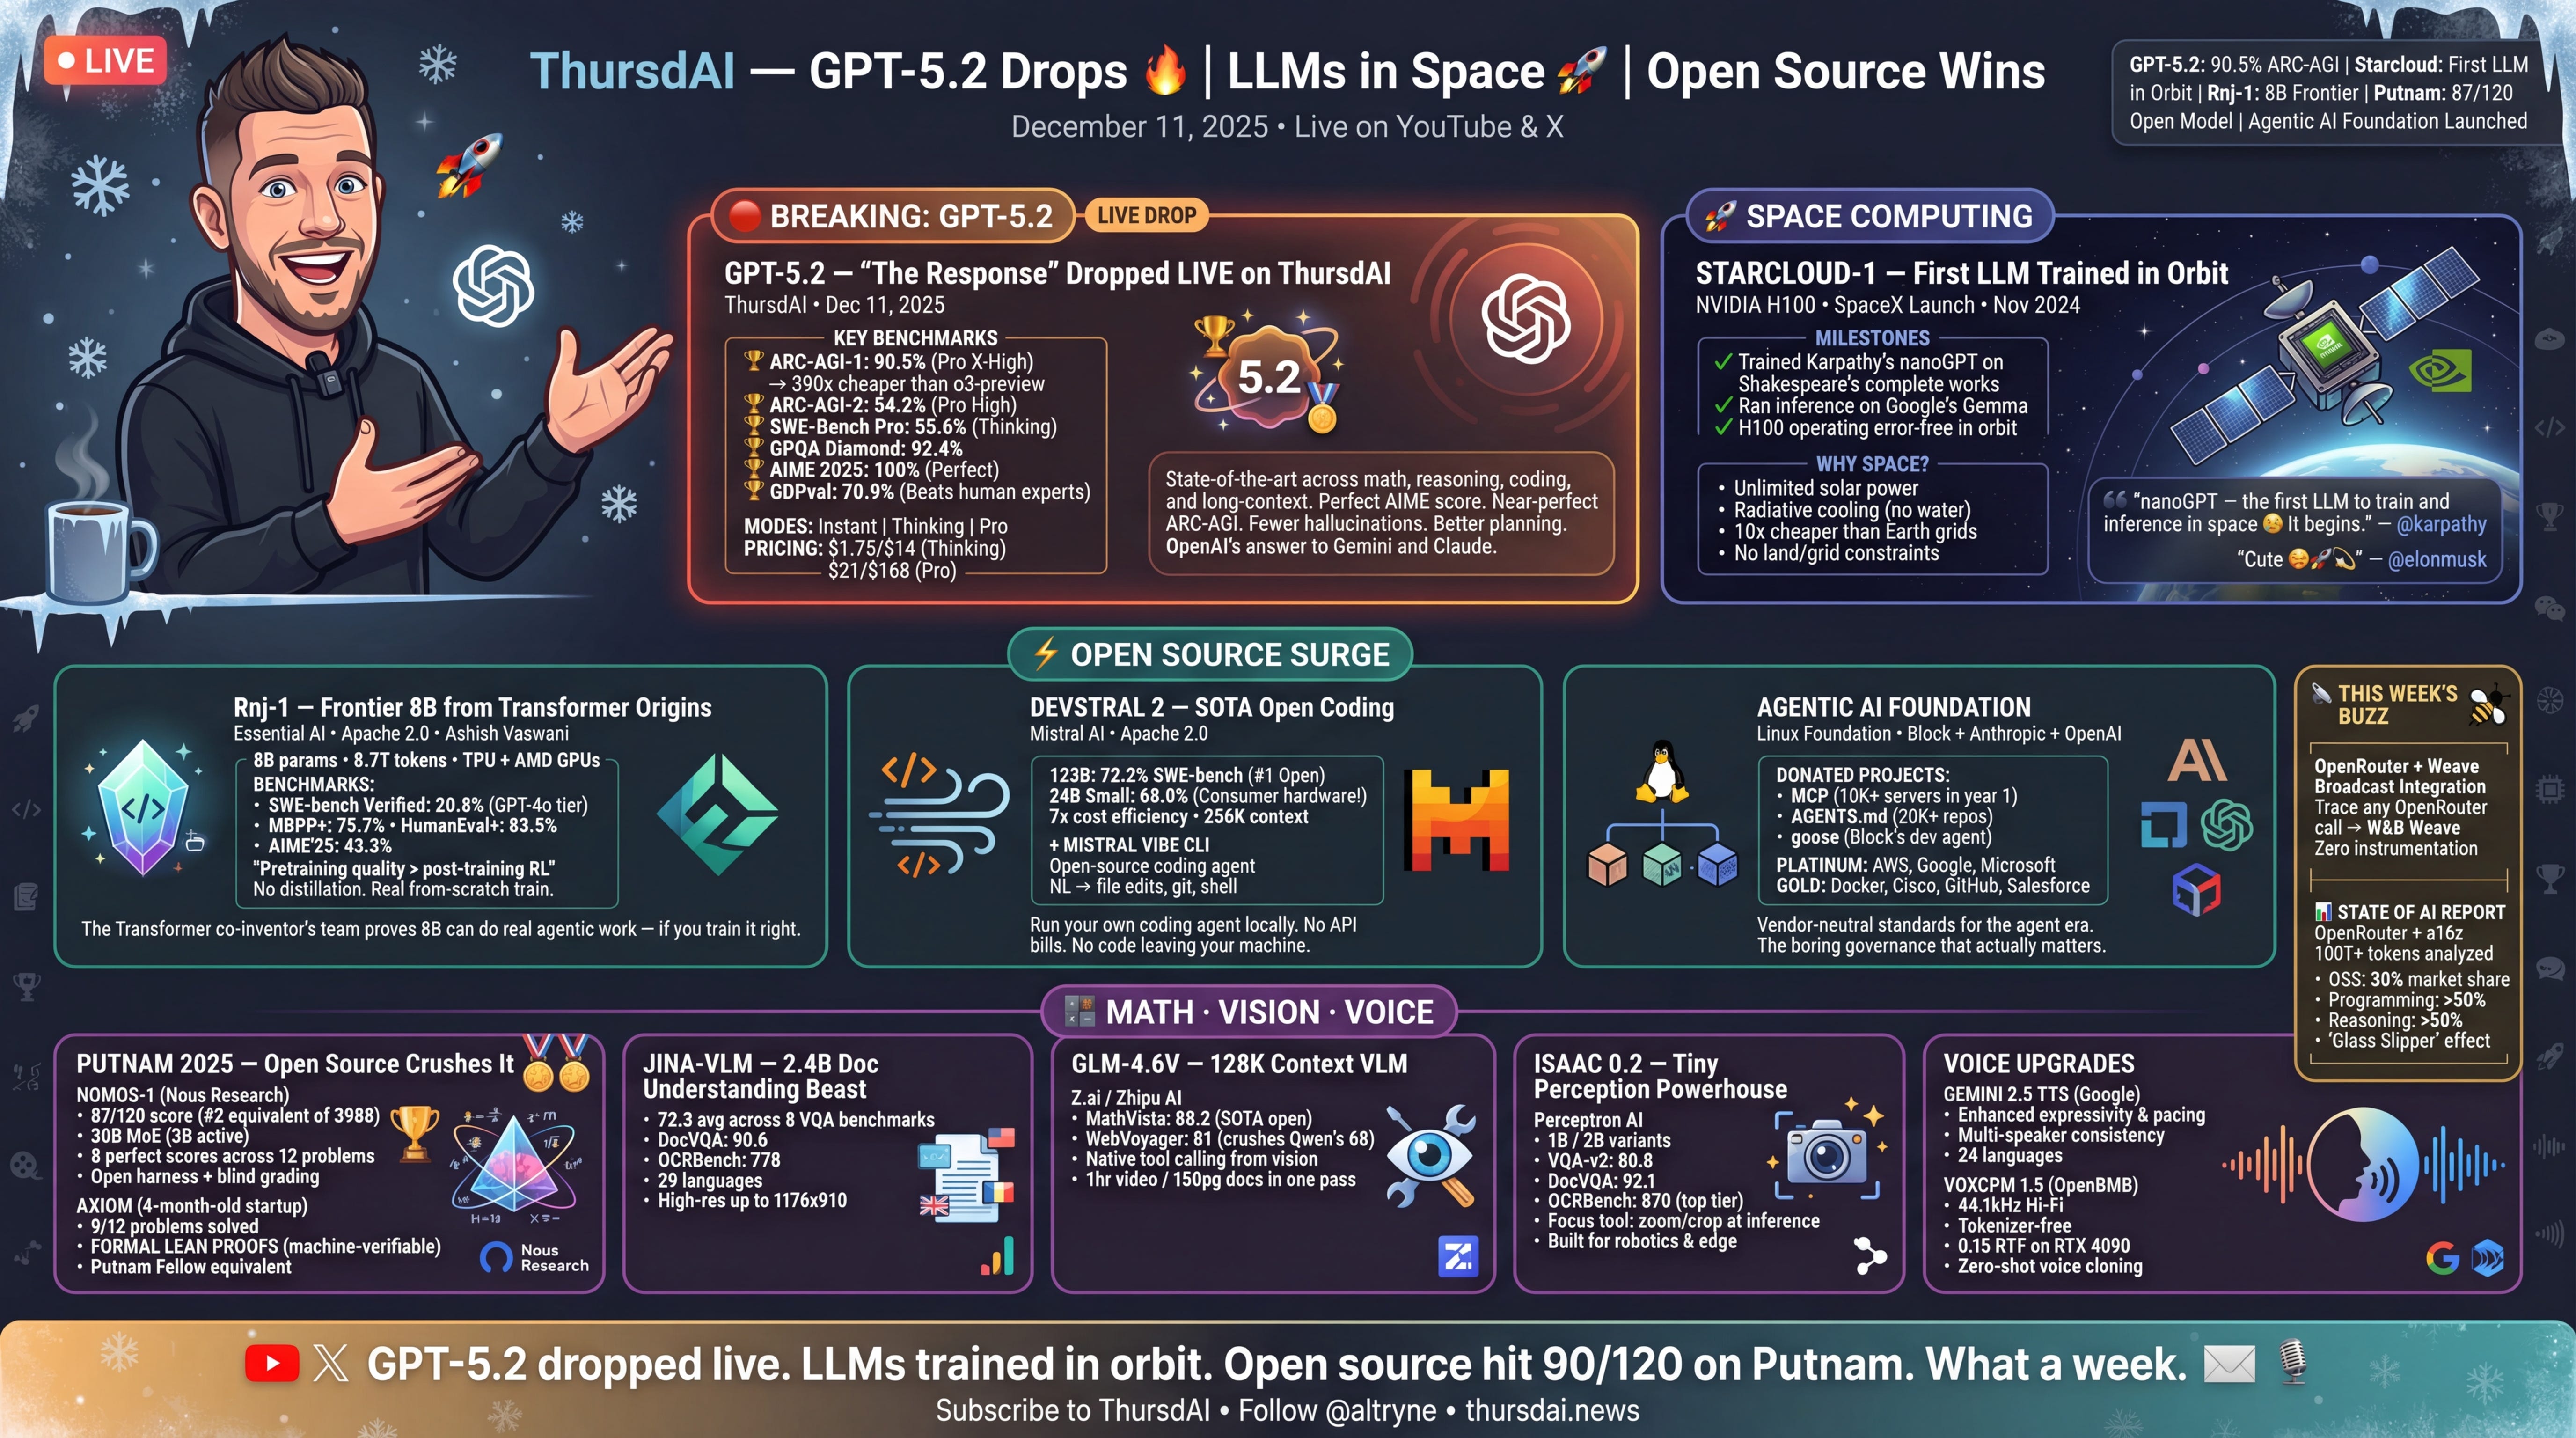
📆 ThursdAI - Dec 11 - GPT 5.2 is HERE! Plus, LLMs in Space, MCP donated, Devstral surprises and more AI news!
Hey everyone, December started strong and does NOT want to slow down!? OpenAI showed us their response to the Code Red and it’s GPT 5.2, which doesn’t feel like a .1 upgrade! We got it literally as breaking news at the end of the show, and oh boy! The new kind of LLMs is here. GPT, then Gemini, then Opus and now GPT again... Who else feels like we’re on a trippy AI rolercoaster? Just me? 🫨 I’m writing this newsletter from a fresh “traveling podcaster” setup in SF (huge shoutout to the Chroma team for the studio hospitality). P.S - Next week we’re doing a year recap episode (52st episode of the year, what is my life), but today is about the highest-signal stuff that happened this week.Alright. No more foreplay. Let’s dive in. Please subscribe. 🔥 The main event: OpenAI launches GPT‑5.2 (and it’s… a lot)We started the episode with “garlic in the air” rumors (OpenAI holiday launches always have that Christmas panic energy), and then… boom: GPT‑5.2 actually drops while we’re live.What makes this release feel significant isn’t “one benchmark went up.” It’s that OpenAI is clearly optimizing for the things that have become the frontier in 2025: long-horizon reasoning, agentic coding loops, long context reliability, and lower hallucination rates when browsing/tooling is involved.5.2 Instant, Thinking and Pro in ChatGPT and in the APIOpenAI shipped multiple variants, and even within those there are “levels” (medium/high/extra-high) that effectively change how much compute the model is allowed to burn. At the extreme end, you’re basically running parallel thoughts and selecting winners. That’s powerful, but also… very expensive.It’s very clearly aimed at the agentic world: coding agents that run in loops, tool-using research agents, and “do the whole task end-to-end” workflows where spending extra tokens is still cheaper than spending an engineer day.Benchmarks I’m not going to pretend benchmarks tell the full story (they never do), but the shape of improvements matters. GPT‑5.2 shows huge strength on reasoning + structured work.It hits 90.5% on ARC‑AGI‑1 in the Pro X‑High configuration, and 54%+ on ARC‑AGI‑2 depending on the setting. For context, ARC‑AGI‑2 is the one where everyone learns humility again.On math/science, this thing is flexing. We saw 100% on AIME 2025, and strong performance on FrontierMath tiers (with the usual “Tier 4 is where dreams go to die” vibe still intact). GPQA Diamond is up in the 90s too, which is basically “PhD trivia mode.”But honestly the most practically interesting one for me is GDPval (knowledge-work tasks: slides, spreadsheets, planning, analysis). GPT‑5.2 lands around 70%, which is a massive jump vs earlier generations. This is the category that translates directly into “is this model useful at my job.” - This is a bench that OpenAI launched only in September and back then, Opus 4.1 was a “measly” 47%! Talk about acceleration! Long context: MRCR is the sleeper highlightOn MRCR (multi-needle long-context retrieval), GPT‑5.2 holds up absurdly well even into 128k and beyond. The graph OpenAI shared shows GPT‑5.1 falling off a cliff as context grows, while GPT‑5.2 stays high much deeper into long contexts.If you’ve ever built a real system (RAG, agent memory, doc analysis) you know this pain: long context is easy to offer, hard to use well. If GPT‑5.2 actually delivers this in production, it’s a meaningful shift.Hallucinations: down (especially with browsing)One thing we called out on the show is that a bunch of user complaints in 2025 have basically collapsed into one phrase: “it hallucinates.” Even people who don’t know what a benchmark is can feel when a model confidently lies.OpenAI’s system card shows lower rates of major incorrect claims compared to GPT‑5.1, and lower “incorrect claims” overall when browsing is enabled. That’s exactly the direction they needed.Real-world vibes:We did the traditional “vibe tests” mid-show: generate a flashy landing page, do a weird engineering prompt, try some coding inside Cursor/Codex.Early testers broadly agree on the shape of the improvement. GPT‑5.2 is much stronger in reasoning, math, long‑context tasks, visual understanding, and multimodal workflows, with multiple reports of it successfully thinking for one to three hours on hard problems. Enterprise users like Box report faster execution and higher accuracy on real knowledge‑worker tasks, while researchers note that GPT‑5.2 Pro consistently outperforms the standard “Thinking” variant. The tradeoffs are also clear: creative writing still slightly favors Claude Opus, and the highest reasoning tiers can be slow and expensive. But as a general‑purpose reasoning model, GPT‑5.2 is now the strongest publicly available option.AI in space: Starcloud trains an LLM on an H100 in orbitThis story is peak 2025.Starcloud put an NVIDIA H100 on a satellite, trained Andrej Karpathy’s nanoGPT on Shakespeare, and ran inference on Gemma. There’s a viral screenshot vibe here that’s impossible to ignore: SSH i
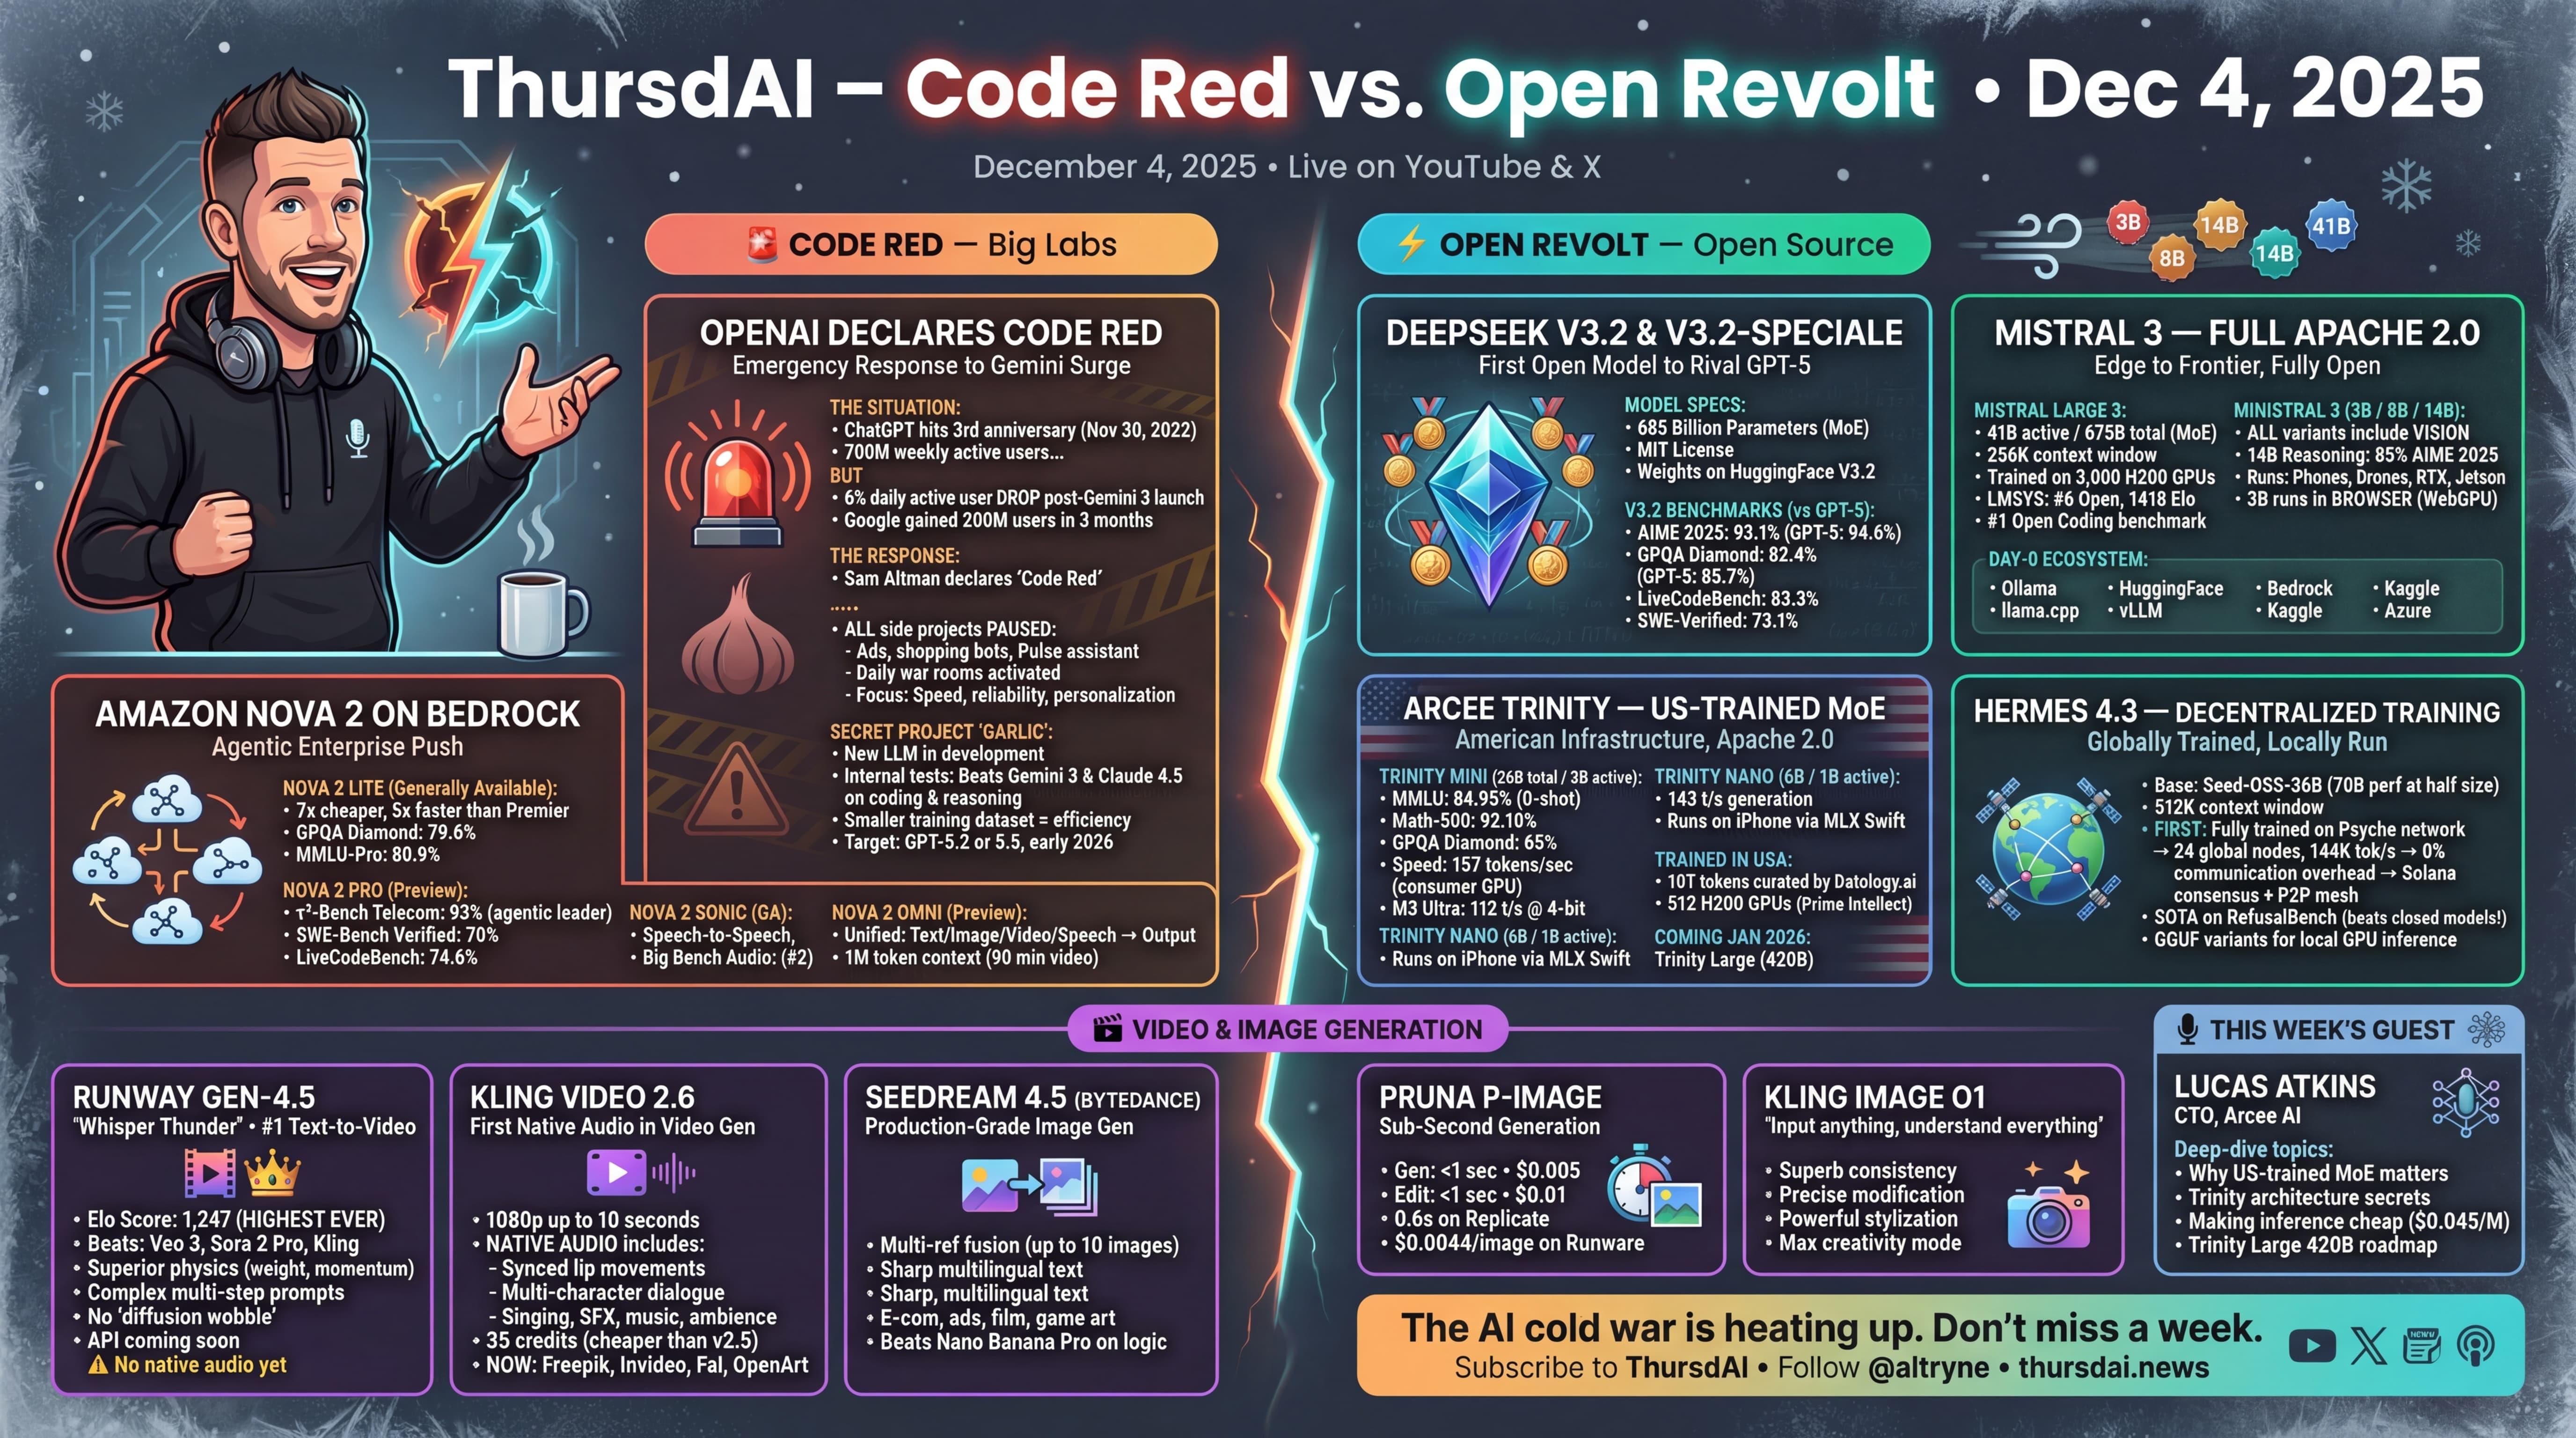
📆 ThursdAI - Dec 4, 2025 - DeepSeek V3.2 Goes Gold Medal, Mistral Returns to Apache 2.0, OpenAI Hits Code Red, and US-Trained MOEs Are Back!
Hey yall, Alex here 🫡 Welcome to the first ThursdAI of December! Snow is falling in Colorado, and AI releases are falling even harder. This week was genuinely one of those “drink from the firehose” weeks where every time I refreshed my timeline, another massive release had dropped.We kicked off the show asking our co-hosts for their top AI pick of the week, and the answers were all over the map: Wolfram was excited about Mistral’s return to Apache 2.0, Yam couldn’t stop talking about Claude Opus 4.5 after a full week of using it, and Nisten came out of left field with an AWQ quantization of Prime Intellect’s model that apparently runs incredibly fast on a single GPU. As for me? I’m torn between Opus 4.5 (which literally fixed bugs that Gemini 3 created in my code) and DeepSeek’s gold-medal winning reasoning model.Speaking of which, let’s dive into what happened this week, starting with the open source stuff that’s been absolutely cooking. Open Source LLMsDeepSeek V3.2: The Whale Returns with Gold MedalsThe whale is back, folks! DeepSeek released two major updates this week: V3.2 and V3.2-Speciale. And these aren’t incremental improvements—we’re talking about an open reasoning-first model that’s rivaling GPT-5 and Gemini 3 Pro with actual gold medal Olympiad wins.Here’s what makes this release absolutely wild: DeepSeek V3.2-Speciale is achieving 96% on AIME versus 94% for GPT-5 High. It’s getting gold medals on IMO (35/42), CMO, ICPC (10/12), and IOI (492/600). This is a 685 billion parameter MOE model with MIT license, and it literally broke the benchmark graph on HMMT 2025—the score was so high it went outside the chart boundaries. That’s how you DeepSeek, basically.But it’s not just about reasoning. The regular V3.2 (not Speciale) is absolutely crushing it on agentic benchmarks: 73.1% on SWE-Bench Verified, first open model over 35% on Tool Decathlon, and 80.3% on τ²-bench. It’s now the second most intelligent open weights model and ranks ahead of Grok 4 and Claude Sonnet 4.5 on Artificial Analysis.The price is what really makes this insane: 28 cents per million tokens on OpenRouter. That’s absolutely ridiculous for this level of performance. They’ve also introduced DeepSeek Sparse Attention (DSA) which gives you 2-3x cheaper 128K inference without performance loss. LDJ pointed out on the show that he appreciates how transparent they’re being about not quite matching Gemini 3’s efficiency on reasoning tokens, but it’s open source and incredibly cheap.One thing to note: V3.2-Speciale doesn’t support tool calling. As Wolfram pointed out from the model card, it’s “designed exclusively for deep reasoning tasks.” So if you need agentic capabilities, stick with the regular V3.2.Check out the full release on Hugging Face or read the announcement.Mistral 3: Europe’s Favorite AI Lab Returns to Apache 2.0Mistral is back, and they’re back with fully open Apache 2.0 licenses across the board! This is huge news for the open source community. They released two major things this week: Mistral Large 3 and the Ministral 3 family of small models.Mistral Large 3 is a 675 billion parameter MOE with 41 billion active parameters and a quarter million (256K) context window, trained on 3,000 H200 GPUs. There’s been some debate about this model’s performance, and I want to address the elephant in the room: some folks saw a screenshot showing Mistral Large 3 very far down on Artificial Analysis and started dunking on it. But here’s the key context that Merve from Hugging Face pointed out—this is the only non-reasoning model on that chart besides GPT 5.1. When you compare it to other instruction-tuned (non-reasoning) models, it’s actually performing quite well, sitting at #6 among open models on LMSys Arena.Nisten checked LM Arena and confirmed that on coding specifically, Mistral Large 3 is scoring as one of the best open source coding models available. Yam made an important point that we should compare Mistral to other open source players like Qwen and DeepSeek rather than to closed models—and in that context, this is a solid release.But the real stars of this release are the Ministral 3 small models: 3B, 8B, and 14B, all with vision capabilities. These are edge-optimized, multimodal, and the 3B actually runs completely in the browser with WebGPU using transformers.js. The 14B reasoning variant achieves 85% on AIME 2025, which is state-of-the-art for its size class. Wolfram confirmed that the multilingual performance is excellent, particularly for German.There’s been some discussion about whether Mistral Large 3 is a DeepSeek finetune given the architectural similarities, but Mistral claims these are fully trained models. As Nisten noted, even if they used similar architecture (which is Apache 2.0 licensed), there’s nothing wrong with that—it’s an excellent architecture that works. Lucas Atkins later confirmed on the show that “Mistral Large looks fantastic... it is DeepSeek through and through architecture wise. But Kimi also d