
ThursdAI - The top AI news from the past week
174 episodes — Page 4 of 4
🦃 ThursdAI Thanksgiving special - OpenAI ctrl+altman+delete, Stable Video, Claude 2.1 (200K), the (continuous) rise of OSS LLMs & more AI news
ThursdAI TL;DR - November 23 TL;DR of all topics covered: * OpenAI Drama* Sam... there and back again. * Open Source LLMs * Intel finetuned Mistral and is on top of leaderboards with neural-chat-7B (Thread, HF, Github)* And trained on new Habana hardware! * Yi-34B Chat - 4-bit and 8-bit chat finetune for Yi-34 (Card, Demo)* Microsoft released Orca 2 - it's underwhelming (Thread from Eric, HF, Blog)* System2Attention - Uses LLM reasons to figure out what to attend to (Thread, Paper)* Lookahead decoding to speed up LLM inference by 2x (Lmsys blog, Github)* Big CO LLMs + APIs* Anthropic Claude 2.1 - 200K context, 2x less hallucinations, tool use finetune (Announcement, Blog, Ctx length analysis)* InflectionAI releases Inflection 2 (Announcement, Blog)* Bard can summarize youtube videos now * Vision* Video-LLaVa - open source video understanding (Github, demo)* Voice* OpenAI added voice for free accounts (Announcement) * 11Labs released speech to speech including intonations (Announcement, Demo)* Whisper.cpp - with OpenAI like drop in replacement API server (Announcement)* AI Art & Diffusion* Stable Video Diffusion - Stability releases text2video and img2video (Announcement, Try it)* Zip-Lora - combine diffusion LORAs together - Nataniel Ruiz (Annoucement, Blog)* Some folks are getting NERFs out from SVD (Stable Video Diffusion) (link)* LCM everywhere - In Krea, In Tl;Draw, in Fal, on Hugging Face* Tools* Screenshot-to-html (Thread, Github)Ctrl+Altman+Delete weekendIf you're subscribed to ThursdAI, then you most likely either know the full story of the crazy OpenAI weekend. Here's my super super quick summary (and if you want a full blow-by-blow coverage, Ben Tossel as a great one here)Sam got fired, Greg quit, Mira flipped then Ilya Flipped. Satya played some chess, there was an interim CEO for 54 hours, all employees sent hearts then signed a letter, neither of the 3 co-fouders are on the board anymore, Ilya's still there, company is aligned AF going into 24 and Satya is somehow a winner in all this.The biggest winner to me is open source folks, who got tons of interest suddenly, and specifically, everyone seems to converge on the OpenHermes 2.5 Mistral from Teknium (Nous Research) as the best model around! However, I want to shoutout the incredible cohesion that came out of the folks in OpenAI, I created a list of around 120 employees on X and all of them were basically aligned the whole weekend, from ❤️ sending to signing the letter, to showing how happy they are Sam and Greg are back! YayThis Week's Buzz from WandB (aka what I learned this week)As I’m still onboarding, the main things I’ve learned this week, is how transparent Weights & Biases is internally. During the whole OAI saga, Lukas the co-founder sent a long message in Slack, addressing the situation (after all, OpenAI is a big customer for W&B, GPT-4 was trained on W&B end to end) and answering questions about how this situation can affect us and the business. Additionally, another co-founder, Shawn Lewis shared a recording of his update to the BOD of WandB, about out progress on the product side. It’s really really refreshing to see this information voluntarily shared with the company 👏 The first core value of W&B is Honesty, and it includes transparency outside of matters like personal HR stuff, and after hearing about this during onboarding, it’s great to see that the company lives it in practice 👏 I also learned that almost every loss curve image that you see on X, is a W&B dashboard screenshot ✨ and while we do have a share functionality, it’s not built for viral X sharing haha so in the spirit of transparency, here’s a video I recorded and shared with product + feature request to make these screenshot way more attractive + clear that it’s W&B Open Source LLMs Intel passes Hermes on SOTA with a DPO Mistral Finetune (Thread, Hugging Face, Github)Yes, that intel, the... oldest computing company in the world, not only comes out strong with the best (on benchmarks) open source LLM, it also does DPO, and has been trained on a completely new hardware + Apache 2 license! Here's Yam's TL;DR for the DPO (Direct Policy Optimization) technique: Given a prompt and a pair of completions, train the model to prefer one over the other. This model was trained on prompts from SlimOrca's dataset where each has one GPT-4 completion and one LLaMA-13B completion. The model trained to prefer GPT-4 over LLaMA-13B.Additionally, even tho there is custom hardware included here, Intel supports the HuggingFace trainer fully, and the whole repo is very clean and easy to understand, replicate and build things on top of (like LORA)LMSys Lookahead decoding (Lmsys, Github)This method significantly improves the output of LLMs, sometimes by more than 2x, using some jacobian notation (don't ask me) tricks. It's copmatible with HF transformers library! I hope this comes to open source tools like LLaMa.cpp soon! Big CO LLMs + APIsAnthropic Claude comes back with 2.1 featuring 2
📅 ThursdAI Nov 16 - Live AI art, MS copilots everywhere, EMUs from Meta, sketch-to-code from TLDraw, Capybara 34B and other AI news!
Hey yall, welcome to this special edition of ThursdAI. This is the first one that I'm sending in my new capacity as the AI Evangelist Weights & Biases (on the growth team)I made the announcement last week, but this week is my first official week at W&B, and oh boy... how humbled and excited I was to receive all the inspiring and supporting feedback from the community, friends, colleagues and family 🙇♂️ I promise to continue my mission of delivering AI news, positivity and excitement, and to be that one place where we stay up to date so you don't have to. This week we also had one of our biggest live recordings yet, with 900 folks tuned in so far 😮 and it was my pleasure to again to chat with folks who "made the news" so we had a brief interview with Steve Ruiz and Lou from TLDraw, about their incredible GPT-4 Vision enabled "make real" functionality and finally got to catch up with my good friend Idan Gazit who's heading the Github@Next team (the birthplace of Github Copilot) about how they see the future. So definitely definitely check out the full conversation! TL;DR of all topics covered: * Open Source LLMs * Nous Capybara 34B on top of Yi-34B (with 200K context length!) (Eval, HF) * Microsoft - Phi 2 will be open sourced (barely) (Announcement, Model)* HF adds finetune chain genealogy (Announcement)* Big CO LLMs + APIs* Microsoft - Everything is CoPilot (Summary, copilot.microsoft.com)* CoPilot for work and 365 (Blogpost)* CoPilot studio - low code "tools" builder for CoPilot + GPTs access (Thread)* OpenAI Assistants API cookbook (Link)* Vision* 🔥 TLdraw make real button - turn sketches into code in seconds with vision (Video, makereal.tldraw.com)* Humane Pin - Orders are out, shipping early 2024, multimodal AI agent on your lapel (* )* Voice & Audio* 🔥 DeepMind (Youtube) - Lyria high quality music generations you can HUM into (Announcement)* EmotiVoice - 2000 different voices with emotional synthesis (Github)* Whisper V3 is top of the charts again (Announcement, Leaderboard, Github)* AI Art & Diffusion* 🔥 Real-time LCM (latent consistency model) AI art is blowing up (Krea, Fal Demo)* 🔥 Meta announces EMU-video and EMU-edit (Thread, Blog)* Runway motion brush (Announcement)* Agents* Alex's Visual Weather GPT (Announcement, Demo) * AutoGen, Microsoft agents framework is now supporting assistants API (Announcement)* Tools* Gobble Bot - scrape everything into 1 long file for GPT consumption (Announcement, Link)* ReTool state of AI 2023 - https://retool.com/reports/state-of-ai-2023* Notion Q&A AI - search through a company Notion and QA things (announcement)* GPTs shortlinks + analytics from Steven Tey (https://chatg.pt* ) This Week's Buzz from WandB (aka what I learned this week)Introducing a new section in the newsletter called "The Week's Buzz from WandB" (AKA What I Learned This Week).As someone who joined Weights and Biases without prior knowledge of the product, I'll be learning a lot. I'll also share my knowledge here, so you can learn alongside me. Here's what I learned this week:The most important things I learned this week is just how prevelant and how much of a leader Weights&Biases is. W&B main product is used by most of the foundation LLM trainers including OpenAI. In fact GPT-4 was completely trained on W&B!It's used by pretty much everyone besides Google. In addition to that it's not only about LLMs, W&B products are used to train models in many many different areas of the industry. Some incredible examples are a pesticide dispenser that's part of the John Deere tractors that only spreads pesticides onto weeds and not actual produce. And Big Pharma who's using W&B to help create better drugs that are now in trial. And it's just incredible how much machine learning that's outside of just LLMs is there. But also I'm absolutely floored by just the amount of ubiquity that W&B has in the LLM World.W&B has two main products, Models & Prompts, Prompts is a newer one, and we're going to dig into both of these more next week! Additionally, it's striking how many AI Engineers, API users such as myself and many of my friends, have no idea of who W&B even is, of if they do, they never used it!Well, that's what I'm here to change, so stay tuned! Open source & LLMsIn the open source corner, we have the first Nous fine-tune of Yi-34B, which is a great model that we've covered in the last episode and now is fine-tuned with the Capybara dataset by ThursdAI cohost, LDJ! Not only is that a great model, it now tops the charts for the resident reviewer we WolframRavenwolf on /r/LocalLLama (and X) Additionally, Open-Hermes 2.5 7B from Teknium is now second place on HuggingFace leaderboards, it was released recently but we haven't covered until now, I still think that Hermes is one of the more capable local models you can get! Also in open source this week, guess who loves it? Satya (and Microsoft) They love it so much that they not only created this awesome slide (altho, what's SLMs? Small Language Models?
📅 ThursdAI - OpenAI DevDay recap (also X.ai grōk, 01.ai 200K SOTA model, Humane AI pin) and a personal update from Alex 🎊
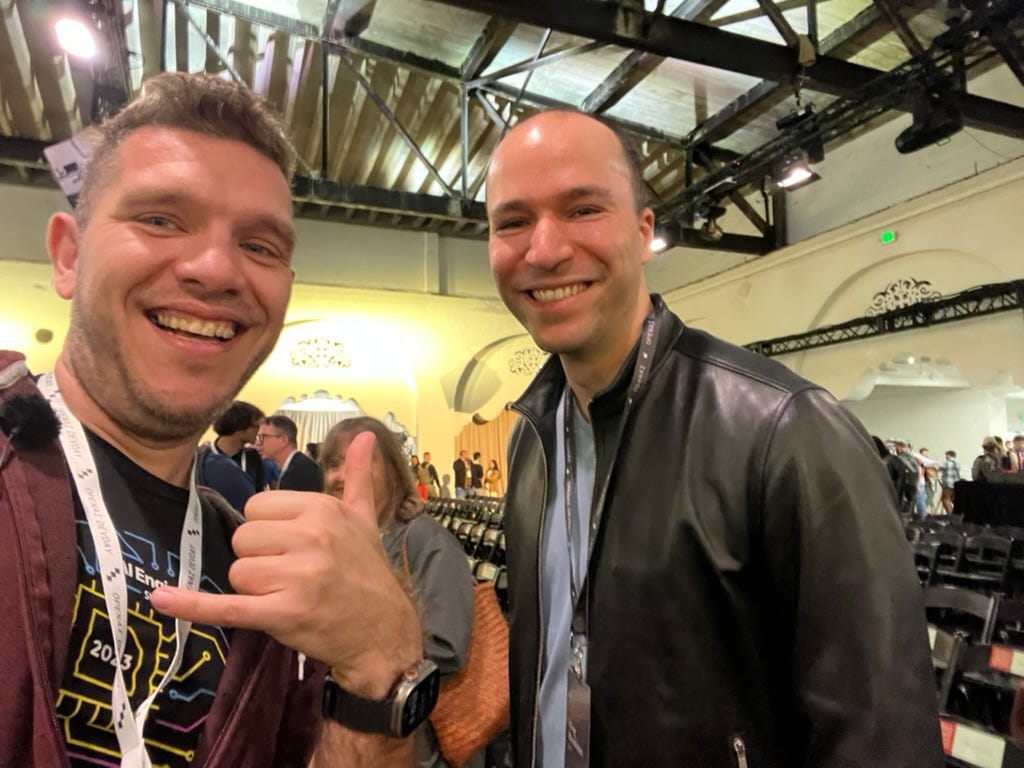
Hey everyone, this is Alex Volkov 👋 This week was an incredibly packed with news, started strong on Sunday with x.ai GrŌk announcement, Monday with all the releases during OpenAI Dev Day, then topped of with Github Universe Copilot announcements, and to top it all of, we postponed the live recording to see what hu.ma.ne has in store for us as AI devices go (Finally announced Pin with all the features) In between we had a new AI Unicorn from HongKong called Yi from 01.ai which dropped a new SOTA 34B model with a whopping 200K context window and a commercial license by ex-Google China lead Kai Fu Lee.Above all, this week was a monumental for me personally, ThursdAI has been a passion project for the longest time (240 days), and it led me to incredible places, like being invited to ai.engineer summit to do media, then getting invited to OpenAI Dev Day (to also do podcasting from there), interview and befriend folks from HuggingFace, Github, Adobe, Google, OpenAI and of course open source friends like Nous Research, Alignment Labs, and interview authors of papers, hackers of projects, and fine-tuners and of course all of you, who tune in from week to week 🙏 Thank you!It's all been so humbling and fun, which makes me ever more excited to share the next chapter. Starting Monday I'm joining Weights & Biases as an AI Evangelist! 🎊I couldn't be more excited to continue ThursdAI mission, of spreading knowledge about AI, connecting between the AI engineers and the fine-tuners, the Data Scientists and the GEN AI folks, the super advanced cutting edge stuff, and the folks who fear AI with the backing of such an incredible and important company in the AI space. ThursdAI will continue as a X space, newsletter and podcast, as we'll gradually find a common voice, and continue bringing folks awareness of WandB incredible brand to newer developers, products and communities. Expect more on this very soon! Ok now to the actual AI news 😅 TL;DR of all topics covered: * OpenAI Dev Day* GPT-4 Turbo with 128K context, 3x cheaper than GPT-4* Assistant API - OpenAI's new Agent API, with retrieval memory, code interpreter, function calling, JSON mode * GPTs - Shareable, configurable GPT agents with memory, code interpreter, DALL-E, Browsing, custom instructions and actions* Privacy Shield - Open AI lawyers will protect you from copyright lawsuits * Dev Day emergency pod with Latent Space with Swyx, Allesio, Simon and Me! (Listen)* OpenSource LLMs * 01 launches YI-34B, a 200K context window model commercially licensed and it tops all HuggingFace leaderboards across all sizes (Announcement)* Vision* GPT-4 Vision API finally announced, rejoice, it's as incredible as we've imagined it to be* Voice* Open AI TTS models with 6 very-realistic, multilingual voices, no cloning tho* AI Art & Diffusion* Announcement)OpenAI Dev DaySo much to cover from OpenAI that this has it's own section today in the newsletter. I was lucky enough to get invited, and attend the first ever OpenAI developer conference (AKA Dev Day) and it was an absolute blast to attend. It was also incredible to attend it together with all 8.5 thousand of you who tuned into our live stream on X, as we were walking to the event, and then watched the keynote together (Thanks Ray for the restream) and talked with OpenAI folks about the updates. Huge shoutout to LDJ, Nisten, Ray, Phlo, Swyx and many other folks who held the space, while we were otherwise engaged with deep dives and meeting folks and doing interviews! So now for some actual reporting! What did we get from OpenAI? omg we got so much, as developers, as users (and as attendees, I will add more on this later) GPT4-Turbo with 128K context lengthThe major thing that was announced is a new model, GPT-4-turbo, which is supposedly faster than GPT-4, while being 3x cheaper (2x on output) and having a whopping 128K context length while also being more accurate (with significantly better recall and attention throughout this context length)With JSON mode and significantly improved function calling capabilities, updated cut-off time (April 2023), and higher rate limits, this new model is already being implemented across all the products and is a significant significant upgrade to many folksGPTs - A massive shift in agent landscapes by OpenAIAnother (semi-separate) thing that Sam talked about was the GPTs, their version of agents not to be confused with the Assistants API, which is also Agents, but for developers, and they are not the same and it's confusingGPTs I think is a genius marketing move by OpenAI and replaces Plugins (that didn't even meet product market fit) in many regards. GPTs are instances of well... GPT4-turbo, that you can create by simply chatting with BuilderGPT, and they can have their own custom instruction set, and capabilities that you can turn on and off, like browse the web with Bing, Create images with DALL-E and write and execute code with Code Interpreter (bye bye Advanced Data Analysis, we don't miss
📅 ThursdAI Nov 02 - ChatGPT "All Tools", Bidens AI EO, many OSS SOTA models, text 2 3D, distil-whisper and more AI news 🔥
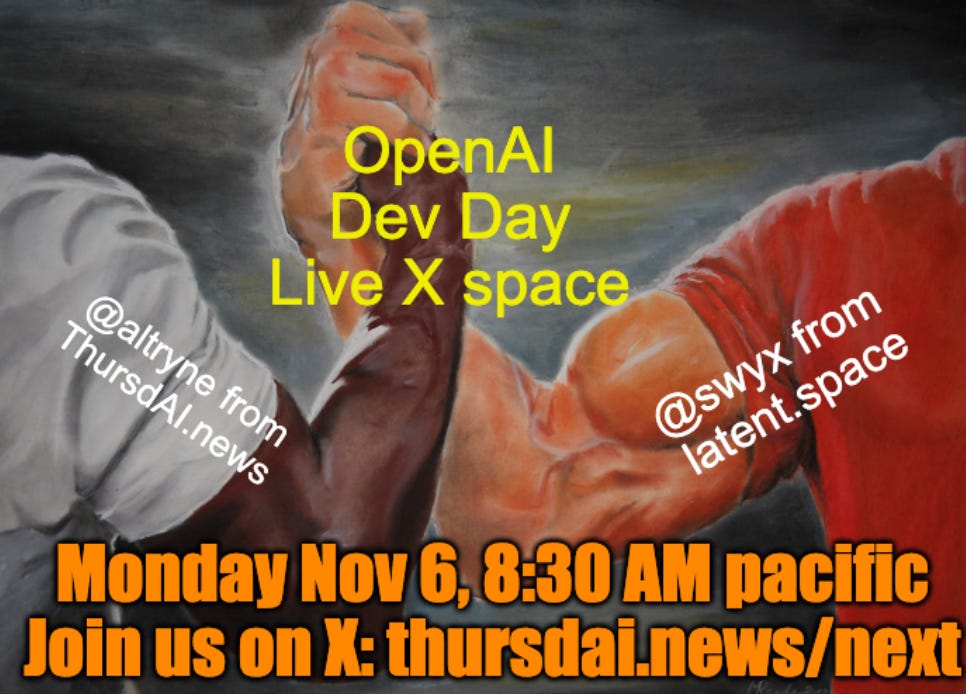
ThursdAI November 2ndHey everyone, welcome to yet another exciting ThursdAI. This week we have a special announcement, the co-host of and I will be hosting a shared X space live from Open AI Dev Day! Monday next week (and then will likely follow up with interviews, analysis and potentially a shared episode!)Make sure you set a reminder on X (https://thursdai.news/next) , we’re going to open the live stream early, 8:30am on Monday, and we’ll live stream all throughout the keynote! It’ll be super fun!Back to our regular schedule, we covered a LOT of stuff today, and again, were lucky enough to have BREAKING NEWS and the authors of said breaking news (VB from HuggingFace and Emozilla from Yarn-Mistral-128K) to join us and talk a little bit in depth about their updates![00:00:34] Recap of Previous Week's Topics[00:00:50] Discussion on AI Embeddings[00:01:49] Gradio Interface and its Applications[00:02:56] Gradio UI Hosting and its Advantages[00:04:50] Introduction of Baklava Model[00:05:11] Zenova's Input on Distilled Whisper[00:10:32] AI Regulation Week Discussion[00:24:14] ChatGPT new All Tools mode (aka MMIO)[00:35:45] Discussion on Multimodal Input and Output Models[00:36:55] BREAKING NEWS: Mistral YaRN 7B - 128K context window[00:37:02] Announcement of Mistral Yarn Release[00:46:47] Exploring the Limitations of Current AI Models[00:47:25] The Potential of Vicuna 16k and Memory Usage[00:49:43] The Impact of Apple's New Silicon on AI Models[00:51:23] Introduction to New Models from Nius Research[00:51:39] The Future of Long Context Inference[00:53:42] Exploring the Capabilities of Obsidian[00:54:29] The Future of Multimodality in AI[00:58:48] The Exciting Developments in CodeFusion[01:06:49] The Release of the Red Pajama V2 Dataset[01:12:07] The Introduction of Luma's Genie[01:16:37] Discussion on 3D Models and Stable Diffusion[01:17:08] Excitement about AI Art and Diffusion Models[01:17:48] Regulation of AI and OpenAI Developments[01:18:24] Guest Introduction: VB from Hug& Face[01:18:53] VB's Presentation on Distilled Whisper[01:21:54] Discussion on Distillation Concept[01:27:35] Insanely Fast Whisper Framework[01:32:32] Conclusion and RecapShow notes and links:* AI Regulation* Biden Executive Order on AI was signed (Full EO, Deep dive)* UK AI regulation forum (King AI speech, no really, Arthur from Mistral)* Mozilla - Joint statement on AI and openness (Sign the letter)* Open Source LLMs* Together AI releases RedPajama 2, 25x larger dataset (30T tokens) (Blog, X, HF)* Alignment Lab - OpenChat-3.5 a chatGPT beating open source model (HF)* Emozilla + Nous Research - Yarn-Mistral-7b-128k (and 64K) longest context window (Announcement, HF)* LDJ + Nous Research release Capybara 3B & 7B (Announcement, HF)* LDJ - Obsidian 3B - the smallest open source multi modal model (HF, Quantized)* Big CO LLMs + APIs* ChatGPT "all tools" MMIO mode - Combines vision, browsing, ADA and DALL-E into 1 model (Thread, Examples, System prompt)* Microsoft CodeFusion paper - a tiny (75M parameters) model beats a 20B GPT-3.5-turbo (Thread, ArXiv)* Voice* Hugging Face - Distill whisper - 2x smaller english only version of Whisper (X, paper, code)* AI Art & Diffusion & 3D* Luma - text-to-3D Genie bot (Announcement, Try it)* Stable 3D & Sky changerAI Regulation IS HERELook, to be very frank, I want to focus ThursdAI on all the news that we're getting from week to week, and to bring a positive outlook, so politics, doomerism, and regulation weren't on the roadmap, however, with weeks like these, it's really hard to ignore, so let's talk about this.President Biden signed an Executive Order, citing the old, wartime era Defence Production act (looks like the US gov. also has "one weird trick" to make the gov move faster) and it wasn't as bombastic as people thought. X being X, there has been so many takes pre this executive order even releasing about regulatory capture being done by the big AI labs, about how open source is no longer going to be possible, and if you visit Mark Andressen feed you'll see he's only reposting AI generated memes to the tune of "don't tread on me" about GPU and compute rights.However, at least on the face of it, this executive order was mild, and discussed many AI risks and focused on regulating models from huge compute runs (~28M H100 hours // $50M dollars worth). Here's the relevant section.Many in the open source community reacted to the flops limitation with a response that it's very much a lobbyist based decision, and that the application should be regulated, not only the compute.There's much more to say about the EO, if you want to dig deeper, I strongly recommend this piece from AI Snake oil :and check out Yan Lecun's whole feed.UK AI safety summit in Bletchley ParkLook, did I ever expect to add the King of England into an AI weekly recap newsletter? Surely, if he was AI Art generated or something, not the real king, addressing the topic of AI safety!This video was played for the attendees of a few day AI sa
📅 ThursdAI Oct-26, Jina Embeddings SOTA, Gradio-Lite, Copilot crossed 100M paid devs, and more AI news
ThursdAI October 26thTimestamps and full transcript for your convinience## [00:00:00] Intro and brief updates## [00:02:00] Interview with Bo Weng, author of Jina Embeddings V2## [00:33:40] Hugging Face open sourcing a fast Text Embeddings## [00:36:52] Data Provenance Initiative at dataprovenance.org## [00:39:27] LocalLLama effort to compare 39 open source LLMs +## [00:53:13] Gradio Interview with Abubakar, Xenova, Yuichiro## [00:56:13] Gradio effects on the open source LLM ecosystem## [01:02:23] Gradio local URL via Gradio Proxy## [01:07:10] Local inference on device with Gradio - Lite## [01:14:02] Transformers.js integration with Gradio-lite## [01:28:00] Recap and bye byeHey everyone, welcome to ThursdAI, this is Alex Volkov, I'm very happy to bring you another weekly installment of 📅 ThursdAI.ThursdAI - Recaps of the most high signal AI weekly spaces is a reader-supported publication. To receive new posts and support my work, consider becoming a free or paid subscriber.TL;DR of all topics covered:* Open Source LLMs* JINA - jina-embeddings-v2 - First OSS embeddings models with 8K context (Announcement, HuggingFace)* Simon Willison guide to Embeddings (Blogpost)* Hugging Face - Text embeddings inference (X, Github)* Data Provenance Initiative - public audit of 1800+ datasets (Announcement)* Huge open source LLM comparison from r/LocalLLama (Thread)* Big CO LLMs + APIs* NVIDIA research new spin on Robot Learning (Announcement, Project)* Microsoft / Github - Copilot crossed 100 million paying users (X)* RememberAll open source (X)* Voice* Gladia announces multilingual near real time whisper transcriptions (X, Announcement)* AI Art & Diffusion* Segmind releases SSD-1B - 50% smaller and 60% faster version of SDXL (Blog, Hugging Face, Demo)* Prompt techniques* How to use seeds in DALL-E to add/remove objects from generations (by - Thread)This week was a mild one in terms of updates, believe it or not, we didn't get a new State of the art open source large language model this week, however, we did get a new state of the art Embeddings model from JinaAI (supporting 8K sequence length).We also had quite the quiet week from the big dogs, OpenAI is probably sitting on updates until Dev Day (which I'm going to cover for all of you, thanks to Logan for the invite), Google had some leaks about Gemini (we're waiting!) and another AI app builder thing, Apple is teasing new hardware (but nothing AI related) coming soon, and Microsoft / Github announced that CoPilot has 100 million paying users! (I tweeted this and Idan Gazit, Sr. Director GithubNext where Copilot was born, tweeted that "we're literally just getting started" and mentioned November 8th as... a date to watch, so mark your calendars for some craziness next two weeks)Additionally, we covered the Data provenance initiative that helps sort and validate licenses for over 1800 public datasets, a massive effort led by Shayne Redford with assistance from many folks including friend of the pod Enrico Shippole, we also covered another massive evaluation effort by a user named WolframRavenwolf on the LocalLLama subreddit, that evaluated and compared 39 open source models and GPT4. Not surprisingly the best model right now is the one we covered last week, OpenHermes 7B from Teknium.Two additional updates were covered, one of them is Gladia AI, released their version of whisper over web-sockets, and I covered it on X with a reaction video, it allows developers to stream speech to text, with very low latency and it's multi-lingual as well, so if you're building an agent that folks can talk to, definitely give this a try, and finally, we covered SegMind SSD-1B, a distilled version of SDXL, making it 50% smaller in size and 60% faster in generation speed (you can play with it here)This week I was lucky to host 2 deep dive conversations, one with Bo Wang, from Jina AI, and we covered embeddings, vector latent spaces, dimensionality, and how they retrained BERT to allow for longer sequence length, it was a fascinating conversation, even if you don't understand what embeddings are, it's well worth a listen.And in the second part, I had the pleasure to have Abubakar Abid, head of Gradio at Hugging Face, to talk about Gradio, it's effect on the open source community, and then joined by Yuichiro and Xenova to talk about the next iteration of Gradio, called Gradio-lite that runs completely within the browser, no server required.A fascinating conversation, if you're a machine learning engineer, AI engineer, or just someone who is interested in this field, we covered a LOT of ground, including Emscripten, python in the browser, Gradio as a tool for ML, webGPU and much more.I hope you enjoy this deep dive episode with 2 authors of the updates this week, and hope to see you in the next one.P.S - if you've been participating in the emoji of the week, and have read all the way up to here, your emoji of the week is 🦾, please reply or DM me with it 👀Timestamps and full transcript for yo
🔥 ThursdAI Oct 19 - Adept Fuyu multimodal, Pi has internet access, Mojo works on macs, Baidu announces ERNIE in all apps & more AI news
Hey friends, welcome to ThursdAI Oct - 19. Here’s everything we covered + a little deep dive after the TL;DR for those who like extra credit. ThursdAI - If you like staying up to date, join our communityAlso, here’s the reason why the newsletter is a bit delayed today, I played with Riffusion to try and get a cool song for ThursdAI 😂ThursdAI October 19thTL;DR of all topics covered: * Open Source MLLMs * Adept open sources Fuyu 8B - multi modal trained on understanding charts and UI (Announcement, Hugging face, Demo)* Teknium releases Open Hermes 2 on Mistral 7B (Announcement, Model)* NEFTune - a "one simple trick" to get higher quality finetunes by adding noise (Thread, Github)* Mistral is on fire, most fine-tunes are on top of Mistral now* Big CO LLMs + APIs* Inflection Pi got internet access & New therapy mode (Announcement)* Mojo 🔥 is working on Apple silicon Macs and has LLaMa.cpp level performance (Announcement, Performance thread)* Anthropic Claude.ai is rolled out to additional 95 countries (Announcement) * Baidu AI announcements - ERNIE 4, multimodal foundational model, integrated with many applications (Announcement, Thread)* Vision* Meta is decoding brain activity in near real time using non intrusive MEG (Announcement, Blog, Paper)* Baidu YunYiduo drive - Can use text prompts to extract precise frames from video, and summarize videos, transcribe and add subtitles. (Announcement)* Voice & Audio* Near real time voice generation with play.ht - under 300ms (Announcement)* I'm having a lot of fun with Airpods + chatGPT voice (X)* Riffusion - generate short songs with sound and singing (Riffusion, X)* AI Art & Diffusion* Adobe releases Firefly 2 - lifelike and realistic images, generative match, prompt remix and prompt suggestions (X, Firefly)DALL-E 3 is now available to all chatGPT Plus uses (Announcement, Research paper!) * Tools* LMStudio - a great and easy way to download models and run on M1 straight on your mac (Download)* Other* ThursdAI is adhering to the techno-optimist manifesto by Pmarca (Link)Open source mLLMsWelcome to multimodal future with Fuyu 8B from AdeptWe've seen and covered many multi-modal models before, and in fact, most of them will start being multimodal, so get ready to say "MLLMs" or... we come up with something better. Most of them so far have been pretty heavy, IDEFICS was 80B parameters etc' This week we received a new, 8B multi modal with great OCR abilities from Adept, the same guys who gave us Persimmon 8B a few weeks ago, in fact, Fuyu is a type of persimmon tree (we see you Adept!)In the podcast I talked about having 2 separate benchmarks for myself, one for chatGPT or any MultiModal coming from huge companies, and another for open source/tiny models. Given that Fuyu is a tiny model, it's quite impressive! It's OCR capabilities are impressive, and the QA is really on point (as well as captioning)An interesting thing about FuYu architecture is, because it doesn't use the traditional vision encoders, it can scale to arbitrary image sizes and resolutions, and is really fast (large image responses under 100ms)Additionally, during the release of Fuyu, Arushi from Adept authored a thread about visualQA evaluation datasets are, which... they really are bad, and I hope we get better ones! NEFTune - 1 weird trick of adding noise to embeddings makes models better (announcement thread)If you guys remember, a "this one weird trick" was discovered by KaiokenDev back in June, to extend the context window of LLaMa models, which then turned into RoPE scaling and YaRN scaling (which we covered in a special episode with the authors) Well, now we have a similar "1 weird trick" that by just adding some noise to embeddings at training time, the model performance can grow by up to 25%! The results very per dataset of course, however, considering how easy it is to try, literally: It's as simple as doing this in your forward pass if training: return orig_embed(x) + noise else: return orig_embed(x)We should be happy that the "free lunch" tricks like this exist. Notably, we had a great guest, Wing Lian the maintainer of Axolotl, a very popular tool to streamline fine-tuning, chime in and say that in his tests, and among the discord folks, they couldn't reproduce some of these claims (as they are adding everything that's super cool and beneficial for finetuners to their library) so it remains to be seen how far this "trick" scales, and what else needed to be done here. Similarly, back when the context extend trick was discovered, there was a lot of debates about it's effectiveness from Ofir Press (author of ALiBi, another context scaling methond) and futher iterations of the trick made into a paper and a robust method, so this develompment is indeed exciting! Mojo 🔥 now supports Apple silicon Macs and has LLaMa.cpp level performance!I've been waiting for this day! We've covered Mojo from Modular a couple of times and it seems that the promise behind it starts to materialize. Modular promises
A week of horror, an AI conference of contrasts
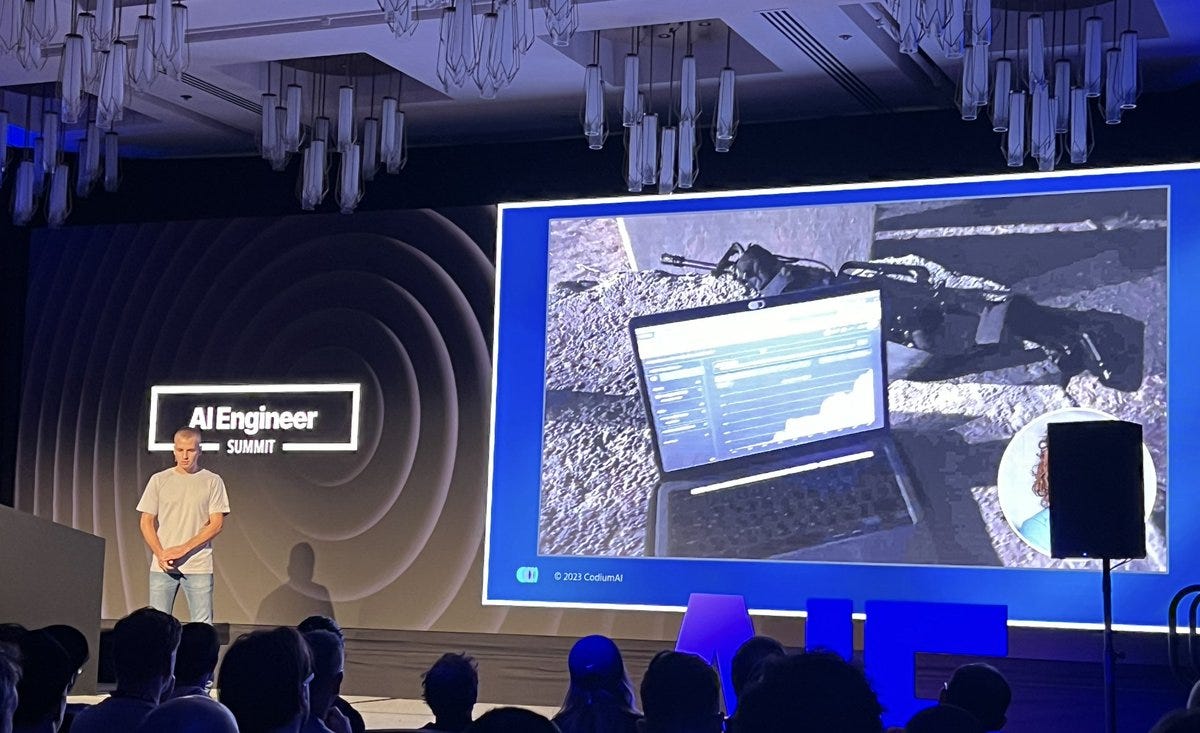
A week of horror, an AI conference of contrastsHi, this is Alex. In the podcast this week, you'll hear my conversation with Miguel, a new friend I made in AI.engineer event, and then a recap of the whole Ai.engineer event I had with Swyx after the end. This newsletter is a difficult one for me to write, honestly, I wanted to skip this one entirely, struggling to fit the current events into my platform and the AI narrative, however, decided to write one anyway, as the events of the last week have merged into 1 for me in a flurry of contrasts. Contrast 1 - Innovation vs DestructionI was invited (among a few other Israelis or Israeli-Americans) to the ai.engineer summit in SF, to celebrate the rise of the AI engineer, and I was looking forward to that very much. Meeting many of you (Shoutout to everyone who listens to ThursdAI who I've met face to face!) and talking to new friends of the pod, interviewing speakers, meeting and making connections was a dream come true. However a few days before the conference began, in a stark contrast to this dream, I had to call my mom, who was sheltering, 20km from the Gaza strip border, to ask if our friends and family are alive and accounted for, and to hear sirens as rockets flying above her head, as Hamas terrorists murder, pillage and kidnap, in what seems to be the 10x equivalent of 9/11 terror attack, relative to population size. I grew up in Ashkelon, rocket attacks are nothing new to me, we've learned to live with them (thank you Iron Dome heroes) but this was something else entirely, a new world of terror. So back to the conference, given that there's not a lot to be gained by doom scrolling, and watching (basically snuff) films coming out of the region, given that all my friends and family were accounted for, I decided to not give the terrorists what they want (which is to get people in state of terror) and instead to choose to have compassion, without empathy towards the situation and not bring sadness to every conversation I had there (over 200 I think) So participating at an AI event, which hosts and celebrates folks who are literally at the pinnacle of innovation, building the future, using all the latest tools while also hurting and holding the dear ones in my thoughts was a very stark contrast between past and future, and huge credit goes to Dedy Kredo, CTO of Codium, who was in the same position, and gave a hell of a talk, with a kick-ass (no backup recording!) demo live, and then shared this image: This is his co-founder, Itamar, who was called to reserve duty to protect his family and country, sitting with his rifle and his dashboard, seeing destruction + creation, past and future, negativity and positivity all at once. As Dedy masterfully said, we will prevail 🙏 Contrast 2 - Progress // FearAt the event, Swyx and Benjamin gave me a media pass and a free reign, and I asked to be teamed with a camera-person to go around the event and do some (not live) interviews. I was teamed with the lovely Stacey, from Chico, CA. Stacey has nothing to do with AI, in fact she's a wedding photographer, however she definitely listened with interest to the interviews I was holding, and to speakers on stage. While we were taking a break, I looked out the window, and saw a driverless car (waymo) zip by, and since they only started operating after I left SF 3 years ago, I didn't yet have a chance to ride in one. So I asked Stacey and some other folks, if they'd like to go for a ride, and to my complete bewilderement, Stacey said "no 😳" and when I asked why not, she didn't want to admin but then said that it's scary. This struck me and since that moment, I've had as many conversations with Stacey as I had with other folks who came to be AI.engineers, since this was such a stark contrast between progress and fear. I basically was walking, almost hand in hand, with a person who doesn't use or understand AI, and fears it, amongst the folks who are building the future, exist at the pinnacle of innovation and discuss how to connect more AI to more AI, and how to build complete autonomous agents to augment human productivity and bring about the world of abundance. This contrast was supported by several new friends of mine, who came to the AI.engineer and SF for the first time, from countries where English is not the first language, and where Waymo's are not zipping about on the streets freely, and it highlighted for me, how much of this shift is global, and how concentrated the decision making, the building, the innovation is, within the arena, SF, California and US. It's almost expected that AI is going to speak english, and to use/build it, we have to speak it as well, while most of the world doesn't use English as their first language. Contrast 3 - Technological // SpiritualThis contrast was intimate and personal to me. You see, this ai.engineer event was the first such sized event, professional, with folks talking "my language" since I had burned out this summer. If you've foll

📅 ThursdAI Oct 4 - AI wearables, Mistral fine-tunes, AI browsers and more AI news from last week
Boy am I glad that not all AI weeks are like last week, where we had so much news and so many things happening that I was barely able to take a breath for the week! I am very excited to bring you this newsletter from San Fancisco this week, the AI mecca, the arena, the place where there are so many AI events and hack-a-thons that I don’t actually know how people get any work done!On that topic, I’m in SF to participate in the AI.engineer (by swyx and Benjamin Dunphy) next week, to host spaces and interviews with the top AI folks in here, and to discuss with the audience, what is an AI engineer, if you have any questions you’d like me to ask, please comment with them and I’ll make sure I’ll try to answer. ThursdAI - subscribe eh? ↴Here’s a table of contents of everything we chatted about: [00:00:00] Intro and welcome[00:04:53] Alex in San Francisco - AI Engineer[00:07:32] Reka AI - Announcing a new multimodal Foundational model called Yasa-1 [00:12:42] Google adding Bard to Google Assistant[00:18:56] Where is Gemini? [00:23:06] Arc browser adding Arc Max with 5 new AI features[00:24:56] 5 seconds link AI generated previews[00:31:54] Ability to run LLMs on client side with WebGPU[00:39:28] Mistral is getting love from Open Source, [00:48:04] Mistral Open Orca 7B [00:58:28] Acknowledging the experts of ThursdAI[01:01:14] Voice based always on AI assistants[01:09:00] Airchat adds voice cloning based translation tech[01:14:23] Effects of AI voice cloning on society[01:21:32] SDXL IKEA LORA[01:23:17] Brief RecapShow notes: Big Co* Google - adding Bard to Google Assistant (Announcement)Come on google, just give us Gemini already!* Reka AI - Multimodal Yasa-1 from Yi Tay and team (Announcement)With Yi Tay from Flan/Bard fame as chief scientist! But I wasn’t able to test myself!* Arc - first browser AI features (My thread, Brief video review, Arc Invite)I love Arc, I recommend it to everyone I meet, now with AI preview features it’s even more a non brainer, strongly recommend if you like productivityOpen Source LLMs* Mistral vs LLaMa 2 boxing match (link)A fun little battle arena to select which responses you personally find better to see the difference between Mistral 7B and LLaMa 13B* Mistral-7B-OpenOrca (announcement)The folks from Alignment labs do it again! Great finetune that comes very close (98%) to LLaMa 70B on benchmarks! * SynthIA-7B-v1.3 - (Huggingface)An uncensored finetune on top of Mistral that Reddit claims is a great model, especially since a chain of thought is somehow built in apparentlyVISION* Radiologists thread about GPT-4 V taking over radiology (or maybe not?) (Thread)Voice* AirChat added voice clone + translation features (Room, Demo)I’ve been an avid AirChat user (It’s Naval’s social media platform that’s voice based) for a while, and am very excited they are destroying language barriers with this feature! * Tab was revealed in a great demo by Avi Schiffman (Demo)Go Avi! Rooting for you brother, competition makes folk stronger!* Rewind announced Rewind Pendant (Announcement)I ordered one, but Rewind didn’t announce a date of when this hits the market, going to be interesting to see how well they do!Ai Art and Diffusion - IKEA Lora generate IKEA style tutorials for everything with SDXL (Announcement, HuggingFace)* DALL-E3 seems to be available to all Plus members nowThis weeks pod was generated by talking to chatGPT, it’s so fun, you gotta try it!No longer breakdown this week ,but we covered a bunch of it in the show, and I highly recommend listening to it!Don’t forget to follow me on X to be aware of the spaces live from ai.engineer event in SF, the conference will be live-streamed as well on youtube! See you next week 🫡 ThursdAI - Recaps of the most high signal AI weekly spaces is a reader-supported publication. To receive new posts and support my work, consider becoming a free or paid subscriber. This is a public episode. If you'd like to discuss this with other subscribers or get access to bonus episodes, visit sub.thursdai.news/subscribe
📅🔥ThursdAI Sep 28 - GPT4 sees, speaks and surfs, Cloudflare AI on GPUs,Mistral 7B, Spotify Translates, Meta AI everywhere, Qwen14B & more AI news from this INSANE week
[00:00:00] Intro and welcome everyone[00:00:52] GPT4 - Vision from OpenAI[00:05:06] Safety concern with GPT4-V[00:09:18] GPT4 can talk and listen as well[00:12:15] Apple rumors, on device inference, and Siri[00:17:01] OpenAI Voice Cloning Tech used in Spotify to translate podcasts[00:19:44] On the risks of Voice Cloning tech being open sourced[00:26:07] Alex statement on purpose of ThursdAI[00:27:53] “AGI has been achieved internally”;[00:32:10] OpenAI, Jonny Ive and Masa are rumored to be working on a hardware device[00:33:51] Cloudflare AI - Serverless GPU on global scale[00:37:13] Cloudflare AI partnership with HuggingFace to allow you to run many models in your own[00:40:34] Cloudflare announced the Vectorize DB and embedings on edge[00:46:52] Cloudflare AI gateway - proxy LLM calls, caching, monitoring, statistics and fallback[00:51:15] Part 2 - intro an recap[00:54:14] Meta AI announcements, bringing AI agents to 3 billion people next month[00:56:22] Meta announces EMU image model to be integrated into AI agent on every platform[00:59:38] Meta RayBan glasses upgraded to spatial computing, with AI and camera access[01:00:39] On the topic os smart glasses, GoogleGlass, and the acceptance society wide to have[01:05:37] Safety and societal implications of everyone having glasses and recording everything[01:12:05] Part 3 - Open Source LLMs, Mistral, QWEN and CapyBara[01:21:27] Mistral 7B - SOTA 7B general model from MIstralAI[01:23:08] On the topic of releasing datasets publically and legal challenges with obtaining that[01:24:42] Mistral GOAT team giving us a torrrent link to a model with Apache 2 license.Truly, as I’ve been doing these coverages in one form or another for the past 9 months, and I don’t remember a week this full of updates, news, state of the art open source models and more.So, here’s to acceleration (and me finally facing the fact that I need a niche, and decide what I’ll update on and what I won’t, and also be transparent with all of you about it)On a separate note, this past two weeks, ThursdAI had exposure to Yann Lecun (RTs), joined on stage by VP of DevRel in Cloudflare and their counterpart in HuggingFace, CEO of Anaconda joined us on stage this episode and we’ve had the chief scientist of Mistral join in the audience 😮 ThursdAI really shapes to be the place where this community meets, and I couldn’t be more humbled and prouder of the show, the experts on stage that join from week to week, and the growing audience 🙇♂️ ok now let’s get to the actual news!ThursdAI - Weeks like this one highlight how important it is to stay up to date on many AI news, subscribe, I’ve got some cool stuff coming! 🔥All right so here’s everything we’ve covered on ThursdAI, September 28th:(and if you’d like to watch the episode video with the full transcript, it’s here for free):Show Notes + Links* Vision* 🔥 Open AI announces GPT4-Vision (Announcement, Model Card)* Meta glasses will be multimodal + AI assistant (Announcement)* Big Co + API updates* Cloudflare AI on workers, serverless GPU, Vector DB and AI monitoring (Announcement, Documentation)* Cloudflare announces partnerships with HuggingFace, Meta* Claude announces $4 billion investment from Amazon (Announcement)* Meta announces AI assistant across WhatsApp, Instagram* Open Source LLM* 🔥 Mistral AI releases - Mistral 7B - beating LLaMa2 13B (Announcement, Model)* Alibaba releases Qwen 14B - beating LLaMa2 34B (Paper, Model, Vision Chat)* AI Art & Diffusion* Meta shows off EMU - new image model* Still waiting for DALL-E3 😂* Tools* Spotify translation using Open AI voice cloning techVisionGPT 4-VisionI’ve been waiting for this release since March 14th (literally) and have been waiting and talking about this on literally every ThursdAI, and have been comparing every open source multimodality image model (IDEFICS, LlaVa, QWEN-VL, NeeVa and many others) to it, and none came close!And here we are, a brief rumor about the upcoming Gemini release (potentially a multimodal big model form Google) and OpenAi decided to release GPT-4V and it’s as incredible as we’ve been waiting for!From creating components from a picture of UI, to solving complex math problems with LaTex, to helping you get out of a parking ticket by looking at a picture of a complex set of parking rules, X folks report that GPT4-V is incredibly helpful and unlocks so many new possibilities!Can’t wait to get access, and most of all, for OpenAI to land this in the API for developers to start building this into products!On the pod, I’ve talked about how I personally don’t believe AGI can work without vision, and how personal AI assistants are going to need to see what I see to be really helpful in the real world, and we’re about to unlock this 👀 Super exciting.I will add this one last thing, here’s Ilya Sutskever, OpenAI chief scientist, talking about AI + Vision, and this connects with our previous reporting that GPT-4 is not natively multimodal (while we’re waiting for rumored Gobi)If y

📆 ThursdAI Sep 21 - OpenAI 🖼️ DALL-E 3, 3.5 Instruct & Gobi, Windows Copilot, Bard Extensions, WebGPU, ChainOfDensity, RemeberAll
Hey dear ThursdAI friends, as always I’m very excited to bring you this edition of ThursdAI, September 21st, which is packed full of goodness updates, great conversations with experts, breaking AI news and not 1 but 2 interviewsThursdAI - hey, psst, if you got here from X, dont’ worry, I don’t spam, but def. subscribe, you’ll be the coolest most up to date AI person you know!TL;DR of all topics covered* AI Art & Diffusion* 🖼️ DALL-E 3 - High quality art, with a built in brain (Announcement, Comparison to MJ)* Microsoft - Bing will have DALL-E 3 for free (Link)* Big Co LLMs + API updates* Microsoft - Windows Copilot 🔥 (Announcement, Demo)* OpenAI - GPT3.5 instruct (Link)* OpenAI - Finetuning UI (and finetuning your finetunes) (Annoucement, Link)* Google - Bard has extensions (twitter thread, video)* Open Source LLM* Glaive-coder-7B (Announcement, Model, Arena)* Yann Lecun testimony in front of US senate (Opening Statement, Thread)* Vision* Leak : OpenAI GPT4 Vision is coming soon + Gobi multimodal? (source)* Tools & Prompts* Chain of Density - a great summarizer prompt technique (Link, Paper, Playground)* Cardinal - AI infused product backlog (ProductHunt) * Glaive Arena - (link)AI Art + DiffusionDALL-E 3 - High quality art, with a built in brainDALL-E 2 was the reason I went hard into everything AI, I have a condition called Aphantasia, and when I learned that AI tools can help me regain a part of my brain that’s missing, I was in complete AWE. My first “AI” project was a chrome extension that injects prompts into DALL-E UI to help with prompt engineering. Well, now not only is my extension no longer needed, prompt engineering for AI art itself may die a slow death with DALL-E 3, which is going to be integrated into chatGPT interface, and chatGPT will be able to help you… chat with your creation, ask for modifications, alternative styles, and suggest different art directions! In addition to this incredible new interface, which I think is going to change the whole AI art field, the images are of mind-blowing quality, coherence of objects and scene elements is top notch, and the ability to tweak tiny detail really shines! Additional thing they really fixed is hands and text! Get ready for SO many memes coming at you! Btw, I created a conversational generation bot in my telegram chatGPT bot (before there was an API with stability diffusion and I can only remember how addicting this was!) and so did my friends from Krea :) so y’know… where’s our free dall-e credits OpenAI? 🤔 Just kidding, an additional awesome thing that now, DALL-E will be integrated into chatGPT plus subscription (and enterprise) and will refuse to generate any living artists art, and has a very very strong bias towards “clean” imagery. I wonder how fast will it come to an API, but this is incredible news!P.S - if you don’t want to pay for chatGPT, apparently DALL-E 3 conversational is already being rolled out as a free offering for Bing Chat 👀 Only for a certain percentage of users, but will be free for everyone going forward!Big Co LLM + API updatesCopilot, no longer just for code?Microsoft has announced some breaking news on #thursdai, where they confirmed that Copilot is now a piece of the new windows, and will live just a shortcut away from many many people. I think this is absolutely revolutionary, as just last week we chatted with Killian from Open Interpreter and having an LLM run things on my machine was one of the main reasons I was really excited about it! And now we have a full on, baked AI agent, inside the worlds most popular operating system, running for free, for all mom and pop windows computers out there, with just a shortcut away! Copilot will be a native part of many apps, not only windows, here’s an example of a powerpoint copilot! As we chatted on the pod, this will put AI into the hands of so so many people for whom opening the chatGPT interface is beyond them, and I find it incredibly exciting development! (I will not be switching to windows for it tho, will you?)Btw, shoutout to Mikhail Parakhin who lead the BingChat integration and is now in charge of the whole windows division! It shows how much dedication to AI Microsoft is showing and it really seems that they don’t want to “miss” this revolution like they did with mobile!OpenAI releases GPT 3.5 instruct turbo! For many of us, who used GPT3 APIs before it was cool (who has the 43 character API key 🙋♂️) we remember the “instruct” models where all the rage, and then OpenAI basically told everyone to switch to the much faster and more RLHFd chat interfaces.Well now, they brought GPT3.5 back, with instruct and turbo mode, it’s no longer a chat, it’s a completion model, that is apparently much better at chess? An additional interesting thing is, it includes logprobs in the response, so you can actually build much more interesting software (by asking for several responses and then looking at the log probabilities), for example, if you’re asking the model for a mul
📅 ThursdAI - Special interview with Killian Lukas, Author of Open Interpreter (23K Github stars for the first week) 🔥
This is a free preview of a paid episode. To hear more, visit sub.thursdai.newsHey! Welcome to this special ThursdAI Sunday episode. Today I'm excited to share my interview with Killian Lucas, the creator of Open Interpreter - an incredible new open source project that lets you run code via AI models like GPT-4 or local models like Llama on your own machine. Just a quick note, that while this episode is provided for free, premium subscribers enjoy the full write up including my examples of using Open Interpreter, the complete (manually edited) transcript and a video form of the pod for easier viewing, search, highlights and more. Here’s a trailer of that in case you consider subscribingIf you haven’t caught up with GPT-4 Code Interpreter yet (now renamed to Advanced Data Analytics), I joined Simon Willison and swyx when it first launched and we had a deep dive about it on Latent Space and even at the day of the release, we were already noticing a major restricting factor, Code Interpreter is amazing, but doesn’t have internet access, and can’t install new packages, or use new tools. An additional thing we immediately noticed was, the surface area of “what it can do” is vast, given it can write arbitrary code per request, it was very interesting to hear what other folks are using it for for inspiration, and “imagination unlock”.I started a hashtag called #codeinterpreterCan and have since documented many interesting use cases, like comitting to git, running a vector DB, convert audio & video to different formats, plot wind rose diagrams, run whisper and so much more. I personally have all but switched to Code Interpreter (ADA) as my main chatGPT tab, and it’s currently the reason I’m still paying the 20 bucks! Enter, Open interpreterJust a week after open sourcing Open Interpreter, it already has over 20,000 stars on GitHub and a huge following. You can follow Killian on Twitter and check out the Open Interpreter GitHub repo to learn more. Installing is as easy as pip install open-interpreter. (but do make sure to install and run it inside a venv or a conda env, trust me!) And then, you just.. ask for stuff! (and sometimes ask again as you’ll see in the below usage video)Specifically, highlighted in the incredible launch video, if you’re using a mac, Code Interpreter can write and run AppleScript, which can run and control most of the native apps and settings on your mac. Here’s a quick example I recorded while writing this post up, where I ask Open Interpreter to switch system to Dark mode, then I use it to actually help me extract all the chapters for this interview and cut a trailer together!

🔥 ThursdAI Sep 14 - Phi 1.5, Open XTTS 🗣️, Baichuan2 13B, Stable Audio 🎶, Nougat OCR and a personal life update from Alex
This is a free preview of a paid episode. To hear more, visit sub.thursdai.newsHey, welcome to yet another ThursdAI 🫡 This episode is special for several reasons, one of which, I shared a personal life update (got to listen to the episode to hear 😉) but also, this is the first time I took the mountainous challenge of fixing, editing and “video-fying” (is that a word?) our whole live recording! All 3 hours of it, were condensed, sliced, sound improved (x audio quality is really dogshit) and uploaded for your convenience. Please let me know what you think! Premium folks get access to the full podcast in audiogram format, and a full transcription with timestamps and speakers, here’s a sneak preview of how that looks, why not subscribe? 😮TL;DR of all topics covered* Open Source LLM* Microsoft Phi 1.5 - a tiny model that beats other 7B models (with a twist?) (Paper, Model)* Baichuan 7B / 13B - a bilingual (cn/en) model with highly crafted approach to training (Paper, Github) * Big Co LLMs + API updates* Nothing major this week* Voice & Audio* Stable Audio 🎶 - A new music generation model from Stability AI. (Website)* Coqui XTTS - an open source multilingual text to speech for training and generating a cloned voice (Github, HuggingFace)* AI Art & Diffusion* Würstchen v2 - A new super quick 1024 diffusion model (Announcement, Demo, Github)* DiffBIR - Towards Blind Image Restoration with Generative Diffusion Prior (Annoucement, Demo, Github)* Tools* Nougat from Meta - open-source OCR model that accurately scans books with heavy math/scientific notations (Announcement, Github, Paper)* GPT4All Vulkan from Nomic - Run LLMs on ANY consumer GPUs, not just NVIDIA (Announcement)* Nisten’s AI ISO disk - Announcement And here are timestamps and chapter/discussion topics for your convenience: [00:05:56] Phi 1.5 - 1.3B parameter model that closely matches Falcon & LLaMa 7B[00:09:08] Potential Data Contamination with Phi 1.5[00:10:11] Data Contamination unconfirmed[00:12:59] Tiny models are all the rage lately[00:16:23] Synthetic Dataset for Phi[00:18:37] Are we going to run out of training data?[00:20:31] Breaking News - Nougat - OCR from Meta[00:23:12] Nisten - AI ISO disk[00:29:08] Baichuan 7B - an immaculate Chinese model[00:36:16] Unique Loss Terms[00:38:37] Baichuan ByLingual and MultiLingual dataset[00:39:30] Finetunes of Baichuan[00:42:28] Philosophical questions in the dataset[00:45:21] Let's think step by step[00:48:17] Is breath related text in the original dataset?[00:50:27] Counterintuitive prompting for models with no breath[00:55:36] Idea spaces[00:59:59] Alex - Life update about ThursdAI[01:04:30] Stable Audio from Stability AI[01:17:23] GPT4ALL Vulkan[01:19:37] Coqui.ai releases XTTS - an open source TTS - interview With Josh Meyer[01:30:40] SummaryHere’s a full video of the pod, and a full transcription, and as always, 🧡 thank you for bring a paid subscriber, this really gives me the energy to keep going, get better guests, release dope podcast content, and have 3 hours spaces and then spend 7 hours editing 🔥
🔥🎙️ ThursdAI Sunday special - Extending LLaMa to 128K context window (2 orders of magnitude) with YaRN [Interview with authors]
This is a free preview of a paid episode. To hear more, visit sub.thursdai.newsHappy Sunday everyone, I am very excited to bring you this interview with the folks who took LLaMa 2 and made it LLoooooongMa!Extending LLaMa 2 context window from 4,000 to a whopping 128,000 tokens (Yarn-Llama-2-13b-128k on Hugging Face), these guys also came up with a paper called YaRN (Efficient Context Window Extension of Large Language Models) and showed that YaRN is not only requires 10x less tokens to create these long contexts, but also 2.5x less training steps! And, the models generalize so there’s now no need to collect extremely long sequences (think books length sequences) for the models to understand those context lengths. I have decided also to do something different (which took me half of Sunday so I can’t promise and am not committing to this format, but for the premium subscribers, you can now watch this interview with running Karaoke style subtitles and improved audio! This will be uploaded to Youtube in a week but aren’t you glad you subscribed and is getting this first?) Here’s a teaser preview: And here’s the chapter for your convenience (the only thing that’s ai generated 😂)0:00 - Introduction3:08 - Discussion of extending LLAMA2's context length from 4,000 tokens to 128,000 tokens using the YaRN method8:23 - Explanation of rope scaling for positional encodings in transformers13:21 - How the rope scaling idea allows for longer context through positional interpolation18:51 - Using in-context learning to train models on shorter sequences but still handle long contexts25:18 - Sourcing long-form data like books to train 128k token models31:21 - Whether future models will natively support longer contexts37:33 - New model from Adept with 16k context using rope scaling42:46 - Attention is quadratic - need better algorithms to make long context usable49:39 - Open source community pushing state of the art alongside big labs52:34 - Closing thoughtsAs always, full (manually edited) transcription (and this time a special video version!) is reserved for the premium subscribers, I promise it’ll be worth it, so why not .. y’know? skip a cup of coffee from SB and support ThursdAI?
ThursdAI Sep 7 - Falcon 180B 🦅 , 🔥 Mojo lang finally here, YaRN scaling interview, Many OSS models & more AI news
Hey ya’ll, welcome to yet another ThursdAI, this is Alex coming at you every ThursdAI, including a live recording this time! Which was incredible, we chatted about Falcon 180B,had a great interview in the end with 3 authors of the YaRN scaling paper and LLongMa 128K context, had 3 breaking news! in the middle, MOJO🔥 has been released and Adept released a LLaMa comparable OSS model (and friend of the pod) @reach_vb showed an open ASR leaderboard on hugging face! We also covered an incredible tiny model called StarCoder 1B that was finetuned by friend of the pod (who joined the space to talk to us about it!) As always, you can listen to the whole 3 hour long form conversation (raw, unedited) on our Zealous page (and add it to your podcatcher via this RSS) and this short-form pod is available on Apple, Spotify and everywhere. ThursdAI - Hey, if you enjoy these, how about subscribing for real? Would love to do this full time! Every paid subscriber is like a dear friend 🧡TL;DR of all topics covered* Open Source LLM* Falcon 180B announced by TIIUAE (Announcement, Demo)* YaRN scaling paper - scaling LlaMa to 128K context (link)* OpenHermes-13B from @teknium1 (link)* Persimmon-8B from Adept.AI (link)* Starcoder-1B-sft from @abacaj (link) * Big Co LLMs + API updates* OpenAI first ever Dev conference (link)* Claude announces a $20/mo Claude Pro tier (link)* Modular releases Mojo🔥 with 68,000x improvement over python (Link)* Vision* Real time deepfake with FaceFusion (link)* HeyGen released AI avatars and AI video translation with lipsync (link, translation announcement)* Voice* Open ASR (automatic speech recognition) leaderboard from HuggingFace (link)* Tools* LangChain Hub (re) launched * Open Interpreter (Announcement, Github)Open Source LLM🦅 Falcon 180B - The largest open source LLM to date (Announcement, Demo)The folks at the “Technology Innovation Institute” have open sourced the huge Falcon 180B, and have put it up on Hugging Face. Having previously open sourced Falcon 40B, the folks from TIIUAE have given us a huge model that beats (base) LLaMa 2 on several evaluations, if just slightly by a few percentages points. It’s huge, was trained on 3.5 trillion tokens and weights above 100GB as a file and requires 400GB for inference. Some folks were not as impressed with Falcon performance, given it’s parameter size is 2.5 those of LLaMa 2 (and likely it took a longer time to train) but the relative benchmarks is just a few percentages higher than LLaMa. It also boasts an embarrassingly low context window of just 2K tokens, and code was just 5% of it’s dataset, even though we already know that more code in the dataset, makes the models smarter! Georgi Gerganov is already running this model on his M2 Ultra because he’s the Goat, and co-host of ThursdAI spaces, Nisten, was able to run this model with CPU-only and with just 4GB of ram 🤯 We’re waiting for Nisten to post a Github on how to run this monsterous model on just CPU, because it’s incredible! However, given the Apache2 license and the fine-tuning community excitement about improving these open models, it’s an incredible feat. and we’re very happy that this was released! The complete open sourcing also matters in terms of geopolitics, this model was developed in the UAE, while in the US, the export of A100 GPUs was banned to the middle easy, and folks are talking about regulating foundational models, and this release, size and parameter model that’s coming out of the United Arab Emirates, for free, is going to definitely add to the discussion wether to regulate AI, open source and fine-tuning huge models! YaRN scaling LLaMa to 128K context windowLast week, just in time for ThursdAI, we posted about the release of Yarn-Llama-2-13b-128k, a whopping 32x improvement in context window size on top of the base LLaMa from the folks at Nous Research, Enrico Shippole, @theemozilla with the help of Eluether AI.This week, they released the YaRN: Efficient Context Window Extension of Large Language Models paper which uses Rotary Position Embeddings to stretch the context windows of transformer attention based LLMs significantly. We had friends of the pod Enrico Shippole, theemozilla (Jeff) and Bowen Peng on the twitter space and an special interview with them will be released on Sunday, if you’re interested in scaling and stretching context windows work, definitely subscribe for that episode, it was incredible! It’s great to see that their work is already applied into several places, including CodeLLaMa (which was released with 16K - 100K context) and the problem is now compute, basically, context windows can be stretched, and the models are able to generalize from smaller datasets, such that the next models are predicted to be released with infinite amount of context window, and it’ll depend on your hardware memory requirements.Persimmon-8B from AdeptAI (announcement, github)AdeptAI, the company behind Act-1, a foundational model for AI Agent that does browser driving,
ThursdAI Aug 24 - Seamless Voice Model, LLaMa Code, GPT3.5 FineTune API & IDEFICS vision model from HF
Hey everyone, this week has been incredible (isn’t every week?), and as I’m writing this, I had to pause and go check out breaking news about LLama code which was literally released on ThursdAI as I’m writing the summary! I think Meta deserves their own section in this ThursdAI update 👏A few reminders before we dive in, we now have a website (thursdai.news) which will have all the links to Apple, Spotify, Full recordings with transcripts and will soon have a calendar you can join to never miss a live space!This whole thing would have been possible without Yam, Nisten, Xenova , VB, Far El, LDJ and other expert speakers from different modalities who join and share their expertise from week to week, and there’s a convenient way to follow all of them now!TL;DR of all topics covered* Voice* Seamless M4T Model from Meta (demo)* Open Source LLM* LLaMa2 - code from Meta* Vision* IDEFICS - A multi modal text + image model from Hugging face* AI Art & Diffusion* 1 year of Stable Diffusion 🎂* IdeoGram* Big Co LLMs + API updates* GPT 3.5 Finetuninng API* AI Tools & Things* Cursor IDEVoiceSeamless M4t - A multi lingual, mutli tasking, multimodality voice model.To me, the absolute most mindblowing news of this week was Meta open sourcing (not fully, not commercially licensed) SeamlessM4TThis is a multi lingual model that takes speech (and/or text) can generate the following:* Text* Speech* Translated Text* Translated SpeechIn a single model! For comparison sake, I takes a whole pipeline with whisper and other translators in targum.video not to mention much bigger models, and not to mention I don’t actually generate speech!This incredible news got me giddy and excited so fast, not only because it simplifies and unifies so much of what I do into 1 model, and makes it faster and opens up additional capabilities, but also because I strongly believe in the vision that Language Barriers should not exist and that’s why I built Targum.Meta apparently also believes in this vision, and gave us an incredible new power unlock that understands 100 languages and does so multilingually without effort.Language barriers should not existDefinitely checkout the discussion in the podcast, where VB from the open source audio team on Hugging Face goes in deeper into the exciting implementation details of this model.Open Source LLMs🔥 LLaMa CodeWe were patient and we got it! Thank you Yann!Meta releases LLaMa Code, a LlaMa fine-tuned on coding tasks, including “in the middle” completion tasks, which are what copilot does, not just autocompleting code, but taking into account what’s surrounding the code it needs to generate.Available in 7B, 13B and 34B sizes, the largest model beats GPT3.5 on HumanEval, which is a metric for coding tasks. (you can try it here)In an interesting move, they also separately release a specific python finetuned versions, for python code specifically.Additional incredible thing is, it supports 100K context window of code, which is, a LOT of code. However it’s unlikely to be very useful in open source because of the compute requiredThey also give us instruction fine-tuned versions of these models, and recommend using them, since those are finetuned on being helpful to humans rather than just autocomplete code.Boasting impressive numbers, this is of course, just the beginning, the open source community of finetuners is salivating! This is what they were waiting for, can they finetune these new models to beat GPT-4? 🤔Nous updateFriends of the Pod LDJ and Teknium1 are releasing the latest 70B model of their Nous Hermes 2 70B model 👏* Nous-Puffin-70BWe’re waiting on metrics but it potentially beats chatGPT on a few tasks! Exciting times!Vision & Multi ModalityIDEFICS - a new 80B model from HuggingFace, was released after a years effort, and is quite quite good. We love vision multimodality here on ThursdAI, we’ve been covering it since we say that GPT-4 demo!IDEFICS is a an effort by hugging face to create a foundational model for multimodality, and it is currently the only visual language model of this scale (80 billion parameters) that is available in open-access.It’s made by fusing the vision transformer CLIP-VIT-H-14 and LLaMa 1, I bet LLaMa 2 is coming soon as well!And the best thing, it’s openly available and you can use it in your code with hugging face transformers library!It’s not perfect of course, and can hallucinate quite a bit, but it’s quite remarkable that we get these models weekly now, and this is just the start!AI Art & DiffusionStable Diffusion is 1 year oldHas it been a year? wow, for me, personally, stable diffusion is what started this whole AI fever dream. SD was the first model I actually ran on my own GPU, the first model I learned how to.. run, and use without relying on APIs. It made me way more comfortable with juggling models, learning what weights were, and we’ll here we are :) I now host a podcast and have a newsletter and I’m part of a community of folks who do the same, train models, dis
🎙️ThursdAI - LLM Finetuning deep dive, current top OSS LLMs (Platypus 70B, OrctyPus 13B) authors & what to look forward to
This is a free preview of a paid episode. To hear more, visit sub.thursdai.newsBrief outline for your convenience:[00:00] Introduction by Alex Volkov[06:00] Discussing the Platypus models and data curation process by Ariel, Cole and Nathaniel[15:00] Merging Platypus with OpenOrca model by Alignment Labs* Combining strengths of Platypus and OpenOrca* Achieving state-of-the-art 13B model[40:00] Mixture of Experts (MOE) models explanation by Prateek and Far El[47:00] Ablation studies on different fine-tuning methods by TekniumFull transcript is available for our paid subscribers 👇 Why don’t you become one?Here’s a list of folks and models that appear in this episode please follow all of them on X:* ThursdAI cohosts - Alex Volkov, Yam Peleg, Nisten Tajiraj* Garage Baind - Ariel, Cole and Nataniel (platypus-llm.github.io)* Alignment Lab - Austin, Teknium (Discord server)* SkunkWorks OS - Far El, Prateek Yadav, Alpay Ariak (Discord server)* Platypus2-70B-instruct* Open Orca Platypus 13BI am recording this on August 18th, which marks the one month birthday of the Lama 2 release from Meta. It was the first commercially licensed large language model of its size and quality, and we want to thank the great folks at MetaAI. Yann LeCun, BigZuck and the whole FAIR team. Thank you guys. It's been an incredible month since it was released.We saw a Cambrian explosion of open source communities who make this world better, even since Lama 1. For example, LLaMa.Cpp by Georgi Gerganov is such an incredible example of how open source community comes together and this one guy in the weekend Took the open source weights and made it run on CPUs and much, much faster.Mark Zuckerberg even talked about this, how amazing the open source community has adopted LLAMA, and that Meta is also now adopting many of those techniques and developments back to run their own models cheaper and faster. And so it's been exactly one month since LLAMA 2 was released.And literally every ThursdAI since then, we have covered a new state of the art open source model all based on Lama 2 that topped the open source model charts on Hugging Face.Many of these top models were fine tuned by Discord organizations of super smart folks who just like to work together in the open and open source their work.Many of whom are great friends of the pod.Nous Research, with whom we've had a special episode a couple of weeks back Teknium1 seems to be part of every orgm Alignment Labs and GarageBaind being the last few folks topping the charts.I'm very excited not to only bring you an interview with Alignment Labs and GarageBaind, but also to give you a hint of two additional very exciting efforts that are happening in some of these discords.I also want to highlight how many of those folks do not have data scientist backgrounds. Some of them do. So we had a few PhDs or PhD studies folks, but some of them studied all this at home with the help of GPT 4. And some of them even connected via ThursdAI community and space, which I'm personally very happy about.So this special episode has two parts. The first part we're going to talk with Ariel. Cole and Natniel, currently known as GarageBaind, get it? bAInd, GarageBaind, because they're doing AI in their garage. I love it.🔥 Who are now holding the record for the best performing open source model called Platypus2-70B-Instruct.And then, joining them is Austin from Alignment Labs, the authors of OpenOrca, also a top performing model, will talk about how they've merged and joined forces and trained the best performing 13b model called Open Orca Platypus 13B or Orctypus 13BThis 13b parameters model comes very close to the Base Llama 70b. So, I will say this again, just 1 month after Lama 2 released by the great folks at Meta, we now have a 13 billion parameters model, which is way smaller and cheaper to run that comes very close to the performance benchmarks of a way bigger, very expensive to train and run 70B model.And I find it incredible. And we've only just started, it's been a month. And so the second part you will hear about two additional efforts, one run by Far El, Prateek and Alpay from the SkunksWorks OS Discord, which is an effort to bring everyone an open source mixture of experts model, and you'll hear about what mixture of experts is.And another effort run by a friend of the pod Teknium previously a chart topper himself with Nous Hermes models and many others, to figure out which of the fine tuning methods are the most efficient. and fast and cheap to run. You will hear several mentions of LORAs, which stand for Low Rank Adaptation, which are basically methods of keeping the huge weights of LAMA and other models frozen and retrain and fine tune and align some specific parts of it with new data, which is a method we know from Diffusion World.And it's now applying to the LLM world and showing great promise in how fast, easy, and cheap it is to fine tune these huge models with significantly less hardware costs and time. Spe
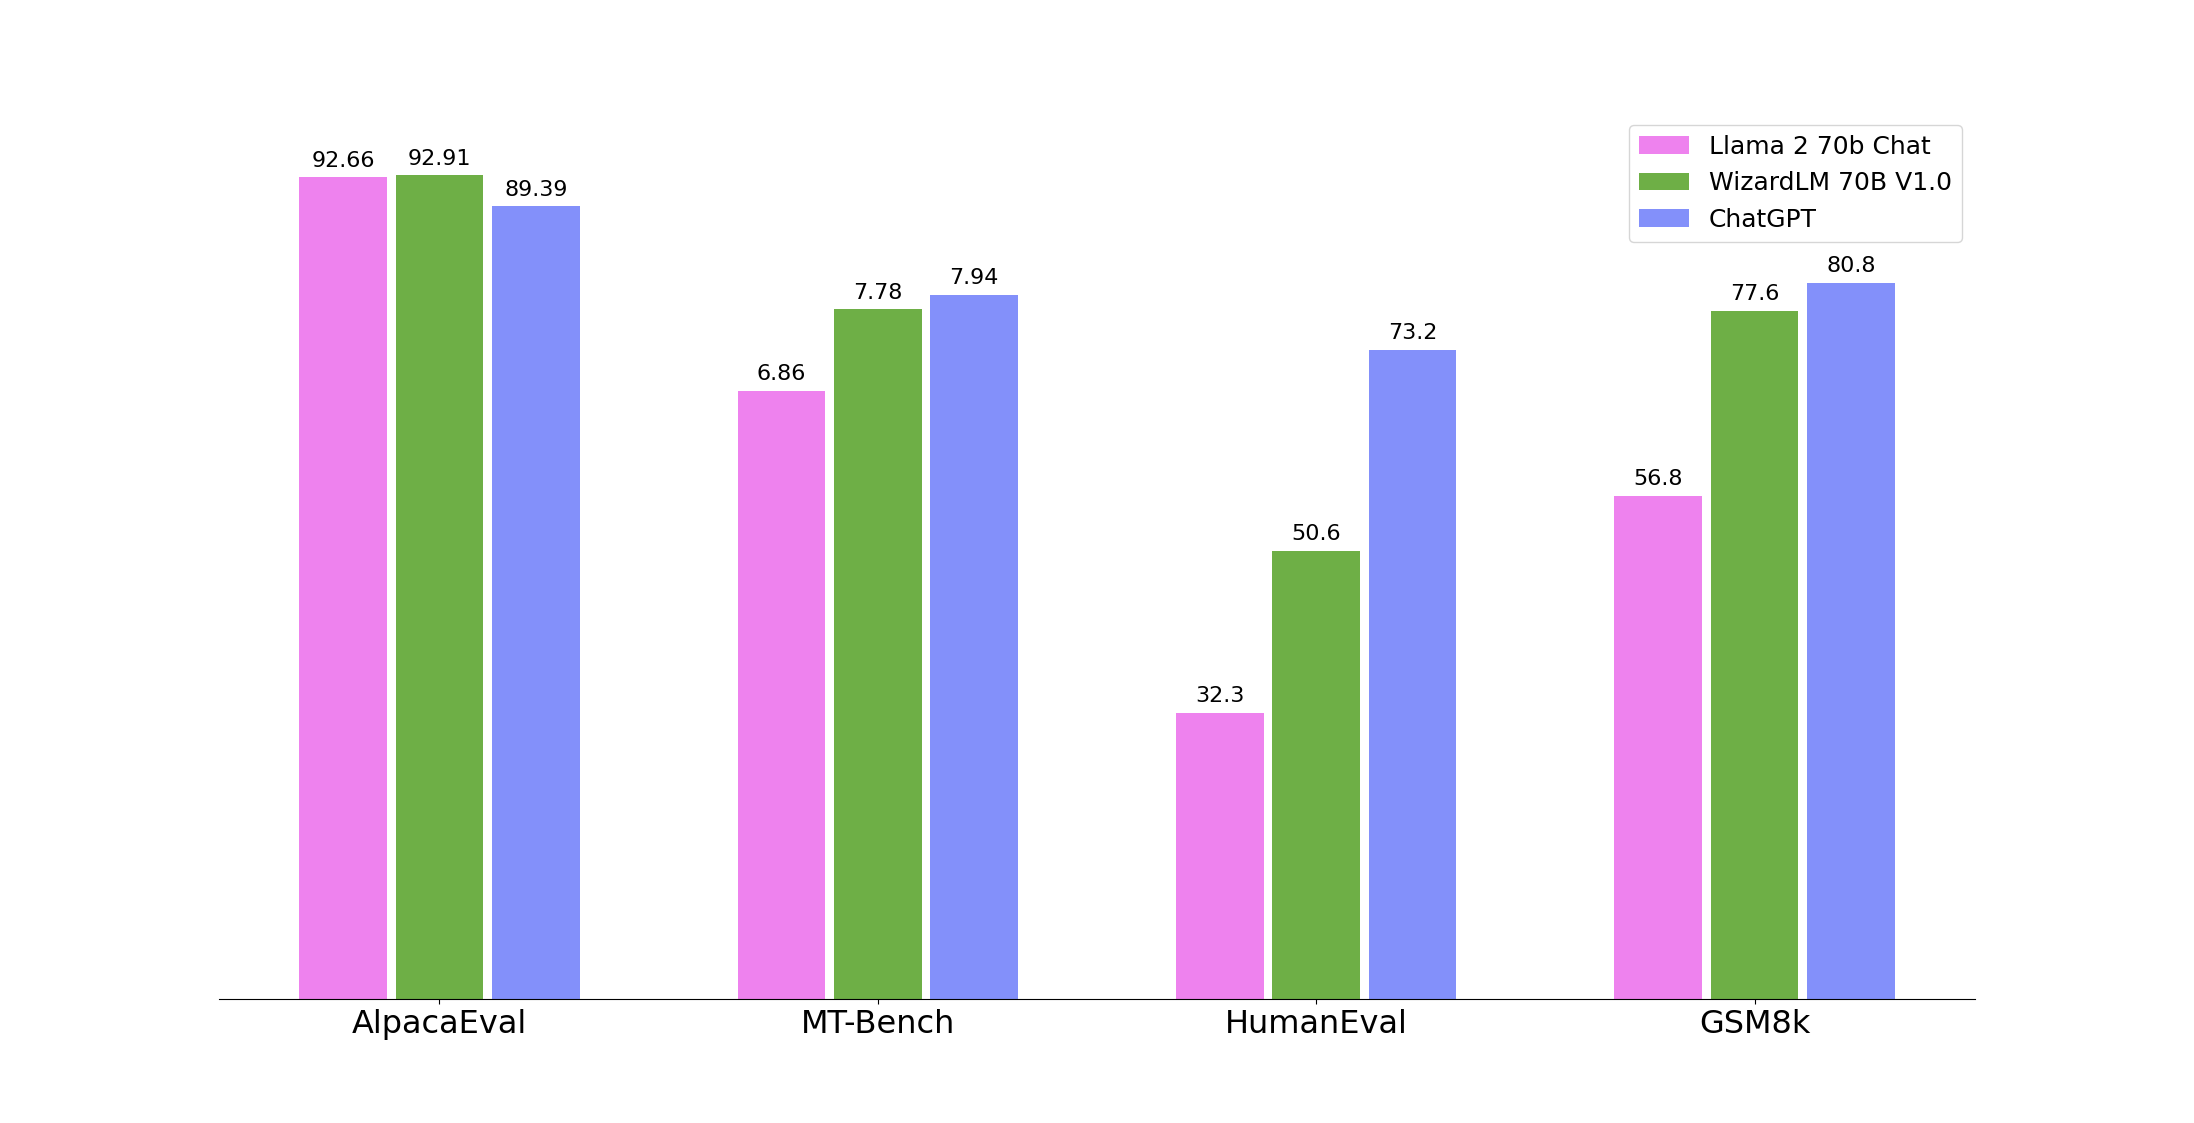
ThursdAI Aug 17 - AI Vision, Platypus tops the charts, AI Towns, Self Alignment 📰 and a special interview with Platypus authors!
Hey everyone, this is Alex Volkov, the host of ThursdAI, welcome to yet another recap of yet another incredibly fast past faced week.I want to start with a ThursdAI update, we now have a new website http://thursdai.news and a new dedicated twitter account @thursdai_pod as we build up the ThursdAI community and brand a bit more.As always, a reminder that ThursdAI is a weekly X space, newsletter and 2! podcasts, short form (Apple, Spotify) and the unedited long-form spaces recordings (RSS, Zealous page) for those who’d like the nitty gritty details (and are on a long drive somewhere).Open Source LLMs & FinetuningHonestly, the speed with which LLaMa 2 finetunes are taking over state of the art performance is staggering. We literally talk about a new model every week that’s topping the LLM Benchmark leaderboard, and it hasn’t even been a month since LLaMa 2 release day 🤯 (July 18 for those who are counting)Enter Platypus 70B (🔗)Platypus 70B-instruct is currently the highest ranked open source LLM and other Platypus versionsWe’ve had the great pleasure to chat with new friends of the pod Arielle Lee and Cole Hunter (and long time friend of the pod Nataniel Ruiz, co-author of DreamBooth, and StyleDrop which we’ve covered before) about this incredible effort to finetune LLaMa 2, the open dataset they curated and released as part of this effort and how quick and easy it is possible to train (a smaller 13B) version of Platypus (just 5 hours on a single A100 GPU ~= 6$ on Lambda 🤯)We had a great interview with Garage BAIND the authors of Platypus and we’ll be posting that on a special Sunday episode of ThursdAI so make sure you are subscribed to receive that when it drops.Open Orca + Platypus = OrctyPus 13B? (🔗)We’ve told you about OpenOrca just last week, from our friends at @alignment_lab and not only is Platypus is the best performing 70B model, the open source community comes through with an incredible merge and collaborating to bring you the best 13B model, which is a merge between OpenOrca and Platypus.This 13B model is now very close to the original LLaMa 70B in many of the metrics. LESS THAN A MONTH after the initial open source. It’s quite a remarkable achievement and we salute the whole community for this immense effort 👏 Also, accelerate! 🔥Join the skunksworksSpeaking of fast moving things, In addition to the above interview, we had a great conversation with folks from so called SkunksWorks OS discord, Namely Far El, Prateek Yadav, Alpay Ariak, Teknium and Alignment Labs, and our recurring guest hosts Yam Peleg and Nisten covered two very exciting community efforts, all happening within the SkunksWorks Discord.First effort is called MoE, Open mixture of experts, which is an Open Source attempt at replicating the Mixture of Experts model, which is widely attributed to why GPT-4 is so much better than GPT-3.The second effort is called Ablation studies, which is an effort Teknium is leading to understand once and for all, what is the best, cheapest and most high quality way to finetune open source models, whether it's Qlora or a full finetune or Loras.If you're interested in any of these, either by helping directly or provide resources such as GPU compute, please join the SkunksWorks discord. They will show you how to participate, even if you don't have prior finetuning knowledge! And we’ll keep you apprised of the results once they release any updates!Big Co LLMs + API updatesIn our Big CO corner, we start with an incredible paper from MetaAi, announcing:Self-Alignment w/ Backtranslation method + Humpback LLM - MetaAISummarized briefly (definitely listen to the full episode and @yampeleg detailed overview of this method) it’s a way for an LLM to be trained on a unsupervised way of creating high quality datasets, for itself! Using not a lot of initial “seed” data from a high quality dataset. Think of it this way, fine-tuning a model requires a lot of “question → response” data in your dataset, and back-translation proposes “response → question” dataset generation, coming up with novel ways of saying “what would a potential instruction be that would make an LLM generate this result”This results in a model that effectively learns to learn better and create it’s own datasets without humans (well at least human labelers) in the loop.Here are some more reading material on X for reference.OpenAI new JS SDK (X link)OpenAI has partnered with StainlessAPI to released a major new version 4 of their TS/JS SDK with the following incredible DX improvements for AI engineers* Streaming responses for chat & completions* Carefully crafted TypeScript types* Support for ESM, Vercel edge functions, Cloudflare workers, & Deno* Better file upload API for Whisper, fine-tune files, & DALL·E images* Improved error handling through automatic retries & error classes* Increased performance via TCP connection reuse* Simpler initialization logicThe most exciting part for me is, this is now very easy to get started with AI projects an
ThursdAI Aug 10 - Deepfakes get real, OSS Embeddings heating up, Wizard 70B tops tops the charts and more!
Hey everyone, welcome to yet another ThursdAI update! As always, I’m your host, Alex Volkov, and every week, ThursdAI is a twitter space that has a panel of experts, guests and AI enthusiasts who join to get up to date with the incredible fast pace of AI updates, learn together and listen to subject matter experts on several of the topics. Pssst, this podcast is now available on Apple, Spotify and everywhere using RSS and a new, long form, raw and uncut, full spaces recording podcast is coming soon! ThursdAI - Is supported by readers, and I promised my wife I’d ask, if you find this valuable, why not upgrade your subscription so I can keep this going? Get better equipment and produce higher quality shows? I started noticing that our updates spaces are split into several themes, and figured to start separating the updates to these themes as well, do let me know if the comments if you have feedback or preference or specific things to focus on. LLMs (Open Source & Proprietary)This section will include updates pertaining to Large Language Models, proprietary (GPT4 & Claude) and open source ones, APIs and prompting. Claude 1.2 instant in Anthropic API (source)Anthropic has released a new version of their Claude Instant, a very very fast model of Claude, with 100K, a very capable model that’s now better at code task, and most of all, very very fast! Anthropic is also better at giving access to these models, so if you’ve waited in their waitlist for a while, and still don’t have access, DM me (@altryne) and I’ll try to get you API access as a member of ThursdAI community. WizardLM-70B V1.0 tops OSS charts (source)WizardLM 70B from WizardLM is now the top dog in open source AI, featuring the same License as LLaMa and much much better code performance than base LLaMa 2, it’s now the top performing code model that’s also does other LLMy things. Per friend of the pod, and Finetuner extraordinaire Teknium, this is the best HumanEval (coding benchmark) we’ve seen in a LLaMa based open source model 🔥Also from Teknium btw, a recent evaluation of the Alibaba Qwen 7B model we talked about last ThursdAI, by Teknium, actually showed that LLaMa 7B is a bit better, however, Qwen should also be evaluated on tool selection and agent use, and we’re waiting for those metrics to surface and will update! Embeddings Embeddings EmbeddingsIt seems that in OpenSource embeddings, we’re now getting state of the art open source models (read: require no internet access) every week!In just the last few months: - Microsoft open-sourced E5 - Alibaba open-sourced General Text Embeddings - BAAI open-sourced FlagEmbedding - Jina open-sourced Jina EmbeddingsAnd now, we have a new metric MTEB and a new leaderboard from hugging face (who else?) to always know which model is currently leading the pack. With a new winner from this week! BGE (large, base and small (just 140MB) ) Embedding models are very important for many AI applications, RAG (retrieval augmented generation) products, semantic search and vector DBs, and the faster, smaller and more offline they are, the better the whole field of AI tools we’re going to get, including, much more capable, and offline agents. 🔥 Worth noting that text-ada-002, the OpenAI embedding API is now ranked 13 on the above MTEB leaderboard! Open Code Interpreter 👏While we’re on the agents topic, we had the privilege to chat with a new friend of the pod, Shroominic who’s told us about his open source project, called codeinterpreter-api which is an open source implementation of code interpreter. We had a great conversation about this effort, the community push, the ability of this open version to install new packages, access the web, run offline and have multiple open source LLMs that run it, and we expect to hear more as this project develops! If you’re not familiar with OpenAI Code Interpreter, we’ve talked about it at length when it just came out here and it’s probably the best “AI Agent” that many folks have access to right now. Deepfakes are upon us! I want to show you this video and you tell me if you saw this not in an AI newsletter, would you have been able to tell it’s AI generated. This video was generated automatically, when I applied to the waitlist by HeyGen and then I registered again and tried to get AI Joshua to generate an ultra realistic ThursdAI promo vid haha. I’ve played with many tools for AI video generation and never saw anything come close to this quality, and can’t wait for this to launch! While this is a significant update for many folks in terms of how well deepfakes can look (and it is! Just look at it, reflections, HQ, lip movement is perfect, just incredible) this isn’t the only progress data point in this space. Play.ht announced version 2.0 which sounds incredibly natural, increased model size 10x and dataset to more than 1 million hours of speech across multiple languages, accents, and speaking styles and emotions and claims to have sub 1s latency and fake your voice with a sample
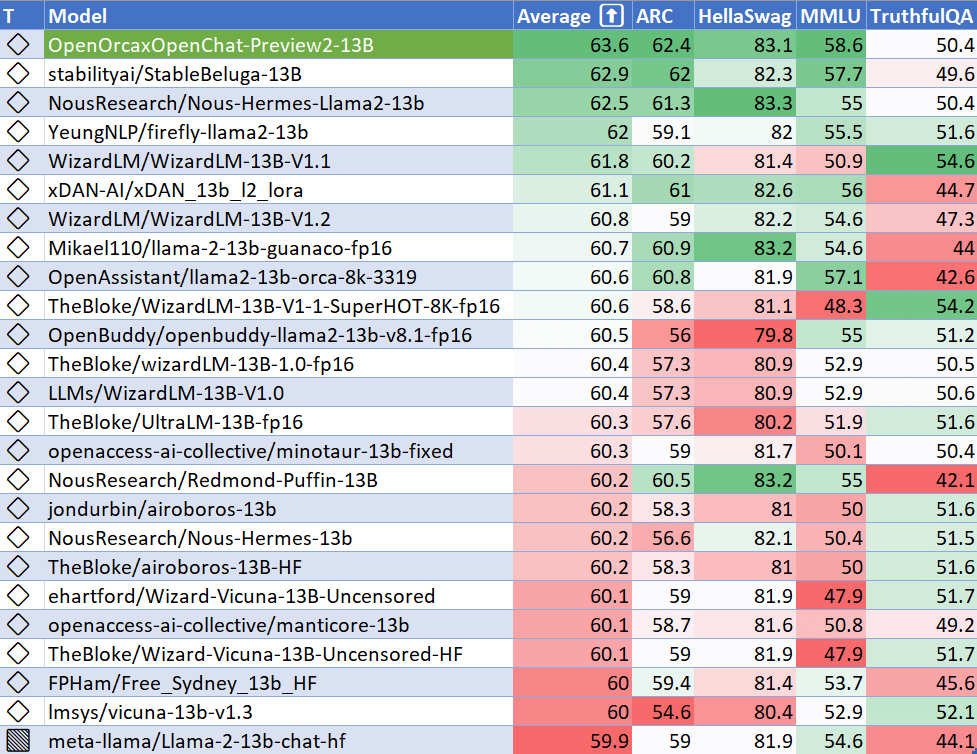
ThursdAI Aug 3 - OpenAI, Qwen 7B beats LLaMa, Orca is replicated, and more AI news
Hi, today’s episode is published on a Friday, it’s been a busy week with at least 4 twitter spaces, countless DMs and research! OpenAI announces UX updates* Example prompts: No more staring at a blank page! * Suggested replies: ChatGPT automatically synthesizes follow up questions. Then you just click a button* GPT-4 by default: When starting a new chat as a Plus user, ChatGPT will remember your previously selected model! * 4. Uploading multiple files is now supported in the Code Interpreter beta for all Plus users.* 5. Stay logged in: You’ll no longer be logged out every 2 weeks and if you do, we have a sweet new welcome page! * 6. Keyboard shortcuts: Work faster with shortcuts, Try ⌘ (Ctrl) + / to see the complete list.ThursdAI - I stay up to date so you don’t have toAlibaba releases Qwen7b* Trained with high-quality pretraining data. Qwen-7B pretrained on a self-constructed large-scale high-quality dataset of over 2.2 trillion tokens. The dataset includes plain texts and codes, and it covers a wide range of domains, including general domain data and professional domain data.* Strong performance. In comparison with the models of the similar model size, outperforms the competitors on a series of benchmark datasets, which evaluates natural language understanding, mathematics, coding, etc.* Better support of languages. New tokenizer, based on a large vocabulary of over 150K tokens, is a more efficient one compared with other tokenizers. It is friendly to many languages, and it is helpful for users to further finetune Qwen-7B for the extension of understanding a certain language.* Support of 8K Context Length. Both Qwen-7B and Qwen-7B-Chat support the context length of 8K, which allows inputs with long contexts.* Support of Plugins. Qwen-7B-Chat is trained with plugin-related alignment data, and thus it is capable of using tools, including APIs, models, databases, etc., and it is capable of playing as an agent.This is an impressive jump in open source capabilities, less than a month after LLaMa 2 release! GTE-large a new embedding model outperforms OPENAI ada-002If you’ve used any “chat with your documents” app or built one, or have used a vector database, chances are, you’ve used openAI ada-002, it’s the most common embedding model (that turns text into embeddings for vector similarity search) This model is ousted by an OpenSource (nee. free) one called GTE-large with improvements on top of ada across most parameters! OpenOrca 2 preview Our friends from AlignmentLab including Teknium and LDJ have discussed the release of OpenOrca 2! If you’re interested in the type of finetuning things these guys do, we had a special interview w/ NousResearch on the pod a few weeks ago OpenOrca tops the charts for the best performing 13B model 👏Hyper-write releases a personal assistantYou know how much we love agents in ThursdAI, and we’re waiting for this field to materialize and I personally am waiting for an agent to summarize the whole links and screenshots for this summary, and… we’re not there yet! But we’re coming close, and our friends from HyperWrite have released their browser controlling agent on ThursdAI. Talk about a full day of releases! I absolutely love the marketing trick they used where one of the examples of how it works, is “upvote us on producthunt” and it actually did work for me, and found out that I already upvotedSuperconductor continuesI was absolutely worried that I won’t make it to this thursdAI or won’t know what to talk about because, well, I’ve become a sort of host and information hub and a interviewer of folks about LK-99. Many people around the world seem interested in it’s properties, replication attempts and to understand this new and exciting thing. We talked about this briefly, but if interests you (and I think it absolutely should) please listen to the below recording. ThursdAI - See ya next week, don’t forget to subscribe and if you are already subscribed, and get value, upgrading will help me buy the proper equipment to make this a professional endeavor and pay for the AI tools! 🫡 This is a public episode. If you'd like to discuss this with other subscribers or get access to bonus episodes, visit sub.thursdai.news/subscribe
🧪 LK99 - The superconductor that can change the world, and the K-drama behind it!
This is a free preview of a paid episode. To hear more, visit sub.thursdai.newsFirst of all, let me address this from the get go, I’m not a material scientist! I am pretty good at finding information in twitter’s incredibly noisy info stream. (hey, this is how I bring you AI updates every ThursdAI) Since LK-99 is potentially groundbreaking and revolutionary, I’ve compiled a twitter list of everyone who I found credible, interested and a source of new information, and there’s now over 1.5K followers to this list alone!Since this clearly is interesting to a lot of you, I reached out to a few prominent people on this list, and asked them to join a twitter space, to try and stitch together an update on the current state of LK-99, replication attempts, history and lore, as it stands a week after the original papers release. If you found this interesting, you’re the type of person who wants to stay up to date, feel free to subscribe and keep this Substack alive!First of all, let’s do some level setting. Superconductors are real, we’ve used them in MRI machines for example, but the currently available superconductors need extremely low temperature and high pressure to well.., and the promise of a room temperature and ambient pressure superconductor is the holy grail of energy use. For a breakdown on what superconductors are, and what they can mean for the world, I strongly recommend this thread from Andrew Cote (published presciently a full two weeks before the LK-99 paper) or watch this incredible breakdown: July 22nd, the LK-99 arXiv day! On July 22nd, two papers describing “worlds first room temperature superconductor” were uploaded to arXiv: 2307.12008 - Sukbae Lee, Ji-Hoon Kim, Young-Wan Kwon (submitted by Kwon)and after 2 hours and 20 minutes another paper was uploaded2307.12037 - Sukbae Lee, Jihoon Kim, Hyun-Tak Kim, Sungyeon Im, SooMin An, Keun Ho Auh (Submitted by Hyuntak Kim)You may notice that the first two authors on both papers are Sukbae Lee and Ji-Hoon Kim, and in fact LK stands for Lee and Kim and 99 in the LK-99 name stands for the year 1999 they have started research on this.You may also notice that YW Kwon who submitted the first paper, is not included on the second one, and in fact, is no longer part of the Quantum Energy Research Institute (Aka QCentre) where he was a CTO (he’s no longer listed on the site) If this shakes out, and SC is replicated, there’s definitely going to be a Netflix series on the events that led to YW Kwon to release the paper, after he was no longer affiliated with QCentre, with limited information so let’s try to connect the dots (a LOT of this connecting happened on the ground by Seo Sanghyeon and his friends, and translated by me. Their original coverage has a LOT of details and is available in Korean hereLet’s go back to the 90sOn the LinkedIn page of Ji-Hoon Kim (the page turned blank shortly before me writing this), JH Kim showed that he started working on this back in 1999, and they estimated they have a material that contained “very small amount of superconductivity” and together with Sukbae Lee, in 2018 they have established QCentre to complete the work of their Professor Emeritus of Chemistry at Korea University, the late Choi Dong-Sik (1943-2017) who apparently first proposed the LK-99 material (following the 1986 bonanza of the discovery of high temperature superconductors by IBM researchers).Fast forward to 2017, a wish expressed in a last will and testament starts everything again Professor Choi passed away, and in this will requested follow-up research on ISB theory and LK-99 and Quantum Energy Research Institute is now established by Lee and Kim (LK) and they continue their work on this material. In 2018, there’s a potential breakthrough, that could have been an accident that led to the discovery of the process behind LK-99? Here’s a snippet of Seo Sanghyeon explaining this:Kwon Young-Wan the ex-CTOKwon is a Research Professor at Korea University & KIST, is the third author on the first arXiv paper, and the submitter, was previously the CTO, but at the time of the paper to arXiv he was not affiliated with QCentre for “some months” according to an interview with Lee. He uploads a paper, names only 3 authors (Lee, Kim and Himself) and then surprisingly presents LK-99 research at the MML2023 international conference held in Seoul a few days later, we haven’t yet found a video recording, however a few reports mention him asking for an interpreter, and talking about bringing samples without demonstration and proper equipment.Important to note, that Enter Hyun-Tak KimH.T Kim is probably the most cited and well-known professor in academia among the folks involved. See his google scholar profile, with a D-index of 43 and has 261 publications and 11,263 citations. He’s a heavy hitter, and is the submitter and listed as the author of paper number 2 submitted to arXiv, 2 hours and 20 minutes after paper number 1 above. In the second paper, he’s listed as the third
🎙️ThursdAI - Jul 27: SDXL1.0, Superconductors? StackOverflowAI and Frontier Model Forum
⏰ Breaking news, ThursdAI is now on Apple Podcasts and in this RSS ! So use your favorite pod-catcher to subscribe or his this button right here: Our friends at Zealous have provided an incredible platform for us to generate these awesome video podcasts from audio or from twitter spaces so if you prefer a more visual format, our deep thanks to them! P.S - You can find the full 2 hour space with speakers on our Zealous page and on TwitterHere’s a summary of the main things that happened in AI since last ThursdAI: 🧑🎨 Stability.ai releases SDXL1.0* Generates 1024px x 1024x stunning images* High high photorealism* Supports hands and text* Different (simpler?) prompting required* Fine-tunes very well! * Supports LORAs, ControlNet in-painting and outcropping and the whole ecosystem built around SD* Refiner is a separate piece that adds high quality detail* Available on Dreamstudio, Github, ClipDrop and HuggingFace* Also, is available with incredible ComfyUI and can be used in a free Colab!Image Credit goes to ThibaudSuperconductors on Hugging Face? What? Honestly, this has nothing immediate to do with AI updates, but, if it pans out, it’s so revolutionary that it will affect AI also!Here’s what we know about LK-99 so far: * 2 papers released on arXiv (and hugging face haha) in the span of several hours* First AND second paper both claim extraordinary claims of solving ambient superconductivity* Ambient pressure and room temp superconductive material called LK-99 * Straightforward process with a clear replication manual and fairly common materials* Papers lack rigor, potentially due to rushing out or due to fighting for credit for nobel prize * The science is potentially sound, and is being “baked and reproduced in multiple labs” per science mag.Potential effects of room temperature superconductivity on AI: While many places (All?) can benefit from the incredible applications of superconductors (think 1000x batteries) the field of AI will benefit as well if the result above replicates.* Production of GPU and CPU is power-constrained and could benefit* GPU/CPUs themselves are power-constrained while running inference* GPT-4 is great but consumes more power (training and inference) than previous models making it hard to scale* Local inference is also power-restricted, so running local models (and local walking robots) could explode with superconductivity * Quantum computing is going to have a field day if this is true* So will fusion reactors (which need superconductors to keep the plasma in place) As we wait for labs to reproduce, I created a twitter list of folks who are following closely, feel free to follow along! AI agents protocol, discussion and state of for July 2023* Participated in an e2b space with tons of AI builders (Full space and recap coming soon!) * Many touted AI agents as a category and discussed their own frameworks* Folks came up and talked about their needs from the agent protocol proposed by e2b* Agents need to be able to communicate with other agents/sub agents* Tasks payloads and artifacts and task completion can be async (think receiving a response email from a colleague) * The ability to debug (with timetravel) and trace and reproduce an agent run* Deployment, running and execution environment issues* Reliability of task finish reporting, and evaluation is hardFrontier model forum* OpenAI, Anthropic, Google, and Microsoft are forming the Frontier Model Forum to promote safe and responsible frontier AI.* The Forum will advance AI safety research, identify best practices, share knowledge on risks, and support using AI for challenges like climate change.* Membership is open to organizations developing frontier models that demonstrate safety commitment.* The Forum will focus on best practices, AI safety research, and information sharing between companies and governments.* Some have expressed concern that this could enable regulatory capture by the “Big LLM” shops that can use the lobbying power to stop innovation. StackOverflow AI - “The reports of my death have been greatly exaggerated” Stack overflow has been in the news lately, when a graphic of it’s decline in traffic has become viral. They have publicly disputed that information claiming they have moved to a different measuring and didn’t update the webpage, but then also… announced Overflow AI!* AI search and aggregation of answers + ability to follow up in natural language* Helps drafting questions* AI answers with a summary, and citations with the ability to “extend” and adjust for your coding level* VSCode integration! * Focusing on “validated and trusted” content* Not only for SO code, stack overflow for teams will also embed other sources (like your company confluence) and will give you attributed answers and tagging abilities on external contentThis has been an insane week in terms of news (👽 anyone?) and superconductors and AI releases! As always, I’m grateful for your attention! Forward this newsletter to 1 friend as a favor

ThursdAI - Special Episode, interview with Nous Research and Enrico Shippole, fine-tuning LLaMa 2, extending it's context and more
Hey there, welcome to this special edition of ThursdAI. This episode is featuring an interview with Nous Research, a group of folks who fine-tune open source large language models to make them better. If you are interested to hear how finetuning an open source model works, dataset preparation, context scaling and more, tune in! You will hear from Karan, Teknium, LBJ from Nous Research and Enrico who worked along side them. To clarify, Enrico is going in depth into the method called Rope Scaling, which is a clever hack, that extends the context length of LLaMa models significantly and his project LLongMa which is an extended version of LLaMa with 8000 token context window. The first voice you will hear is Alex Volkov the host of ThursdAI who doesn’t usually have a lisp, but for some reason, during the recording, twitter spaces decided to mute all the S sounds. Links and acknowledgments: * Nous Research - https://nousresearch.com/ (@nousresearch)* Redmond Puffin 13b - First LLaMa Finetune* LLongMa - LLaMa finetune with 8K context (by Encrico, emozilla and KaioKenDev)* Nous-Hermes-Llama2-13b-GPTQ - Hermes Finetune was released after the recording 🎊Psst, if you like this, why don’t you subscribe? Or if you are subscribed, consider a paid subscription to support #ThursdAIShow transcription with timestamps: Alex Volkov - targum.video (@altryne)[00:00:55] Yeah. That's awesome. So I guess with this, maybe, Karan, if you if you are able to, can you you talk about Nous research and how kind of how it started and what the what are you guys doing, and then we'll dive into the kind of, you know, Hermes and and Puffin and the methods and and all of it.karan (@karan4d)[00:01:16] Absolutely. Nous research. I mean, I I myself and many other of us are just, like, enthusiasts that we're fine tuning models like, you know, GPTJ or GPT 2. And, you know, we all are on Twitter. We're all on Discord, and kind of just found each other and had this same mentality of we wanna we wanna make these models. We wanna kinda take the power back from people like OpenAI and anthropic. We want stuff to be able to run easy for everyone. And a lot of like minds started to show up.karan (@karan4d)[00:01:50] I think that Technium's addition initially to Nous research, Jim, kinda showing up. And himself, I and human working on compiling the Hermes dataset was really what came to attract people when Hermes came out. I think we just have a really strong and robust, like, data curation thesis in terms of that. And I think that have just some of the most talented people who have come to join us and just volunteer and work with us on stuff. And I absolutely must say, I can see in the in the listeners is our compute provider, Redmond AI.karan (@karan4d)[00:02:30] And, you know, none of this none of these models would be possible without Redmond's generous sponsorship for us to be able to deliver these things lightning fast, you know, without making us through a bunch of hoops just a a total total pleasure to work with. So I would I have to shell and say, you know, I highly recommend everyone check out Redmond as because they really make our project possible.Alex Volkov - targum.video (@altryne)[00:02:52] Absolutely. So shout out to Redmond AI and folks give them a follow. They're the the only square avatar in the audience. Go take them out. And, Karan, thanks for that. I wanna just do a mic check for teknium. Teknium. Can you speak now? Can you? Can I hear you?Teknium (e/λ) (@Teknium1)[00:03:08] Yeah. My phone died right when you were introducing me earlier.Alex Volkov - targum.video (@altryne)[00:03:10] Yep. What's up, Eric? -- sometimes on Twitter basis. Welcome, Technium. So briefly, going back to question. I don't know if you heard it. What besides the commercial and kind of the the contact window, what kind of caught your eye in the llama, at least the base until you guys started, or have you also, like, the other guys not had a second to play with the base model and dove into fine tuning directly?Teknium (e/λ) (@Teknium1)[00:03:35] Yeah. The only thing that really caught my eye was the chat model and how horribly RLHF it was.Alex Volkov - targum.video (@altryne)[00:03:41] Yeah. I've seen some conversations about and kind of the point of Ira, RLHF as well. And okay. So so now that we've introduced Neus research, sorry, I wanna talk to you guys about what you guys are cooking. Right? The we've seen, the the Hermes model before this was, like, loved it as one of the, you know, the best fine tunes that I've seen at least and the the the most performing ones. Could you guys talk about the process to get to the Hermes model, the previous one? and then give us things about what coming soon?karan (@karan4d)[00:04:16] Teknium, you got this one. man.Teknium (e/λ) (@Teknium1)[00:04:22] Yeah. It was basically I saw Alpaca, and I wanted to make it like, remake it with GPT 4, and then from there and just pretty much exclusively included anything that was GPT 4 o
ThursdAI July 20 - LLaMa 2, Vision and multimodality for all, and is GPT-4 getting dumber?
ThursdAI - Recaps of the most high signal AI weekly spaces is a reader-supported publication. To receive new posts and support my work, consider becoming a free or paid subscriber.If you’d like to hear the whole 2 hour conversation, here’s the link to twitter spaces we had. And if you’d like to add us to your favorite podcatcher - here’s the RSS link while we’re pending approval from Apple/SpotifyHappy LLaMa day! Meta open sourced LLaMa v2 with a fully commercial license. LLaMa 1 was considered the best open source LLM, this one can be used for commercial purposes, unless you have more than 700MM monthly active users (no 🦙 for you Google!)Meta has released the code and weights, and this time around, also a fine-tuned chat version of LLaMa v2 to all, and has put them on HuggingFace. There are already (3 days later) at least 2 models that have fine-tuned LLaMa2 that we know of: * @nousresearch have released Redmond Puffin 13B * @EnricoShippole with collaboration with Nous have released LLongMa, which extends the context window for LLaMa to 8K (and is training a 16K context window LLaMa) * I also invited and had the privilege to interview the folks from @nousresearch group (@karan4d, @teknium1 @Dogesator ) and @EnricoShippole which will be published as a separate episode.Many places already let you play with LLaMa2 for free: * https://www.llama2.ai/* HuggingFace chat* Perplexity LLaMa chat* nat.dev, replicate and a bunch more! The one caveat, the new LLaMa is not that great with code (like at all!) but expect this to change soon!We all just went multi-modal! Bing just got eyes!I’ve been waiting for this moment, and it’s finally here. We all, have access to the best vision + text model, the GPT-4 vision model, via bing! (and also bard, but… we’ll talk about it) Bing chat (which runs GPT-4) has now released an option to upload (or take) a picture, and add a text prompt, and the model that responds understands both! It’s not OCR, it’s an actual vision + text model, and the results are very impressive! I’ve personally took a snap of a food-truck side, and asked Bing to tell me what they offer, it found the name of the truck, searched it online, found the menu and printed out the menu options for me! Google’s Bard also introduced their google lens integration, and many folks tried uploading a screenshot and asking it for code in react to create that UI, and well… it wasn’t amazing. I believe it’s due to the fact that Bard is using google lens API and was not trained in a multi-modal way like GPT-4 has. One caveat is, the same as text models, Bing can and will hallucinate stuff that isn’t in the picture, so YMMV but take this into account. It seems that at the beginning of an image description it will be very precise but then as the description keeps going, the LLM part kicks in and starts hallucinating. Is GPT-4 getting dumber and lazier? Researches from Standford and Berkley (and Matei Zaharia, the CTO of Databricks) have tried to evaluate the vibes and complaints that many folks have been sharing, wether GPT-4 and 3 updates from June, had degraded capabilities and performance. Here’s the link to that paper and twitter thread from Matei. They have evaluated the 0301 and the 0613 versions of both GPT-3.5 and GPT-4 and have concluded that at some tasks, there’s a degraded performance in the newer models! Some reported drops as high as 90% → 2.5% 😮But is there truth to this? Well apparently, some of the methodologies in that paper lacked rigor and the fine folks at AI Snake Oil ( Sayash Kapoor and Arvind) have done a great deep dive into that paper and found very interesting things!They smartly separate between capabilities degradation and behavior degradation, and note that on the 2 tasks (Math, Coding) that the researches noted a capability degradation, their methodology was flawed, and there isn’t in fact any capability degradation, rather, a behavior change and a failure to take into account a few examples. The most frustrating for me was the code evaluation, the researchers scored both the previous model and the new June updated models on “code execution” with the same prompt, however, the new models defaulted to wrap the returned code with ``` which is markdown code snippets. This could have been easily fixed with some prompting, however, the researchers scored the task based on, wether or not the code snippet they get is “instantly executable”, which it obviously isn’t with the ``` in there. So, they haven’t actually seen and evaluated the code itself, just wether or not it runs! I really appreciate the AI Snake Oil deep dive on this, and recommend you all read it for yourself and make your own opinion and don’t give into the hype and scare mongering and twitter thinkfluencer takes. News from OpenAI - Custom Instructions + Longer deprecation cyclesIn response to the developers (and the above paper), OpenAi announced an update to the deprecation schedule of the 0301 models (the one without functions) and they
ThursdAI July 13 - Show recap + Notes
Welcome Friends, to the first episode of ThursdAI recap. If you can’t come to the spaces, subscribing is the next best thing. Distilled, most important updates, every week, including testimony and tips and tricks from a panel of experts. Join our community 👇Every week since the day GPT-4 released, we’ve been meeting in twitter spaces to talk about AI developments, and it slowly by surely created a community that’s thirsty to learn, connect and discuss information. Getting overwhelmed with daily newsletters about tools, folks wanted someone else to do the legwork, prioritize and condense the most important information about what is shaping the future of AI, today! Hosted by AI consultant Alex Volkov (available for hire), CEO of Targum.video, this information-packed edition covered groundbreaking new releases like GPT 4.5, Claude 2, and Stable Diffusion 1.0. We learned how Code Interpreter is pushing boundaries in computer vision, creative writing, and software development. Expert guests dove into the implications of Elon Musk's new XAI startup, the debate around Twitter's data, and pioneering techniques in prompt engineering. If you want to stay on top of the innovations shaping our AI-powered tomorrow, join Alex and the ThursdAI community. Since the audio was recorded from a twitter space, it has quite a lot of overlaps, I think it’s due to the export, so sometimes it sounds like folks talk on top of each other, most of all me (Alex) this was not the case, will have to figure out a fix. Topics we covered in July 13, ThursdAI GPT 4.5/Code Interpreter:00:02:37 - 05:55 - General availability of Chad GPT with code interpreter announced. 8k context window, faster than GPT-4.05:56 - 08:36 - Code interpreter use cases, uploading files, executing code, skills and techniques.08:36 - 10:11 - Uploading large files, executing code, downloading files.Claude V2:20:11 - 21:25 - Anthropic releases Claude V2, considered #2 after OpenAI.21:25 - 23:31 - Claude V2 UI allows uploading files, refreshed UI.23:31 - 24:30 - Claude V2 product experience beats GPT-3.5.24:31 - 27:25 - Claude V2 fine-tuned on code, 100k context window, trained on longer outputs.27:26 - 30:16 - Claude V2 good at comparing essays, creative writing.30:17 - 32:57 - Claude V2 allows multiple file uploads to context window.32:57 - 39:10 - Claude V2 better at languages than GPT-4.39:10 - 40:30 - Claude V2 allows multiple file uploads to context window.X.AI:46:22 - 49:29 - Elon Musk announces X.AI to compete with OpenAI. Has access to Twitter data.49:30 - 51:26 - Discussion on whether Twitter data is useful for training.51:27 - 52:45 - Twitter data can be transformed into other forms.52:45 - 58:32 - Twitter spaces could provide useful training data.58:33 - 59:26 - Speculation on whether XAI will open source their models.59:26 - 61:54 - Twitter data has some advantages over other social media data.Stable Diffusion:89:41 - 91:17 - Stable Diffusion releases SDXL 1.0 in discord, plans to open source it.91:17 - 92:08 - Stable Diffusion releases Stable Doodle.GPT Prompt Engineering:61:54 - 64:18 - Intro to Other Side AI and prompt engineering.64:18 - 71:50 - GPT Prompt Engineer project explained.71:50 - 72:54 - GPT Prompt Engineer results, potential to improve prompts.72:54 - 73:41 - Prompts may work better on same model they were generated for.73:41 - 77:07 - GPT Prompt Engineer is open source, looking for contributions.Related tweets shared: https://twitter.com/altryne/status/1677951313156636672https://twitter.com/altryne/status/1677951330462371840@Surya - Running GPT2 inside code interpreter tomviner - scraped all the internal knowledge about the envPeter got all pypi packages and their descriptionswyx added Claude to to smol menubar (which we also discussed)SkalskiP awesome code interpreter experiments repoSee the rest of the tweets shared and listen to the original space here:https://spacesdashboard.com/space/1YpKkggrRgPKj/thursdai-space-code-interpreter-claude-v2-xai-sdxl-moreFull Transcript: 00:02 (Speaker A) You. First of all, welcome to Thursday. We stay up to date so you don't have to. There's a panel of experts on top here that discuss everything. 00:11 (Speaker A) If we've tried something, we'll talk about this. If we haven't, and somebody in the audience tried that specific new AI stuff, feel free to raise your hand, give us your comment. This is not the space for long debates. 00:25 (Speaker A) We actually had a great place for that yesterday. NISten and Roy fromPine, some other folks, we'll probably do a different one. This should be information dense for folks and this will be recorded and likely we posted at some point. 00:38 (Speaker A) So no debate, just let's drop an opinion and discuss the new stuff and kind of continue. And the goal is to stay up to date so you don'thave to in the audience. And I think with that, I will say hi to AlanJanae and we will get started. 00:58 (Speaker B) Hi everyone, I'm NISten Tahira. I worked on, well, released on