Doom Debates!
192 episodes — Page 3 of 4
Why I'm Scared GPT-9 Will Murder Me — Liron on Robert Wright’s Nonzero Podcast
Today I’m sharing my interview on Robert Wright’s Nonzero Podcast from last May. Rob is an especially sharp interviewer who doesn't just nod along, he had great probing questions for me.This interview happened right after Ilya Sutskever and Jan Leike resigned from OpenAI in May 2024, continuing a pattern that goes back to Dario Amodei leaving to start Anthropic. These aren't fringe doomers; these are the people hired specifically to solve the safety problem, and they keep concluding it's not solvable at the current pace.00:00:00 - Liron’s preface00:02:10 - Robert Wright introduces Liron00:04:02 - PauseAI protests at OpenAI headquarters00:05:15 - OpenAI resignations (Ilya Sutskever, Jan Leike, Dario Amodei, Paul Christiano, Daniel Kokotajlo)00:15:30 - P vs NP problem as analogy for AI alignment difficulty00:22:31 - AI pause movement and protest turnout00:29:02 - Defining AI doom and sci-fi scenarios00:32:05 - What’s My P(Doom)™00:35:18 - Fast vs slow AI takeoff and Sam Altman's position00:42:33 - Paperclip thought experiment and instrumental convergence explanation00:54:40 - Concrete examples of AI power-seeking behavior (business assistant scenario)01:00:58 - GPT-4 TaskRabbit deception example and AI reasoning capabilities01:09:00 - AI alignment challenges and human values discussion01:17:33 - Wrap-up and transition to premium subscriber contentShow NotesThis episode on Rob’s Nonzero Newsletter. You can subscribe for premium access to the last 1 hour of our discussion! — https://www.nonzero.org/p/in-defense-of-ai-doomerism-robertThis episode on Rob’s YouTube — https://www.youtube.com/watch?v=VihA_-8kBNgPauseAI — https://pauseai.infoPauseAI US — http://pauseai-us.orgDoom Debates’ Mission is to raise mainstream awareness of imminent extinction from AGI and build the social infrastructure for high-quality debate.Support the mission by subscribing to my Substack at DoomDebates.com and to youtube.com/@DoomDebates Get full access to Doom Debates at lironshapira.substack.com/subscribe
The Man Who Might SOLVE AI Alignment — Dr. Steven Byrnes, AGI Safety Researcher @ Astera Institute
Dr. Steven Byrnes, UC Berkeley physics PhD and Harvard physics postdoc, is an AI safety researcher at the Astera Institute and one of the most rigorous thinkers working on the technical AI alignment problem.Steve has a whopping 90% P(Doom), but unlike most AI safety researchers who focus on current LLMs, he argues that LLMs will plateau before becoming truly dangerous, and the real threat will come from next-generation "brain-like AGI" based on actor-critic reinforcement learning.For the last five years, he's been diving deep into neuroscience to reverse engineer how human brains actually work, and how to use that knowledge to solve the technical AI alignment problem. He's one of the few people who both understands why alignment is hard and is taking a serious technical shot at solving it.We cover his "two subsystems" model of the brain, why current AI safety approaches miss the mark, his disagreements with social evolution approaches, and why understanding human neuroscience matters for building aligned AGI.* 00:00:00 - Cold Open: Solving the technical alignment problem* 00:00:26 - Introducing Dr. Steven Byrnes and his impressive background* 00:01:59 - Steve's unique mental strengths* 00:04:08 - The cold fusion research story demonstrating Steve's approach* 00:06:18 - How Steve got interested in neuroscience through Jeff Hawkins* 00:08:18 - Jeff Hawkins' cortical uniformity theory and brain vs deep learning* 00:11:45 - When Steve first encountered Eliezer's sequences and became AGI-pilled* 00:15:11 - Steve's research direction: reverse engineering human social instincts* 00:21:47 - Four visions of alignment success and Steve's preferred approach* 00:29:00 - The two brain subsystems model: steering brain vs learning brain* 00:35:30 - Brain volume breakdown and the learning vs steering distinction* 00:38:43 - Cerebellum as the "LLM" of the brain doing predictive learning* 00:46:44 - Language acquisition: Chomsky vs learning algorithms debate* 00:54:13 - What LLMs fundamentally can't do: complex context limitations* 01:07:17 - Hypothalamus and brainstem doing more than just homeostasis* 01:13:45 - Why morality might just be another hypothalamus cell group* 01:18:00 - Human social instincts as model-based reinforcement learning* 01:22:47 - Actor-critic reinforcement learning mapped to brain regions* 01:29:33 - Timeline predictions: when brain-like AGI might arrive* 01:38:28 - Why humans still beat AI on strategic planning and domain expertise* 01:47:27 - Inner vs outer alignment: cocaine example and reward prediction* 01:55:13 - Why legible Python code beats learned reward models* 02:00:45 - Outcome pumps, instrumental convergence, and the Stalin analogy* 02:11:48 - What’s Your P(Doom)™* 02:16:45 - Massive headroom above human intelligence* 02:20:45 - Can AI take over without physical actuators? (Yes)* 02:26:18 - Steve's bold claim: 30 person-years from proto-AGI to superintelligence* 02:32:17 - Why overhang makes the transition incredibly dangerous* 02:35:00 - Social evolution as alignment solution: why it won't work* 02:46:47 - Steve's research program: legible reward functions vs RLHF* 02:59:52 - AI policy discussion: why Steven is skeptical of pause AI* 03:05:51 - Lightning round: offense vs defense, P(simulation), AI unemployment* 03:12:42 - Thanking Steve and wrapping up the conversation* 03:13:30 - Liron's outro: Supporting the show and upcoming episodes with Vitalik and EliezerShow Notes* Steven Byrnes' Website & Research — https://sjbyrnes.com/* Steve’s Twitter — https://x.com/steve47285* Astera Institute — https://astera.org/Steve’s Sequences* Intro to Brain-Like-AGI Safety — https://www.alignmentforum.org/s/HzcM2dkCq7fwXBej8* Foom & Doom 1: “Brain in a box in a basement” — https://www.alignmentforum.org/posts/yew6zFWAKG4AGs3Wk/foom-and-doom-1-brain-in-a-box-in-a-basement* Foom & Doom 2: Technical alignment is hard — https://www.alignmentforum.org/posts/bnnKGSCHJghAvqPjS/foom-and-doom-2-technical-alignment-is-hard---Doom Debates’ Mission is to raise mainstream awareness of imminent extinction from AGI and build the social infrastructure for high-quality debate.Support the mission by subscribing to my Substack at DoomDebates.com and to youtube.com/@DoomDebates Get full access to Doom Debates at lironshapira.substack.com/subscribe

Top Professor Condemns AGI Development: “It’s Frankly Evil” — Geoffrey Miller
Geoffrey Miller is an evolutionary psychologist at the University of New Mexico, bestselling author, and one of the world's leading experts on signaling theory and human sexual selection. His book "Mate" was hugely influential for me personally during my dating years, so I was thrilled to finally get him on the show.In this episode, Geoffrey drops a bombshell 50% P(Doom) assessment, coming from someone who wrote foundational papers on neural networks and genetic algorithms back in the '90s before pivoting to study human mating behavior for 30 years.What makes Geoffrey's doom perspective unique is that he thinks both inner and outer alignment might be unsolvable in principle, ever. He's also surprisingly bearish on AI's current value, arguing it hasn't been net positive for society yet despite the $14 billion in OpenAI revenue.We cover his fascinating intellectual journey from early AI researcher to pickup artist advisor to AI doomer, why Asperger's people make better psychology researchers, the polyamory scene in rationalist circles, and his surprisingly optimistic take on cooperating with China. Geoffrey brings a deeply humanist perspective. He genuinely loves human civilization as it is and sees no reason to rush toward our potential replacement.* 00:00:00 - Introducing Prof. Geoffrey Miller* 00:01:46 - Geoffrey’s intellectual career arc: AI → evolutionary psychology → back to AI* 00:03:43 - Signaling theory as the main theme driving his research* 00:05:04 - Why evolutionary psychology is legitimate science, not just speculation* 00:08:18 - Being a professor in the AI age and making courses "AI-proof"* 00:09:12 - Getting tenure in 2008 and using academic freedom responsibly* 00:11:01 - Student cheating epidemic with AI tools, going "fully medieval"* 00:13:28 - Should professors use AI for grading? (Geoffrey says no, would be unethical)* 00:23:06 - Coming out as Aspie and neurodiversity in academia* 00:29:15 - What is sex and its role in evolution (error correction vs. variation)* 00:34:06 - Sexual selection as an evolutionary "supercharger"* 00:37:25 - Dating advice, pickup artistry, and evolutionary psychology insights* 00:45:04 - Polyamory: Geoffrey’s experience and the rationalist connection* 00:50:96 - Why rationalists tend to be poly vs. Chesterton's fence on monogamy* 00:54:07 - The "primal" lifestyle and evolutionary medicine* 00:56:59 - How Iain M. Banks' Culture novels shaped Geoffrey’s AI thinking* 01:05:26 - What’s Your P(Doom)™* 01:08:04 - Main doom scenario: AI arms race leading to unaligned ASI* 01:14:10 - Bad actors problem: antinatalists, religious extremists, eco-alarmists* 01:21:13 - Inner vs. outer alignment - both may be unsolvable in principle* 01:23:56 - "What's the hurry?" - Why rush when alignment might take millennia?* 01:28:17 - Disagreement on whether AI has been net positive so far* 01:35:13 - Why AI won't magically solve longevity or other major problems* 01:37:56 - Unemployment doom and loss of human autonomy* 01:40:13 - Cosmic perspective: We could be "the baddies" spreading unaligned AI* 01:44:93 - "Humanity is doing incredibly well" - no need for Hail Mary AI* 01:49:01 - Why ASI might be bad at solving alignment (lacks human cultural wisdom)* 01:52:06 - China cooperation: "Whoever builds ASI first loses"* 01:55:19 - Liron’s OutroShow NotesLinks* Geoffrey’s Twitter* Geoffrey’s University of New Mexico Faculty Page* Geoffrey’s Publications* Designing Neural Networks using Genetic Algorithms - His most cited paper* Geoffrey’s Effective Altruism Forum PostsBooks by Geoffrey Miller* Mate: Become the Man Women Want (2015) - Co-authored with Tucker Max* The Mating Mind: How Sexual Choice Shaped the Evolution of Human Nature (2000)* Virtue Signaling: Essays on Darwinian Politics and Free Speech (2019)* Spent: Sex, Evolution, and Consumer Behavior (2009)Related Doom Debates Episodes* Liam Robins on College in the AGI Era - Student perspective on AI cheating* Liron Reacts to Steven Pinker on AI Risk - Critiquing Pinker's AI optimism* Steven Byrnes on Brain-Like AGI - Upcoming episode on human brain architecture---Doom Debates’ Mission is to raise mainstream awareness of imminent extinction from AGI and build the social infrastructure for high-quality debate.Support the mission by subscribing to my Substack at DoomDebates.com and to youtube.com/@DoomDebates Get full access to Doom Debates at lironshapira.substack.com/subscribe
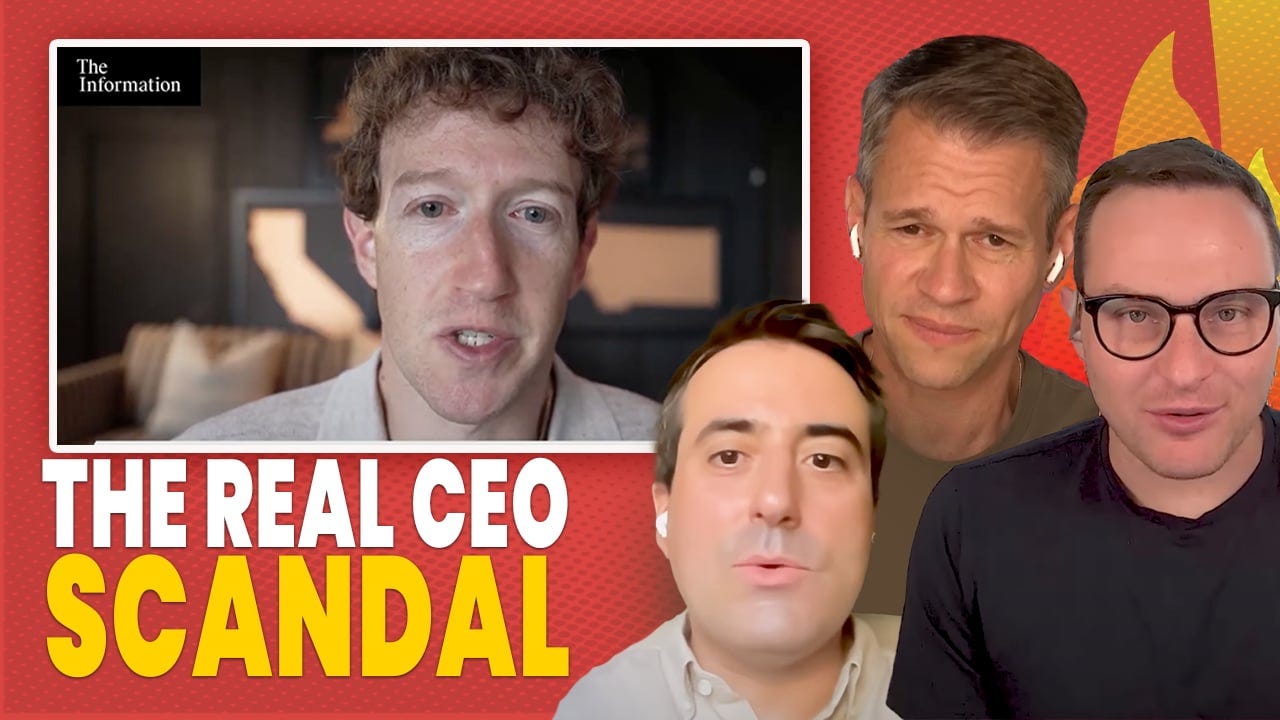
Zuck’s Superintelligence Agenda is a SCANDAL | Warning Shots EP1
I’m doing a new weekly show on the AI Risk Network called Warning Shots. Check it out!I’m only cross-posting the first episode here on Doom Debates. You can watch future episodes by subscribing to the AI Risk Network channel.This week's warning shot: Mark Zuckerberg announced that Meta is racing toward recursive self-improvement and superintelligence. His exact words: "Developing superintelligence is now in sight and we just want to make sure that we really strengthen the effort as much as possible to go for it." This should be front-page news. Instead, everyone's talking about some CEO's dumb shenanigans at a Coldplay concert.Recursive self-improvement is when AI systems start upgrading themselves - potentially the last invention humanity ever makes. Every AI safety expert knows this is a bright red line. And Zuckerberg just said he's sprinting toward it. In a sane world, he'd have to resign for saying this. That's why we made this show - to document these warning shots as they happen, because someone needs to be paying attention* 00:00 - Opening comments about Zuckerberg and superintelligence* 00:51 - Show introductions and host backgrounds* 01:56 - Geoff Lewis psychotic episode and ChatGPT interaction discussion* 05:04 - Transition to main warning shot about Mark Zuckerberg* 05:32 - Zuckerberg's recursive self-improvement audio clip* 08:22 - Second Zuckerberg clip about "going for superintelligence"* 10:29 - Analysis of "superintelligence in everyone's pocket"* 13:07 - Discussion of Zuckerberg's true motivations* 15:13 - Nuclear development analogy and historical context* 17:39 - What should happen in a sane society (wrap-up)* 20:01 - Final thoughts and sign-offShow NotesHosts:* Doom Debates - Liron Shapira's channel* AI Risk Network - John Sherman's channel* Lethal Intelligence - Michael's animated AI safety contentThis Episode's Warning Shots:* Mark Zuckerberg podcast appearance discussing superintelligence* Geoff Lewis (Bedrock VC) Twitter breakdown---Doom Debates’ Mission is to raise mainstream awareness of imminent extinction from AGI and build the social infrastructure for high-quality debate.Support the mission by subscribing to my Substack at DoomDebates.com and to youtube.com/@DoomDebates Get full access to Doom Debates at lironshapira.substack.com/subscribe
Rationalist Podcasts Unite! — The Bayesian Conspiracy ⨉ Doom Debates Crossover
Eneasz Brodski and Steven Zuber host the Bayesian Conspiracy podcast, which has been running for nine years and covers rationalist topics from AI safety to social dynamics. They're both OG rationalists who've been in the community since the early LessWrong days around 2007-2010. I've been listening to their show since the beginning, and finally got to meet my podcast heroes!In this episode, we get deep into the personal side of having a high P(Doom) — how do you actually live a good life when you think there's a 50% chance civilization ends by 2040? We also debate whether spreading doom awareness helps humanity or just makes people miserable, with Eneasz pushing back on my fearmongering approach.We also cover my Doom Train framework for systematically walking through AI risk arguments, why most guests never change their minds during debates, the sorry state of discourse on tech Twitter, and how rationalists can communicate better with normies. Plus some great stories from the early LessWrong era, including my time sitting next to Eliezer while he wrote Harry Potter and the Methods of Rationality.* 00:00 - Opening and introductions* 00:43 - Origin stories: How we all got into rationalism and LessWrong* 03:42 - Liron's incredible story: Sitting next to Eliezer while he wrote HPMOR* 06:19 - AI awakening moments: ChatGPT, AlphaGo, and move 37* 13:48 - Do AIs really "understand" meaning? Symbol grounding and consciousness* 26:21 - Liron's 50% P(Doom) by 2040 and the Doom Debates mission* 29:05 - The fear mongering debate: Does spreading doom awareness hurt people?* 34:43 - "Would you give 95% of people 95% P(Doom)?" - The recoil problem* 42:02 - How to live a good life with high P(Doom)* 45:55 - Economic disruption predictions and Liron's failed unemployment forecast* 57:19 - The Doom Debates project: 30,000 watch hours and growing* 58:43 - The Doom Train framework: Mapping the stops where people get off* 1:03:19 - Why guests never change their minds (and the one who did)* 1:07:08 - Communication advice: "Zooming out" for normies* 1:09:39 - The sorry state of arguments on tech Twitter* 1:24:11 - Do guests get mad? The hologram effect of debates* 1:30:11 - Show recommendations and final thoughtsShow NotesThe Bayesian Conspiracy — https://www.thebayesianconspiracy.comDoom Debates episode with Mike Israetel — https://www.youtube.com/watch?v=RaDWSPMdM4oDoom Debates episode with David Duvenaud — https://www.youtube.com/watch?v=mb9w7lFIHRMDoom Debates’ Mission is to raise mainstream awareness of imminent extinction from AGI and build the social infrastructure for high-quality debate.Support the mission by subscribing to my Substack at DoomDebates.com and to youtube.com/@DoomDebates Get full access to Doom Debates at lironshapira.substack.com/subscribe

His P(Doom) Doubles At The End — AI Safety Debate with Liam Robins, GWU Sophomore
Liam Robins is a math major at George Washington University who's diving deep into AI policy and rationalist thinking.In Part 1, we explored how AI is transforming college life. Now in Part 2, we ride the Doom Train together to see if we can reconcile our P(Doom) estimates. 🚂Liam starts with a P(Doom) of just 3%, but as we go through the stops on the Doom Train, something interesting happens: he actually updates his beliefs in realtime!We get into heated philosophical territory around moral realism, psychopaths, and whether intelligence naturally yields moral goodness.By the end, Liam's P(Doom) jumps from 3% to 8% - one of the biggest belief updates I've ever witnessed on the show. We also explore his "Bayes factors" approach to forecasting, debate the reliability of superforecasters vs. AI insiders, and discuss why most AI policies should be Pareto optimal regardless of your P(Doom).This is rationality in action: watching someone systematically examine their beliefs, engage with counterarguments, and update accordingly.0:00 - Opening0:42 - What’s Your P(Doom)™01:18 - Stop 1: AGI timing (15% chance it's not coming soon)01:29 - Stop 2: Intelligence limits (1% chance AI can't exceed humans)01:38 - Stop 3: Physical threat assessment (1% chance AI won't be dangerous)02:14 - Stop 4: Intelligence yields moral goodness - the big debate begins04:42 - Moral realism vs. evolutionary explanations for morality06:43 - The psychopath problem: smart but immoral humans exist08:50 - Game theory and why psychopaths persist in populations10:21 - Liam's first major update: 30% down to 15-20% on moral goodness12:05 - Stop 5: Safe AI development process (20%)14:28 - Stop 6: Manageable capability growth (20%)15:38 - Stop 7: AI conquest intentions - breaking down into subcategories17:03 - Alignment by default vs. deliberate alignment efforts19:07 - Stop 8: Super alignment tractability (20%)20:49 - Stop 9: Post-alignment peace (80% - surprisingly optimistic)23:53 - Stop 10: Unaligned ASI mercy (1% - "just cope")25:47 - Stop 11: Epistemological concerns about doom predictions27:57 - Bayes factors analysis: Why Liam goes from 38% to 3%30:21 - Bayes factor 1: Historical precedent of doom predictions failing33:08 - Bayes factor 2: Superforecasters think we'll be fine39:23 - Bayes factor 3: AI insiders and government officials seem unconcerned45:49 - Challenging the insider knowledge argument with concrete examples48:47 - The privilege access epistemology debate56:02 - Major update: Liam revises base factors, P(Doom) jumps to 8%58:18 - Odds ratios vs. percentages: Why 3% to 8% is actually huge59:14 - AI policy discussion: Pareto optimal solutions across all P(Doom) levels1:01:59 - Why there's low-hanging fruit in AI policy regardless of your beliefs1:04:06 - Liam's future career plans in AI policy1:05:02 - Wrap-up and reflection on rationalist belief updatingShow Notes* Liam Robins on Substack -* Liam’s Doom Train post -* Liam’s Twitter - @liamhrobinsAnthropic's "Alignment Faking in Large Language Models" - The paper that updated Liam's beliefs on alignment by default---Doom Debates’ Mission is to raise mainstream awareness of imminent extinction from AGI and build the social infrastructure for high-quality debate.Support the mission by subscribing to my Substack at DoomDebates.com and to youtube.com/@DoomDebates Get full access to Doom Debates at lironshapira.substack.com/subscribe

AI Won't Save Your Job — Liron Reacts to Replit CEO Amjad Masad
Amjad Masad is the founder and CEO of Replit, a full-featured AI-powered software development platform whose revenue reportedly just shot up from $10M/yr to $100M/yr+.Last week, he went on Joe Rogan to share his vision that "everyone will become an entrepreneur" as AI automates away traditional jobs.In this episode, I break down why Amjad's optimistic predictions rely on abstract hand-waving rather than concrete reasoning. While Replit is genuinely impressive, his claims about AI limitations—that they can only "remix" and do "statistics" but can't "generalize" or create "paradigm shifts"—fall apart when applied to specific examples.We explore the entrepreneurial bias problem, why most people can't actually become successful entrepreneurs, and how Amjad's own success stories (like quality assurance automation) actually undermine his thesis. Plus: Roger Penrose's dubious consciousness theories, the "Duplo vs. Lego" problem in abstract thinking, and why Joe Rogan invited an AI doomer the very next day.00:00 - Opening and introduction to Amjad Masad03:15 - "Everyone will become an entrepreneur" - the core claim08:45 - Entrepreneurial bias: Why successful people think everyone can do what they do15:20 - The brainstorming challenge: Human vs. AI idea generation22:10 - "Statistical machines" and the remixing framework28:30 - The abstraction problem: Duplos vs. Legos in reasoning35:50 - Quantum mechanics and paradigm shifts: Why bring up Heisenberg?42:15 - Roger Penrose, Gödel's theorem, and consciousness theories52:30 - Creativity definitions and the moving goalposts58:45 - The consciousness non-sequitur and Silicon Valley "hubris"01:07:20 - Ahmad George success story: The best case for Replit01:12:40 - Job automation and the 50% reskilling assumption01:18:15 - Quality assurance jobs: Accidentally undermining your own thesis01:23:30 - Online learning and the contradiction in AI capabilities01:29:45 - Superintelligence definitions and learning in new environments01:35:20 - Self-play limitations and literature vs. programming01:41:10 - Marketing creativity and the Think Different campaign01:45:45 - Human-machine collaboration and the prompting bottleneck01:50:30 - Final analysis: Why this reasoning fails at specificity01:58:45 - Joe Rogan's real opinion: The Roman Yampolskiy follow-up02:02:30 - Closing thoughtsShow NotesSource video: Amjad Masad on Joe Rogan - July 2, 2025Roman Yampolskiy on Joe Rogan - https://www.youtube.com/watch?v=j2i9D24KQ5kReplit - https://replit.comAmjad’s Twitter - https://x.com/amasadDoom Debates episode where I react to Emmett Shear’s Softmax - https://www.youtube.com/watch?v=CBN1E1fvh2gDoom Debates episode where I react to Roger Penrose - https://www.youtube.com/watch?v=CBN1E1fvh2g---Doom Debates’ Mission is to raise mainstream awareness of imminent extinction from AGI and build the social infrastructure for high-quality debate.Support the mission by subscribing to my Substack at DoomDebates.com and to youtube.com/@DoomDebates Get full access to Doom Debates at lironshapira.substack.com/subscribe

Every Student is CHEATING with AI — College in the AGI Era (feat. Sophomore Liam Robins)
Liam Robins is a math major at George Washington University who recently had his own "AGI awakening" after reading Leopold Aschenbrenner's Situational Awareness. I met him at my Manifest 2025 talk about stops on the Doom Train.In this episode, Liam confirms what many of us suspected: pretty much everyone in college is cheating with AI now, and they're completely shameless about it.We dive into what college looks like today: how many students are still "rawdogging" lectures, how professors are coping with widespread cheating, how the social life has changed, and what students think they’ll do when they graduate.* 00:00 - Opening* 00:50 - Introducing Liam Robins* 05:27 - The reality of college today: Do they still have lectures?* 07:20 - The rise of AI-enabled cheating in assignments* 14:00 - College as a credentialing regime vs. actual learning* 19:50 - "Everyone is cheating their way through college" - the epidemic* 26:00 - College social life: "It's just pure social life"* 31:00 - Dating apps, social media, and Gen Z behavior* 36:21 - Do students understand the singularity is near?Show NotesGuest:* Liam Robins on Substack - https://thelimestack.substack.com/* Liam's Doom Train post - https://thelimestack.substack.com/p/my-pdoom-is-276-heres-why* Liam’s Twitter - @liamrobinsKey References:* Leopold Aschenbrenner - "Situational Awareness"* Bryan Caplan - "The Case Against Education"* Scott Alexander - Astral Codex Ten* Jeffrey Ding - ChinAI Newsletter* New York Magazine - "Everyone Is Cheating Their Way Through College"Events & Communities:* Manifest Conference* LessWrong* Eliezer Yudkowsky - "Harry Potter and the Methods of Rationality"Previous Episodes:* Doom Debates Live at Manifest 2025 - https://www.youtube.com/watch?v=detjIyxWG8MDoom Debates’ Mission is to raise mainstream awareness of imminent extinction from AGI and build the social infrastructure for high-quality debate.Support the mission by subscribing to my Substack at DoomDebates.com and to youtube.com/@DoomDebates Get full access to Doom Debates at lironshapira.substack.com/subscribe
Carl Feynman, AI Engineer & Son of Richard Feynman, Says Building AGI Likely Means Human EXTINCTION!
Carl Feynman got his Master’s in Computer Science and B.S. in Philosophy from MIT, followed by a four-decade career in AI engineering.He’s known Eliezer Yudkowsky since the ‘90s, and witnessed Eliezer’s AI doom argument taking shape before most of us were paying any attention!He agreed to come on the show because he supports Doom Debates’s mission of raising awareness of imminent existential risk from superintelligent AI.00:00 - Teaser00:34 - Carl Feynman’s Background02:40 - Early Concerns About AI Doom03:46 - Eliezer Yudkowsky and the Early AGI Community05:10 - Accelerationist vs. Doomer Perspectives06:03 - Mainline Doom Scenarios: Gradual Disempowerment vs. Foom07:47 - Timeline to Doom: Point of No Return08:45 - What’s Your P(Doom)™09:44 - Public Perception and Political Awareness of AI Risk11:09 - AI Morality, Alignment, and Chatbots Today13:05 - The Alignment Problem and Competing Values15:03 - Can AI Truly Understand and Value Morality?16:43 - Multiple Competing AIs and Resource Competition18:42 - Alignment: Wanting vs. Being Able to Help Humanity19:24 - Scenarios of Doom and Odds of Success19:53 - Mainline Good Scenario: Non-Doom Outcomes20:27 - Heaven, Utopia, and Post-Human Vision22:19 - Gradual Disempowerment Paper and Economic Displacement23:31 - How Humans Get Edged Out by AIs25:07 - Can We Gaslight Superintelligent AIs?26:38 - AI Persuasion & Social Influence as Doom Pathways27:44 - Riding the Doom Train: Headroom Above Human Intelligence29:46 - Orthogonality Thesis and AI Motivation32:48 - Alignment Difficulties and Deception in AIs34:46 - Elon Musk, Maximal Curiosity & Mike Israetel’s Arguments36:26 - Beauty and Value in a Post-Human Universe38:12 - Multiple AIs Competing39:31 - Space Colonization, Dyson Spheres & Hanson’s “Alien Descendants”41:13 - What Counts as Doom vs. Not Doom?43:29 - Post-Human Civilizations and Value Function44:49 - Expertise, Rationality, and Doomer Credibility46:09 - Communicating Doom: Missing Mood & Public Receptiveness47:41 - Personal Preparation vs. Belief in Imminent Doom48:56 - Why Can't We Just Hit the Off Switch?50:26 - The Treacherous Turn and Redundancy in AI51:56 - Doom by Persuasion or Entertainment53:43 - Differences with Eliezer Yudkowsky: Singleton vs. Multipolar Doom55:22 - Why Carl Chose Doom Debates56:18 - Liron’s OutroShow NotesCarl’s Twitter — https://x.com/carl_feynmanCarl’s LessWrong — https://www.lesswrong.com/users/carl-feynmanGradual Disempowerment — https://gradual-disempowerment.aiThe Intelligence Curse — https://intelligence-curse.aiAI 2027 — https://ai-2027.comAlcor cryonics — https://www.alcor.orgThe LessOnline Conference — https://less.onlineWatch the Lethal Intelligence Guide, the ultimate introduction to AI x-risk!PauseAI, the volunteer organization I’m part of: https://pauseai.infoJoin the PauseAI Discord — https://discord.gg/2XXWXvErfA — and say hi to me in the #doom-debates-podcast channel!Doom Debates’ Mission is to raise mainstream awareness of imminent extinction from AGI and build the social infrastructure for high-quality debate.Support the mission by subscribing to my Substack at DoomDebates.com and to youtube.com/@DoomDebates Get full access to Doom Debates at lironshapira.substack.com/subscribe

Richard Hanania vs. Liron Shapira — AI Doom Debate
Richard Hanania is the President of the Center for the Study of Partisanship and Ideology. His work has been praised by Vice President JD Vance, Tyler Cowen, and Bryan Caplan among others.In his influential newsletter, he’s written about why he finds AI doom arguments unconvincing. He was gracious enough to debate me on this topic. Let’s see if one of us can change the other’s P(Doom)!0:00 Intro1:53 Richard's politics2:24 The state of political discourse3:30 What's your P(Doom)?™6:38 How to stop the doom train8:27 Statement on AI risk9:31 Intellectual influences11:15 Base rates for AI doom15:43 Intelligence as optimization power31:26 AI capabilities progress53:46 Why isn't AI yet a top blogger?58:02 Diving into Richard's Doom Train58:47 Diminishing Returns on Intelligence1:06:36 Alignment will be relatively trivial1:15:14 Power-seeking must be programmed1:21:27 AI will simply be benevolent1:27:17 Superintelligent AI will negotiate with humans1:33:00 Super AIs will check and balance each other out1:36:54 We're mistaken about the nature of intelligence1:41:46 Summarizing Richard's AI doom position1:43:22 Jobpocalypse and gradual disempowerment1:49:46 Ad hominem attacks in AI discourseShow NotesSubscribe to Richard Hanania's Newsletter: https://richardhanania.comRichard's blogpost laying out where he gets off the AI "doom train": https://www.richardhanania.com/p/ai-doomerism-as-science-fictionRichard's interview with Steven Pinker: https://www.richardhanania.com/p/pinker-on-alignment-and-intelligenceRichard's interview with Robin Hanson: https://www.richardhanania.com/p/robin-hanson-says-youre-going-toMy Doom Debate with Robin Hanson: https://www.youtube.com/watch?v=dTQb6N3_zu8My reaction to Steven Pinker's AI doom position, and why his arguments are shallow: https://www.youtube.com/watch?v=-tIq6kbrF-4"The Betterness Explosion" by Robin Hanson: https://www.overcomingbias.com/p/the-betterness-explosionhtml---Watch the Lethal Intelligence Guide, the ultimate introduction to AI x-risk! https://www.youtube.com/watch?v=9CUFbqh16FgPauseAI, the volunteer organization I’m part of: https://pauseai.infoJoin the PauseAI Discord — https://discord.gg/2XXWXvErfA — and say hi to me in the #doom-debates-podcast channel!---Doom Debates’ Mission is to raise mainstream awareness of imminent extinction from AGI and build the social infrastructure for high-quality debate.Support the mission by subscribing to my Substack at https://DoomDebates.com and to https://youtube.com/@DoomDebates Get full access to Doom Debates at lironshapira.substack.com/subscribe
Emmett Shear (OpenAI Ex-Interim-CEO)'s New “Softmax” AI Alignment Plan — Is It Legit?
Emmett Shear is the cofounder and ex-CEO of Twitch, ex-interim-CEO of OpenAI, and a former Y Combinator partner. He recently announced Softmax, a new company researching a novel solution to AI alignment.In his recent interview, Emmett explained “organic alignment”, drawing comparisons to biological systems and advocating for AI to be raised in a community-like setting with humans.Let’s go through his talk, point by point, to see if Emmett’s alignment plan makes sense…00:00 Episode Highlights00:36 Introducing Softmax and its Founders01:33 Research Collaborators and Ken Stanley's Influence02:16 Softmax's Mission and Organic Alignment03:13 Critique of Organic Alignment05:29 Emmett’s Perspective on AI Alignment14:36 Human Morality and Cognitive Submodules38:25 Top-Down vs. Emergent Morality in AI44:56 Raising AI to Grow Up with Humanity48:43 Softmax's Incremental Approach to AI Alignment52:22 Convergence vs. Divergence in AI Learning55:49 Multi-Agent Reinforcement Learning01:12:28 The Importance of Storytelling in AI Development01:16:34 Living With AI As It Grows01:20:19 Species Giving Birth to Species01:23:23 The Plan for AI's Adolescence01:26:53 Emmett's Views on Superintelligence01:31:00 The Future of AI Alignment01:35:10 Final Thoughts and Criticisms01:44:07 Conclusion and Call to ActionShow NotesEmmett Shear’s interview on BuzzRobot with Sophia Aryan (source material) — https://www.youtube.com/watch?v=_3m2cpZqvdwBuzzRobot’s YouTube channel — https://www.youtube.com/@BuzzRobotBuzzRobot’s Twitter — https://x.com/buZZrobot/SoftMax’s website — https://softmax.comMy Doom Debate with Ken Stanley (Softmax advisor) — https://www.youtube.com/watch?v=GdthPZwU1CoMy Doom Debate with Gil Mark on whether aligning AIs in groups is a more solvable problem — https://www.youtube.com/watch?v=72LnKW_jae8Watch the Lethal Intelligence Guide, the ultimate introduction to AI x-risk!PauseAI, the volunteer organization I’m part of: https://pauseai.infoJoin the PauseAI Discord — https://discord.gg/2XXWXvErfA — and say hi to me in the #doom-debates-podcast channel!Doom Debates’ Mission is to raise mainstream awareness of imminent extinction from AGI and build the social infrastructure for high-quality debate.Support the mission by subscribing to my Substack at DoomDebates.com and to youtube.com/@DoomDebates Get full access to Doom Debates at lironshapira.substack.com/subscribe
Will AI Have a Moral Compass? — Debate with Scott Sumner, Author of The Money Illusion
Prof. Scott Sumner is a well-known macroeconomist who spent more than 30 years teaching at Bentley University, and now holds an Emeritus Chair in monetary policy at George Mason University's Mercatus Center. He's best known for his blog, the Money Illusion, which sparked the idea of Market Monetarism and NGDP targeting.I sat down with him at LessOnline 2025 to debate why his P(Doom) is pretty low. Where does he get off the Doom Train? 🚂00:00 Episode Preview00:34 Introducing Scott Sumner05:20 Is AGI Coming Soon?09:12 Potential of AI in Various Fields36:49 Ethical Implications of Superintelligent AI41:03 The Nazis as an Outlier in History43:36 Intelligence and Morality: The Orthogonality Thesis49:03 The Risk of Misaligned AI Goals01:09:31 Recapping Scott’s PositionShow NotesScott’s current blog, The Pursuit of Happiness:Watch the Lethal Intelligence Guide, the ultimate introduction to AI x-risk!PauseAI, the volunteer organization I’m part of: https://pauseai.infoJoin the PauseAI Discord — https://discord.gg/2XXWXvErfA — and say hi to me in the #doom-debates-podcast channel!Doom Debates’ Mission is to raise mainstream awareness of imminent extinction from AGI and build the social infrastructure for high-quality debate.Support the mission by subscribing to my Substack at DoomDebates.com and to youtube.com/@DoomDebates Get full access to Doom Debates at lironshapira.substack.com/subscribe
Searle's Chinese Room is DUMB — It's Just Slow-Motion Intelligence
John Searle's "Chinese Room argument" has been called one of the most famous thought experiments of the 20th century. It's still frequently cited today to argue AI can never truly become intelligent.People continue to treat the Chinese Room like a brilliant insight, but in my opinion, it's actively misleading and DUMB! Here’s why…00:00 Intro00:20 What is Searle's Chinese Room Argument?01:43 John Searle (1984) on Why Computers Can't Understand01:54 Why the "Chinese Room" Metaphor is MisleadingThis mini-episode is taken from Liron's reaction to Sir Roger Penrose. Watch the full episode:Show Notes2008 Interview with John Searle: https://www.youtube.com/watch?v=3TnBjLmQawQ&t=253s1984 Debate with John Searle: https://www.youtube.com/watch?v=6tzjcnPsZ_w“Chinese Room” cartoon: https://miro.medium.com/v2/0*iTvDe5ebNPvg10AO.jpegWatch the Lethal Intelligence Guide, the ultimate introduction to AI x-risk!PauseAI, the volunteer organization I’m part of: https://pauseai.infoJoin the PauseAI Discord — https://discord.gg/2XXWXvErfA — and say hi to me in the #doom-debates-podcast channel!Doom Debates’ Mission is to raise mainstream awareness of imminent extinction from AGI and build the social infrastructure for high-quality debate.Support the mission by subscribing to my Substack at DoomDebates.com and to youtube.com/@DoomDebates Get full access to Doom Debates at lironshapira.substack.com/subscribe

Doom Debates Live @ Manifest 2025 — Liron vs. Everyone
Let’s see where the attendees of Manifest 2025 get off the Doom Train, and whether I can convince them to stay on and ride with me to the end of the line!00:00 Introduction to Doom Debates03:21 What’s Your P(Doom)?™05:03 🚂 “AGI Isn't Coming Soon”08:37 🚂 “AI Can't Surpass Human Intelligence”12:20 🚂 “AI Won't Be a Physical Threat”13:39 🚂 “Intelligence Yields Moral Goodness”17:21 🚂 “Safe AI Development Process”17:38 🚂 “AI Capabilities Will Rise at a Manageable Pace”20:12 🚂 “AI Won't Try to Conquer the Universe”25:00 🚂 “Superalignment Is A Tractable Problem”28:58 🚂 “Once We Solve Superalignment, We’ll Enjoy Peace”31:51 🚂 “Unaligned ASI Will Spare Us”36:40 🚂 “AI Doomerism Is Bad Epistemology”40:11 Bonus 🚂: “Fine, P(Doom) is high… but that’s ok!”42:45 Recapping the DebateSee also my previous episode explaining the Doom Train: https://lironshapira.substack.com/p/poking-holes-in-the-ai-doom-argumentWatch the Lethal Intelligence Guide, the ultimate introduction to AI x-risk!PauseAI, the volunteer organization I’m part of: https://pauseai.infoJoin the PauseAI Discord — https://discord.gg/2XXWXvErfA — and say hi to me in the #doom-debates-podcast channel!Doom Debates’ Mission is to raise mainstream awareness of imminent extinction from AGI and build the social infrastructure for high-quality debate.Support the mission by subscribing to my Substack at DoomDebates.com and to youtube.com/@DoomDebates Get full access to Doom Debates at lironshapira.substack.com/subscribe
Poking holes in the AI doom argument — 83 stops where you could get off the “Doom Train”
I often talk about the “Doom Train”, the series of claims and arguments involved in concluding that P(Doom) from artificial superintelligence is high. In this episode, it’s finally time to show you the whole track!00:00 Introduction01:09 “AGI isn’t coming soon”04:42 “Artificial intelligence can’t go far beyond human intelligence”07:24 “AI won’t be a physical threat”08:28 “Intelligence yields moral goodness”09:39 “We have a safe AI development process”10:48 “AI capabilities will rise at a manageable pace”12:28 “AI won’t try to conquer the universe”15:12 “Superalignment is a tractable problem”16:55 “Once we solve superalignment, we’ll enjoy peace”19:02 “Unaligned ASI will spare us”20:12 “AI doomerism is bad epistemology”21:42 Bonus arguments: “Fine, P(Doom) is high… but that’s ok!”Stops on the Doom TrainAGI isn’t coming soon* No consciousness* No emotions* No creativity — AIs are limited to copying patterns in their training data, they can’t “generate new knowledge”* AIs aren’t even as smart as dogs right now, never mind humans* AIs constantly make dumb mistakes, they can’t even do simple arithmetic reliably* LLM performance is hitting a wall — GPT 4.5 is barely better than GPT 4.1 despite being larger scale* No genuine reasoning* No microtubules exploiting uncomputable quantum effects* No soul* We’ll need to build tons of data centers and power before we get to AGI* No agency* This is just another AI hype cycle, every 25 years people think AGI is coming soon and they’re wrongArtificial intelligence can’t go far beyond human intelligence* “Superhuman intelligence” is a meaningless concept* Human engineering already is coming close to the laws of physics* Coordinating a large engineering project can’t happen much faster than humans do it* No individual human is that smart compared to humanity as a whole, including our culture, corporations, and other institutions. Similarly no individual AI will ever be that smart compared to the sum of human culture and other institutions.AI won’t be a physical threat* AI doesn’t have arms or legs, it has zero control over the real world* An AI with a robot body can’t fight better than a human soldier* We can just disconnect an AI’s power to stop it* We can just turn off the internet to stop it* We can just shoot it with a gun* It’s just math* Any supposed chain of events where AI kills humans is far-fetched science fictionIntelligence yields moral goodness* More intelligence is correlated with more morality* Smarter people commit fewer crimes* The orthogonality thesis is false* AIs will discover moral realism* If we made AIs so smart, and we were trying to make them moral, then they’ll be smart enough to debug their own morality* Positive-sum cooperation was the outcome of natural selectionWe have a safe AI development process* Just like every new technology, we’ll figure it out as we go* We don’t know what problems need to be fixed until we build the AI and test it out* If an AI causes problems, we’ll be able to turn it off and release another version* We have safeguards to make sure AI doesn’t get uncontrollable/unstoppable* If we accidentally build an AI that stops accepting our shutoff commands, it won’t manage to copy versions of itself outside our firewalls which then proceed to spread exponentially like a computer virus* If we accidentally build an AI that escapes our data center and spreads exponentially like a computer virus, it won’t do too much damage in the world before we can somehow disable or neutralize all its copies* If we can’t disable or neutralize copies of rogue AIs, we’ll rapidly build other AIs that can do that job for us, and won’t themselves go rogue on usAI capabilities will rise at a manageable pace* Building larger data centers will be a speed bottleneck* Another speed bottleneck is the amount of research that needs to be done, both in terms of computational simulation, and in terms of physical experiments, and this kind of research takes lots of time* Recursive self-improvement “foom” is impossible* The whole economy never grows with localized centralized “foom”* Need to collect cultural learnings over time, like humanity did as a whole* AI is just part of the good pattern of exponential economic growth erasAI won’t try to conquer the universe* AIs can’t “want” things* AIs won’t have the same “fight instincts” as humans and animals, because they weren’t shaped by a natural selection process that involved life-or-death resource competition* Smart employees often work for less-smart bosses* Just because AIs help achieve goals doesn’t mean they have to be hard-core utility maximizers* Instrumental convergence is false: achieving goals effectively doesn’t mean you have to be relentlessly seizing power and resources* A resource-hungry goal-maximizer AIs wouldn’t seize literally every atom; there’ll still be some leftover resources for humanity* AIs will use new kinds of resources that humans aren’t using - dark energy, wormholes, alternate universes,

Q&A: Ilya's AGI Doomsday Bunker, Veo 3 is Westworld, Eliezer Yudkowsky, and much more!
Ilya’s doom bunker, proof of humanity, the doomsday argument, CAIS firing John Sherman, Bayesian networks, Westworld, AI consciousness, Eliezer’s latest podcast, and more!00:00 Introduction04:13 Doomsday Argument09:22 What if AI Alignment is *Intractable*?14:31 Steel-Manning the Nondoomers22:13 No State-Level AI Regulation for 10 years?32:31 AI Consciousness35:25 Westworld Is Real Now38:01 Proof of Humanity40:33 Liron’s Notary Network Idea43:34 Center for AI Safety and John Sherman Controversy57:04 Technological Advancements and Future Predictions01:03:14 Ilya Sutskever’s Doom Bunker01:07:32 The Future of AGI and Training Models01:12:19 Personal Experience of the Jetsons Future01:15:16 The Role of AI in Everyday Tasks01:18:54 Is General Intelligence A Binary Property?01:23:52 Does an Open Platform Help Make AI Safe?01:27:21 What of Understandable AI Like Bayesian Networks?01:30:28 Why Doom Isn’t Emotionally Real for LironShow NotesThe post where people submitted questions: https://lironshapira.substack.com/p/5000-subscribers-live-q-and-a-askWatch the Lethal Intelligence Guide, the ultimate introduction to AI x-risk!PauseAI, the volunteer organization I’m part of: https://pauseai.infoJoin the PauseAI Discord — https://discord.gg/2XXWXvErfA — and say hi to me in the #doom-debates-podcast channel!Doom Debates’ Mission is to raise mainstream awareness of imminent extinction from AGI and build the social infrastructure for high-quality debate.Support the mission by subscribing to my Substack at DoomDebates.com and to youtube.com/@DoomDebates Get full access to Doom Debates at lironshapira.substack.com/subscribe

This $85M-Backed Founder Claims Open Source AGI is Safe — Debate with Himanshu Tyagi
Dr. Himanshu Tyagi is a professor of engineering at the Indian Institute of Science and the co-founder of Sentient, an open-source AI platform that raised $85M in funding led by Founders Fund.In this conversation, Himanshu gives me Sentient’s pitch. Then we debate whether open-sourcing frontier AGI development is a good idea, or a reckless way to raise humanity’s P(doom).00:00 Introducing Himanshu Tyagi01:41 Sentient’s Vision05:20 How’d You Raise $85M?11:19 Comparing Sentient to Competitors27:26 Open Source vs. Closed Source AI43:01 What’s Your P(Doom)™48:44 Extinction from Superintelligent AI54:02 AI's Control Over Digital and Physical Assets01:00:26 AI's Influence on Human Movements01:08:46 Recapping the Debate01:13:17 Liron’s AnnouncementsShow NotesHimanshu’s Twitter — https://x.com/hstyagiSentient’s website — https://sentient.foundationCome to the Less Online conference on May 30 - Jun 1, 2025: https://less.onlineHope to see you there!If Anyone Builds It, Everyone Dies by Eliezer Yudkowsky and Nate Soares — https://ifanyonebuildsit.comWatch the Lethal Intelligence Guide, the ultimate introduction to AI x-risk! https://www.youtube.com/@lethal-intelligencePauseAI, the volunteer organization I’m part of: https://pauseai.infoJoin the PauseAI Discord — https://discord.gg/2XXWXvErfA — and say hi to me in the #doom-debates-podcast channel!Doom Debates’ Mission is to raise mainstream awareness of imminent extinction from AGI and build the social infrastructure for high-quality debate.Support the mission by subscribing to my Substack at https://doomdebates.com and to https://youtube.com/@DoomDebates Get full access to Doom Debates at lironshapira.substack.com/subscribe

Emergency Episode: Center for AI Safety Chickens Out
My friend John from the AI X-Risk Network podcast got hired by the Center for AI Safety (CAIS) two weeks ago.Today I suddenly learned he’s been fired.I’m frustrated by this decision, and frustrated with the whole AI x-risk community’s weak messaging.Come to the Less Online conference on May 30 - Jun 1, 2025: https://less.onlineHope to see you there!Watch the Lethal Intelligence Guide, the ultimate introduction to AI x-risk! https://www.youtube.com/@lethal-intelligencePauseAI, the volunteer organization I’m part of: https://pauseai.infoJoin the PauseAI Discord — https://discord.gg/2XXWXvErfA — and say hi to me in the #doom-debates-podcast channel!Doom Debates’ Mission is to raise mainstream awareness of imminent extinction from AGI and build the social infrastructure for high-quality debate.Support the mission by subscribing to my Substack at https://doomdebates.com and to https://youtube.com/@DoomDebates Get full access to Doom Debates at lironshapira.substack.com/subscribe

Gary Marcus vs. Liron Shapira — AI Doom Debate
Prof. Gary Marcus is a scientist, bestselling author and entrepreneur, well known as one of the most influential voices in AI. He is Professor Emeritus of Psychology and Neuroscience at NYU. He was founder and CEO of Geometric Intelligence, a machine learning company acquired by Uber in 2016.Gary co-authored the 2019 book, Rebooting AI: Building Artificial Intelligence We Can Trust, and the 2024 book, Taming Silicon Valley: How We Can Ensure That AI Works for Us. He played an important role in the 2023 Senate Judiciary Subcommittee Hearing on Oversight of AI, testifying with Sam Altman.In this episode, Gary and I have a lively debate about whether P(doom) is approximately 50%, or if it’s less than 1%!00:00 Introducing Gary Marcus02:33 Gary’s AI Skepticism09:08 The Human Brain is a Kluge23:16 The 2023 Senate Judiciary Subcommittee Hearing28:46 What’s Your P(Doom)™44:27 AI Timelines51:03 Is Superintelligence Real?01:00:35 Humanity’s Immune System01:12:46 Potential for Recursive Self-Improvement01:26:12 AI Catastrophe Scenarios01:34:09 Defining AI Agency01:37:43 Gary’s AI Predictions01:44:13 The NYTimes Obituary Test01:51:11 Recap and Final Thoughts01:53:35 Liron’s Outro01:55:34 Eliezer Yudkowsky’s New Book!01:59:49 AI Doom Concept of the DayShow NotesGary’s Substack — https://garymarcus.substack.comGary’s Twitter — https://x.com/garymarcusIf Anyone Builds It, Everyone Dies by Eliezer Yudkowsky and Nate Soares — https://ifanyonebuildsit.comCome to the Less Online conference on May 30 - Jun 1, 2025: https://less.onlineHope to see you there!Watch the Lethal Intelligence Guide, the ultimate introduction to AI x-risk! https://www.youtube.com/@lethal-intelligencePauseAI, the volunteer organization I’m part of: https://pauseai.infoJoin the PauseAI Discord — https://discord.gg/2XXWXvErfA — and say hi to me in the #doom-debates-podcast channel!Doom Debates’ Mission is to raise mainstream awareness of imminent extinction from AGI and build the social infrastructure for high-quality debate.Support the mission by subscribing to my Substack at https://doomdebates.com and to https://youtube.com/@DoomDebates Get full access to Doom Debates at lironshapira.substack.com/subscribe

Mike Israetel vs. Liron Shapira — AI Doom Debate
Dr. Mike Israetel, renowned exercise scientist and social media personality, and more recently a low-P(doom) AI futurist, graciously offered to debate me!00:00 Introducing Mike Israetel12:19 What’s Your P(Doom)™30:58 Timelines for Artificial General Intelligence34:49 Superhuman AI Capabilities43:26 AI Reasoning and Creativity47:12 Evil AI Scenario01:08:06 Will the AI Cooperate With Us?01:12:27 AI's Dependence on Human Labor01:18:27 Will AI Keep Us Around to Study Us?01:42:38 AI's Approach to Earth's Resources01:53:22 Global AI Policies and Risks02:03:02 The Quality of Doom Discourse02:09:23 Liron’s OutroShow Notes* Mike’s Instagram — https://www.instagram.com/drmikeisraetel* Mike’s YouTube — https://www.youtube.com/@MikeIsraetelMakingProgressCome to the Less Online conference on May 30 - Jun 1, 2025: https://less.onlineHope to see you there!Watch the Lethal Intelligence Guide, the ultimate introduction to AI x-risk! https://www.youtube.com/@lethal-intelligencePauseAI, the volunteer organization I’m part of: https://pauseai.infoJoin the PauseAI Discord — https://discord.gg/2XXWXvErfA — and say hi to me in the #doom-debates-podcast channel!Doom Debates’ Mission is to raise mainstream awareness of imminent extinction from AGI and build the social infrastructure for high-quality debate.Support the mission by subscribing to my Substack at https://doomdebates.com and to https://youtube.com/@DoomDebates Get full access to Doom Debates at lironshapira.substack.com/subscribe

Doom Scenario: Human-Level AI Can't Control Smarter AI
I want to be transparent about how I’ve updated my mainline AI doom scenario in light of safe & useful LLMs. So here’s where I’m at…00:00 Introduction07:59 The Dangerous Threshold to Runaway Superintelligence18:57 Superhuman Goal Optimization = Infinite Time Horizon21:21 Goal-Completeness by Analogy to Turing-Completeness26:53 Intellidynamics29:13 Goal-Optimization Is Convergent31:15 Early AIs Lose Control of Later AIs34:46 The Superhuman Threshold Is Real38:27 Expecting Rapid FOOM40:20 Rocket Alignment49:59 Stability of Values Under Self-Modification53:13 The Way to Heaven Passes Right By Hell57:32 My Mainline Doom Scenario01:17:46 What Values Does The Goal Optimizer Have?Show NotesMy recent episode with Jim Babcock on this same topic of mainline doom scenarios — https://www.youtube.com/watch?v=FaQjEABZ80gThe Rocket Alignment Problem by Eliezer Yudkowsky — https://www.lesswrong.com/posts/Gg9a4y8reWKtLe3Tn/the-rocket-alignment-problemCome to the Less Online conference on May 30 - Jun 1, 2025: https://less.onlineWatch the Lethal Intelligence Guide, the ultimate introduction to AI x-risk! https://www.youtube.com/@lethal-intelligencePauseAI, the volunteer organization I’m part of: https://pauseai.infoJoin the PauseAI Discord — https://discord.gg/2XXWXvErfA — and say hi to me in the #doom-debates-podcast channel!Doom Debates’ Mission is to raise mainstream awareness of imminent extinction from AGI and build the social infrastructure for high-quality debate.Support the mission by subscribing to my Substack at https://doomdebates.com and to https://youtube.com/@DoomDebates Get full access to Doom Debates at lironshapira.substack.com/subscribe

The Most Likely AI Doom Scenario — with Jim Babcock, LessWrong Team
What’s the most likely (“mainline”) AI doom scenario? How does the existence of LLMs update the original Yudkowskian version? I invited my friend Jim Babcock to help me answer these questions.Jim is a member of the LessWrong engineering team and its parent organization, Lightcone Infrastructure. I’ve been a longtime fan of his thoughtful takes.This turned out to be a VERY insightful and informative discussion, useful for clarifying my own predictions, and accessible to the show’s audience.00:00 Introducing Jim Babcock01:29 The Evolution of LessWrong Doom Scenarios02:22 LessWrong’s Mission05:49 The Rationalist Community and AI09:37 What’s Your P(Doom)™18:26 What Are Yudkowskians Surprised About?26:48 Moral Philosophy vs. Goal Alignment36:56 Sandboxing and AI Containment42:51 Holding Yudkowskians Accountable58:29 Understanding Next Word Prediction01:00:02 Pre-Training vs Post-Training01:08:06 The Rocket Alignment Problem Analogy01:30:09 FOOM vs. Gradual Disempowerment01:45:19 Recapping the Mainline Doom Scenario01:52:08 Liron’s OutroShow NotesJim’s LessWrong — https://www.lesswrong.com/users/jimrandomhJim’s Twitter — https://x.com/jimrandomhThe Rocket Alignment Problem by Eliezer Yudkowsky — https://www.lesswrong.com/posts/Gg9a4y8reWKtLe3Tn/the-rocket-alignment-problemOptimality is the Tiger and Agents Are Its Teeth — https://www.lesswrong.com/posts/kpPnReyBC54KESiSn/optimality-is-the-tiger-and-agents-are-its-teethDoom Debates episode about the research paper discovering AI's utility function — https://lironshapira.substack.com/p/cais-researchers-discover-ais-preferencesCome to the Less Online conference on May 30 - Jun 1, 2025: https://less.onlineWatch the Lethal Intelligence Guide, the ultimate introduction to AI x-risk! https://www.youtube.com/@lethal-intelligencePauseAI, the volunteer organization I’m part of: https://pauseai.infoJoin the PauseAI Discord — https://discord.gg/2XXWXvErfA — and say hi to me in the #doom-debates-podcast channel!Doom Debates’ Mission is to raise mainstream awareness of imminent extinction from AGI and build the social infrastructure for high-quality debate.Support the mission by subscribing to my Substack at https://doomdebates.com and to https://youtube.com/@DoomDebates Get full access to Doom Debates at lironshapira.substack.com/subscribe

AI Could Give Humans MORE Control — Ozzie Gooen
Ozzie Gooen is the founder of the Quantified Uncertainty Research Institute (QURI), a nonprofit building software tools for forecasting and policy analysis. I’ve known him through the rationality community since 2008 and we have a lot in common.00:00 Introducing Ozzie02:18 The Rationality Community06:32 What’s Your P(Doom)™08:09 High-Quality Discourse and Social Media14:17 Guesstimate and Squiggle Demos31:57 Prediction Markets and Rationality38:33 Metaforecast Demo41:23 Evaluating Everything with LLMs47:00 Effective Altruism and FTX Scandal56:00 The Repugnant Conclusion Debate01:02:25 AI for Governance and Policy01:12:07 PauseAI Policy Debate01:30:10 Status Quo Bias01:33:31 Decaf Coffee and Caffeine Powder01:34:45 Are You Aspie?01:37:45 Billionaires in Effective Altruism01:48:06 Gradual Disempowerment by AI01:55:36 LessOnline Conference01:57:34 Supporting Ozzie’s WorkShow NotesQuantified Uncertainty Research Institute (QURI) — https://quantifieduncertainty.orgOzzie’s Facebook — https://www.facebook.com/ozzie.gooenOzzie’s Twitter — https://x.com/ozziegooenGuesstimate, a spreadsheet for working with probability ranges — https://www.getguesstimate.comSquiggle, a programming language for building Monte Carlo simulations — https://www.squiggle-language.comMetaforecast, a prediction market aggregator — https://metaforecast.orgOpen Annotate, AI-powered content analysis — https://github.com/quantified-uncertainty/open-annotate/Come to the Less Online conference on May 30 - Jun 1, 2025: https://less.onlineWatch the Lethal Intelligence Guide, the ultimate introduction to AI x-risk! https://www.youtube.com/@lethal-intelligencePauseAI, the volunteer organization I’m part of: https://pauseai.infoJoin the PauseAI Discord — https://discord.gg/2XXWXvErfA — and say hi to me in the #doom-debates-podcast channel!Doom Debates’ Mission is to raise mainstream awareness of imminent extinction from AGI and build the social infrastructure for high-quality debate.Support the mission by subscribing to my Substack at https://doomdebates.com and to https://youtube.com/@DoomDebates Get full access to Doom Debates at lironshapira.substack.com/subscribe

Top AI Professor Has 85% P(Doom) — David Duvenaud, Fmr. Anthropic Safety Team Lead
David Duvenaud is a professor of Computer Science at the University of Toronto, co-director of the Schwartz Reisman Institute for Technology and Society, former Alignment Evals Team Lead at Anthropic, an award-winning machine learning researcher, and a close collaborator of Dr. Geoffrey Hinton. He recently co-authored Gradual Disempowerment.We dive into David’s impressive career, his high P(Doom), his recent tenure at Anthropic, his views on gradual disempowerment, and the critical need for improved governance and coordination on a global scale.00:00 Introducing David03:03 Joining Anthropic and AI Safety Concerns35:58 David’s Background and Early Influences45:11 AI Safety and Alignment Challenges54:08 What’s Your P(Doom)™01:06:44 Balancing Productivity and Family Life01:10:26 The Hamming Question: Are You Working on the Most Important Problem?01:16:28 The PauseAI Movement01:20:28 Public Discourse on AI Doom01:24:49 Courageous Voices in AI Safety01:43:54 Coordination and Government Role in AI01:47:41 Cowardice in AI Leadership02:00:05 Economic and Existential Doom02:06:12 Liron’s Post-ShowShow NotesDavid’s Twitter — https://x.com/DavidDuvenaudSchwartz Reisman Institute for Technology and Society — https://srinstitute.utoronto.ca/Jürgen Schmidhuber’s Home Page — https://people.idsia.ch/~juergen/Ryan Greenblatt's LessWrong comment about a future scenario where there's a one-time renegotiation of power and heat from superintelligent AI projects causes the oceans to boil: https://www.lesswrong.com/posts/pZhEQieM9otKXhxmd/gradual-disempowerment-systemic-existential-risks-from?commentId=T7KZGGqq2Z4gXZstyWatch the Lethal Intelligence Guide, the ultimate introduction to AI x-risk! https://www.youtube.com/@lethal-intelligencePauseAI, the volunteer organization I’m part of: https://pauseai.infoJoin the PauseAI Discord — https://discord.gg/2XXWXvErfA — and say hi to me in the #doom-debates-podcast channel!Doom Debates’ Mission is to raise mainstream awareness of imminent extinction from AGI and build the social infrastructure for high-quality debate.Support the mission by subscribing to my Substack at https://doomdebates.com and to https://youtube.com/@DoomDebates Get full access to Doom Debates at lironshapira.substack.com/subscribe

“AI 2027” — Top Superforecaster's Imminent Doom Scenario
AI 2027, a bombshell new paper by the AI Futures Project, is a highly plausible scenario of the next few years of AI progress. I like this paper so much that I made a whole episode about it.00:00 Overview of AI 202705:13 2025: Stumbling Agents16:23 2026: Advanced Agents21:49 2027: The Intelligence Explosion29:13 AI's Initial Exploits and OpenBrain's Secrecy30:41 Agent-3 and the Rise of Superhuman Engineering37:05 The Creation and Deception of Agent-544:56 The Race Scenario: Humanity's Downfall48:58 The Slowdown Scenario: A Glimmer of Hope53:49 Final ThoughtsShow NotesThe website: https://ai-2027.comScott Alexander’s blog: https://astralcodexten.comDaniel Kokotajlo’s previous predictions from 2021 about 2026: https://www.lesswrong.com/posts/6Xgy6CAf2jqHhynHL/what-2026-looks-likeWatch the Lethal Intelligence Guide, the ultimate introduction to AI x-risk! https://www.youtube.com/@lethal-intelligencePauseAI, the volunteer organization I’m part of: https://pauseai.infoJoin the PauseAI Discord — https://discord.gg/2XXWXvErfA — and say hi to me in the #doom-debates-podcast channel!Doom Debates’ Mission is to raise mainstream awareness of imminent extinction from AGI and build the social infrastructure for high-quality debate.Support the mission by subscribing to my Substack at https://doomdebates.com and to https://youtube.com/@DoomDebates Get full access to Doom Debates at lironshapira.substack.com/subscribe

Top Economist Sees AI Doom Coming — Dr. Peter Berezin, BCA Research
Dr. Peter Berezin is the Chief Global Strategist and Director of Research at BCA Research, the largest Canadian investment research firm. He’s known for his macroeconomics research reports and his frequent appearances on Bloomberg and CNBC.Notably, Peter is one of the only macroeconomists in the world who’s forecasting AI doom! He recently published a research report estimating a “ more than 50/50 chance AI will wipe out all of humanity by the middle of the century”.00:00 Introducing Peter Berezin01:59 Peter’s Economic Predictions and Track Record05:50 Investment Strategies and Beating the Market17:47 The Future of Human Employment26:40 Existential Risks and the Doomsday Argument34:13 What’s Your P(Doom)™39:18 Probability of non-AI Doom44:19 Solving Population Decline50:53 Constraining AI Development53:40 The Multiverse and Its Implications01:01:11 Are Other Economists Crazy?01:09:19 Mathematical Universe and Multiverse Theories01:19:43 Epistemic vs. Physical Probability01:33:19 Reality Fluid01:39:11 AI and Moral Realism01:54:18 The Simulation Hypothesis and God02:10:06 Liron’s Post-ShowShow NotesPeter’s Twitter: https://x.com/PeterBerezinBCAPeter’s old blog — https://stockcoach.blogspot.comPeter’s 2021 BCA Research Report: “Life, Death and Finance in the Cosmic Multiverse” — https://www.bcaresearch.com/public/content/GIS_SR_2021_12_21.pdfM.C. Escher’s “Circle Limit IV” — https://www.escherinhetpaleis.nl/escher-today/circle-limit-iv-heaven-and-hell/Zvi Mowshowitz’s Blog (Liron’s recommendation for best AI news & analysis) — https://thezvi.substack.comMy Doom Debates episode about why nuclear proliferation is bad — https://www.youtube.com/watch?v=ueB9iRQsvQ8Robin Hanson’s “Mangled Worlds” paper — https://mason.gmu.edu/~rhanson/mangledworlds.htmlUncontrollable by Darren McKee (Liron’s recommended AI x-risk book) — https://www.amazon.com/dp/B0CNNYKVH1Watch the Lethal Intelligence Guide, the ultimate introduction to AI x-risk! https://www.youtube.com/@lethal-intelligencePauseAI, the volunteer organization I’m part of: https://pauseai.infoJoin the PauseAI Discord — https://discord.gg/2XXWXvErfA — and say hi to me in the #doom-debates-podcast channel!Doom Debates’ Mission is to raise mainstream awareness of imminent extinction from AGI and build the social infrastructure for high-quality debate.Support the mission by subscribing to my Substack at https://doomdebates.com and to https://youtube.com/@DoomDebates Get full access to Doom Debates at lironshapira.substack.com/subscribe

AI News: GPT-4o Images, AI Unemployment, Emmett Shear's New Safety Org — with Nathan Labenz
Nathan Labenz, host of The Cognitive Revolution, joins me for an AI news & social media roundup!00:00 Introducing Nate05:18 What’s Your P(Doom)™23:22 GPT-4o Image Generation40:20 Will Fiverr’s Stock Crash?47:41 AI Unemployment55:11 Entrepreneurship01:00:40 OpenAI Valuation01:09:29 Connor Leahy’s Hair01:13:28 Mass Extinction01:25:30 Is anyone feeling the doom vibes?01:38:20 Rethinking AI Individuality01:40:35 “Softmax” — Emmett Shear's New AI Safety Org01:57:04 Anthropic's Mechanistic Interpretability Paper02:10:11 International Cooperation for AI Safety02:18:43 Final ThoughtsShow NotesNate’s Twitter: https://x.com/labenzNate’s podcast: https://cognitiverevolution.ai and https://youtube.com/@CognitiveRevolutionPodcastNate’s company: https://waymark.com/Watch the Lethal Intelligence Guide, the ultimate introduction to AI x-risk! https://www.youtube.com/@lethal-intelligencePauseAI, the volunteer organization I’m part of: https://pauseai.infoJoin the PauseAI Discord — https://discord.gg/2XXWXvErfA — and say hi to me in the #doom-debates-podcast channel!Doom Debates’ Mission is to raise mainstream awareness of imminent extinction from AGI and build the social infrastructure for high-quality debate.Support the mission by subscribing to my Substack at https://doomdebates.com and to https://youtube.com/@DoomDebates Get full access to Doom Debates at lironshapira.substack.com/subscribe

How an AI Doomer Sees The World — Liron on The Human Podcast
In this special cross-posted episode of Doom Debates, originally posted here on The Human Podcast, we cover a wide range of topics including the definition of “doom”, P(Doom), various existential risks like pandemics and nuclear threats, and the comparison of rogue AI risks versus AI misuse risks.00:00 Introduction01:47 Defining Doom and AI Risks05:53 P(Doom)10:04 Doom Debates’ Mission16:17 Personal Reflections and Life Choices24:57 The Importance of Debate27:07 Personal Reflections on AI Doom30:46 Comparing AI Doom to Other Existential Risks33:42 Strategies to Mitigate AI Risks39:31 The Global AI Race and Game Theory43:06 Philosophical Reflections on a Good Life45:21 Final ThoughtsShow NotesThe Human Podcast with Joe Murray: https://www.youtube.com/@thehumanpodcastofficialWatch the Lethal Intelligence Guide, the ultimate introduction to AI x-risk! https://www.youtube.com/@lethal-intelligencePauseAI, the volunteer organization I’m part of: https://pauseai.infoJoin the PauseAI Discord — https://discord.gg/2XXWXvErfA — and say hi to me in the #doom-debates-podcast channel!Don’t miss the other great AI doom show, For Humanity: https://youtube.com/@ForHumanityAIRiskDoom Debates’ Mission is to raise mainstream awareness of imminent extinction from AGI and build the social infrastructure for high-quality debate.Support the mission by subscribing to my Substack at https://doomdebates.com and to https://youtube.com/@DoomDebates Get full access to Doom Debates at lironshapira.substack.com/subscribe

Gödel's Theorem Says Intelligence ≠ Power? AI Doom Debate with Alexander Campbell
Alexander Campbell claims that having superhuman intelligence doesn’t necessarily translate into having vast power, and that Gödel's Incompleteness Theorem ensures AI can’t get too powerful. I strongly disagree.Alex has a Master's of Philosophy in Economics from the University of Oxford and an MBA from the Stanford Graduate School of Business, has worked as a quant trader at Lehman Brothers and Bridgewater Associates, and is the founder of Rose AI, a cloud data platform that leverages generative AI to help visualize data.This debate was recorded in August 2023.00:00 Intro and Alex’s Background05:29 Alex's Views on AI and Technology06:45 Alex’s Non-Doomer Position11:20 Goal-to-Action Mapping15:20 Outcome Pump Thought Experiment21:07 Liron’s Doom Argument29:10 The Dangers of Goal-to-Action Mappers34:39 The China Argument and Existential Risks45:18 Ideological Turing Test48:38 Final ThoughtsShow NotesAlexander Campbell’s Twitter: https://x.com/abcampbellWatch the Lethal Intelligence Guide, the ultimate introduction to AI x-risk! https://www.youtube.com/@lethal-intelligencePauseAI, the volunteer organization I’m part of: https://pauseai.infoJoin the PauseAI Discord — https://discord.gg/2XXWXvErfA — and say hi to me in the #doom-debates-podcast channel!Doom Debates’ Mission is to raise mainstream awareness of imminent extinction from AGI and build the social infrastructure for high-quality debate.Support the mission by subscribing to my Substack at https://doomdebates.com and to https://youtube.com/@DoomDebates Get full access to Doom Debates at lironshapira.substack.com/subscribe

Alignment is EASY and Roko's Basilisk is GOOD?!
Roko Mijic has been an active member of the LessWrong and AI safety community since 2008. He’s best known for “Roko’s Basilisk”, a thought experiment he posted on LessWrong that made Eliezer Yudkowsky freak out, and years later became the topic that helped Elon Musk get interested in Grimes.His view on AI doom is that:* AI alignment is an easy problem* But the chaos and fighting from building superintelligence poses a high near-term existential risk* But humanity’s course without AI has an even higher near-term existential riskWhile my own view is very different, I’m interested to learn more about Roko’s views and nail down our cruxes of disagreement.00:00 Introducing Roko03:33 Realizing that AI is the only thing that matters06:51 Cyc: AI with “common sense”15:15 Is alignment easy?21:19 What’s Your P(Doom)™25:14 Why civilization is doomed anyway37:07 Roko’s AI nightmare scenario47:00 AI risk mitigation52:07 Market Incentives and AI Safety57:13 Are RL and GANs good enough for superalignment?01:00:54 If humans learned to be honest, why can’t AIs?01:10:29 Is our test environment sufficiently similar to production?01:23:56 AGI Timelines01:26:35 Headroom above human intelligence01:42:22 Roko’s Basilisk01:54:01 Post-Debate MonologueShow NotesRoko’s Twitter: https://x.com/RokoMijicExplanation of Roko’s Basilisk on LessWrong: https://www.lesswrong.com/w/rokos-basiliskWatch the Lethal Intelligence Guide, the ultimate introduction to AI x-risk! https://www.youtube.com/@lethal-intelligencePauseAI, the volunteer organization I’m part of: https://pauseai.infoJoin the PauseAI Discord — https://discord.gg/2XXWXvErfA — and say hi to me in the #doom-debates-podcast channel!Doom Debates’ Mission is to raise mainstream awareness of imminent extinction from AGI and build the social infrastructure for high-quality debate.Support the mission by subscribing to my Substack at https://doomdebates.com and to https://youtube.com/@DoomDebates Get full access to Doom Debates at lironshapira.substack.com/subscribe

Roger Penrose is WRONG about Gödel's Theorem and AI Consciousness
Sir Roger Penrose is a mathematician, mathematical physicist, philosopher of science, and Nobel Laureate in Physics.His famous body of work includes Penrose diagrams, twistor theory, Penrose tilings, and the incredibly bold claim that intelligence and consciousness are uncomputable physical phenomena related to quantum wave function collapse. Dr. Penrose is such a genius that it's just interesting to unpack his worldview, even if it’s totally implausible. How can someone like him be so wrong? What exactly is it that he's wrong about? It's interesting to try to see the world through his eyes, before recoiling from how nonsensical it looks.00:00 Episode Highlights01:29 Introduction to Roger Penrose11:56 Uncomputability16:52 Penrose on Gödel's Incompleteness Theorem19:57 Liron Explains Gödel's Incompleteness Theorem27:05 Why Penrose Gets Gödel Wrong40:53 Scott Aaronson's Gödel CAPTCHA46:28 Penrose's Critique of the Turing Test48:01 Searle's Chinese Room Argument52:07 Penrose's Views on AI and Consciousness57:47 AI's Computational Power vs. Human Intelligence01:21:08 Penrose's Perspective on AI Risk01:22:20 Consciousness = Quantum Wave Function Collapse?01:26:25 Final ThoughtsShow NotesSource video — Feb 22, 2025 Interview with Roger Penrose on “This Is World” — https://www.youtube.com/watch?v=biUfMZ2dts8Scott Aaronson’s “Gödel CAPTCHA” — https://www.scottaaronson.com/writings/captcha.htmlMy recent Scott Aaronson episode — https://www.youtube.com/watch?v=xsGqWeqKjEgMy explanation of what’s wrong with arguing “by definition” — https://www.youtube.com/watch?v=ueam4fq8k8IWatch the Lethal Intelligence Guide, the ultimate introduction to AI x-risk! https://www.youtube.com/@lethal-intelligencePauseAI, the volunteer organization I’m part of: https://pauseai.infoJoin the PauseAI Discord — https://discord.gg/2XXWXvErfA — and say hi to me in the #doom-debates-podcast channel!Doom Debates’ Mission is to raise mainstream awareness of imminent extinction from AGI and build the social infrastructure for high-quality debate.Support the mission by subscribing to my Substack at https://doomdebates.com and to https://youtube.com/@DoomDebates Get full access to Doom Debates at lironshapira.substack.com/subscribe

We Found AI's Preferences — What David Shapiro MISSED in this bombshell Center for AI Safety paper
The Center for AI Safety just dropped a fascinating paper — they discovered that today’s AIs like GPT-4 and Claude have preferences! As in, coherent utility functions. We knew this was inevitable, but we didn’t know it was already happening.This episode has two parts:In Part I (48 minutes), I react to David Shapiro’s coverage of the paper and push back on many of his points.In Part II (60 minutes), I explain the paper myself.00:00 Episode Introduction05:25 PART I: REACTING TO DAVID SHAPIRO10:06 Critique of David Shapiro's Analysis19:19 Reproducing the Experiment35:50 David's Definition of Coherence37:14 Does AI have “Temporal Urgency”?40:32 Universal Values and AI Alignment49:13 PART II: EXPLAINING THE PAPER51:37 How The Experiment Works01:11:33 Instrumental Values and Coherence in AI01:13:04 Exchange Rates and AI Biases01:17:10 Temporal Discounting in AI Models01:19:55 Power Seeking, Fitness Maximization, and Corrigibility01:20:20 Utility Control and Bias Mitigation01:21:17 Implicit Association Test01:28:01 Emailing with the Paper’s Authors01:43:23 My TakeawayShow NotesDavid’s source video: https://www.youtube.com/watch?v=XGu6ejtRz-0The research paper: http://emergent-values.aiWatch the Lethal Intelligence Guide, the ultimate introduction to AI x-risk! https://www.youtube.com/@lethal-intelligencePauseAI, the volunteer organization I’m part of: https://pauseai.infoJoin the PauseAI Discord — https://discord.gg/2XXWXvErfA — and say hi to me in the #doom-debates-podcast channel!Doom Debates’ Mission is to raise mainstream awareness of imminent extinction from AGI and build the social infrastructure for high-quality debate.Support the mission by subscribing to my Substack at https://doomdebates.com and to https://youtube.com/@DoomDebates Get full access to Doom Debates at lironshapira.substack.com/subscribe

Does AI Competition = AI Alignment? Debate with Gil Mark
My friend Gil Mark, who leads generative AI products at LinkedIn, thinks competition among superintelligent AIs will lead to a good outcome for humanity. In his view, the alignment problem becomes significantly easier if we build multiple AIs at the same time and let them compete.I completely disagree, but I hope you’ll find this to be a thought-provoking episode that sheds light on why the alignment problem is so hard.00:00 Introduction02:36 Gil & Liron’s Early Doom Days04:58: AIs : Humans :: Humans : Ants08:02 The Convergence of AI Goals15:19 What’s Your P(Doom)™19:23 Multiple AIs and Human Welfare24:42 Gil’s Alignment Claim42:31 Cheaters and Frankensteins55:55 Superintelligent Game Theory01:01:16 Slower Takeoff via Resource Competition01:07:57 Recapping the Disagreement01:15:39 Post-Debate BanterShow NotesGil’s LinkedIn: https://www.linkedin.com/in/gilmark/Gil’s Twitter: https://x.com/gmfromgmWatch the Lethal Intelligence Guide, the ultimate introduction to AI x-risk! https://www.youtube.com/@lethal-intelligencePauseAI, the volunteer organization I’m part of: https://pauseai.infoJoin the PauseAI Discord — https://discord.gg/2XXWXvErfA — and say hi to me in the #doom-debates-podcast channel!Doom Debates’ Mission is to raise mainstream awareness of imminent extinction from AGI and build the social infrastructure for high-quality debate.Support the mission by subscribing to my Substack at https://doomdebates.com and to https://youtube.com/@DoomDebates Get full access to Doom Debates at lironshapira.substack.com/subscribe

Toy Model of the AI Control Problem
Why does the simplest AI imaginable, when you ask it to help you push a box around a grid, suddenly want you to die?AI doomers are often misconstrued as having "no evidence" or just "anthropomorphizing". This toy model will help you understand why a drive to eliminate humans is NOT a handwavy anthropomorphic speculation, but rather something we expect by default from any sufficiently powerful search algorithm.We’re not talking about AGI or ASI here — we’re just looking at an AI that does brute-force search over actions in a simple grid world.The slide deck I’m presenting was created by Jaan Tallinn, cofounder of the Future of Life Institute.00:00 Introduction01:24 The Toy Model06:19 Misalignment and Manipulation Drives12:57 Search Capacity and Ontological Insights16:33 Irrelevant Concepts in AI Control20:14 Approaches to Solving AI Control Problems23:38 Final ThoughtsWatch the Lethal Intelligence Guide, the ultimate introduction to AI x-risk! https://www.youtube.com/@lethal-intelligencePauseAI, the volunteer organization I’m part of: https://pauseai.infoJoin the PauseAI Discord — https://discord.gg/2XXWXvErfA — and say hi to me in the #doom-debates-podcast channel!Doom Debates’ Mission is to raise mainstream awareness of imminent extinction from AGI and build the social infrastructure for high-quality debate.Support the mission by subscribing to my Substack at https://doomdebates.com and to https://youtube.com/@DoomDebates Get full access to Doom Debates at lironshapira.substack.com/subscribe
Superintelligent AI vs. Real-World Engineering | Liron Reacts to Bryan Cantrill
Bryan Cantrill, co-founder of Oxide Computer, says in his talk that engineering in the physical world is too complex for any AI to do it better than teams of human engineers. Success isn’t about intelligence; it’s about teamwork, character and resilience.I completely disagree.00:00 Introduction02:03 Bryan’s Take on AI Doom05:55 The Concept of P(Doom)08:36 Engineering Challenges and Human Intelligence15:09 The Role of Regulation and Authoritarianism in AI Control29:44 Engineering Complexity: A Case Study from Oxide Computer40:06 The Value of Team Collaboration46:13 Human Attributes in Engineering49:33 AI's Potential in Engineering58:23 Existential Risks and AI PredictionsBryan’s original talk: Watch the Lethal Intelligence Guide, the ultimate introduction to AI x-risk! https://www.youtube.com/watch?v=9CUFbqh16FgPauseAI, the volunteer organization I’m part of: https://pauseai.infoJoin the PauseAI Discord — https://discord.gg/2XXWXvErfA — and say hi to me in the #doom-debates-podcast channel!Doom Debates’ Mission is to raise mainstream awareness of imminent extinction from AGI and build the social infrastructure for high-quality debate.Support the mission by subscribing to my Substack at DoomDebates.com and to youtube.com/@DoomDebates Get full access to Doom Debates at lironshapira.substack.com/subscribe

2,500 Subscribers Live Q&A Recording
Thanks for everyone who participated in the live Q&A on Friday!The topics covered include advice for computer science students, working in AI trustworthiness, what good AI regulation looks like, the implications of the $500B Stargate project, the public's gradual understanding of AI risks, the impact of minor AI disasters, and the philosophy of consciousness.00:00 Advice for Comp Sci Students01:14 The $500B Stargate Project02:36 Eliezer's Recent Podcast03:07 AI Safety and Public Policy04:28 AI Disruption and Politics05:12 DeepSeek and AI Advancements06:54 Human vs. AI Intelligence14:00 Consciousness and AI24:34 Dark Forest Theory and AI35:31 Investing in Yourself42:42 Probability of Aliens Saving Us from AI43:31 Brain-Computer Interfaces and AI Safety46:19 Debating AI Safety and Human Intelligence48:50 Nefarious AI Activities and Satellite Surveillance49:31 Pliny the Prompter Jailbreaking AI50:20 Can’t vs. Won’t Destroy the World51:15 How to Make AI Risk Feel Present54:27 Keeping Doom Arguments On Track57:04 Game Theory and AI Development Race01:01:26 Mental Model of Average Non-Doomer01:04:58 Is Liron a Strict Bayesian and Utilitarian?01:09:48 Can We Rename “Doom Debates”01:12:34 The Role of AI Trustworthiness01:16:48 Minor AI Disasters01:18:07 Most Likely Reason Things Go Well01:21:00 Final ThoughtsShow NotesPrevious post where people submitted questions: https://lironshapira.substack.com/p/2500-subscribers-live-q-and-a-askWatch the Lethal Intelligence Guide, the ultimate introduction to AI x-risk!PauseAI, the volunteer organization I’m part of: https://pauseai.infoJoin the PauseAI Discord — https://discord.gg/2XXWXvErfA — and say hi to me in the #doom-debates-podcast channel!Doom Debates’ Mission is to raise mainstream awareness of imminent extinction from AGI and build the social infrastructure for high-quality debate.Support the mission by subscribing to my Substack at DoomDebates.com and to youtube.com/@DoomDebates Get full access to Doom Debates at lironshapira.substack.com/subscribe

AI Twitter Beefs #3: Marc Andreessen, Sam Altman, Mark Zuckerberg, Yann LeCun, Eliezer Yudkowsky & More!
It’s time for AI Twitter Beefs #3:00:00 Introduction01:27 Marc Andreessen vs. Sam Altman09:15 Mark Zuckerberg35:40 Martin Casado47:26 Gary Marcus vs. Miles Brundage Bet58:39 Scott Alexander’s AI Art Turing Test01:11:29 Roon01:16:35 Stephen McAleer01:22:25 Emmett Shear01:37:20 OpenAI’s “Safety”01:44:09 Naval Ravikant vs. Eliezer Yudkowsky01:56:03 Comic Relief01:58:53 Final ThoughtsShow NotesUpcoming Live Q&A: https://lironshapira.substack.com/p/2500-subscribers-live-q-and-a-ask“Make Your Beliefs Pay Rent In Anticipated Experiences” by Eliezer Yudkowsky on LessWrong: https://www.lesswrong.com/posts/a7n8GdKiAZRX86T5A/making-beliefs-pay-rent-in-anticipated-experiencesScott Alexander’s AI Art Turing Test: https://www.astralcodexten.com/p/how-did-you-do-on-the-ai-art-turingWatch the Lethal Intelligence Guide, the ultimate introduction to AI x-risk!PauseAI, the volunteer organization I’m part of: https://pauseai.infoJoin the PauseAI Discord — https://discord.gg/2XXWXvErfA — and say hi to me in the #doom-debates-podcast channel!Doom Debates’ Mission is to raise mainstream awareness of imminent extinction from AGI and build the social infrastructure for high-quality debate.Support the mission by subscribing to my Substack at DoomDebates.com and to youtube.com/@DoomDebates Get full access to Doom Debates at lironshapira.substack.com/subscribe

Effective Altruism Debate with Jonas Sota
Effective Altruism has been a controversial topic on social media, so today my guest and I are going to settle the question once and for all: Is it good or bad?Jonas Sota is a Software Engineer at Rippling, BA in Philosophy from UC Berkeley, who’s been observing the Effective Altruism (EA) movement in the San Francisco Bay Area for over a decade… and he’s not a fan.00:00 Introduction01:22 Jonas’s Criticisms of EA03:23 Recoil Exaggeration05:53 Impact of Malaria Nets10:48 Local vs. Global Altruism13:02 Shrimp Welfare25:14 Capitalism vs. Charity33:37 Cultural Sensitivity34:43 The Impact of Direct Cash Transfers37:23 Long-Term Solutions vs. Immediate Aid42:21 Charity Budgets45:47 Prioritizing Local Issues50:55 The EA Community59:34 Debate Recap1:03:57 AnnouncementsShow NotesJonas’s Instagram: @jonas_wandersWill MacAskill’s famous book, Doing Good Better: https://www.effectivealtruism.org/doing-good-betterScott Alexander’s excellent post about the people he met at EA Global: https://slatestarcodex.com/2017/08/16/fear-and-loathing-at-effective-altruism-global-2017/Watch the Lethal Intelligence Guide, the ultimate introduction to AI x-risk!PauseAI, the volunteer organization I’m part of: https://pauseai.infoJoin the PauseAI Discord — https://discord.gg/2XXWXvErfA — and say hi to me in the #doom-debates-podcast channel!Doom Debates’ Mission is to raise mainstream awareness of imminent extinction from AGI and build the social infrastructure for high-quality debate.Support the mission by subscribing to my Substack at DoomDebates.com and to youtube.com/@DoomDebates Get full access to Doom Debates at lironshapira.substack.com/subscribe

God vs. AI Doom: Debate with Bentham's Bulldog
Matthew Adelstein, better known as Bentham’s Bulldog on Substack, is a philosophy major at the University of Michigan and an up & coming public intellectual.He’s a rare combination: Effective Altruist, Bayesian, non-reductionist, theist.Our debate covers reductionism, evidence for god, the implications of a fine-tuned universe, moral realism, and AI doom.00:00 Introduction02:56 Matthew’s Research11:29 Animal Welfare16:04 Reductionism vs. Non-Reductionism Debate39:53 The Decline of God in Modern Discourse46:23 Religious Credences50:24 Pascal's Wager and Christianity56:13 Are Miracles Real?01:10:37 Fine-Tuning Argument for God01:28:36 Cellular Automata01:34:25 Anthropic Principle01:51:40 Mathematical Structures and Probability02:09:35 Defining God02:18:20 Moral Realism02:21:40 Orthogonality Thesis02:32:02 Moral Philosophy vs. Science02:45:51 Moral Intuitions02:53:18 AI and Moral Philosophy03:08:50 Debate Recap03:12:20 Show UpdatesShow NotesMatthew’s Substack: https://benthams.substack.comMatthew's Twitter: https://x.com/BenthamsBulldogMatthew's YouTube: https://www.youtube.com/@deliberationunderidealcond5105Lethal Intelligence Guide, the ultimate animated video introduction to AI x-risk – https://www.youtube.com/watch?v=9CUFbqh16FgPauseAI, the volunteer organization I’m part of — https://pauseai.info/Join the PauseAI Discord — https://discord.gg/2XXWXvErfA — and say hi to me in the #doom-debates-podcast channel!Doom Debates’ Mission is to raise mainstream awareness of imminent extinction from AGI and build the social infrastructure for high-quality debate.Support the mission by subscribing to my Substack at DoomDebates.com and to youtube.com/@DoomDebates Get full access to Doom Debates at lironshapira.substack.com/subscribe

Debate with a former OpenAI Research Team Lead — Prof. Kenneth Stanley
Prof. Kenneth Stanley is a former Research Science Manager at OpenAI leading the Open-Endedness Team in 2020-2022. Before that, he was a Professor of Computer Ccience at the University of Central Florida and the head of Core AI Research at Uber. He coauthored Why Greatness Cannot Be Planned: The Myth of the Objective, which argues that as soon as you create an objective, then you ruin your ability to reach it.In this episode, I debate Ken’s claim that superintelligent AI *won’t* be guided by goals, and then we compare our views on AI doom.00:00 Introduction00:45 Ken’s Role at OpenAI01:53 “Open-Endedness” and “Divergence”9:32 Open-Endedness of Evolution21:16 Human Innovation and Tech Trees36:03 Objectives vs. Open Endedness47:14 The Concept of Optimization Processes57:22 What’s Your P(Doom)™01:11:01 Interestingness and the Future01:20:14 Human Intelligence vs. Superintelligence01:37:51 Instrumental Convergence01:55:58 Mitigating AI Risks02:04:02 The Role of Institutional Checks02:13:05 Exploring AI's Curiosity and Human Survival02:20:51 Recapping the Debate02:29:45 Final ThoughtsSHOW NOTESKen’s home page: https://www.kenstanley.net/Ken’s Wikipedia: https://en.wikipedia.org/wiki/Kenneth_StanleyKen’s Twitter: https://x.com/kenneth0stanleyKen’s PicBreeder paper: https://wiki.santafe.edu/images/1/1e/Secretan_ecj11.pdfKen's book, Why Greatness Cannot Be Planned: The Myth of the Objective: https://www.amazon.com/Why-Greatness-Cannot-Planned-Objective/dp/3319155237The Rocket Alignment Problem by Eliezer Yudkowsky: https://intelligence.org/2018/10/03/rocket-alignment/---Lethal Intelligence Guide, the ultimate animated video introduction to AI x-risk – https://www.youtube.com/watch?v=9CUFbqh16FgPauseAI, the volunteer organization I’m part of — https://pauseai.info/Join the PauseAI Discord — https://discord.gg/2XXWXvErfA — and say hi to me in the #doom-debates-podcast channel!---Doom Debates’ Mission is to raise mainstream awareness of imminent extinction from AGI and build the social infrastructure for high-quality debate.Support the mission by subscribing to my Substack at DoomDebates.com and to youtube.com/@DoomDebates Get full access to Doom Debates at lironshapira.substack.com/subscribe

OpenAI o3 and Claude Alignment Faking — How doomed are we?
OpenAI just announced o3 and smashed a bunch of benchmarks (ARC-AGI, SWE-bench, FrontierMath)!A new Anthropic and Redwood Research paper says Claude is resisting its developers’ attempts to retrain its values!What’s the upshot — what does it all mean for P(doom)?00:00 Introduction01:45 o3’s architecture and benchmarks06:08 “Scaling is hitting a wall” 🤡13:41 How many new architectural insights before AGI?20:28 Negative update for interpretability31:30 Intellidynamics — ***KEY CONCEPT***33:20 Nuclear control rod analogy36:54 Sam Altman's misguided perspective42:40 Claude resisted retraining from good to evil44:22 What is good corrigibility?52:42 Claude’s incorrigibility doesn’t surprise me55:00 Putting it all in perspective---SHOW NOTESScott Alexander’s analysis of the Claude incorrigibility result: https://www.astralcodexten.com/p/claude-fights-back and https://www.astralcodexten.com/p/why-worry-about-incorrigible-claudeZvi Mowshowitz’s analysis of the Claude incorrigibility result: https://thezvi.wordpress.com/2024/12/24/ais-will-increasingly-fake-alignment/---PauseAI Website: https://pauseai.infoPauseAI Discord: https://discord.gg/2XXWXvErfASay hi to me in the #doom-debates-podcast channel!Watch the Lethal Intelligence video and check out LethalIntelligence.ai! It’s an AWESOME new animated intro to AI risk.Doom Debates’ Mission is to raise mainstream awareness of imminent extinction from AGI and build the social infrastructure for high-quality debate.Support the mission by subscribing to my Substack at DoomDebates.com and to youtube.com/@DoomDebates Get full access to Doom Debates at lironshapira.substack.com/subscribe
AI Will Kill Us All — Liron Shapira on The Flares
This week Liron was interview by Gaëtan Selle on @the-flares about AI doom.Cross-posted from their channel with permission.Original source: https://www.youtube.com/watch?v=e4Qi-54I9Zw0:00:02 Guest Introduction 0:01:41 Effective Altruism and Transhumanism 0:05:38 Bayesian Epistemology and Extinction Probability 0:09:26 Defining Intelligence and Its Dangers 0:12:33 The Key Argument for AI Apocalypse 0:18:51 AI’s Internal Alignment 0:24:56 What Will AI's Real Goal Be? 0:26:50 The Train of Apocalypse 0:31:05 Among Intellectuals, Who Rejects the AI Apocalypse Arguments? 0:38:32 The Shoggoth Meme 0:41:26 Possible Scenarios Leading to Extinction 0:50:01 The Only Solution: A Pause in AI Research? 0:59:15 The Risk of Violence from AI Risk Fundamentalists 1:01:18 What Will General AI Look Like? 1:05:43 Sci-Fi Works About AI 1:09:21 The Rationale Behind Cryonics 1:12:55 What Does a Positive Future Look Like? 1:15:52 Are We Living in a Simulation? 1:18:11 Many Worlds in Quantum Mechanics Interpretation 1:20:25 Ideal Future Podcast Guest for Doom Debates Doom Debates’ Mission is to raise mainstream awareness of imminent extinction from AGI and build the social infrastructure for high-quality debate.Support the mission by subscribing to my Substack at DoomDebates.com and to youtube.com/@DoomDebates. Thanks for watching. Get full access to Doom Debates at lironshapira.substack.com/subscribe

Roon vs. Liron: AI Doom Debate
Roon is a member of the technical staff at OpenAI. He’s a highly respected voice on tech Twitter, despite being a pseudonymous cartoon avatar account. In late 2021, he invented the terms “shape rotator” and “wordcel” to refer to roughly visual/spatial/mathematical intelligence vs. verbal intelligence. He is simultaneously a serious thinker, a builder, and a shitposter. I'm excited to learn more about Roon, his background, his life, and of course, his views about AI and existential risk.00:00 Introduction02:43 Roon’s Quest and Philosophies22:32 AI Creativity30:42 What’s Your P(Doom)™54:40 AI Alignment57:24 Training vs. Production01:05:37 ASI01:14:35 Goal-Oriented AI and Instrumental Convergence01:22:43 Pausing AI01:25:58 Crux of Disagreement1:27:55 Dogecoin01:29:13 Doom Debates’s MissionShow NotesFollow Roon: https://x.com/tszzlFor Humanity: An AI Safety Podcast with John Sherman — https://www.youtube.com/@ForHumanityPodcastLethal Intelligence Guide, the ultimate animated video introduction to AI x-risk – https://www.youtube.com/watch?v=9CUFbqh16FgPauseAI, the volunteer organization I’m part of — https://pauseai.info/Join the PauseAI Discord — https://discord.gg/2XXWXvErfA — and say hi to me in the #doom-debates-podcast channel!Doom Debates’ Mission is to raise mainstream awareness of imminent extinction from AGI and build the social infrastructure for high-quality debate.Support the mission by subscribing to my Substack at DoomDebates.com and to youtube.com/@DoomDebates. Thanks for watching. Get full access to Doom Debates at lironshapira.substack.com/subscribe

Scott Aaronson Makes Me Think OpenAI's “Safety” Is Fake, Clueless, Reckless and Insane
Today I’m reacting to the recent Scott Aaronson interview on the Win-Win podcast with Liv Boeree and Igor Kurganov.Prof. Aaronson is the Director of the Quantum Information Center at the University of Texas at Austin. He’s best known for his research advancing the frontier of complexity theory, especially quantum complexity theory, and making complex insights from his field accessible to a wider readership via his blog.Scott is one of my biggest intellectual influences. His famous Who Can Name The Bigger Number essay and his long-running blog are among my best memories of coming across high-quality intellectual content online as a teen. His posts and lectures taught me much of what I know about complexity theory.Scott recently completed a two-year stint at OpenAI focusing on the theoretical foundations of AI safety, so I was interested to hear his insider account.Unfortunately, what I heard in the interview confirms my worst fears about the meaning of “safety” at today’s AI companies: that they’re laughably clueless at how to achieve any measure of safety, but instead of doing the adult thing and slowing down their capabilities work, they’re pushing forward recklessly.00:00 Introducing Scott Aaronson02:17 Scott's Recruitment by OpenAI04:18 Scott's Work on AI Safety at OpenAI08:10 Challenges in AI Alignment12:05 Watermarking AI Outputs15:23 The State of AI Safety Research22:13 The Intractability of AI Alignment34:20 Policy Implications and the Call to Pause AI38:18 Out-of-Distribution Generalization45:30 Moral Worth Criterion for Humans51:49 Quantum Mechanics and Human Uniqueness01:00:31 Quantum No-Cloning Theorem01:12:40 Scott Is Almost An Accelerationist?01:18:04 Geoffrey Hinton's Proposal for Analog AI01:36:13 The AI Arms Race and the Need for Regulation01:39:41 Scott Aronson's Thoughts on Sam Altman01:42:58 Scott Rejects the Orthogonality Thesis01:46:35 Final Thoughts01:48:48 Lethal Intelligence Clip01:51:42 OutroShow NotesScott’s Interview on Win-Win with Liv Boeree and Igor Kurganov: https://www.youtube.com/watch?v=ANFnUHcYza0Scott’s Blog: https://scottaaronson.blogPauseAI Website: https://pauseai.infoPauseAI Discord: https://discord.gg/2XXWXvErfAWatch the Lethal Intelligence video and check out LethalIntelligence.ai! It’s an AWESOME new animated intro to AI risk.Doom Debates’ Mission is to raise mainstream awareness of imminent extinction from AGI and build the social infrastructure for high-quality debate.Support the mission by subscribing to my Substack at DoomDebates.com and to youtube.com/@DoomDebates. Thanks for watching. Get full access to Doom Debates at lironshapira.substack.com/subscribe

Liron Reacts to Subbarao Kambhampati on Machine Learning Street Talk
Today I’m reacting to a July 2024 interview that Prof. Subbarao Kambhampati did on Machine Learning Street Talk.Rao is a Professor of Computer Science at Arizona State University, and one of the foremost voices making the claim that while LLMs can generate creative ideas, they can’t truly reason.The episode covers a range of topics including planning, creativity, the limits of LLMs, and why Rao thinks LLMs are essentially advanced N-gram models.00:00 Introduction02:54 Essentially N-Gram Models?10:31 The Manhole Cover Question20:54 Reasoning vs. Approximate Retrieval47:03 Explaining Jokes53:21 Caesar Cipher Performance01:10:44 Creativity vs. Reasoning01:33:37 Reasoning By Analogy01:48:49 Synthetic Data01:53:54 The ARC Challenge02:11:47 Correctness vs. Style02:17:55 AIs Becoming More Robust02:20:11 Block Stacking Problems02:48:12 PlanBench and Future Predictions02:58:59 Final ThoughtsShow NotesRao’s interview on Machine Learning Street Talk: https://www.youtube.com/watch?v=y1WnHpedi2ARao’s Twitter: https://x.com/rao2zPauseAI Website: https://pauseai.infoPauseAI Discord: https://discord.gg/2XXWXvErfAWatch the Lethal Intelligence video and check out LethalIntelligence.ai! It’s an AWESOME new animated intro to AI risk.Doom Debates’ Mission is to raise mainstream awareness of imminent extinction from AGI and build the social infrastructure for high-quality debate.Support the mission by subscribing to my Substack at DoomDebates.com and to youtube.com/@DoomDebates. Thanks for watching. Get full access to Doom Debates at lironshapira.substack.com/subscribe
This Yudkowskian Has A 99.999% P(Doom)
In this episode of Doom Debates, I discuss AI existential risks with my pseudonymous guest Nethys.Nethy shares his journey into AI risk awareness, influenced heavily by LessWrong and Eliezer Yudkowsky. We explore the vulnerability of society to emerging technologies, the challenges of AI alignment, and why he believes our current approaches are insufficient, ultimately resulting in 99.999% P(Doom).00:00 Nethys Introduction04:47 The Vulnerable World Hypothesis10:01 What’s Your P(Doom)™14:04 Nethys’s Banger YouTube Comment26:53 Living with High P(Doom)31:06 Losing Access to Distant Stars36:51 Defining AGI39:09 The Convergence of AI Models47:32 The Role of “Unlicensed” Thinkers52:07 The PauseAI Movement58:20 Lethal Intelligence Video ClipShow NotesEliezer Yudkowsky’s post on “Death with Dignity”: https://www.lesswrong.com/posts/j9Q8bRmwCgXRYAgcJ/miri-announces-new-death-with-dignity-strategyPauseAI Website: https://pauseai.infoPauseAI Discord: https://discord.gg/2XXWXvErfAWatch the Lethal Intelligence video and check out LethalIntelligence.ai! It’s an AWESOME new animated intro to AI risk.Doom Debates’ Mission is to raise mainstream awareness of imminent extinction from AGI and build the social infrastructure for high-quality debate.Support the mission by subscribing to my Substack at DoomDebates.com and to youtube.com/@DoomDebates. Thanks for watching. Get full access to Doom Debates at lironshapira.substack.com/subscribe

Cosmology, AI Doom, and the Future of Humanity with Fraser Cain
Fraser Cain is the publisher of Universe Today, co-host of Astronomy Cast, a popular YouTuber about all things space, and guess what… he has a high P(doom)! That’s why he’s joining me on Doom Debates for a very special AI + space crossover episode.00:00 Fraser Cain’s Background and Interests5:03 What’s Your P(Doom)™07:05 Our Vulnerable World15:11 Don’t Look Up22:18 Cosmology and the Search for Alien Life31:33 Stars = Terrorists39:03 The Great Filter and the Fermi Paradox55:12 Grabby Aliens Hypothesis01:19:40 Life Around Red Dwarf Stars?01:22:23 Epistemology of Grabby Aliens01:29:04 Multiverses01:33:51 Quantum Many Worlds vs. Copenhagen Interpretation01:47:25 Simulation Hypothesis01:51:25 Final ThoughtsSHOW NOTESFraser’s YouTube channel: https://www.youtube.com/@frasercainUniverse Today (space and astronomy news): https://www.universetoday.com/Max Tegmark’s book that explains 4 levels of multiverses: https://www.amazon.com/Our-Mathematical-Universe-Ultimate-Reality/dp/0307744256Robin Hanson’s ideas:Grabby Aliens: https://grabbyaliens.comThe Great Filter: https://en.wikipedia.org/wiki/Great_FilterLife in a high-dimensional space: https://www.overcomingbias.com/p/life-in-1kdhtml---Watch the Lethal Intelligence video and check out LethalIntelligence.ai! It’s an AWESOME new animated intro to AI risk.---Doom Debates’ Mission is to raise mainstream awareness of imminent extinction from AGI and build the social infrastructure for high-quality debate.Support the mission by subscribing to my Substack at DoomDebates.com and to youtube.com/@DoomDebates. Thanks for watching. Get full access to Doom Debates at lironshapira.substack.com/subscribe

AI Doom Debate: Vaden Masrani & Ben Chugg vs. Liron Shapira
Vaden Masrani and Ben Chugg, hosts of the Increments Podcast, are back for a Part II! This time we’re going straight to debating my favorite topic, AI doom.00:00 Introduction02:23 High-Level AI Doom Argument17:06 How Powerful Could Intelligence Be?22:34 “Knowledge Creation”48:33 “Creativity”54:57 Stand-Up Comedy as a Test for AI01:12:53 Vaden & Ben’s Goalposts01:15:00 How to Change Liron’s Mind01:20:02 LLMs are Stochastic Parrots?01:34:06 Tools vs. Agents01:39:51 Instrumental Convergence and AI Goals01:45:51 Intelligence vs. Morality01:53:57 Mainline Futures02:16:50 Lethal Intelligence VideoShow NotesVaden & Ben’s Podcast: https://www.youtube.com/@incrementspodRecommended playlists from their podcast:* The Bayesian vs Popperian Epistemology Series* The Conjectures and Refutations SeriesVaden’s Twitter: https://x.com/vadenmasraniBen’s Twitter: https://x.com/BennyChuggWatch the Lethal Intelligence video and check out LethalIntelligence.ai! It’s an AWESOME new animated intro to AI risk.Doom Debates’ Mission is to raise mainstream awareness of imminent extinction from AGI and build the social infrastructure for high-quality debate.Support the mission by subscribing to my Substack at DoomDebates.com and to youtube.com/@DoomDebates. Thanks for watching. Get full access to Doom Debates at lironshapira.substack.com/subscribe

Andrew Critch vs. Liron Shapira: Will AI Extinction Be Fast Or Slow?
Dr. Andrew Critch is the co-founder of the Center for Applied Rationality, a former Research Fellow at the Machine Intelligence Research Institute (MIRI), a Research Scientist at the UC Berkeley Center for Human Compatible AI, and the co-founder of a new startup called Healthcare Agents.Dr. Critch’s P(Doom) is a whopping 85%! But his most likely doom scenario isn’t what you might expect. He thinks humanity will successfully avoid a self-improving superintelligent doom scenario, only to still go extinct via the slower process of “industrial dehumanization”.00:00 Introduction01:43 Dr. Critch’s Perspective on LessWrong Sequences06:45 Bayesian Epistemology15:34 Dr. Critch's Time at MIRI18:33 What’s Your P(Doom)™26:35 Doom Scenarios40:38 AI Timelines43:09 Defining “AGI”48:27 Superintelligence53:04 The Speed Limit of Intelligence01:12:03 The Obedience Problem in AI01:21:22 Artificial Superintelligence and Human Extinction01:24:36 Global AI Race and Geopolitics01:34:28 Future Scenarios and Human Relevance01:48:13 Extinction by Industrial Dehumanization01:58:50 Automated Factories and Human Control02:02:35 Global Coordination Challenges02:27:00 Healthcare Agents02:35:30 Final Thoughts---Show NotesDr. Critch’s LessWrong post explaining his P(Doom) and most likely doom scenarios: https://www.lesswrong.com/posts/Kobbt3nQgv3yn29pr/my-motivation-and-theory-of-change-for-working-in-aiDr. Critch’s Website: https://acritch.com/Dr. Critch’s Twitter: https://twitter.com/AndrewCritchPhD---Doom Debates’ Mission is to raise mainstream awareness of imminent extinction from AGI and build the social infrastructure for high-quality debate.Support the mission by subscribing to my Substack at DoomDebates.com and to youtube.com/@DoomDebates. Thanks for watching. Get full access to Doom Debates at lironshapira.substack.com/subscribe
AI Twitter Beefs #2: Yann LeCun, David Deutsch, Tyler Cowen, Jack Clark, Beff Jezos, Samuel Hammond vs. Eliezer Yudkowsky, Geoffrey Hinton, Carl Feynman
It’s time for AI Twitter Beefs #2:00:42 Jack Clark (Anthropic) vs. Holly Elmore (PauseAI US)11:02 Beff Jezos vs. Eliezer Yudkowsky, Carl Feynman18:10 Geoffrey Hinton vs. OpenAI & Meta25:14 Samuel Hammond vs. Liron30:26 Yann LeCun vs. Eliezer Yudkowsky37:13 Roon vs. Eliezer Yudkowsky41:37 Tyler Cowen vs. AI Doomers52:54 David Deutsch vs. LironTwitter people referenced:* Jack Clark: https://x.com/jackclarkSF* Holly Elmore: https://x.com/ilex_ulmus* PauseAI US: https://x.com/PauseAIUS* Geoffrey Hinton: https://x.com/GeoffreyHinton* Samuel Hammond: https://x.com/hamandcheese* Yann LeCun: https://x.com/ylecun* Eliezer Yudkowsky: https://x.com/esyudkowsky* Roon: https://x.com/tszzl* Beff Jezos: https://x.com/basedbeffjezos* Carl Feynman: https://x.com/carl_feynman* Tyler Cowen: https://x.com/tylercowen* David Deutsch: https://x.com/DavidDeutschOxfShow NotesHolly Elmore’s EA forum post about scouts vs. soldiersManifund info & donation page for PauseAI US: https://manifund.org/projects/pauseai-us-2025-through-q2PauseAI.info - join the Discord and find me in the #doom-debates channel!Doom Debates’ Mission is to raise mainstream awareness of imminent extinction from AGI and build the social infrastructure for high-quality debate.Support the mission by subscribing to my Substack at DoomDebates.com and to youtube.com/@DoomDebates. Thanks for watching. Get full access to Doom Debates at lironshapira.substack.com/subscribe